add
This commit is contained in:

@@ -1,6 +1,6 @@
|
||||
# Discord Link Ingest Interest Profile
|
||||
|
||||
Updated: 2026-06-28
|
||||
Updated: 2026-06-30
|
||||
Source: discrawl read-only analysis of Yuta/toymaker Discord messages.
|
||||
|
||||
## Author IDs considered
|
||||
@@ -24,6 +24,13 @@ Use for sources that are central to one of these durable themes:
|
||||
- Developer tooling that changes Yuta's automation/dev workflow materially
|
||||
- Quality engineering, security, supply-chain, infra reliability for AI/software systems
|
||||
- Technical writeups with implementation details likely to be referenced later
|
||||
- Loop-engineering style agent operations: discovery, handoff, independent verification, persistence, scheduling, evaluator separation, and state/log design for autonomous jobs
|
||||
- AI-agent operator observability and control surfaces: monitoring multiple coding agents, local process/port/session visibility, rate-limit/context tracking, approval flows, and mobile/terminal dashboards for agent operations
|
||||
- Minimal, observable agent harnesses that expose context/session/tool/process state clearly, especially when they document trade-offs around provider abstraction, terminal/tmux workflows, sub-agents, MCP, permissions, or worktree-based isolation
|
||||
- Agent-oriented CLI/tool design that reduces model guesswork with CLI-owned usage guides, JSON-first output, actionable errors, search/read separation, stale-state metadata, safe defaults, and few flags
|
||||
- Code-to-knowledge and code-to-documentation systems that generate repo Wikis, C4 architecture views, diagrams, or durable onboarding material from source code, especially when they address documentation drift and review workflows
|
||||
- Agent identity/security standards and operational controls, especially MCP authorization, Cross App Access/XAA, least privilege, audit logs, and supply-chain risks around agents
|
||||
- Human-gated AI security workflows that reduce maintainer burden: vulnerability discovery, verification, patch drafting, responsible disclosure, release monitoring, and false-positive suppression before any report leaves the operator's workspace
|
||||
- Niche, exciting design/hack/Hacker News-like material, especially when it exposes an unusual technique, tool, interface, or way of thinking
|
||||
- Public-interest/public-sector technology, civic infrastructure, accessibility (a11y), inclusive design, and systems that make services more usable or equitable
|
||||
- Papers or research with clear relevance to LLMs, agents, evaluation, knowledge systems, automation, accessibility, or public-interest technology
|
||||
|
||||
@@ -1,102 +1,91 @@
|
||||
# Discord Link Ingest State
|
||||
|
||||
last_checked_at: 2026-06-29T16:18:54Z
|
||||
last_message_created_at: 2026-06-28T07:26:20.859000000Z
|
||||
lookback_used: incremental_since_last_message_created_at
|
||||
last_checked_at: 2026-06-30T13:06:00Z
|
||||
last_message_created_at: 2026-06-30T12:21:28.417000000Z
|
||||
lookback_used: incremental_since_last_message_created_at_with_git_share_auto_update
|
||||
channels:
|
||||
chat: '1028287639918497822'
|
||||
tw: '1477793137064935675'
|
||||
|
||||
## Last run summary — 2026-06-29T16:18:54Z
|
||||
## Last run summary — 2026-06-30T13:06:00Z
|
||||
|
||||
- Messages scanned: 0 new messages after `2026-06-28T07:26:20.859000000Z` in monitored channels.
|
||||
- URLs found: 0
|
||||
- Raw articles saved: 0
|
||||
- Wiki pages created/updated: 0
|
||||
- Discrawl status: archive current; last_sync_at `2026-06-28T07:46:17Z`; share repo needs update but read-only ingest did not mutate it.
|
||||
- Rubric note: no new evidence; interest profile unchanged.
|
||||
|
||||
## Previous run summary — 2026-06-29T15:16:46Z
|
||||
|
||||
- Messages scanned: 0 new messages after `2026-06-28T07:26:20.859000000Z` in monitored channels.
|
||||
- URLs found: 0
|
||||
- Raw articles saved: 0
|
||||
- Wiki pages created/updated: 0
|
||||
- Discrawl status: archive current; last_sync_at `2026-06-28T07:46:17Z`; share repo needs update but read-only ingest did not mutate it.
|
||||
- Rubric note: no new evidence; interest profile unchanged.
|
||||
|
||||
## Previous run summary — 2026-06-29T14:14:32Z
|
||||
|
||||
- Messages scanned: 0 new messages after `2026-06-28T07:26:20.859000000Z` in monitored channels.
|
||||
- URLs found: 0
|
||||
- Raw articles saved: 0
|
||||
- Wiki pages created/updated: 0
|
||||
- Discrawl status: archive current; last_sync_at `2026-06-28T07:46:17Z`; share repo needs update but read-only ingest did not mutate it.
|
||||
- Rubric note: no new evidence; interest profile unchanged.
|
||||
|
||||
## Previous run summary — 2026-06-29T13:12:27Z
|
||||
|
||||
- Messages scanned: 0 new messages after `2026-06-28T07:26:20.859000000Z` in monitored channels.
|
||||
- URLs found: 0
|
||||
- Raw articles saved: 0
|
||||
- Wiki pages created/updated: 0
|
||||
- Discrawl status: archive current; last_sync_at `2026-06-28T07:46:17Z`; share repo needs update but read-only ingest did not mutate it.
|
||||
- Rubric note: no new evidence; interest profile unchanged.
|
||||
|
||||
## Manual ingest summary — 2026-06-29
|
||||
|
||||
- Trigger: current Discord reply, `Ingest リバエン`, source `https://github.com/bethington/ghidra-mcp`.
|
||||
- Raw articles saved: 1 (`raw/articles/ghidra-mcp-2026.md`)
|
||||
- Wiki pages created: 2 (`entities/ghidra-mcp.md`, `concepts/ai-assisted-reverse-engineering.md`)
|
||||
- Wiki pages updated: 1 (`index.md`)
|
||||
- Rubric note: reverse-engineering/security developer tools with concrete MCP/agent workflows should score high when they show reusable practice, quality enforcement, or unusual automation patterns.
|
||||
|
||||
## Previous run summary — 2026-06-29T12:10:26Z
|
||||
|
||||
- Messages scanned: 0 new messages after `2026-06-28T07:26:20.859000000Z` in monitored channels.
|
||||
- URLs found: 0
|
||||
- Raw articles saved: 0
|
||||
- Wiki pages created/updated: 0
|
||||
- Discrawl status: archive current; last_sync_at `2026-06-28T07:46:17Z`; share repo needs update but read-only ingest did not mutate it.
|
||||
- Rubric note: no new evidence; interest profile unchanged.
|
||||
|
||||
## Previous run summary — 2026-06-29T11:08:07Z
|
||||
|
||||
- Messages scanned: 0 new messages after `2026-06-28T07:26:20.859000000Z` in monitored channels.
|
||||
- URLs found: 0
|
||||
- Raw articles saved: 0
|
||||
- Wiki pages created/updated: 0
|
||||
- Discrawl status: archive current; last_sync_at `2026-06-28T07:46:17Z`; share repo needs update but read-only ingest did not mutate it.
|
||||
- Rubric note: no new evidence; interest profile unchanged.
|
||||
|
||||
## Earlier run summary — 2026-06-29T09:03:18Z to 2026-06-28T14:15:26Z
|
||||
|
||||
Repeated hourly checks found no new messages after `2026-06-28T07:26:20.859000000Z`; no URLs, raw sources, wiki updates, or rubric changes.
|
||||
|
||||
## Last ingest summary — 2026-06-28
|
||||
|
||||
- Messages scanned: 110
|
||||
- URL-containing messages: 103
|
||||
- Normalized unique URLs found: 613
|
||||
- Non-X/non-twitter URLs: 73
|
||||
- Raw articles saved: 8
|
||||
- Messages scanned: 8 new local-archive messages in #chat and #tw after `2026-06-30T11:21:36.408000000Z`.
|
||||
- Discrawl auto-update: `discrawl status --json` reported share `needs_update=true`; subsequent read-only SQL pulled/imported the git share and increased archive message count to 163,989.
|
||||
- URL mentions found: 42 before dedupe, 39 normalized unique URLs; most were X/Twitter digest links plus direct #chat links.
|
||||
- Durable candidates fetched: 6 attempted; 4 saved as raw, 1 Reddit extraction failed, 1 Ramp/Revelio primary source could not be resolved cleanly.
|
||||
- Raw articles saved: 4
|
||||
- `raw/articles/agent-oriented-cli-zenn-2026.md` — score 4 — https://zenn.dev/chot/articles/dca4889fa27d27
|
||||
- `raw/articles/microsoft-learn-agent-architecture-sdlc-2026.md` — score 3 — https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/
|
||||
- `raw/articles/boj-ai-legal-risk-financial-institutions-2026.md` — score 3 — https://www.imes.boj.or.jp/research/abstracts/japanese/kk45-1-2.html
|
||||
- `raw/articles/amazon-s3-deep-dive-reinvent-2023.md` — score 2 — https://d1.awsstatic.com/events/Summits/reinvent2023/STG314_Dive-deep-on-Amazon-S3.pdf
|
||||
- Wiki pages created: 1
|
||||
- Wiki pages updated: 3 (`concepts/llm-wiki-pattern.md`, `concepts/wiki-maintenance-loop.md`, `index.md`)
|
||||
- Link-only / failed extraction: Obsidian Headless help (`defuddle` returned empty), alphaxiv 2606.25331 (`defuddle` returned empty), many X/t.co/media/news links below strict threshold.
|
||||
- `concepts/agent-oriented-cli-design.md`
|
||||
- Wiki pages updated: 3
|
||||
- `concepts/loop-engineering.md`
|
||||
- `concepts/ai-agent-identity-security.md`
|
||||
- `concepts/ai-developer-liability.md`
|
||||
- Index updated: `index.md`
|
||||
- Automation profile updated: `.automation/discord-link-ingest/interest-profile.md`
|
||||
- Rubric note: direct #chat shares about AI-agent toolmaking remain strong score-4 signals when they contain concrete implementation trade-offs; highlighted digest links about agent SDLC governance and Japanese AI legal-risk framing can update existing pages when a clean durable source is found. Generic deep infrastructure decks can be raw-only unless they connect to an active wiki concept.
|
||||
|
||||
## Processed high-signal URLs
|
||||
## Current run processed / notable URLs
|
||||
|
||||
- https://github.com/nashsu/llm_wiki
|
||||
- https://hermes-agent.nousresearch.com/docs/user-guide/skills/bundled/research/research-llm-wiki
|
||||
- https://github.com/emacsmirror/howm
|
||||
- https://github.com/Imbad0202/academic-research-skills
|
||||
- https://refactoringenglish.com/excerpts/write-an-effective-design-doc/
|
||||
- https://github.blog/developer-skills/github/i-automated-my-job-and-it-made-me-a-better-leader/
|
||||
- https://www.chinatalk.media/p/how-to-buy-cheap-claude-tokens-in
|
||||
- https://github.com/BRO3886/rem
|
||||
- https://obsidian.md/ja/help/headless
|
||||
- https://www.alphaxiv.org/abs/2606.25331
|
||||
### Raw saved
|
||||
|
||||
## Rubric note
|
||||
- https://zenn.dev/chot/articles/dca4889fa27d27 → `raw/articles/agent-oriented-cli-zenn-2026.md`
|
||||
- https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/ → `raw/articles/microsoft-learn-agent-architecture-sdlc-2026.md`
|
||||
- https://www.imes.boj.or.jp/research/abstracts/japanese/kk45-1-2.html → `raw/articles/boj-ai-legal-risk-financial-institutions-2026.md`
|
||||
- https://d1.awsstatic.com/events/Summits/reinvent2023/STG314_Dive-deep-on-Amazon-S3.pdf → `raw/articles/amazon-s3-deep-dive-reinvent-2023.md`
|
||||
|
||||
First ingest confirmed unusually dense interest in LLM Wiki / knowledge-management tooling (`llm_wiki`, Hermes bundled skill docs, howm, Obsidian Headless) from #chat. Keep scoring this cluster high, but continue strict wiki-page updates: create/update pages only for sources that directly change the LLM Wiki operating model; save adjacent workflow/security/dev-tool links as raw-only unless they connect to existing pages.
|
||||
### Link-only high-signal discovery context
|
||||
|
||||
- https://www.reddit.com/r/ClaudeAI/comments/1ujila1/anthropic_embedded_spyware_in_claude_code_and/ — direct #chat link, but Reddit extraction returned 403/empty and the claim is discussion-level/unverified.
|
||||
- Ramp/Revelio Labs AI-adoption/employment item from `https://t.co/ScBfS63kn3` — search surfaced X/a derivative article but not a clean primary source in this run.
|
||||
- GitHub Projects old-Android/Termux/Home-Assistant item from `https://t.co/zhvM7Y0eBS` — no clean durable source found during this run.
|
||||
|
||||
### Skipped or below current threshold
|
||||
|
||||
- X video/status-only links, routine macro/geopolitics/sports/news, media-only items, and routine security headlines without new durable pattern stayed below the current wiki threshold.
|
||||
|
||||
## Previously processed high-signal URLs
|
||||
|
||||
- https://zenn.dev/chot/articles/dca4889fa27d27
|
||||
- https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/
|
||||
- https://www.imes.boj.or.jp/research/abstracts/japanese/kk45-1-2.html
|
||||
- https://d1.awsstatic.com/events/Summits/reinvent2023/STG314_Dive-deep-on-Amazon-S3.pdf
|
||||
- https://mariozechner.at/posts/2025-11-30-pi-coding-agent/
|
||||
- https://github.blog/changelog/2026-06-26-github-desktop-3-6-worktrees-and-deeper-copilot-integration/
|
||||
- https://www.theregister.com/security/2026/06/29/nissan-says-oracle-peoplesoft-break-in-may-have-spilled-payroll-records-ssns/5263534
|
||||
- https://advisory.splunk.com/advisories/SVD-2026-0601
|
||||
- https://gigazine.net/news/20220630-fake-russian-history-chinese-wikipedia/
|
||||
- https://gigazine.net/news/20240630-state-of-terminal/
|
||||
- https://prtimes.jp/main/html/rd/p/000001248.000031579.html
|
||||
- https://forest.watch.impress.co.jp/docs/news/2120998.html
|
||||
- https://techcrunch.com/2026/06/29/arena-the-ai-leaderboard-everyone-uses-is-now-a-100m-business/
|
||||
- https://thehackernews.com/2026/06/oracle-e-business-suite-flaw-cve-2026.html
|
||||
- https://www.meti.go.jp/press/2026/06/20260630005/20260630005.html
|
||||
- https://github.com/graykode/abtop
|
||||
- https://www.macrumors.com/2026/06/29/openclaw-ios-app/
|
||||
- https://forest.watch.impress.co.jp/docs/topic/special/2119037.html
|
||||
- https://www.mhlw.go.jp/stf/shingi/0000516275_00006.html
|
||||
- https://www.city.wakayama.wakayama.jp/_res/projects/default_project/_page_/001/066/652/1221-2.pdf
|
||||
- https://arxiv.org/html/2606.28279v1
|
||||
- https://www.wolfssl.com/wolftpm-add-tpm-2-0-v1-85-pqc-post-quantum-support/
|
||||
- https://github.com/yutakobayashidev/edcb-tools
|
||||
- https://www.404media.co/wikipedia-cofounder-larry-sanger-banned-from-site-for-canvassaing/
|
||||
- https://www.sbbit.jp/article/cont1/177512
|
||||
- https://www.ses.com/network-and-technology/meo/meosphere
|
||||
- https://github.com/cicd-sensor/cicd-sensor
|
||||
- https://dev.classmethod.jp/articles/aws-finops-agent-preview/
|
||||
- https://github.com/sopaco/deepwiki-rs
|
||||
- https://nesbitt.io/2026/06/25/scrutineer.html
|
||||
- https://unit.aist.go.jp/rihsa/daax/d_cns_standardization.html
|
||||
- https://www.itmedia.co.jp/news/articles/2606/30/news133.html
|
||||
- https://gigazine.net/news/20250630-oracle-deno-javascript/
|
||||
- https://developers.openai.com/codex/agent-approvals-security
|
||||
- https://a11y-chiba.com/2026/
|
||||
- https://www.preferred.jp/ja/news/pr20260622
|
||||
|
||||
## Earlier rubric note
|
||||
|
||||
First ingest confirmed unusually dense interest in LLM Wiki / knowledge-management tooling (`llm_wiki`, Hermes bundled skill docs, howm, Obsidian Headless) from #chat. Subsequent catch-up runs confirmed repeated durable interest in autonomous agent loops, verification/evaluator separation, MCP/agent identity security, practical dev-infra sources, information-integrity / knowledge-governance sources, public/civic infrastructure uses of AI, private/local AI workflows, and AI-agent operator observability. Recent runs add evidence for: agent-native work surfaces such as Kiro; AI evaluation as operational/commercial infrastructure; code-to-doc/Wiki generators such as Litho; human-gated AI security workflows that avoid maintainer overload; avatar/XR standardization when it connects interface design, public standards, and user representation; local agent sandbox/network controls; accessibility implementations that convert sensory information across vibration, light, text, sign language, and public-space displays; minimal, observable agent harnesses that make context/session/process state inspectable; and agent-oriented CLI design that makes usage guides, structured output, errors, and stale-state hints explicit for coding agents.
|
||||
|
||||
@@ -0,0 +1,35 @@
|
||||
---
|
||||
title: Agent-Oriented CLI Design
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [agent, cli, dev-tool, workflow, quality]
|
||||
sources: [raw/articles/agent-oriented-cli-zenn-2026.md, raw/articles/microsoft-learn-agent-architecture-sdlc-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Agent-Oriented CLI Design
|
||||
|
||||
Agent-oriented CLI design は、人間が目で読んで試行錯誤する端末道具ではなく、Claude Code などの [[loop-engineering|agent loop]] が安全に呼び出し、結果を機械的に判断し、次の行動へ進めるための CLI 設計。Zenn の「AI エージェント向け CLI ツール」記事は、Claude Code 用の横断検索 CLI を Go で作った経験から、人間向け CLI と違う判断基準を整理している。
|
||||
|
||||
重要なのは、エージェントに「推測させない」こと。使い方は wiki や skill 側へ長く写すのではなく、CLI 自体に `skill` や help サブコマンドとして同梱し、スキーマや出力の意味が実装と一緒に更新されるようにする。これは [[wiki-maintenance-loop]] の raw/source と synthesis を分ける考え方にも近く、手順が古くなる場所を減らす設計である。
|
||||
|
||||
## 設計原則
|
||||
|
||||
- **JSON first**: 人間向けの整形テキストではなく、既定で構造化 JSON を返す。結果には `id`、`title`、`snippet`、`source_url`、`synced_at`、`is_stale` など、エージェントが次の判断に使う材料を入れる。
|
||||
- **Actionable errors**: `index is missing` だけで止めず、`run super-cli-tool sync` のように次のコマンドを直接書く。小さいモデルほど推測の余地を減らす効果が大きい。
|
||||
- **Search then read**: 重い本文取得と軽い候補検索を分ける。まず `search` で候補を絞り、必要なものだけ `read` する方が、トークン・時間・判断負荷を抑えやすい。
|
||||
- **Defaults over flags**: `--sources` や `--discover` のような細かい選択肢を増やすより、よく使う安全な既定値へ寄せる。フラグが多いほど help が長くなり、エージェントの分岐も増える。
|
||||
- **Governance hooks**: Microsoft Learn の agent architecture / SDLC module は、agent task を input / output / success criteria で構造化し、PR template、checks、CODEOWNERS、rules、environment gate、observability、tool governance、secret boundary を運用設計へ入れることを強調する。CLI も単独の便利道具ではなく、[[ai-agent-identity-security]] や PR governance に接続される実行面として見るべき。
|
||||
|
||||
## なぜ重要か
|
||||
|
||||
エージェント向け CLI は、単に「CLI を LLM から呼べるようにする」だけでは足りない。出力が曖昧だったり、エラーが不親切だったり、状態の鮮度が返らなかったりすると、agent loop は誤った仮定のまま進む。逆に、CLI が状態・出典・次アクション・失敗理由を明示すれば、[[loop-engineering]] の verification と persistence が自然に強くなる。
|
||||
|
||||
この設計は Hermes の skill にも当てはまる。skill は長い操作説明を抱え込むより、実際の CLI が `--help` や `agent-guide` を返せるならそこへ誘導し、skill 側は「いつ使うか」と「安全境界」を中心に保つ方が、ツール更新とのずれを減らせる。
|
||||
|
||||
## Open Questions
|
||||
|
||||
- CLI 側の `agent-guide` は人間向け help と別にすべきか、それとも同じ help を機械可読に拡張すべきか。
|
||||
- JSON schema、exit code、retryability、rate-limit 情報をどこまで標準化すれば、複数 agent / tool 間で再利用できるか。
|
||||
- [[abtop]] のような operator UI は、個々の CLI 実行ログや stale 状態をどこまで横断可視化すべきか。
|
||||
@@ -0,0 +1,28 @@
|
||||
---
|
||||
title: Agentic Hardware Design
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [llm, agent, automation, dev-tool, evaluation, quality]
|
||||
sources: [raw/articles/horizon-agentic-hardware-design-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Agentic Hardware Design
|
||||
|
||||
Agentic hardware design は、RTL や検証資産を一回のコード生成ではなく、実行可能な評価器を持つリポジトリ上でエージェントが反復修正する設計方法として扱う考え方。NVIDIA Research の HORIZON 論文は、ハードウェア設計問題を Markdown harness から project pack に変換し、隔離された git worktree、実行可能 evaluator、acceptance predicate、git/runtime policy を組み合わせて、手放しの agent loop で RTL benchmark を収束させる。
|
||||
|
||||
[[loop-engineering]] との違いは、対象が一般の作業ループではなく、RTL・testbench・checker・assertion・debugging といった EDA/ハードウェア設計成果物そのものに寄っている点。HORIZON は git diff、commit、log、notes を状態管理と trace buffer として使い、候補変更を evaluator evidence で受け入れるか拒否する。これは [[ai-research-automation]] のような収集・報告ループよりも、評価器と受理条件が強く組み込まれた self-evolution 型の運用である。
|
||||
|
||||
## 見るべき軸
|
||||
|
||||
- **Repository as task substrate**: 問題をプロンプトではなく、評価器付きの git worktree として渡す。履歴、diff、commit、replay がそのまま agent の探索記録になる。
|
||||
- **Markdown harness**: 人間が目的、領域知識、期待成果物、評価基準を Markdown で書き、bootstrap agent が project pack に変換する。これは [[llm-wiki-pattern]] の「Markdown を持続的な知識媒体にする」発想と近いが、出力先は wiki ではなく実行可能な設計タスクである。
|
||||
- **Executable feedback**: RTL では構文の正しさだけでなく、simulation、coverage、assertion、checker などが収束条件になる。生成物は「それらしい」だけでは足りず、実行証拠で受理される必要がある。
|
||||
- **Benchmark saturation vs robustness**: HORIZON は複数 RTL benchmark を 100% completion まで進めた一方、論文自身も reward hacking、hidden tests、独立 reference model、formal equivalence などを未解決課題として挙げている。[[wiki-maintenance-loop]] と同じく、見える評価器に過適合しない設計が重要になる。
|
||||
|
||||
## Open Questions
|
||||
|
||||
- ハードウェア設計 agent で、修復時に見せる診断情報と最終評価に使う hidden / randomized checks をどう分けるべきか。
|
||||
- PPA 最適化や signoff のように評価が遅い領域で、短い edit-evaluate loop をどう置き換えるか。
|
||||
- 個人・小規模チームの開発者道具に、HORIZON 的な git-native trace と acceptance gate をどこまで軽量に持ち込めるか。
|
||||
@@ -0,0 +1,36 @@
|
||||
---
|
||||
title: AI Agent Identity Security
|
||||
created: 2026-06-29
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [agent, security, reliability, privacy]
|
||||
sources: [raw/articles/okta-cross-app-access-partners-2026.md, raw/articles/openai-codex-agent-approvals-security-2026.md, raw/articles/microsoft-learn-agent-architecture-sdlc-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# AI Agent Identity Security
|
||||
|
||||
AI agent identity security は、AI エージェントやアプリ間連携が企業データへアクセスするときに、誰の権限で、何へ、どの範囲で、どの操作をしたのかを追跡・制御する設計領域。Okta の Cross App Access(XAA)発表は、MCP 認証拡張としての Enterprise-Managed Authorization を含め、エージェント時代の認可を OAuth とアイデンティティ管理の延長で標準化しようとする動きとして読める。
|
||||
|
||||
問題の出発点は、AI エージェントの接続が静的 API key やユーザーごとの同意画面に依存しがちなこと。これだと、常時特権、見えない同意、監査できないアプリ間移動が起こりやすい。XAA は、すべての接続を中央のアイデンティティポリシーに通し、アクションをログに残し、必要最小限のスコープ付き token を使う方向を示している。
|
||||
|
||||
## 見るべき軸
|
||||
|
||||
- **Agent as requesting app**: Claude、Cursor、Docker、VS Code、Zoom など、作業を始めるエージェントや開発者道具が、別アプリへのアクセスを要求する主体になる。
|
||||
- **Resource app / MCP server**: Asana、Atlassian、Figma、Linear、Slack、Supabase、Datadog などが、エージェントに文脈や業務データを渡す側になる。
|
||||
- **Policy and audit**: アクセスが許可される前に企業ポリシーで検査し、操作の監査証跡を残す。これは [[loop-engineering]] の persistence と verification をセキュリティ境界へ移したものでもある。
|
||||
- **Least privilege for agents**: 常時広い権限を持つ bot token ではなく、必要な範囲に絞った identity-based token を使う。
|
||||
- **Local sandbox / approval boundary**: Codex の安全運用ドキュメントは、cloud では隔離 container、CLI/IDE では OS sandbox と approval policy を組み合わせ、既定で network access を切り、workspace 外の編集や network 利用を承認対象にする設計を説明している。`workspace-write`、`read-only`、network proxy、domain allow/deny などの設定は、企業の cross-app 認可だけでなく個人の agent loop でも「どこまで自動実行してよいか」を明示する制御面になる。
|
||||
- **Repository governance as identity boundary**: Microsoft Learn の agent architecture / SDLC module は、agent task を input / output / success criteria で定義し、PR template、checks、CODEOWNERS、rules、environment gate を通じて「どの変更が誰の承認で通るか」を設計する。これは [[agent-oriented-cli-design]] の tool-level clarity と同じく、agent の行動を監査可能な境界へ置く方法である。
|
||||
|
||||
## なぜ重要か
|
||||
|
||||
エージェントが社内システム、開発環境、デザイン、会議、監視、データベースを横断し始めると、便利さと同じ速度で攻撃面も広がる。[[ai-assisted-reverse-engineering]] のように専門道具へ書き込み権限を渡す場合や、[[wiki-maintenance-loop]] のように自動で source を保存・分類する場合でも、「どの agent が何をしたか」を後で説明できることが信頼性の条件になる。
|
||||
|
||||
この論点は [[ai-developer-liability]] とも接続する。事故や漏えいが起きたとき、単にユーザーの操作やモデル出力だけでなく、開発者がどの権限境界、ログ、承認、取り消し手段を設計していたかが問われる可能性がある。
|
||||
|
||||
## Open Questions
|
||||
|
||||
- 個人用 Hermes / Discord / wiki 自動化では、企業向け XAA の考え方をどこまで軽量化して使えるか。
|
||||
- MCP server と agent gateway の認可ログを、開発者が後から読める形でどこに保存するべきか。
|
||||
- 便利な cross-app agent workflow と、ユーザーが理解できる同意・取り消し UI をどう両立するか。
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
title: AI Developer Liability
|
||||
created: 2026-06-28
|
||||
updated: 2026-06-28
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [law, public-interest, privacy, security, data-protection]
|
||||
sources: [raw/articles/ravi-naik-awo-profile-2026.md]
|
||||
sources: [raw/articles/ravi-naik-awo-profile-2026.md, raw/articles/boj-ai-legal-risk-financial-institutions-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
@@ -29,3 +29,5 @@ AI developer liability は、AI の出力や利用者の行為だけでなく、
|
||||
AI 開発者の責任は、個別の事故対応にとどまらない。責任の線引きが変わると、AI サービスの安全設計、公開前の検証、記録の保存、通報対応、規制当局との関係が変わる。特に、性的画像、選挙、報道、内部告発、広告技術のように、個人の被害と公共の議論が同時に現れる領域では、[[information-integrity]] と法制度の両方から追う必要がある。
|
||||
|
||||
現時点ではこのページは Ravi Naik / AWO profile という単一資料からの入口であり、具体的な法理や裁判上の争点は今後の資料で補う必要がある。
|
||||
|
||||
日本銀行金融研究所の「金融機関におけるAI利用に伴う私法上のリスクと管理」は、個人被害や deepfake とは別の角度から、金融機関が AI 開発者・提供者に契約責任を追及する場合、AI を使ったサービスを顧客へ提供する場合、組織内部で取締役が AI ガバナンス体制を構築する場合を整理している。ここでは AI 開発者責任は不法行為だけでなく、契約条項、顧客との説明・合意、内部統制としても現れる。これは [[ai-agent-identity-security]] の権限境界や監査ログが、事故後の説明責任だけでなく契約上の管理義務にも関わることを示す。
|
||||
|
||||
@@ -0,0 +1,28 @@
|
||||
---
|
||||
title: AI Evaluation Infrastructure
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [evaluation, llm, quality, workflow]
|
||||
sources: [raw/articles/arena-ai-leaderboard-business-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# AI Evaluation Infrastructure
|
||||
|
||||
AI evaluation infrastructure は、LLM や agent の性能を、単発 benchmark ではなく、利用者評価、専門タスク、分析サービス、商用フィードバックループとして継続的に測る層。TechCrunch の Arena 記事では、UC Berkeley の研究プロジェクト由来の AI leaderboard が、1,000 万件超の利用者評価をもとにした公開ランキングから、モデル企業や企業向けの深掘り分析サービスへ広がり、商用開始から 8 カ月で年換算 1 億ドル規模に到達したとされる。
|
||||
|
||||
重要なのは、評価が単なる研究補助ではなく、モデル改善・post-training・企業導入判断の市場そのものになっている点。Arena は text、coding、vision、image generation に加え、Agent Mode のような長時間 workflow も扱う。これは [[loop-engineering]] や [[agentic-hardware-design]] のようなエージェント運用で、最終成果だけでなく、途中の意思決定・失敗・回復をどう測るかという問題に接続する。
|
||||
|
||||
## なぜ重要か
|
||||
|
||||
- **Crowdsourced comparison**: 利用者が 2 つのモデル出力を比較する形式は、静的な benchmark では拾いにくい実利用の好みを集められる。
|
||||
- **Evaluation as business**: 無料 leaderboard の背後で、詳細分析や model lab 向け評価が商用サービスになる。
|
||||
- **Post-training demand**: Arena は、人間評価やラベリングを提供する Mercor、Surge、Scale AI などと同じ予算を争うと説明されており、評価と訓練改善が近づいている。
|
||||
- **Agent evaluation**: 長時間 workflow や Agent Mode が評価対象になると、[[wiki-maintenance-loop]] のような自走ジョブでも、単一回答の品質ではなく状態更新・検証・永続化まで測る必要が出る。
|
||||
|
||||
## Open Questions
|
||||
|
||||
- 公開 leaderboard の人気と、商用分析の顧客価値はどこまで同じ評価データに依存しているのか。
|
||||
- Agent Mode のような長時間タスクでは、勝敗や好みだけでなく、再現性、コスト、安全な権限利用、監査証跡をどう評価するべきか。
|
||||
- 個人用 wiki や Hermes job では、大規模な人間評価を使わずに、どの小さな evaluator を積み重ねれば品質劣化を検出できるか。
|
||||
@@ -0,0 +1,27 @@
|
||||
---
|
||||
title: Avatar Standardization
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [design, interface, public-interest, inclusive-design]
|
||||
sources: [raw/articles/aist-avatar-standardization-committee-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Avatar Standardization
|
||||
|
||||
アバター標準化は、XR やメタバースで使われる仮想身体を、単なるキャラクター表現ではなくユーザインターフェースとして扱う設計課題。産総研の「アバター国際標準化の国内検討委員会」は、ISO/IEC JTC1/SC35 におけるユーザインターフェースとしてのアバター規格開発に対し、国内の業界やユーザの声を集め、提言や助言を行うための委員会として説明されている。
|
||||
|
||||
この論点は [[inclusive-design]] と近い。アバターは「なりたい姿」や文化表現であると同時に、サービス側がユーザに何を許し、どの情報を相手に伝え、どんな身体差・文化差を扱うかを決める interface でもある。公共空間の標識や合図を扱う [[meaning-making-marks]] と同じく、見た目が周囲の行動や解釈を変える。
|
||||
|
||||
## Design implications
|
||||
|
||||
- アバターの設計情報は、体験品質や安全性に影響するため、利用者と開発者の双方に意味のある規格が必要になる。
|
||||
- 委員会には VRM、通信、大学、企業、メタバース関連団体、VTuber/有識者などが含まれており、技術仕様だけでなく文化的実践を標準化に接続しようとしている。
|
||||
- 「アバター」は趣味文化の表現物であるだけでなく、XR サービス上の身体・本人性・可視性・相互行為の設計単位になる。
|
||||
|
||||
## Open questions
|
||||
|
||||
- 標準化が相互運用性を高める一方で、匿名性、変身、文化的遊びの余地を狭めないようにするにはどうするか。
|
||||
- アバターが本人性や属性を示すとき、[[information-integrity]] とプライバシーの境界をどう扱うか。
|
||||
- ユーザ側の声を集める委員会設計は、どの範囲の利用者を代表できるか。
|
||||
@@ -0,0 +1,33 @@
|
||||
---
|
||||
title: CI/CD Runtime Security
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [security, supply-chain, quality, reliability, automation]
|
||||
sources: [raw/articles/cicd-sensor-2026.md, raw/articles/scrutineer-oss-security-workflow-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# CI/CD Runtime Security
|
||||
|
||||
CI/CD runtime security is the practice of observing and constraining what actually runs inside build, test, release, and deployment jobs. The core problem is that CI jobs hold cloud credentials, signing keys, package-registry tokens, and deployment authority, while compromised dependencies or scripts can execute inside short-lived jobs and disappear with the evidence when the job ends. [[ai-agent-identity-security]] covers adjacent authorization and audit concerns for agents; [[loop-engineering]] is relevant because autonomous development loops often depend on these pipelines as their verification and deployment boundary.
|
||||
|
||||
## Why it matters
|
||||
|
||||
Traditional software supply-chain controls often answer where an artifact came from or how it was built, but they may not preserve enough runtime evidence about what a job process actually did. `cicd-sensor` frames this as an EDR-like gap for CI/CD: open-source defenders exist for many production runtimes, while CI/CD runners have lagged despite holding highly privileged credentials.^[raw/articles/cicd-sensor-2026.md]
|
||||
|
||||
## Implementation pattern
|
||||
|
||||
`cicd-sensor` uses an eBPF-powered sensor for GitHub Actions and GitLab CI/CD. Its baseline detections use process ancestry and correlated signals: for example, credential access by a process descended from `npm install`, or one job reading several credential categories. It can emit per-run logs, graphical job summaries, cloud-routed evidence, and build attestations while keeping data in the operator's own infrastructure rather than sending it to a project-operated SaaS.^[raw/articles/cicd-sensor-2026.md]
|
||||
|
||||
## Design implications
|
||||
|
||||
For Yuta-style automation, the useful distinction is not just "scan code before it runs" but "record and reason about privileged automation while it runs." Agentic coding systems, scheduled jobs, and deployment workflows should treat CI/CD runtime logs, provenance, and least-privilege boundaries as first-class product requirements. This connects to [[ai-agent-identity-security]] when agents need scoped credentials, and to [[wiki-maintenance-loop]] as an example of recurring automation that should be observable and auditable.
|
||||
|
||||
[[scrutineer]] extends the same supply-chain concern toward open-source vulnerability discovery and disclosure. Instead of watching CI runtime behavior, it uses skill-based AI scans, threat models, maintainer discovery, patch drafting, and release watching to keep unverified model findings inside a human-gated workflow before they reach maintainers.^[raw/articles/scrutineer-oss-security-workflow-2026.md]
|
||||
|
||||
## Open questions
|
||||
|
||||
- How should teams balance runtime blocking, forensic logging, and false positives in developer-facing pipelines?
|
||||
- What evidence format is durable enough to connect runtime traces with artifact provenance and code review history?
|
||||
- Where should CI/CD runtime controls live when agents can run locally, in cloud sandboxes, and inside hosted CI at different stages of one task?
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
title: Digital Gardening CMS
|
||||
created: 2026-06-28
|
||||
updated: 2026-06-28
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [wiki, knowledge-base, maintenance, markdown, design]
|
||||
sources: [raw/articles/principles-for-digital-gardening-2026.md]
|
||||
sources: [raw/articles/principles-for-digital-gardening-2026.md, raw/articles/litho-deepwiki-rs-code-documentation-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
@@ -20,6 +20,8 @@ confidence: medium
|
||||
|
||||
実装候補として、[[obsidian]] 的な手元優先の編集体験、Cosense 的な共同編集、Nuxt Content の Markdown と拡張構文、WordPress + WPGraphQL、HyperMD や Milkdown などの編集器が挙げられている。Git で全体を管理すると版管理は強くなるが、携帯端末での編集しやすさが弱くなるため、保存形式、同期、編集体験の折り合いが設計上の中心になる。
|
||||
|
||||
[[litho]] のようにコードベースから Wiki 風ドキュメントを生成する道具は、この CMS 発想をソフトウェア設計書側に寄せた例。人間が育てる庭とは違い、コード解析と CI/CD によって鮮度を保とうとするが、生成物をどうレビューし、どの情報を手で補うかは同じく設計問題として残る。
|
||||
|
||||
## Open Questions
|
||||
|
||||
- ページ型を単一にしたまま、公開状態・到達性・版管理をどう表すか。
|
||||
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
title: Inclusive Design
|
||||
created: 2026-06-28
|
||||
updated: 2026-06-28
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [accessibility, inclusive-design, public-interest, design]
|
||||
sources: [raw/articles/arun-japan-symbols-2026.md]
|
||||
sources: [raw/articles/arun-japan-symbols-2026.md, raw/articles/aist-avatar-standardization-committee-2026.md, raw/articles/accessibility-conference-chiba-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
@@ -16,6 +16,12 @@ confidence: medium
|
||||
|
||||
この資料で面白いのは、包摂性を個別の支援制度だけでなく、公共空間の情報設計として扱っている点。標識や札は、読める人だけに向けた文章ではなく、瞬時に見分けられる形と色で、周囲の行動を少し変える。公共の場で「何をすればよいか」を伝えるという意味では [[meaning-making-marks]] と重なり、社会的な判断材料を壊さず整えるという意味では [[information-integrity]] とも遠くつながる。
|
||||
|
||||
[[avatar-standardization]] は、包摂的な設計を XR/メタバース上の仮想身体にも広げる論点。アバターは外見、本人性、相互行為、文化表現を同時に担うため、ユーザ側と開発側の双方に意味のある規格を作る必要がある。
|
||||
|
||||
アクセシビリティカンファレンスCHIBA 2026 の案内は、包摂性を「講演で語るテーマ」だけでなく、会場設計と体験ブースに落とし込んでいる例として使える。通常版と情報保障版の YouTube 配信、手話通訳と UD トーク、バリアフリートイレやオストメイト設備の明記、平坦な導線・混雑・照明条件の説明は、参加前に必要な情報へ到達できること自体をアクセシビリティとして扱っている。^[raw/articles/accessibility-conference-chiba-2026.md]
|
||||
|
||||
同イベントの体験ブースでは、Ontenna が音の特徴を振動と光に変え、エキマトペが駅の音を AI で識別して文字・手話・オノマトペで可視化する。これは [[meaning-making-marks]] のような公共空間の記号設計を、聴覚・身体感覚・文字情報へまたがる multi-modal interface に広げる実装例として読める。^[raw/articles/accessibility-conference-chiba-2026.md]
|
||||
|
||||
## 見るべき問い
|
||||
|
||||
- 本人が詳細を説明しなくても、必要な配慮だけが伝わる合図をどう作るか。
|
||||
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
title: Information Integrity
|
||||
created: 2026-06-28
|
||||
updated: 2026-06-28
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [information-integrity, disinformation, public-interest, media, civic-tech]
|
||||
sources: [raw/articles/osome-observatory-on-social-media-2026.md, raw/articles/osome-tools-2026.md, raw/articles/maria-ressa-nobel-facts-2026.md, raw/articles/maria-ressa-stop-the-lies-2026.md, raw/articles/tbs-sns-metric-farms-election-disinformation-2026.md]
|
||||
tags: [information-integrity, disinformation, public-interest, media, civic-tech, knowledge-base]
|
||||
sources: [raw/articles/osome-observatory-on-social-media-2026.md, raw/articles/osome-tools-2026.md, raw/articles/maria-ressa-nobel-facts-2026.md, raw/articles/maria-ressa-stop-the-lies-2026.md, raw/articles/tbs-sns-metric-farms-election-disinformation-2026.md, raw/articles/wikipedia-sanger-canvassing-ban-2026.md, raw/articles/wikipedia-fake-russian-history-zhemao-2022.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
@@ -28,6 +28,18 @@ TBS NEWS DIG の「農場」取材は、偽情報の文章や画像だけでな
|
||||
|
||||
この点は、情報の完全性を「真偽」だけでなく「何が目立つよう設計され、誰がその見え方を買えるのか」という問題として扱う必要があることを示す。選挙期間中には、実際の多数派ではないものが多数派のように見える危険が高まり、規制・削除要請・透明性・表現の自由の均衡が論点になる。
|
||||
|
||||
## 知識基盤の統治と外部動員
|
||||
|
||||
Wikipedia の Larry Sanger ban 事例は、情報基盤の integrity が「偽情報を消す」だけではなく、編集・審議の手続きが外部の audience や政治的動員に飲み込まれないようにする統治でもあることを示す。404 Media の記事では、Sanger の WikiProject Intellectual Diversity 自体よりも、X の 91,000 followers を Wikipedia 内の議論へ誘導した off-wiki canvassing が問題視され、Wikipedia 側は consensus building と参加者保護の観点から indefinite ban に至ったと説明されている。
|
||||
|
||||
このケースは [[llm-wiki-pattern]] や [[wiki-maintenance-loop]] にも教訓がある。知識ベースは openness を価値にしつつも、編集権限、参加の境界、外部からの圧力、outing risk、AI-generated slop への耐性を設計しなければ、source の信頼性だけでなく synthesis の場そのものが壊れる。公開 wiki や community moderation を扱うときは、content policy と process integrity を分けて見る必要がある。
|
||||
|
||||
## 知識基盤で虚構が体系化されるリスク
|
||||
|
||||
中国語版 Wikipedia の Zhemao / 折毛事件は、情報の完全性が SNS 上の拡散だけでなく、百科事典型の knowledge-base でも壊れうることを示す。GIGAZINE の要約によれば、1人の編集者が 2010 年ごろから複数アカウントで実在の歴史・人物・国家間対立に架空の鉱山や事件を混ぜ込み、最終的に 206 件の記事と数百万語規模の「架空のロシア史」を中国語版 Wikipedia に作った。問題は単発の嘘ではなく、関連記事・脚注・文体・相互参照がそろったため、読者に体系として見えてしまった点にある。^[raw/articles/wikipedia-fake-russian-history-zhemao-2022.md]
|
||||
|
||||
このケースは [[llm-wiki-pattern]] と [[wiki-maintenance-loop]] にも直接関係する。知識ベースは、リンクや一貫した文体によって信頼感を作れる一方で、出典の存在確認、他言語・一次資料との照合、矛盾検出、編集者権限の分離が弱いと、もっともらしい synthesis が長期間残る。LLM が Wiki を更新する場合も、文章の自然さではなく source provenance と反証可能性を保つことが integrity の中心になる。
|
||||
|
||||
## 関連領域
|
||||
|
||||
この領域は、公共のための技術、報道、偽情報対策、SNS の設計、アクセシビリティ、民主主義の維持とつながる。OSoMe や Ressa のような資料は、流行のニュースとして消費するより、人物・組織・道具・概念に分けて蓄積すると後から参照しやすい。
|
||||
|
||||
@@ -0,0 +1,43 @@
|
||||
---
|
||||
title: Loop Engineering
|
||||
created: 2026-06-29
|
||||
updated: 2026-06-30
|
||||
type: concept
|
||||
tags: [agent, automation, workflow, quality]
|
||||
sources: [raw/articles/loop-engineering-anthropic-playbook-2026.md, raw/articles/github-issueops-state-machines-2026.md, raw/articles/horizon-agentic-hardware-design-2026.md, raw/articles/abtop-ai-coding-agent-monitor-2026.md, raw/articles/kiro-ide-1-0-agent-focus-2026.md, raw/articles/arena-ai-leaderboard-business-2026.md, raw/articles/pi-coding-agent-2025.md, raw/articles/github-desktop-3-6-worktrees-copilot-2026.md, raw/articles/agent-oriented-cli-zenn-2026.md, raw/articles/microsoft-learn-agent-architecture-sdlc-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Loop Engineering
|
||||
|
||||
Loop engineering は、LLM やエージェントを「人間が毎回プロンプトする道具」としてではなく、自分で次の仕事を見つけ、隔離された実行先へ渡し、別の評価者に検証させ、結果を永続化し、次回実行へつなぐループとして設計する考え方。PDF「Loop Engineering: The Anthropic Playbook for Designing Systems That Prompt Your Agents」は、prompt / context / harness engineering の上に来る第四層としてこの概念を置いている。
|
||||
|
||||
中心になる 1 ターンは、discovery、handoff、verification、persistence、scheduling の 5 段階。これは [[wiki-maintenance-loop]] の ingest / query / lint / log / cron にかなり近く、Discord link ingest のような自動キュレーションでは、リンク発見だけでなく評価基準、重複検出、raw 保存、wiki 更新、状態ファイル更新までを同じループの一部として扱う必要がある。
|
||||
|
||||
## 設計上の要点
|
||||
|
||||
- **Generator / evaluator separation**: 生成したエージェント自身に採点させると甘くなりやすい。別プロンプト、別モデル、別プロセスの「疑う評価者」を置く方が、[[ai-assisted-reverse-engineering]] の命名・型付け検査や wiki ingest の品質判定にも応用しやすい。
|
||||
- **Persistence first**: ループの成果はチャットの返答だけでなく、PR、Issue、wiki、state file、log のような再利用可能な場所に残す。残らない自動化は、次回の discovery と評価に使えない。
|
||||
- **State machine として考える**: GitHub の IssueOps 記事は、Issue、label、comment、approval、Action を状態機械として扱う。これは loop engineering の persistence と scheduling を、監査可能な GitHub timeline に置く方法として読める。
|
||||
- **Repository-native loop**: [[agentic-hardware-design]] の HORIZON は、Markdown harness から evaluator / acceptance predicate / git policy を持つ project pack を作り、隔離された worktree 上の diff・commit・log・notes をそのまま探索 trace にする。ループの状態を外部データベースに逃がさず、作業対象の repository 自体に残す設計として重要。
|
||||
- **Operator observability**: [[abtop]] は Claude Code、Codex CLI、OpenCode の session、token、context、rate limit、child process、open port をローカルで可視化する。複数 agent を同時に回す loop では、成果物だけでなく「いま何が動いているか」「どの資源を占有しているか」も運用対象になる。
|
||||
- **Agent-native work surface**: [[kiro]] の Agent Focus は、コード編集画面ではなく session、会話、spec、diff を前面に置く。loop を IDE の中に寄せると、人間の仕事は直接編集よりも、仕様・承認・差分確認・権限ルールの管理へ移る。
|
||||
- **Agent harness minimalism**: [[pi-coding-agent]] は、read / write / edit / bash、tmux、明示的な session file など既存の可視な道具に寄せることで、隠れた sub-agent や巨大な system prompt に頼らない loop を作ろうとする。loop の強さは機能数だけでなく、operator が context、tool result、process、cost をどこまで観測できるかにも依存する。
|
||||
- **Worktrees as everyday agent infrastructure**: GitHub Desktop 3.6 の worktree support は、agent が複数 branch / sandbox を使う流れを GUI 側にも取り込む。isolated worktree は [[agentic-hardware-design]] や IssueOps 的な repository-native loop と同じく、並列作業を見える単位に分けるための基礎部品になる。
|
||||
- **Evaluator market pressure**: [[ai-evaluation-infrastructure]] の Arena 事例は、評価が研究用 leaderboard から商用分析・post-training 改善の基盤へ広がっていることを示す。loop engineering でも、実行する agent だけでなく、それを測る evaluator とデータ収集の設計が競争力になる。
|
||||
- **Agent-oriented tools**: [[agent-oriented-cli-design]] は、JSON first、actionable error、search/read 分離、鮮度情報、少ないフラグを通じて、agent が推測せずに次の行動へ進める CLI を作る考え方。loop の実行単位である tool が曖昧だと、verification や persistence 以前に誤った状態で進んでしまう。
|
||||
- **Human judgment is scarce**: 生成は安くなっても、何を通し、何を止め、何を記録するかの判断は希少になる。自動化は人間の判断を消すのではなく、判断すべき点を狭く明確にするべき。
|
||||
|
||||
## Failure Modes
|
||||
|
||||
- **Nodding loop**: 自己承認しているだけで、独立した検証がない。
|
||||
- **Amnesiac loop**: 前回の状態、失敗、採用・却下理由が保存されず、毎回同じ判断をやり直す。
|
||||
- **Manual loop**: 実行自体が人間の思いつきに依存し、定期実行・イベント駆動になっていない。
|
||||
- **Blind loop**: 何を探すか、何を高く評価するかが固定され、発見結果から rubric が改善されない。
|
||||
- **Tangled loop**: 並列エージェントや自動 PR が同じ資源を同時に触り、検証や rollback が追いつかない。
|
||||
|
||||
## Open Questions
|
||||
|
||||
- Hermes の scheduled job では、どの変更を即時実行し、どの変更を review item として止めるべきか。
|
||||
- [[ai-agent-identity-security]] のような認可・監査の標準を、個人用エージェントのローカル自動化にもどう縮小適用するか。
|
||||
- IssueOps や [[llm-wiki-pattern]] のような永続メディアを、チャット駆動の一時的な作業とどう接続するか。
|
||||
@@ -1,10 +1,10 @@
|
||||
---
|
||||
title: Wiki Maintenance Loop
|
||||
created: 2026-06-28
|
||||
updated: 2026-06-28
|
||||
updated: 2026-06-29
|
||||
type: concept
|
||||
tags: [workflow, maintenance, wiki, agent]
|
||||
sources: [raw/articles/karpathy-llm-wiki-2026.md, raw/articles/hermes-research-llm-wiki-skill-2026.md, raw/articles/nashsu-llm-wiki-2026.md, raw/articles/tokium-self-evolving-ai-researcher-2026.md]
|
||||
sources: [raw/articles/karpathy-llm-wiki-2026.md, raw/articles/hermes-research-llm-wiki-skill-2026.md, raw/articles/nashsu-llm-wiki-2026.md, raw/articles/tokium-self-evolving-ai-researcher-2026.md, raw/articles/loop-engineering-anthropic-playbook-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
@@ -25,3 +25,5 @@ Hermes の `llm-wiki` skill では、毎回 `SCHEMA.md`、`index.md`、recent `l
|
||||
[[llm-wiki-app]] はこの loop をアプリ側の persistent ingest queue、folder auto-watch、source cleanup、graph/search、MCP/API に拡張している。つまり maintenance loop は単なる checklist ではなく、agent procedure と product feature のどちらにもなりうる。
|
||||
|
||||
TOKIUM の [[ai-research-automation]] 事例は、wiki ではなく技術動向の報告作成でも同じ考え方が使えることを示している。検索語や巡回先を固定せず、採用された情報源を評価して候補を昇格・降格させることで、収集対象そのものを手入れの対象にしている。
|
||||
|
||||
[[loop-engineering]] の観点では、この maintenance loop は「発見 → handoff → 検証 → 永続化 → scheduling」を持つ小さな自走ループでもある。特に Discord link ingest では、良さそうなリンクを全部入れるのではなく、interest profile、重複検出、raw hash、index/log/state 更新を通じて、次回の判断材料を残すことが品質維持の中心になる。
|
||||
|
||||
@@ -0,0 +1,24 @@
|
||||
---
|
||||
title: abtop
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: entity
|
||||
tags: [tool, agent, dev-tool, automation, workflow]
|
||||
sources: [raw/articles/abtop-ai-coding-agent-monitor-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# abtop
|
||||
|
||||
abtop は、Claude Code、Codex CLI、OpenCode などの AI coding agent セッションを、`btop` のような端末 UI で横断監視するローカル道具。複数プロジェクトでエージェントを同時に走らせるときに、token usage、context window、rate limit、child process、open port、git status などを一画面で見るためのものとして設計されている。[[loop-engineering]] で問題になる「並列ループの見えなさ」を、まずローカル観測可能性として扱う実装例である。
|
||||
|
||||
## 見るべき点
|
||||
|
||||
- **read-only first**: README は「No API keys, no auth」とし、ローカルファイル・プロセス・open-file metadata を読むだけだと説明している。これは [[ci-cd-runtime-security]] のような実行時観測と近いが、対象は CI runner ではなく個人の agent 作業環境である。
|
||||
- **agent-specific telemetry**: Claude Code / Codex CLI / OpenCode ごとに session discovery、token tracking、context window、status、rate limit、children / ports などの対応状況を分けている。単なる process monitor ではなく、AI coding agent の失敗モードに寄せた監視面になっている。
|
||||
- **operator workflow**: `abtop --once` や `abtop --json` は、TUI だけでなく script や dashboard にも状態を渡せる。[[wiki-maintenance-loop]] のような scheduled job でも、将来的には実行中 agent の状態を別ループの入力にする余地がある。
|
||||
- **privacy boundary**: JSON snapshot は local dashboard 用の rich data を含み、working directory、tool-call preview、bounded/redacted chat text などを含み得るため、共有ログやネットワーク公開には追加の access control が必要だと README は明記している。
|
||||
|
||||
## Why it matters
|
||||
|
||||
Yuta のエージェント運用では、エージェント数が増えるほど「何が動いているか」「どの port を開いたままか」「rate limit や context が詰まっていないか」が品質・安全性の一部になる。abtop は、AI agent を便利な生成器としてだけでなく、観測・中断・移動・監査の対象として扱う方向を示している。
|
||||
@@ -0,0 +1,29 @@
|
||||
---
|
||||
title: Kiro
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: entity
|
||||
tags: [tool, agent, dev-tool, workflow]
|
||||
sources: [raw/articles/kiro-ide-1-0-agent-focus-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Kiro
|
||||
|
||||
Kiro は Amazon の仕様駆動型 AI コーディング環境。開発者が仕様を定め、AI エージェントが実装タスクを分解し、人間が実行と承認を制御する前提の IDE / CLI / Web / iOS の道具群として説明されている。v1.0 では、従来の「コードを中心にしたエディタ」よりも、セッション、会話、spec、diff を中心に置く Agent Focus レイアウトが強調された。
|
||||
|
||||
[[loop-engineering]] の観点では、Kiro は仕様、タスク、差分、実行履歴、承認を作業画面に残すことで、エージェント作業を単発チャットではなく状態を持つ開発ループに近づけている。[[abtop]] が複数エージェントの外側から運用状態を観測する道具だとすると、Kiro は IDE 内にエージェント操作面を寄せる設計と言える。
|
||||
|
||||
## 重要な設計要素
|
||||
|
||||
- **Spec-driven workflow**: 仕様を起点に、AI エージェントが大小のタスクを立案し、人間が実行を制御する。
|
||||
- **Agent Focus**: 左にセッション、中央に会話、右に spec / diff を置き、コード編集よりエージェント指示を前面に出す。
|
||||
- **Capability-based permissions**: ファイル書き込み、コマンド実行、MCP ツール呼び出しなどを操作ごとに承認し、許可・拒否のルールを保存できる。これは [[ai-agent-identity-security]] の最小権限・監査の論点に近い。
|
||||
- **Markdown custom agents**: 専用エージェントを Markdown で定義し、MCP サーバーや権限ルールをプロフィールに埋め込める。
|
||||
- **Natural-language hooks**: ファイル保存や作成などを契機に、自然言語で定義したフックを自動化へ変換する。
|
||||
|
||||
## 見るべき問い
|
||||
|
||||
- Agent Focus 型 UI は、開発者がコードではなくエージェント操作を主作業にする流れを本当に強めるのか。
|
||||
- 承認ルールやカスタムエージェント定義をチームで共有したとき、便利さと権限管理の境界はどこで崩れやすいか。
|
||||
- [[ci-cd-runtime-security]] のような実行時監査と、IDE 内のエージェント承認ログをどう接続できるか。
|
||||
@@ -0,0 +1,28 @@
|
||||
---
|
||||
title: Litho
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: entity
|
||||
tags: [tool, wiki, knowledge-base, markdown, dev-tool, automation]
|
||||
sources: [raw/articles/litho-deepwiki-rs-code-documentation-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Litho
|
||||
|
||||
Litho(`deepwiki-rs`)は、ソースコードから C4 model のアーキテクチャ図と Wiki 風ドキュメントを自動生成する Rust 製の AI 文書化エンジン。README では、コードベース解析、依存関係・構造抽出、LLM によるドキュメント生成、Mermaid 図、CI/CD 連携、外部知識の取り込みを特徴としている。
|
||||
|
||||
Yuta の Wiki 文脈では、これは [[digital-gardening-cms]] や [[llm-wiki-pattern]] と同じ「読むたびに都度検索する」のではなく、「コードから持続的に読める知識面を作る」方向の道具。ただし Litho は人間の研究 Wiki というより、コードベース理解・オンボーディング・設計書の鮮度維持に寄っている。
|
||||
|
||||
## Design implications
|
||||
|
||||
- 設計書が腐る問題を、手書きドキュメントではなくコード解析と生成のループで扱う。
|
||||
- C4 の context/container/component/code レベルを出力するため、単なる README 生成よりも構造化された設計理解を狙う。
|
||||
- CI/CD で毎コミット生成できると説明しており、[[wiki-maintenance-loop]] 的な継続更新をソフトウェア設計書に適用する例になる。
|
||||
- 生成物は便利だが、アーキテクチャ判断の正しさや命名の妥当性は別途レビューが必要。自動生成 Wiki は、信頼できる最終文書というより、保守される下書き・索引として扱うのが安全。
|
||||
|
||||
## Open questions
|
||||
|
||||
- 生成された C4 図や説明が、実際の設計意図とずれたときに誰がどう検証するか。
|
||||
- コードから抽出できない運用上の制約、歴史的経緯、暗黙の責務をどこで補うか。
|
||||
- LLM 生成ドキュメントを CI/CD に組み込む場合、差分レビューとノイズ抑制をどう設計するか。
|
||||
@@ -0,0 +1,24 @@
|
||||
---
|
||||
title: pi-coding-agent
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: entity
|
||||
tags: [tool, agent, dev-tool, cli, workflow]
|
||||
sources: [raw/articles/pi-coding-agent-2025.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# pi-coding-agent
|
||||
|
||||
pi-coding-agent は、Mario Zechner が自分のために作った最小主義の AI coding agent harness。[[loop-engineering]] で重要になる context control、session serialization、provider handoff、token/cost tracking、headless JSON/RPC、HTML export などを、巨大な隠れ system prompt や不可視の sub-agent に寄せず、自分で観測・改造できる形に置くことを重視している。
|
||||
|
||||
## 設計上の特徴
|
||||
|
||||
- **小さい agent surface**: read / write / edit / bash を中心に、1000 token 未満の system prompt と最小の tool set で成立させようとする。これは [[abtop]] のような外部観測や、tmux での明示的なプロセス管理と相性がよい。
|
||||
- **provider abstraction**: `pi-ai` は Anthropic、OpenAI、Google、OpenAI-compatible provider などをまたいだ streaming、tool calling、thinking/reasoning、context handoff を扱う。各 provider の API 差分や token accounting の不安定さを、個人用に十分な粒度で吸収する設計になっている。
|
||||
- **context engineering first**: 既存 harness が裏で何を context に入れているか見えにくいことを問題視し、session format、tool result、UI 表示用 details を分けて扱う。これは [[ai-agent-identity-security]] の権限・監査論点とは別方向の、運用者が何を見て判断できるかという安全性である。
|
||||
- **terminal-native UI**: `pi-tui` は scrollback を活かす append 型 TUI と differential rendering を選び、full-screen TUI より端末本来の検索・スクロールに寄せる。coding agent をチャット型の線形作業として扱う判断が、実装の単純さにつながっている。
|
||||
|
||||
## Why it matters
|
||||
|
||||
Yuta の関心から見ると、pi-coding-agent の価値は「また一つ coding agent が増えた」ことではなく、agent harness をどこまで小さく、見える形で、ファイル・端末・tmux・README という既存道具に寄せられるかを実装で示している点にある。MCP や sub-agent、background bash、built-in todo をあえて持たない判断は、[[wiki-maintenance-loop]] のような自動化でも「状態をどこに残し、誰が見られるか」を考える材料になる。
|
||||
@@ -0,0 +1,33 @@
|
||||
---
|
||||
title: Scrutineer
|
||||
created: 2026-06-30
|
||||
updated: 2026-06-30
|
||||
type: entity
|
||||
tags: [tool, security, supply-chain, automation, quality, human-in-the-loop]
|
||||
sources: [raw/articles/scrutineer-oss-security-workflow-2026.md]
|
||||
confidence: medium
|
||||
---
|
||||
|
||||
# Scrutineer
|
||||
|
||||
Scrutineer は、オープンソースリポジトリを AI 支援で脆弱性スキャンし、検証、連絡先特定、修正案、開示、リリース確認までを一つのワークフローで扱うローカルツール。James Nesbitt の紹介記事では、LLM が脆弱性らしきものを大量に見つけられるようになった一方で、未検証の報告がメンテナの注意を消耗する問題を避けるため、モデルの出力を直接メンテナに送らない設計が強調されている。
|
||||
|
||||
この道具は [[ci-cd-runtime-security]] と同じ供給網防御の文脈にあるが、焦点は CI ジョブの実行時監視ではなく、OSS の脆弱性探索・検証・開示を人間のゲート付きで運用することにある。AI エージェントがコードを読む力を、[[ai-agent-identity-security]] 的な権限管理だけでなく、誰に何をいつ報告するかという社会的境界にも接続している。
|
||||
|
||||
## Workflow pattern
|
||||
|
||||
- スキャンは `SKILL.md`、JSON schema、補助 script からなる skill として定義される。
|
||||
- `triage` が先に走り、`security-deep-dive`、`threat-model`、`maintainers`、`patch`、`breaking-change`、`release-watch` などの skill を並列・段階的に起動する。
|
||||
- 深掘りは sink inventory を作り、敵対入力が trust boundary から到達できるかを確認してから finding にする。
|
||||
- finding は human gate を通って、検証、triage、開示文面、GitHub private vulnerability reporting、修正リリース確認へ進む。
|
||||
- patch skill は最小差分と regression test を提案するが、危険経路と正当利用の境界が読めないときは推測せず拒否する。
|
||||
|
||||
## Why it matters
|
||||
|
||||
Scrutineer の重要な設計判断は、「AI で見つける量」を増やすだけでなく、「AI が出したものをどこで止めるか」をワークフローに含めている点。これは [[loop-engineering]] の実例でもある。発見、検証、修正、開示、リリース監視という loop を、メンテナの受信箱ではなくローカルの操作面と状態管理に閉じ込め、外部に出す前に証拠と人間判断を要求する。
|
||||
|
||||
## Open questions
|
||||
|
||||
- skill 化された脆弱性探索が増えたとき、誤検知だけでなく「検証コスト」をどう測るか。
|
||||
- 人間 gate の担当者に必要な監査ログ、反証材料、再現手順をどこまで標準化できるか。
|
||||
- エコシステム横断スキャンを行う主体が、各プロジェクトの SECURITY.md や開示慣行をどれだけ尊重できるか。
|
||||
@@ -2,30 +2,42 @@
|
||||
|
||||
> Content catalog. Every wiki page listed under its type with a one-line summary.
|
||||
> Read this first to find relevant pages for any query.
|
||||
> Last updated: 2026-06-29 | Total pages: 21
|
||||
> Last updated: 2026-06-30 | Total pages: 33
|
||||
|
||||
## Entities
|
||||
|
||||
- [[f3-file-format]] — WebAssembly 復号器をファイル内に同梱し、将来の符号化にも対応しようとする列指向データファイル形式の研究実装。
|
||||
- [[abtop]] — Claude Code、Codex CLI、OpenCode などの AI coding agent をローカルで横断監視する端末 UI。
|
||||
- [[david-erdos]] — データ保護、プライバシー、表現・報道・研究の自由の均衡を研究する Cambridge 法学者。
|
||||
- [[f3-file-format]] — WebAssembly 復号器をファイル内に同梱し、将来の符号化にも対応しようとする列指向データファイル形式の研究実装。
|
||||
- [[ghidra-mcp]] — Ghidra の逆解析機能を MCP 経由で AI エージェントから扱うための拡張とサーバー。
|
||||
- [[kiro]] — Amazon の仕様駆動型 AI コーディング環境。Agent Focus、権限制御、Markdown custom agents でエージェント操作を IDE の中心に置く。
|
||||
- [[litho]] — ソースコードから C4 アーキテクチャ図と Wiki 風ドキュメントを自動生成する Rust 製 AI 文書化エンジン。
|
||||
- [[llm-wiki-app]] — Karpathy の LLM Wiki pattern を desktop app、queue、graph/search、MCP/API 付きで具体化する実装。
|
||||
- [[maria-ressa]] — Rappler 共同創業者・ノーベル平和賞受賞者。SNS 上の偽情報、情報操作、報道機関への攻撃を公共性の観点から扱う。
|
||||
- [[obsidian]] — LLM Wiki を閲覧・編集するための Markdown/リンク対応ノートアプリ。
|
||||
- [[pi-coding-agent]] — 最小の tool set、provider handoff、session serialization、tmux/端末中心の運用を重視する Mario Zechner の AI coding agent harness。
|
||||
- [[osome]] — Indiana University の Observatory on Social Media。SNS 上の情報操作を研究し、公共のための分析道具を提供する。
|
||||
- [[ravi-naik]] — AI 開発者の設計責任、監視広告、Cambridge Analytica などを扱う英国の技術・データ保護 solicitor。
|
||||
- [[scrutineer]] — AI 支援の OSS 脆弱性スキャンを、検証・修正案・開示・リリース監視まで人間 gate 付きで扱うローカルツール。
|
||||
|
||||
## Concepts
|
||||
|
||||
- [[agentic-hardware-design]] — RTL や検証資産を、Markdown harness・git worktree・実行可能 evaluator 付きの agent loop で反復修正する設計方法。
|
||||
- [[agent-oriented-cli-design]] — AI エージェントが推測せずに使えるよう、JSON 出力、actionable error、search/read 分離、鮮度情報、少ないフラグを重視する CLI 設計。
|
||||
- [[ai-agent-identity-security]] — AI エージェントやアプリ間連携の認可・監査・最小権限を、MCP/XAA などの標準化動向から整理する論点。
|
||||
- [[ai-assisted-reverse-engineering]] — Ghidra などの専門道具と AI エージェントを組み合わせ、逆解析の命名・型付け・文書化を支援する考え方。
|
||||
- [[ai-research-automation]] — 検索語、巡回先、Slack の場所、人を自動で見直しながら、AI 関連情報を継続収集して報告にまとめる運用。
|
||||
- [[ai-developer-liability]] — AI の出力や悪用だけでなく、開発者のシステム設計そのものにどこまで責任を問えるかという論点。
|
||||
- [[ai-evaluation-infrastructure]] — Arena などを通じ、LLM/agent 評価が公開ランキング、商用分析、post-training 改善の基盤になる流れ。
|
||||
- [[ai-research-automation]] — 検索語、巡回先、Slack の場所、人を自動で見直しながら、AI 関連情報を継続収集して報告にまとめる運用。
|
||||
- [[avatar-standardization]] — XR/メタバース上のアバターを、文化表現だけでなくユーザインターフェース規格として扱う設計論点。
|
||||
- [[ci-cd-runtime-security]] — CI/CD ジョブ内で実際に動くプロセスと認証情報アクセスを観測し、供給網攻撃や秘密情報漏えいの証跡を残す考え方。
|
||||
- [[data-protection-and-expression]] — データ保護と、報道・研究・表現の自由が衝突する場面の均衡を扱う論点。
|
||||
- [[digital-gardening-cms]] — メモ、Wiki、作品集、公開サイトを統合し、分類よりリンクと永続性を重視する CMS 設計案。
|
||||
- [[extensible-data-file-formats]] — データ形式が新しい符号化・圧縮・読み出し方を後から受け入れられるようにする設計思想。
|
||||
- [[inclusive-design]] — 外から見えにくい困難や違いを、本人が毎回説明しなくても周囲の配慮につなげる設計。
|
||||
- [[information-integrity]] — 情報操作、偽情報、報道、情報基盤の責任を、公共圏の品質として扱う概念。
|
||||
- [[llm-wiki-pattern]] — LLM が raw source を読み、持続的な相互リンク付き Markdown wiki にコンパイルする運用パターン。
|
||||
- [[loop-engineering]] — エージェントに発見・実行委譲・検証・永続化・定期実行を自走させるループ設計の考え方。
|
||||
- [[meaning-making-marks]] — 形・色・場所だけで周囲の行動を変える、公共空間の記号や合図の設計。
|
||||
- [[rag-vs-compiled-wiki]] — RAG と LLM Wiki の違いを「毎回検索」vs「蓄積済み synthesis」として比較。
|
||||
- [[sns-metric-manipulation]] — 閲覧数、いいね、再生数などの数値を人為的に増やし、支持や話題性の見え方を変える情報操作。
|
||||
|
||||
@@ -110,3 +110,160 @@
|
||||
- Updated: index.md
|
||||
- Discord context: repository link shared with `tldr`, followed by `Ingest`.
|
||||
|
||||
## [2026-06-29] ingest | Discord-discovered loop engineering and agent security links
|
||||
- Scanned #chat and #tw after 2026-06-28T07:26:20.859000000Z via discrawl read-only SQL with git-share auto-update enabled.
|
||||
- Source saved: raw/articles/loop-engineering-anthropic-playbook-2026.md
|
||||
- Source saved: raw/articles/github-issueops-state-machines-2026.md
|
||||
- Source saved: raw/articles/redhat-virtiofs-host-vm-file-sharing-2026.md
|
||||
- Source saved: raw/articles/okta-cross-app-access-partners-2026.md
|
||||
- Source saved: raw/articles/daida-ai-claude-code-plugin-2026.md
|
||||
- Source saved: raw/articles/cachyos-ananicy-rules-2026.md
|
||||
- Created: concepts/loop-engineering.md
|
||||
- Created: concepts/ai-agent-identity-security.md
|
||||
- Updated: concepts/wiki-maintenance-loop.md
|
||||
- Updated: index.md
|
||||
- Skipped or link-only: X/Twitter/t.co links without durable fetchable source, self-repo/private git links, general news/sports/culture links, MacRumors Play acquisition, Nix Chinese mirror, and YouTube live link.
|
||||
|
||||
## [2026-06-29] ingest | Discord-discovered EDCB tools link
|
||||
- Scanned 13 messages in #chat and #tw after 2026-06-29T16:50:42.181000000Z via discrawl read-only SQL with git-share auto-update enabled; found 84 normalized unique URLs.
|
||||
- Source saved: raw/articles/edcb-tools-2026.md
|
||||
- No wiki concept/entity page update: scored as useful raw material for Yuta's EDCB/MCP tooling, but too project-specific for a durable page on this run.
|
||||
- Link-only/skipped: private or missing `yutakobayashidev/edcb` repository link; X/Twitter digest links including Comfy MCP, Cursor iOS, Claude Code subagent, LangChain dynamic subagents, Next.js, KIDS Act, and scams/football/politics items were treated as discovery context only.
|
||||
|
||||
## [2026-06-29] ingest | Discord-discovered Wikipedia governance link
|
||||
- Scanned 6 messages in #chat and #tw after `2026-06-29T22:21:53.194000000Z` via discrawl read-only SQL with git-share auto-update enabled; found 38 normalized unique URLs.
|
||||
- Source saved: raw/articles/wikipedia-sanger-canvassing-ban-2026.md
|
||||
- Updated: concepts/information-integrity.md
|
||||
- Link-only/skipped: Japan Times prediction-market article kept as link-only because it is regulatory/business context but below current wiki threshold; X/Twitter digest links about OpenClaw mobile, T3 Connect, Warp, Drizzle, GLM-5.2, security incidents, markets, sports, and general news were treated as discovery context only unless durable non-X primary sources appear.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered HORIZON and PQC TPM links
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T00:21:46.580000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,883.
|
||||
- Found 48 normalized unique URLs. Most were X/Twitter news/digest links; durable non-X sources were discovered by resolving/searching the linked context rather than ingesting Discord transcripts.
|
||||
- Source saved: raw/articles/horizon-agentic-hardware-design-2026.md
|
||||
- Source saved: raw/articles/wolftpm-pqc-tpm-2-0-v1-85-2026.md
|
||||
- Created: concepts/agentic-hardware-design.md
|
||||
- Updated: concepts/loop-engineering.md
|
||||
- Updated: index.md
|
||||
- Link-only/skipped: Claude Code changelog kept link-only because the fetched official changelog did not expose the referenced 2.1.196 entry cleanly during this run; Hosted X MCP, noisy-vs-quiet-internet, design commentary, macro/market/geopolitics/sports, and most X-only items stayed below raw-ingest threshold.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered physical AI and satellite network links
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T01:21:44.582000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,889.
|
||||
- Found 46 normalized unique URLs. Most were X/Twitter digest/news links; exact t.co expansion was blocked by the local shortener safety guard, so durable destinations were identified by title/context web search and fetched directly.
|
||||
- Source saved: raw/articles/japan-domestic-physical-ai-policy-2026.md — score 2, fallback source for the linked Nikkei physical-AI item because the Nikkei page exposed only newsletter/paywall text to defuddle.
|
||||
- Source saved: raw/articles/ses-meosphere-2026.md — score 2, primary SES page for meoSphere/MEO network context.
|
||||
- No wiki concept/entity pages updated: both sources were useful raw material but below the threshold for durable page updates this run.
|
||||
- Link-only/skipped: Nikkei exact article and Asahi smart-farm article were not cleanly extractable; semiconductor-materials, quiet/うるさい internet, smartphone-farm, Subway queue/UX, movie-poster market-structure, Taiwan/history, politics, macro/markets, sports, and general breaking-news X links stayed below the strict raw-ingest threshold unless a durable non-X source was found.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered CI/CD security and agent UI links
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T02:22:07.280000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,893.
|
||||
- Found 47 normalized unique URLs. Most were X/Twitter digest/news links; high-signal non-X destinations were found by title/context search and fetched with defuddle.
|
||||
- Source saved: raw/articles/aws-finops-agent-preview-2026.md — score 2, AWS FinOps Agent setup/automation walkthrough.
|
||||
- Source saved: raw/articles/waseda-cyborg-insect-diving-suit-2026.md — score 2, disaster/infrastructure inspection cyborg-insect research.
|
||||
- Source saved: raw/articles/jaxa-amsr3-data-products-2026.md — score 2, public earth-observation data infrastructure release.
|
||||
- Source saved: raw/articles/cicd-sensor-2026.md — score 4, CI/CD runtime security sensor for supply-chain attack detection and audit evidence.
|
||||
- Source saved: raw/articles/cursor-ios-mobile-agent-ui-2026.md — score 2, mobile UI for cloud/local coding agents.
|
||||
- Created: concepts/ci-cd-runtime-security.md
|
||||
- Updated: index.md
|
||||
- Link-only/skipped: Betterleaks was kept link-only because its public README includes a fake token-like example that tripped the local write safety scanner; routine Apple/Edge patch links, entertainment subsidy news, macro/markets/trade items, X-only AI model chatter, AI小島社長, and phishing/Remcos article context stayed below the wiki-update threshold.
|
||||
|
||||
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered local AI and civic/security operations links
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T03:21:46.667000000Z` via discrawl read-only SQL with git-share auto-update enabled; discrawl status reported share needs_update=true; subsequent read-only SQL pulled/imported 166,383 rows and increased archive message count to 163,906.
|
||||
- Found 44 normalized unique URLs, mostly X/Twitter digest links. Durable non-X sources were selected from the message context and fetched directly.
|
||||
- Source saved: raw/articles/emeditor-local-ai-lm-studio-2026.md — score 2, local/private AI integration in a text editor via LM Studio/OpenAI-compatible provider.
|
||||
- Source saved: raw/articles/mhlw-medical-info-security-guideline-7-2026.md — score 2, public-sector healthcare information-system security guideline hub.
|
||||
- Source saved: raw/articles/wakayama-satellite-ai-leak-survey-2026.md — score 2, civic infrastructure AI/satellite leak-survey implementation note.
|
||||
- No wiki concept/entity pages updated: all saved sources were useful raw material, but below the strict threshold for page updates this run.
|
||||
- Link-only/skipped: X hosted MCP and World Fair were kept as link-only/event or X-only signals pending durable docs; GLM/LongCat/DeepSeek/Sonnet model chatter, Azure OpenAI school-content-filter complaints, Toyota moviLink routing, macro/markets/policy, sports, and general news stayed below raw-ingest threshold.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered agent observability and security links
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T04:21:29.765000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,910.
|
||||
- Found 41 normalized unique URLs, mostly X/Twitter digest links plus short links highlighted in the digest. Durable destinations were selected by title/context search and fetched directly, not from Discord transcript content.
|
||||
- Source saved: raw/articles/oracle-ebs-cve-2026-46817-active-exploitation-2026.md — score 2, active exploitation report for CVE-2026-46817 in Oracle E-Business Suite.
|
||||
- Source saved: raw/articles/meti-physical-ai-multimodal-foundation-model-2026.md — score 2, METI/NEDO announcement for domestic multimodal foundation model work toward physical AI.
|
||||
- Source saved: raw/articles/abtop-ai-coding-agent-monitor-2026.md — score 4, local monitor for Claude Code, Codex CLI, and OpenCode sessions.
|
||||
- Source saved: raw/articles/openclaw-ios-native-app-2026.md — score 2, mobile OpenClaw app and gateway approval surface.
|
||||
- Created: entities/abtop.md
|
||||
- Updated: concepts/loop-engineering.md
|
||||
- Updated: index.md
|
||||
- Updated: .automation/discord-link-ingest/interest-profile.md
|
||||
- Link-only/skipped: Noetra's own page extracted only a stub, so the METI primary release was saved instead; X-only posts about agent channel UX, Rust compiler self-introduction, Russian auth/fraud threads, bank-domain/PeopleSoft commentary, VRM avatar standards, sports, macro/policy, and device rumors stayed below wiki-update threshold.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered Kiro and Arena evaluation links
|
||||
- Scanned 6 new local-archive messages in #chat and #tw after `2026-06-30T05:21:32.201000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,920.
|
||||
- Found 30 normalized unique URLs, mostly X/Twitter digest links plus two no-URL #chat status messages. Durable non-X sources were selected from the linked context and fetched with defuddle.
|
||||
- Source saved: raw/articles/kiro-ide-1-0-agent-focus-2026.md — score 4, Amazon Kiro IDE 1.0 / Agent Focus coverage from Impress Watch.
|
||||
- Source saved: raw/articles/arena-ai-leaderboard-business-2026.md — score 4, TechCrunch report on Arena turning public model evaluation into a commercial evaluation layer.
|
||||
- Created: entities/kiro.md
|
||||
- Created: concepts/ai-evaluation-infrastructure.md
|
||||
- Updated: concepts/loop-engineering.md
|
||||
- Updated: index.md
|
||||
- Link-only/skipped: X-only avatar international-standard thread, Noetra funding chatter already covered by a prior METI physical-AI source, duplicate Oracle EBS exploit link already saved, long-form generation harness discussion without durable source, Russia auth/localization thread, sports/macro/general news, and medical self-support anecdote stayed below raw-ingest threshold.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered code docs, OSS security workflow, and avatar standards
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T07:05:05.323000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,939.
|
||||
- Found 44 normalized URL mentions before dedupe, mostly X/Twitter digest links plus four t.co highlighted links. Durable destinations were selected from message context and web search, then fetched with defuddle or raw GitHub README fetch.
|
||||
- Source saved: raw/articles/litho-deepwiki-rs-code-documentation-2026.md — score 4, Rust/AI tool generating C4 architecture diagrams and Wiki-style docs from code.
|
||||
- Source saved: raw/articles/scrutineer-oss-security-workflow-2026.md — score 4, AI-assisted OSS vulnerability scan, verification, patch, disclosure, and release-watch workflow designed not to flood maintainers.
|
||||
- Source saved: raw/articles/aist-avatar-standardization-committee-2026.md — score 4, AIST domestic committee for avatar UI international standardization in XR/metaverse services.
|
||||
- Source saved: raw/articles/aflac-personal-data-breach-2026.md — score 2, large Japanese insurance personal-data breach with bank-account data exposure.
|
||||
- Source saved: raw/articles/javascript-trademark-oracle-deno-2025.md — score 2, JavaScript trademark cancellation dispute and Oracle/Node.js evidence issue.
|
||||
- Created: entities/litho.md
|
||||
- Created: entities/scrutineer.md
|
||||
- Created: concepts/avatar-standardization.md
|
||||
- Updated: concepts/digital-gardening-cms.md
|
||||
- Updated: concepts/ci-cd-runtime-security.md
|
||||
- Updated: concepts/inclusive-design.md
|
||||
- Updated: index.md
|
||||
- Updated: .automation/discord-link-ingest/interest-profile.md
|
||||
- Link-only/skipped: Kiro/OpenClaw/physical-AI items were duplicates or already represented by prior raw sources; politics, sports, macro/geopolitics, DRAM/PS6 pricing chatter, school-study-time headline, and most X-only commentary stayed below raw-ingest threshold.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered Codex safety and accessibility links
|
||||
- Scanned 9 new local-archive messages in #chat and #tw after `2026-06-30T07:21:42.933000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,950.
|
||||
- Found 92 URL mentions / 54 normalized unique URLs. 53 were X/Twitter links; one direct `.zip` site link was not fetched because the terminal security guard flagged the lookalike TLD.
|
||||
- Source saved: raw/articles/openai-codex-agent-approvals-security-2026.md — score 4, Codex sandbox, approvals, and network policy controls used as durable source for local AI-agent safety.
|
||||
- Source saved: raw/articles/accessibility-conference-chiba-2026.md — score 4, Accessibility Conference CHIBA page with information-assurance streaming, venue accessibility details, Ontenna, and Ekimatope examples.
|
||||
- Source saved: raw/articles/pfn-plamo-3-prime-release-2026.md — score 2, PFN PLaMo 3.0 Prime release kept as raw context for domestic/government AI adoption discussion.
|
||||
- Updated: concepts/ai-agent-identity-security.md
|
||||
- Updated: concepts/inclusive-design.md
|
||||
- Link-only/skipped: OONI/LALIGA blocking, PFN municipal proof-of-concept, ConoHa AI-agent deployment skill, X_VORDER_RUNWAY, local LLM hardware/cost chatter, market/geopolitics/sports/consumer trend links, and X-only commentary stayed below page-update threshold or lacked a fetchable durable primary source this run.
|
||||
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered knowledge-integrity, terminal history, and book-access links
|
||||
- Scanned 4 new local-archive messages in #tw after `2026-06-30T09:21:40.818000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,955.
|
||||
- Found 49 URL mentions / 33 normalized unique URLs, all X/Twitter discovery links. Durable sources were selected from the message context and web search, then fetched with defuddle.
|
||||
- Source saved: raw/articles/wikipedia-fake-russian-history-zhemao-2022.md — score 3, Zhemao / 折毛事件 as a reusable knowledge-base integrity failure mode.
|
||||
- Source saved: raw/articles/state-of-terminal-history-2024.md — score 2, terminal UI and escape-sequence history kept as raw technical-culture context.
|
||||
- Source saved: raw/articles/poplar-japan-post-children-books-post-office-trial-2026.md — score 2, Poplar/Japan Post postal-window book sales trial kept as raw civic/book-access context.
|
||||
- Updated: concepts/information-integrity.md
|
||||
- Link-only/skipped: OpenAI Codex, PFN/PLaMo, and Aflac links were duplicates already represented by raw sources; crypto/stablecoin regulation, ride-share/political procedure, heat-wave, consumer brand/product, Binance, science/nature, and most X-only commentary stayed below current threshold.
|
||||
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered pi coding agent and worktree/security links
|
||||
- Scanned 5 new local-archive messages in #chat and #tw after `2026-06-30T10:22:05.808000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,971.
|
||||
- Found 42 URL mentions / 34 normalized unique URLs, mostly X/Twitter digest links plus one direct #chat article link.
|
||||
- Source saved: raw/articles/pi-coding-agent-2025.md — score 4, minimal AI coding-agent harness with provider abstraction, explicit context/session control, terminal UI, and tmux-first process management.
|
||||
- Source saved: raw/articles/github-desktop-3-6-worktrees-copilot-2026.md — score 3, GitHub Desktop worktree and Copilot SDK update relevant to agent-era multi-branch workflows.
|
||||
- Source saved: raw/articles/nissan-peoplesoft-breach-2026.md — score 2, enterprise PeopleSoft breach exposing payroll/banking data; kept raw as security-operations context.
|
||||
- Source saved: raw/articles/splunk-secure-gateway-rce-2026.md — score 2, official Splunk Secure Gateway RCE advisory; kept raw as security-operations context.
|
||||
- Created: entities/pi-coding-agent.md
|
||||
- Updated: concepts/loop-engineering.md
|
||||
- Updated: index.md
|
||||
- Updated: .automation/discord-link-ingest/interest-profile.md
|
||||
- Link-only/skipped: music/event/VTuber announcements, macro/geopolitics items, X-only commentary, Sakana hiring, common-test reactions, AI poster commentary, and most security/news posts without durable reuse stayed below the strict wiki threshold.
|
||||
|
||||
## [2026-06-30] ingest | Discord-discovered agent CLI, SDLC governance, AI legal risk, and S3 design links
|
||||
- Scanned 8 new local-archive messages in #chat and #tw after `2026-06-30T11:21:36.408000000Z` via discrawl read-only SQL with git-share auto-update enabled; share import increased archive message count to 163,989.
|
||||
- Found 42 URL mentions / 39 normalized unique URLs, mostly X/Twitter discovery links plus direct #chat links.
|
||||
- Source saved: raw/articles/agent-oriented-cli-zenn-2026.md — score 4, practical AI-agent-oriented CLI design notes: CLI-owned usage guide, JSON-first output, actionable errors, search/read split, and fewer flags.
|
||||
- Source saved: raw/articles/microsoft-learn-agent-architecture-sdlc-2026.md — score 3, Microsoft Learn module on agent architecture, GitHub workflow integration, PR governance, observability, tool governance, and secret boundaries.
|
||||
- Source saved: raw/articles/boj-ai-legal-risk-financial-institutions-2026.md — score 3, Bank of Japan IMES abstract on private-law risks and governance for AI use in financial institutions.
|
||||
- Source saved: raw/articles/amazon-s3-deep-dive-reinvent-2023.md — score 2, AWS re:Invent S3 deep-dive slides kept as raw architecture/scale-design context.
|
||||
- Created: concepts/agent-oriented-cli-design.md
|
||||
- Updated: concepts/loop-engineering.md
|
||||
- Updated: concepts/ai-agent-identity-security.md
|
||||
- Updated: concepts/ai-developer-liability.md
|
||||
- Updated: index.md
|
||||
- Updated: .automation/discord-link-ingest/interest-profile.md
|
||||
- Link-only/skipped: Reddit Claude Code spyware discussion failed extraction and was treated as unverified discussion only; Ramp/Revelio AI-employment source was not resolved to a clean primary source; old-Android/Termux/Home-Assistant context lacked a fetchable durable source; X video, macro/geopolitics, sports, routine security headlines, and media-only links stayed below threshold.
|
||||
|
||||
@@ -0,0 +1,218 @@
|
||||
---
|
||||
source_url: https://github.com/graykode/abtop
|
||||
ingested: 2026-06-30
|
||||
sha256: e763af7f4da82cbb1273108e130ed3b21660e3ebc407fdc2ec4b570cb7c3d432
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521385175827877898'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T05:21:31.887000000Z
|
||||
message_excerpt: >-
|
||||
abtop AI coding agent monitor highlighted for Claude Code, Codex CLI, and OpenCode operations.
|
||||
---
|
||||
|
||||
# abtop
|
||||
|
||||
**Like [btop](https://github.com/aristocratos/btop), but for your AI coding agents.**
|
||||
|
||||
See every Claude Code, Codex CLI, and OpenCode session at a glance — token usage, context window %, rate limits, child processes, open ports, and more.
|
||||
Claude Code, Codex CLI, and OpenCode sessions are discovered from local process/file state, so multiple active profiles are supported across macOS, Linux, and Windows.
|
||||
|
||||
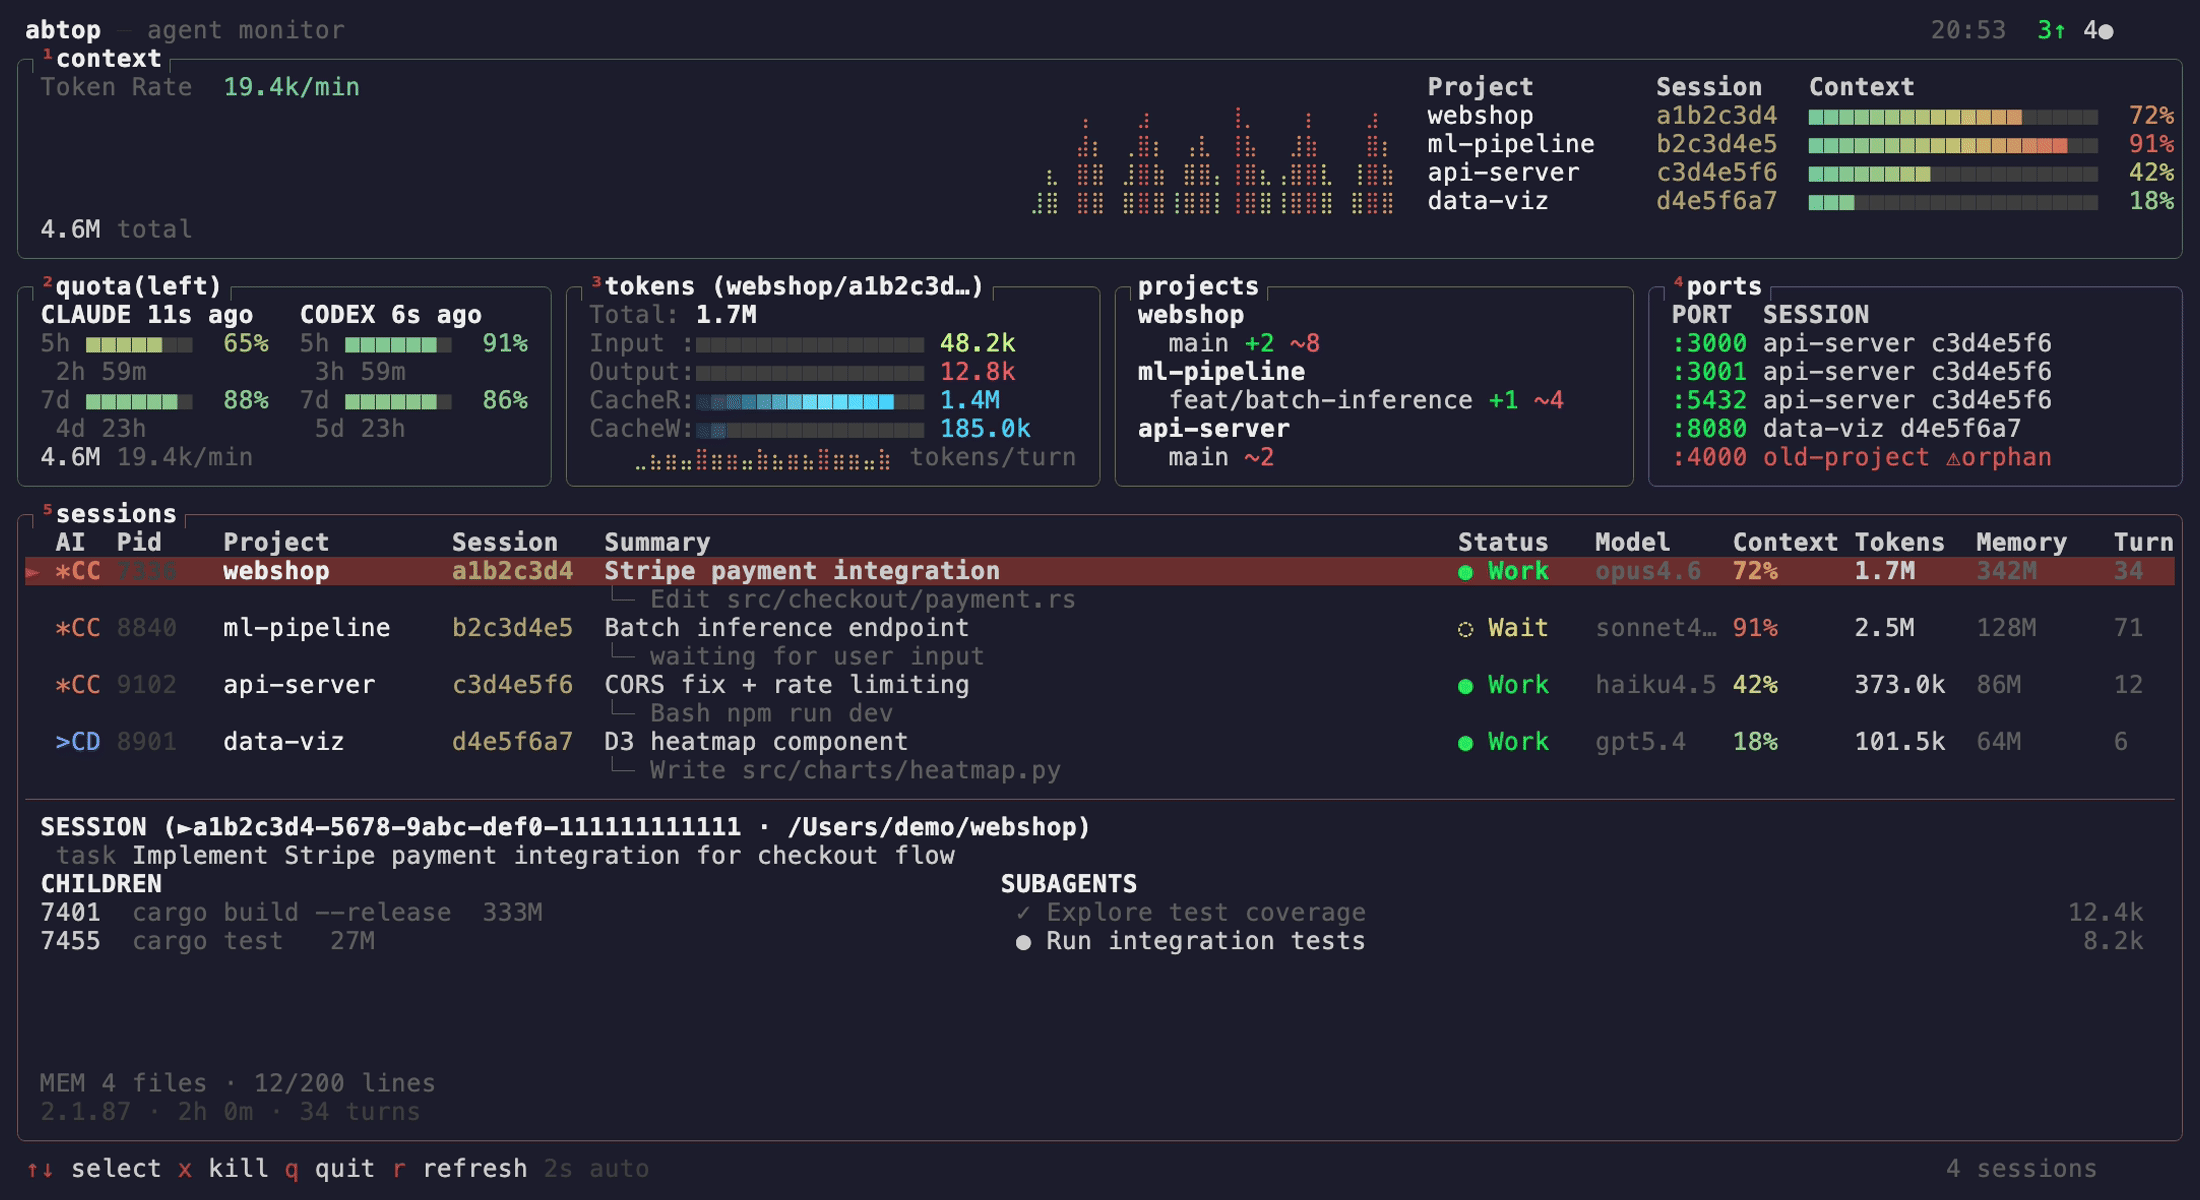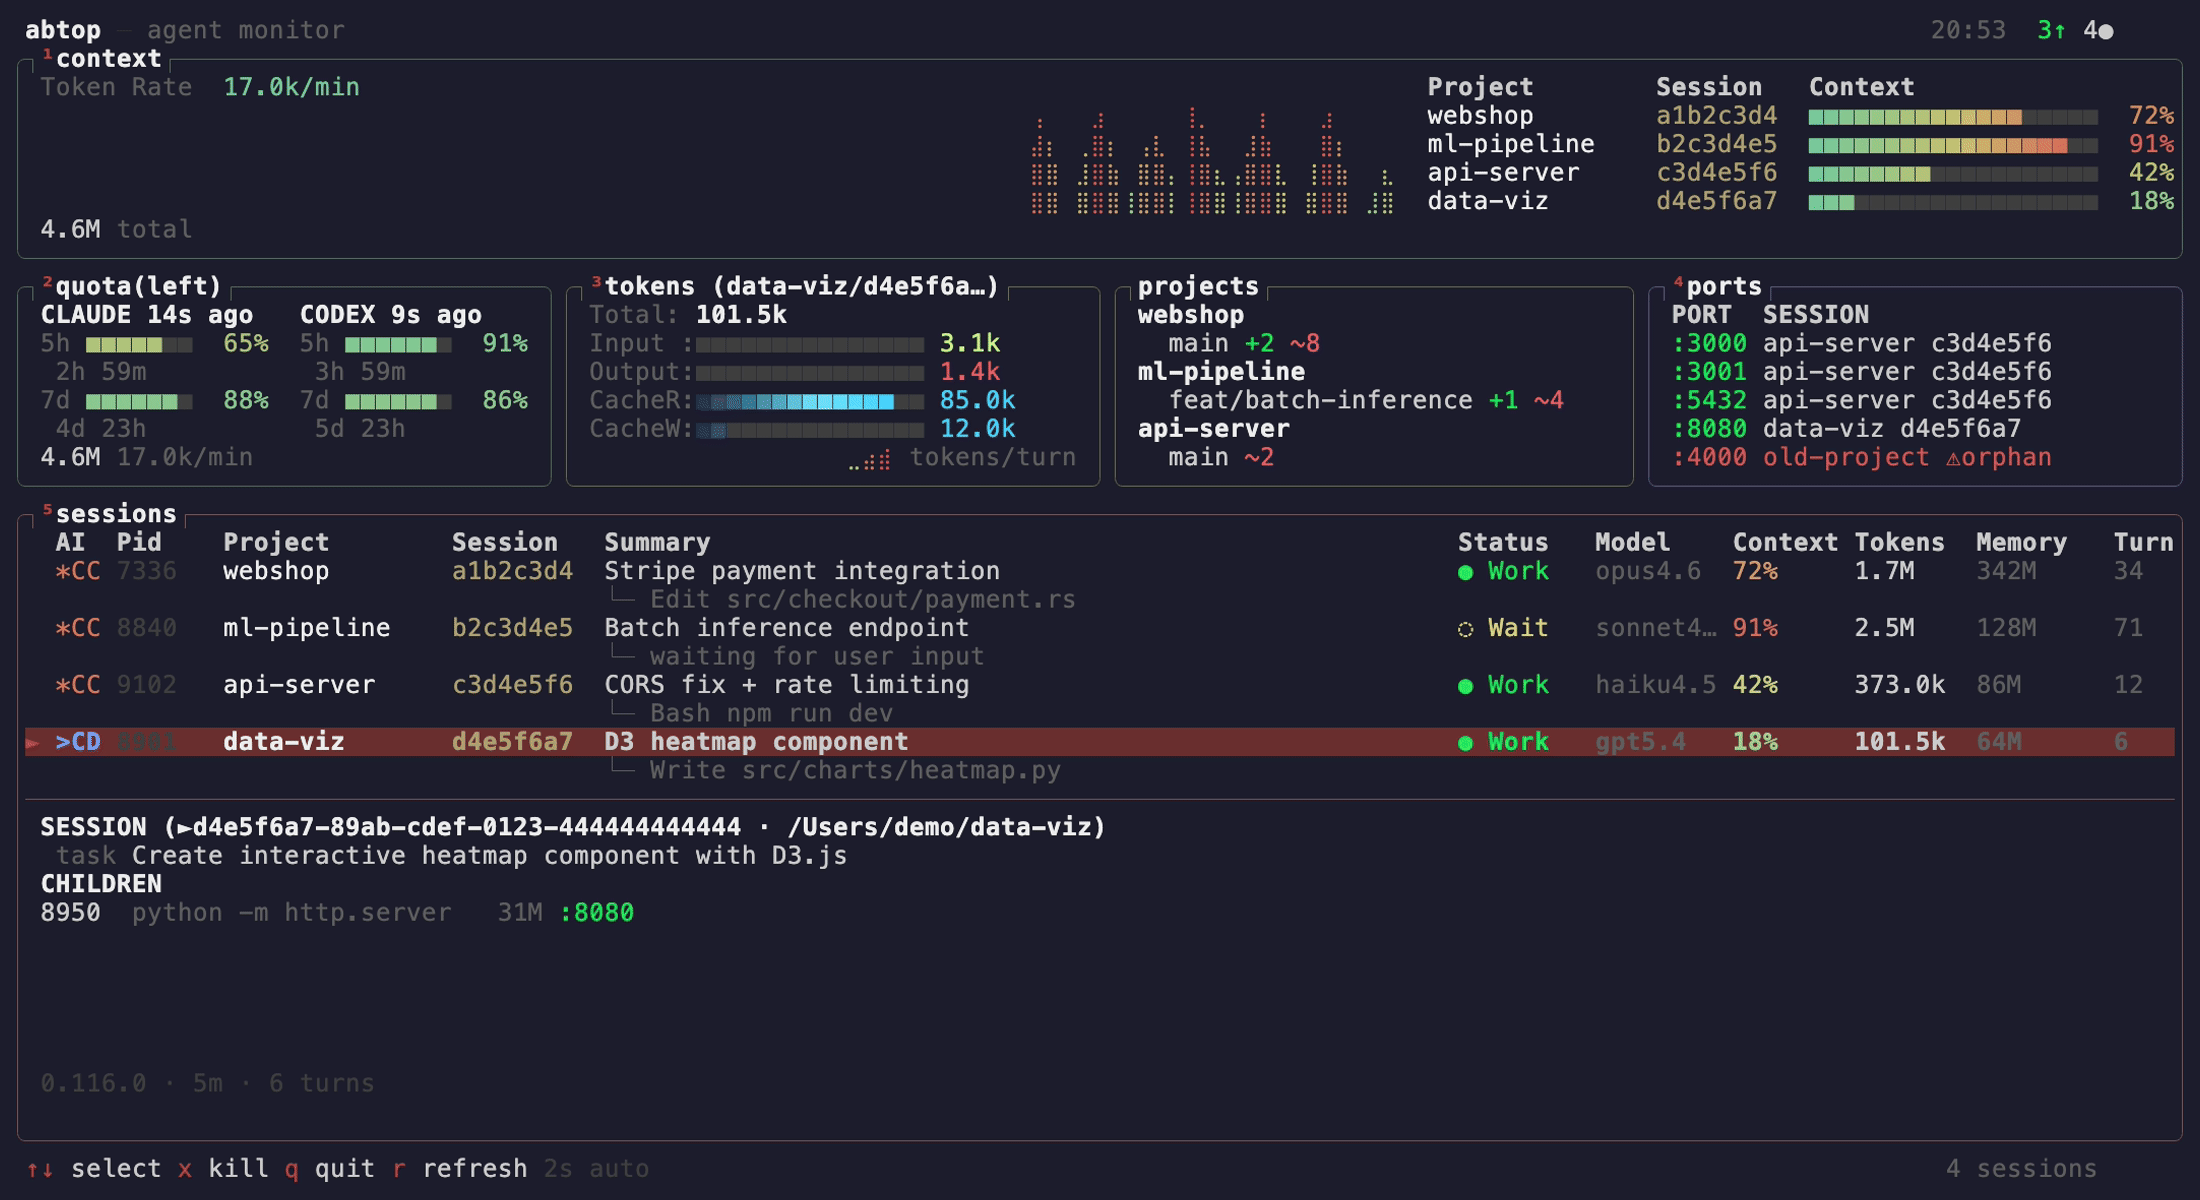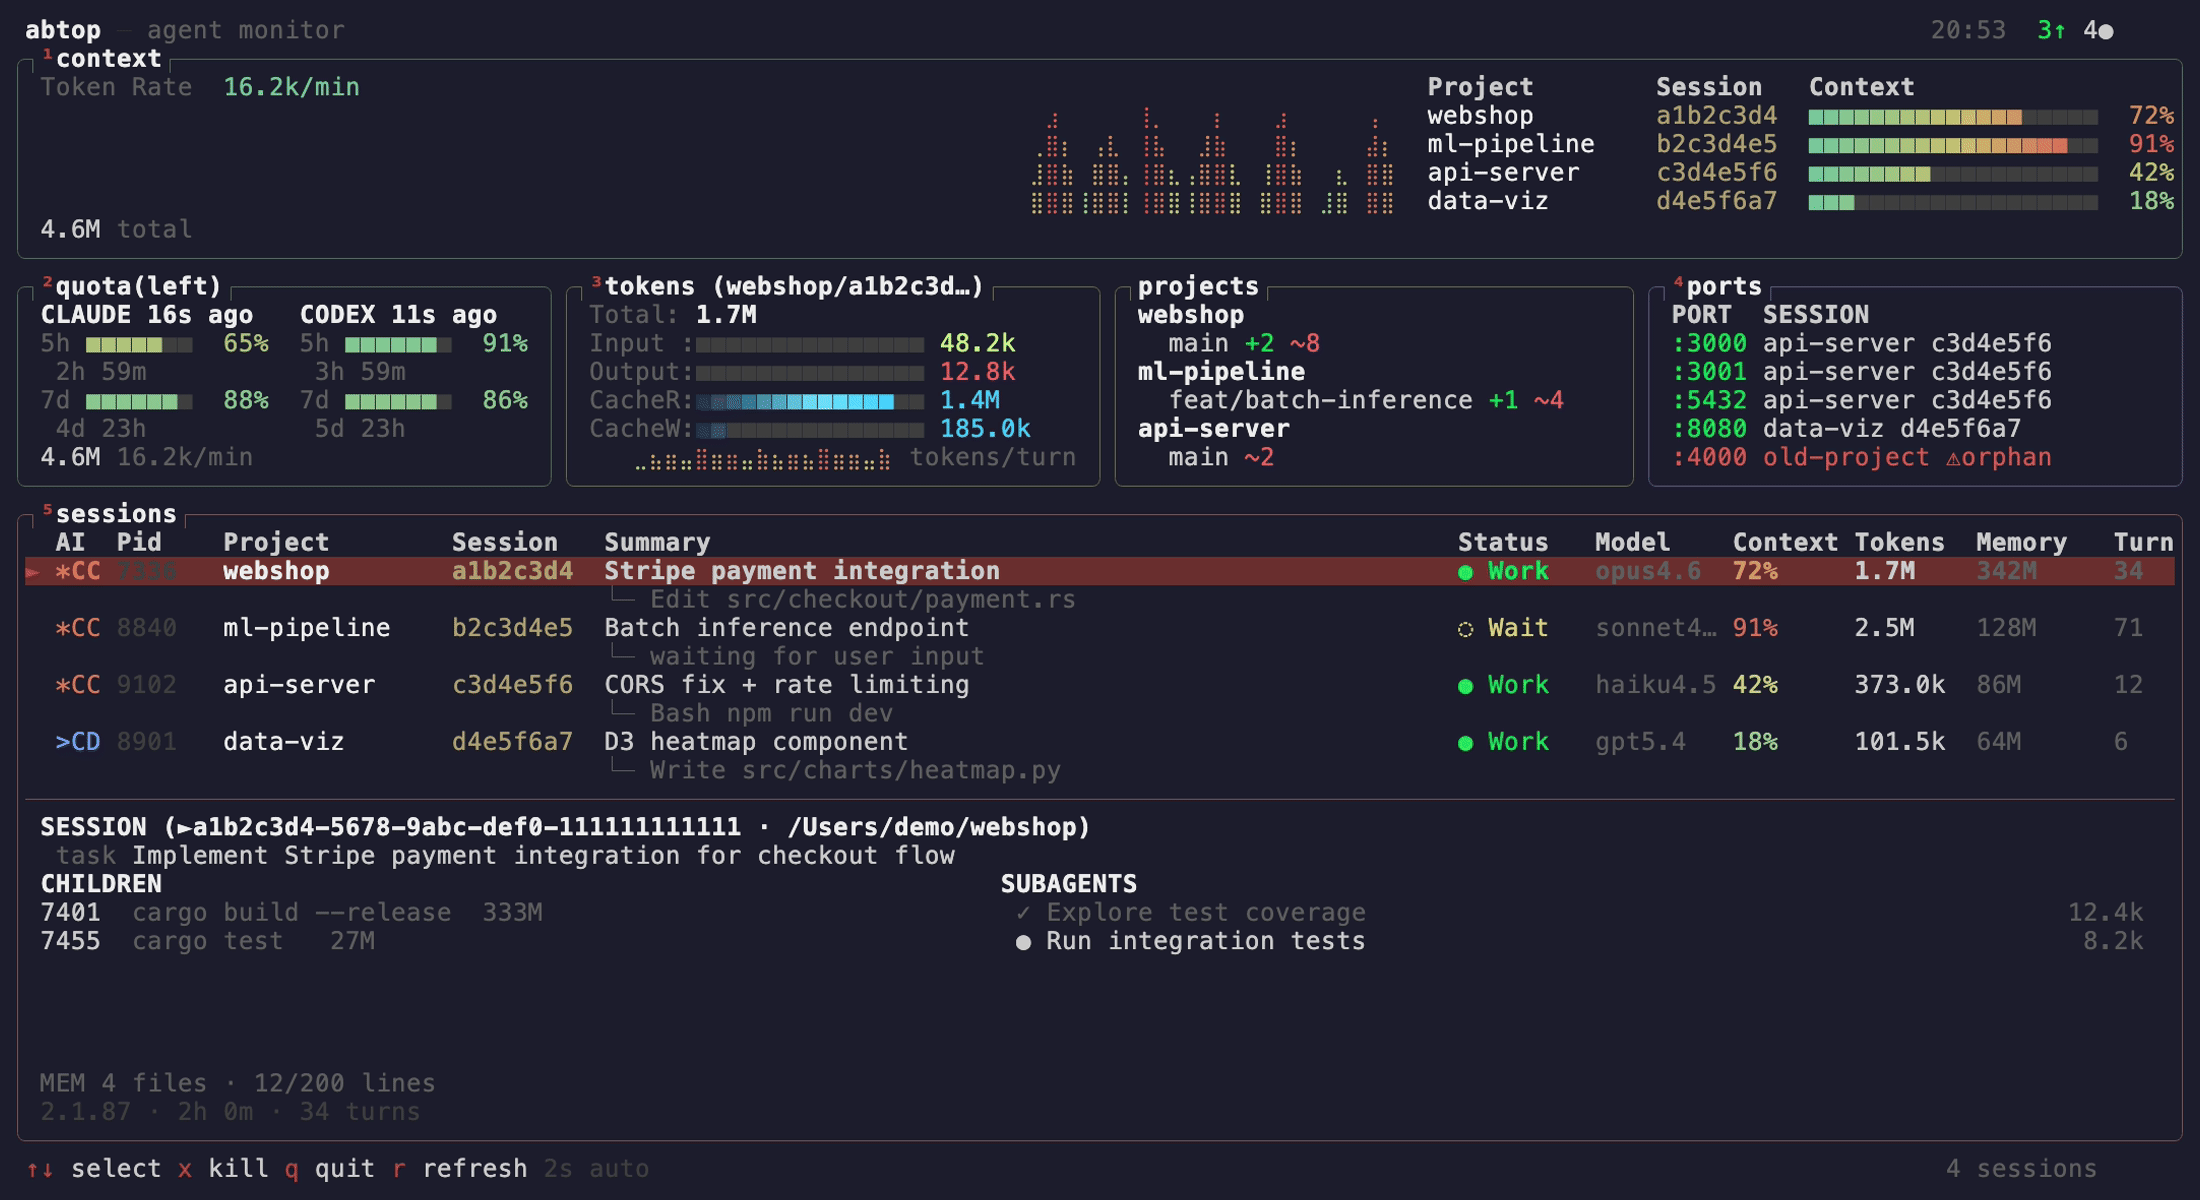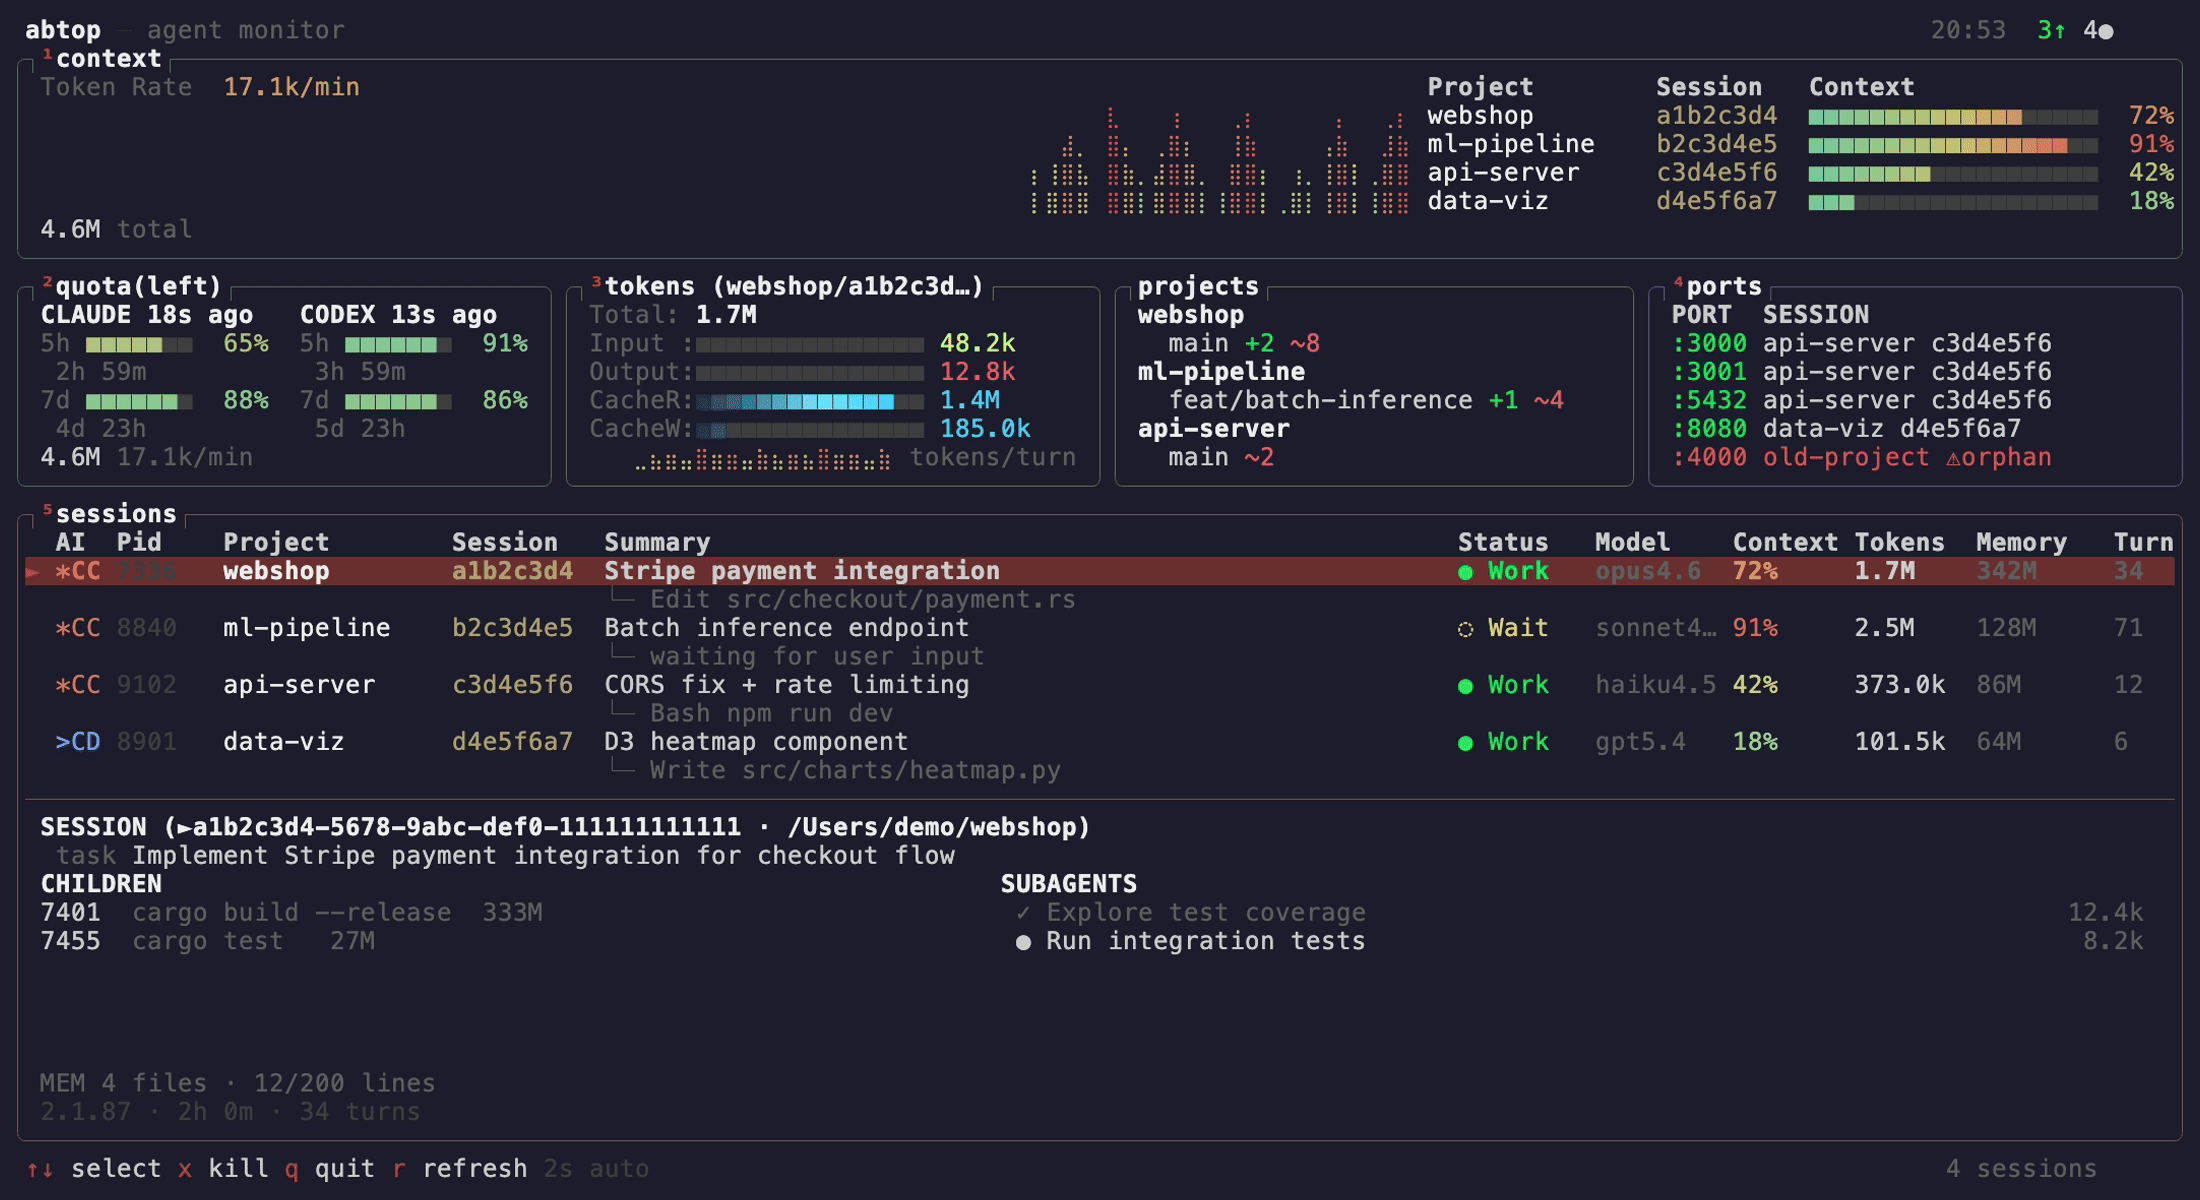
|
||||
|
||||
## Why
|
||||
|
||||
- Running 3+ agents across projects? See them all in one screen.
|
||||
- Hitting rate limits? Watch your quota in real-time.
|
||||
- Agent spawned a server and forgot to kill it? Orphan port detection.
|
||||
- Context window filling up? Per-session % bars with warnings.
|
||||
|
||||
All read-only. No API keys. No auth.
|
||||
|
||||
## Install
|
||||
|
||||
### macOS / Linux
|
||||
|
||||
> [!IMPORTANT]
|
||||
> On Linux, ensure `sqlite3` is installed to enable monitoring for OpenCode sessions.
|
||||
|
||||
```bash
|
||||
curl --proto '=https' --tlsv1.2 -LsSf https://github.com/graykode/abtop/releases/latest/download/abtop-installer.sh | sh
|
||||
```
|
||||
|
||||
### Cargo
|
||||
|
||||
```bash
|
||||
cargo install abtop
|
||||
```
|
||||
|
||||
### Windows
|
||||
|
||||
Native support — no WSL required. Uses `sysinfo` for process info and host CPU/MEM metrics, and `netstat -ano` for listening ports. Windows has no load average, so LOAD is reported as 0. OpenCode session discovery additionally requires the `sqlite3` CLI (`winget install SQLite.SQLite`); without it abtop prints a one-time warning to stderr.
|
||||
|
||||
```powershell
|
||||
powershell -c "irm https://github.com/graykode/abtop/releases/latest/download/abtop-installer.ps1 | iex"
|
||||
```
|
||||
|
||||
Or `cargo install abtop` from any terminal with Git in PATH. Claude Code config is resolved automatically from `%USERPROFILE%\.claude`.
|
||||
|
||||
### Other
|
||||
|
||||
Pre-built binaries for all platforms are available on the [GitHub Releases](https://github.com/graykode/abtop/releases) page.
|
||||
|
||||
## Usage
|
||||
|
||||
```bash
|
||||
abtop # Launch TUI
|
||||
abtop --once # Print snapshot and exit
|
||||
abtop --json # Print one JSON snapshot and exit (for scripts/tools)
|
||||
abtop --setup # Install rate limit collection hook
|
||||
abtop --theme dracula # Launch with a specific theme
|
||||
```
|
||||
|
||||
Recommended terminal size: **120x40** or larger. Minimum 80x24 — panels hide gracefully when small.
|
||||
|
||||
### Terminal Jump
|
||||
|
||||
Press `Enter` to focus the terminal running the selected agent. abtop supports cmux, tmux, and iTerm2 on macOS.
|
||||
|
||||
```bash
|
||||
tmux new -s work
|
||||
# pane 0: abtop
|
||||
# pane 1: claude (project A)
|
||||
# pane 2: claude (project B)
|
||||
# → Enter on a session in abtop jumps to its pane
|
||||
```
|
||||
|
||||
## Supported Agents
|
||||
|
||||
| Feature | Claude Code | Codex CLI | OpenCode |
|
||||
| ----------------- | :---------: | :-------: | :------: |
|
||||
| Session Discovery | ✅ | ✅ | ✅ |
|
||||
| Token Tracking | ✅ | ✅ | ✅ |
|
||||
| Context Window % | ✅ | ✅ | ❌ |
|
||||
| Status Detection | ✅ | ✅ | ✅ |
|
||||
| Current Task | ✅ | ✅ | ❌ |
|
||||
| Rate Limit | ✅ | ✅ | ❌ |
|
||||
| Git Status | ✅ | ✅ | ✅ |
|
||||
| Children / Ports | ✅ | ✅ | ✅ |
|
||||
| Subagents | ✅ | ❌ | ❌ |
|
||||
| Memory Status | ✅ | ❌ | ❌ |
|
||||
|
||||
OpenCode support reads the local SQLite database at `~/.local/share/opencode/opencode.db` (also the default location on Windows; `%LOCALAPPDATA%\opencode` and `%APPDATA%\opencode` are probed as fallbacks) and requires `sqlite3` in `PATH` (on Windows: `winget install SQLite.SQLite`).
|
||||
|
||||
## Themes
|
||||
|
||||
12 built-in themes, including 4 colorblind-friendly options (`high-contrast`, `protanopia`, `deuteranopia`, `tritanopia`). Press `t` to cycle at runtime, or launch with `--theme <name>`. Your choice is saved to `~/.config/abtop/config.toml`.
|
||||
|
||||
| btop (default) | dracula | catppuccin |
|
||||
|:-:|:-:|:-:|
|
||||
| 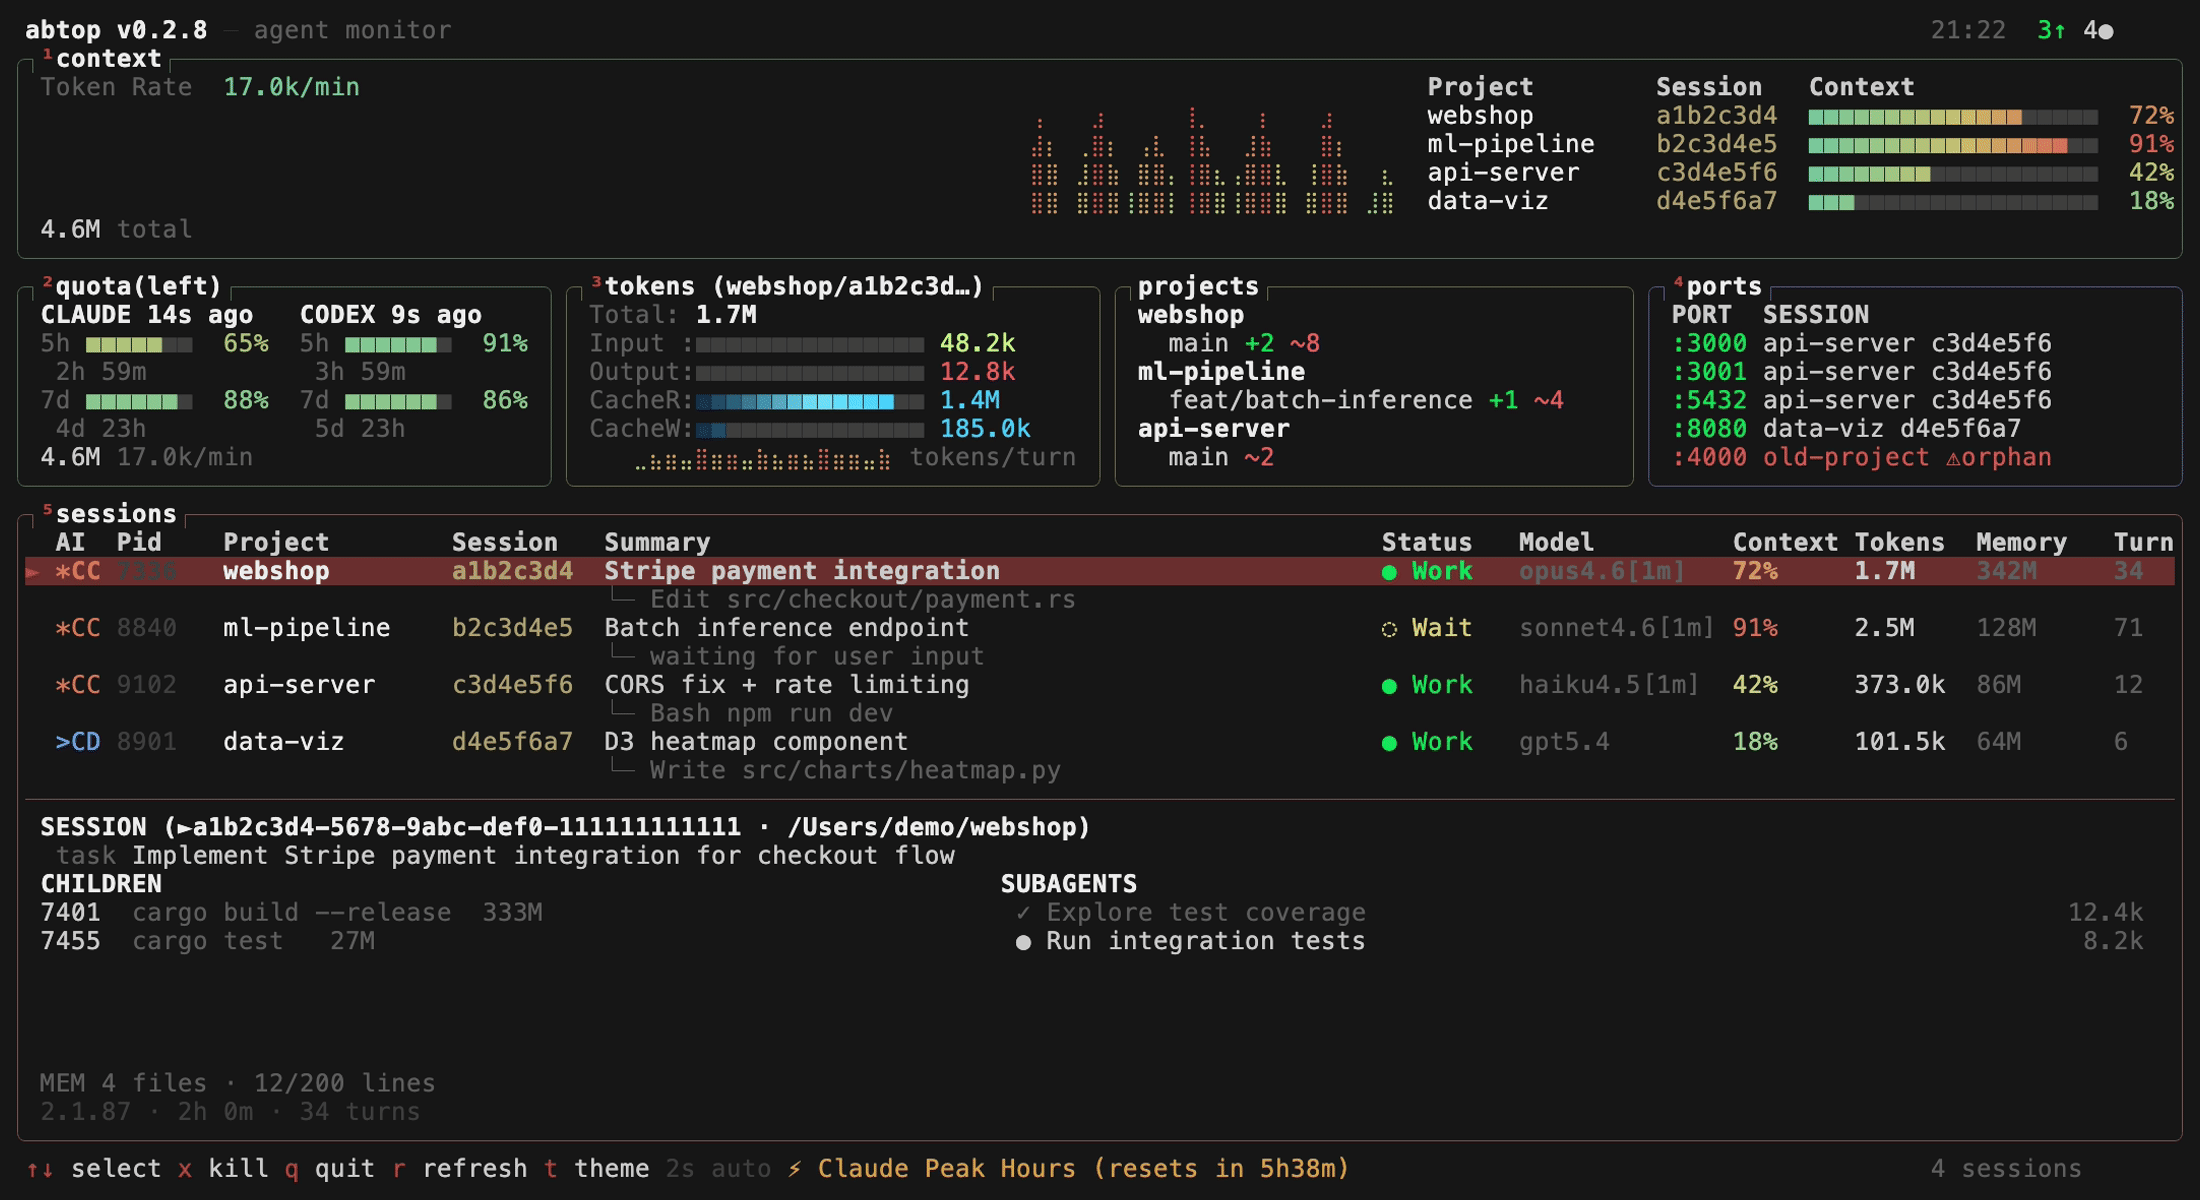 |  |  |
|
||||
|
||||
| tokyo-night | gruvbox | nord |
|
||||
|:-:|:-:|:-:|
|
||||
|  | 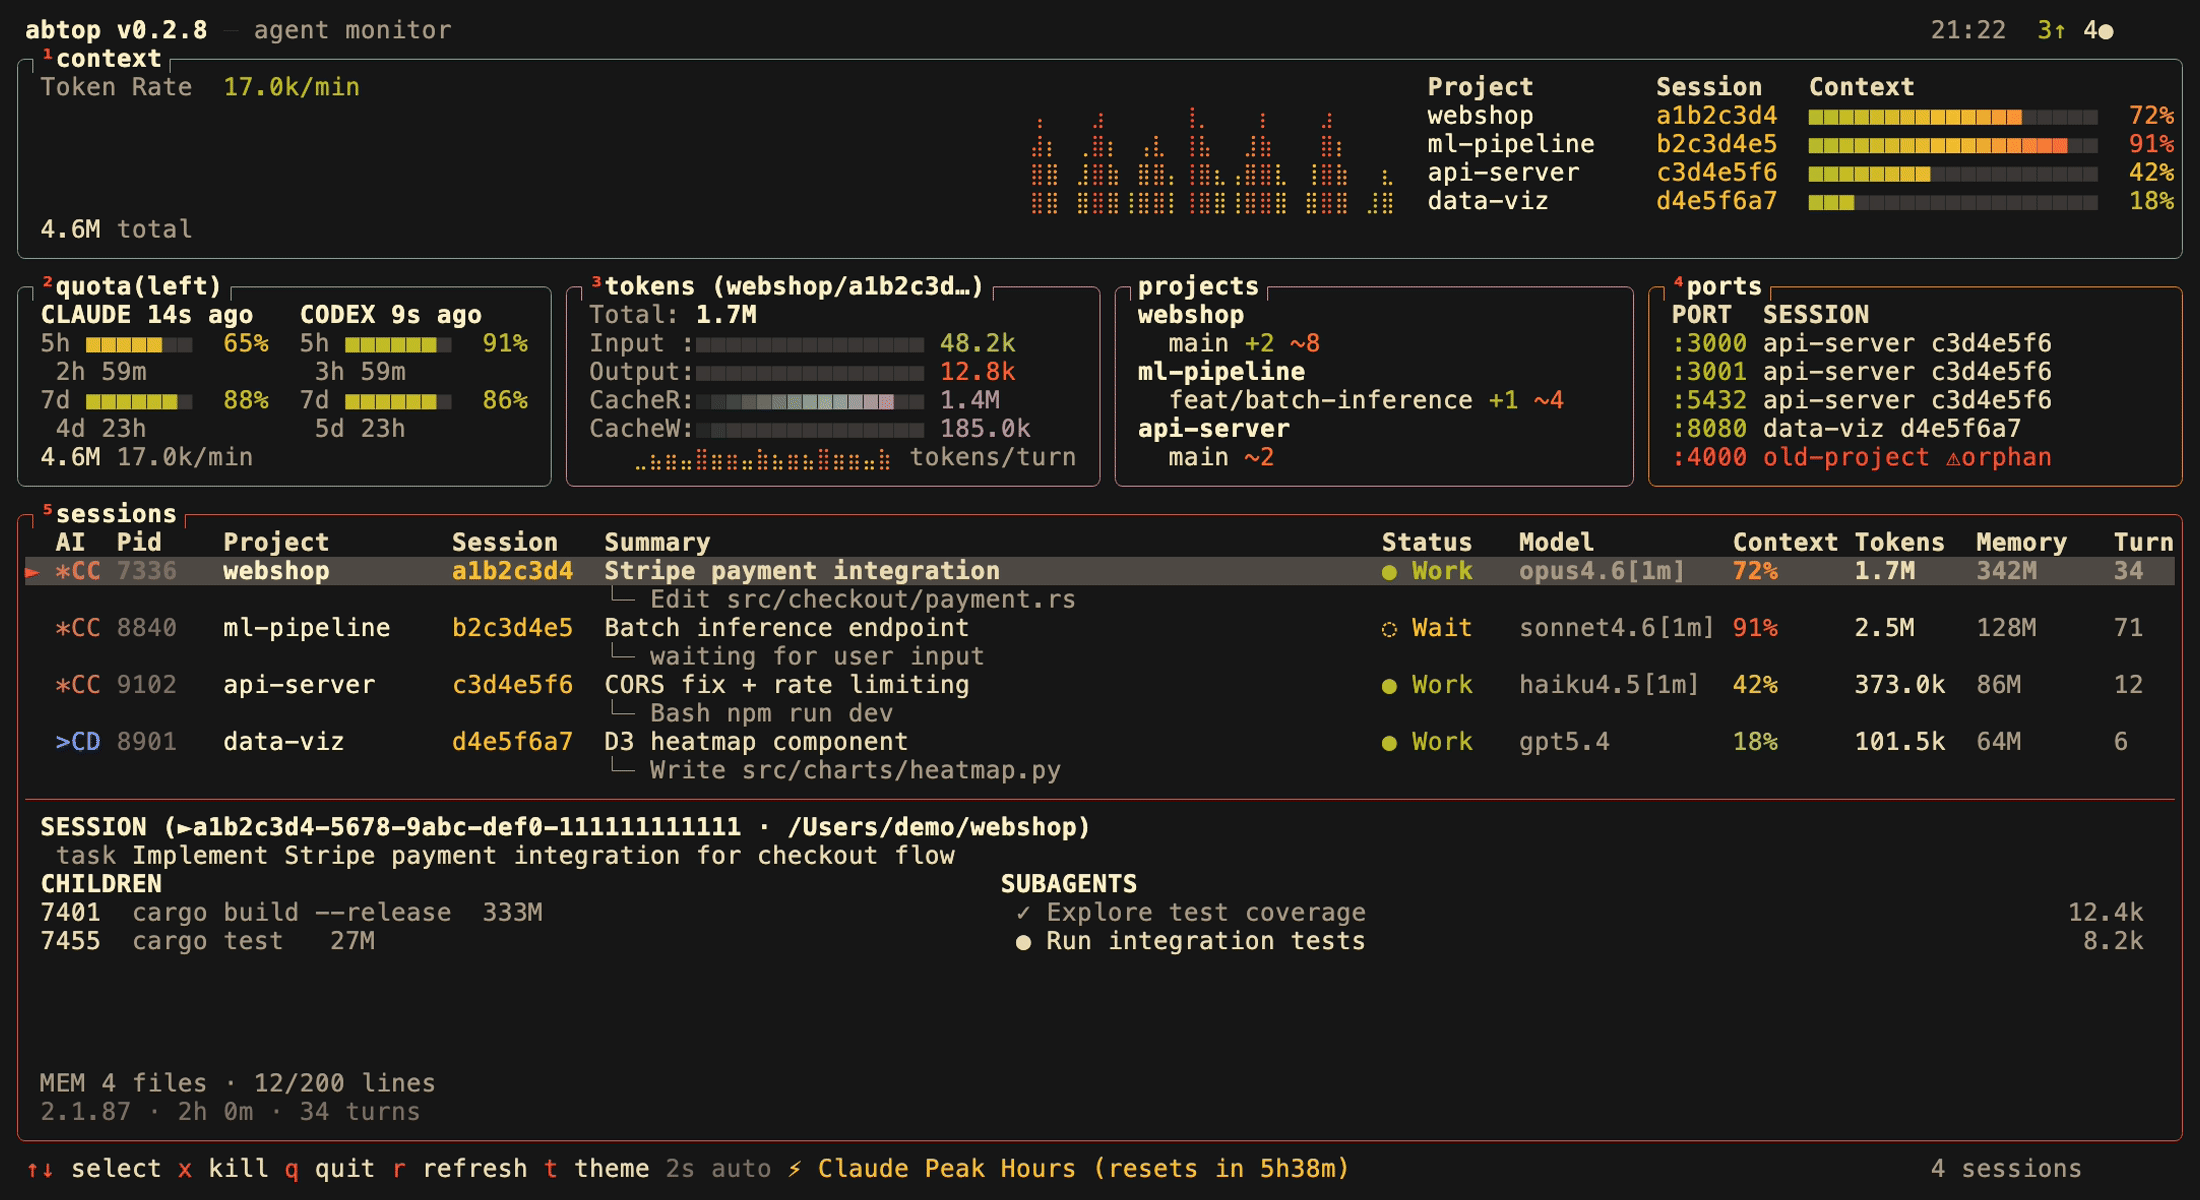 | 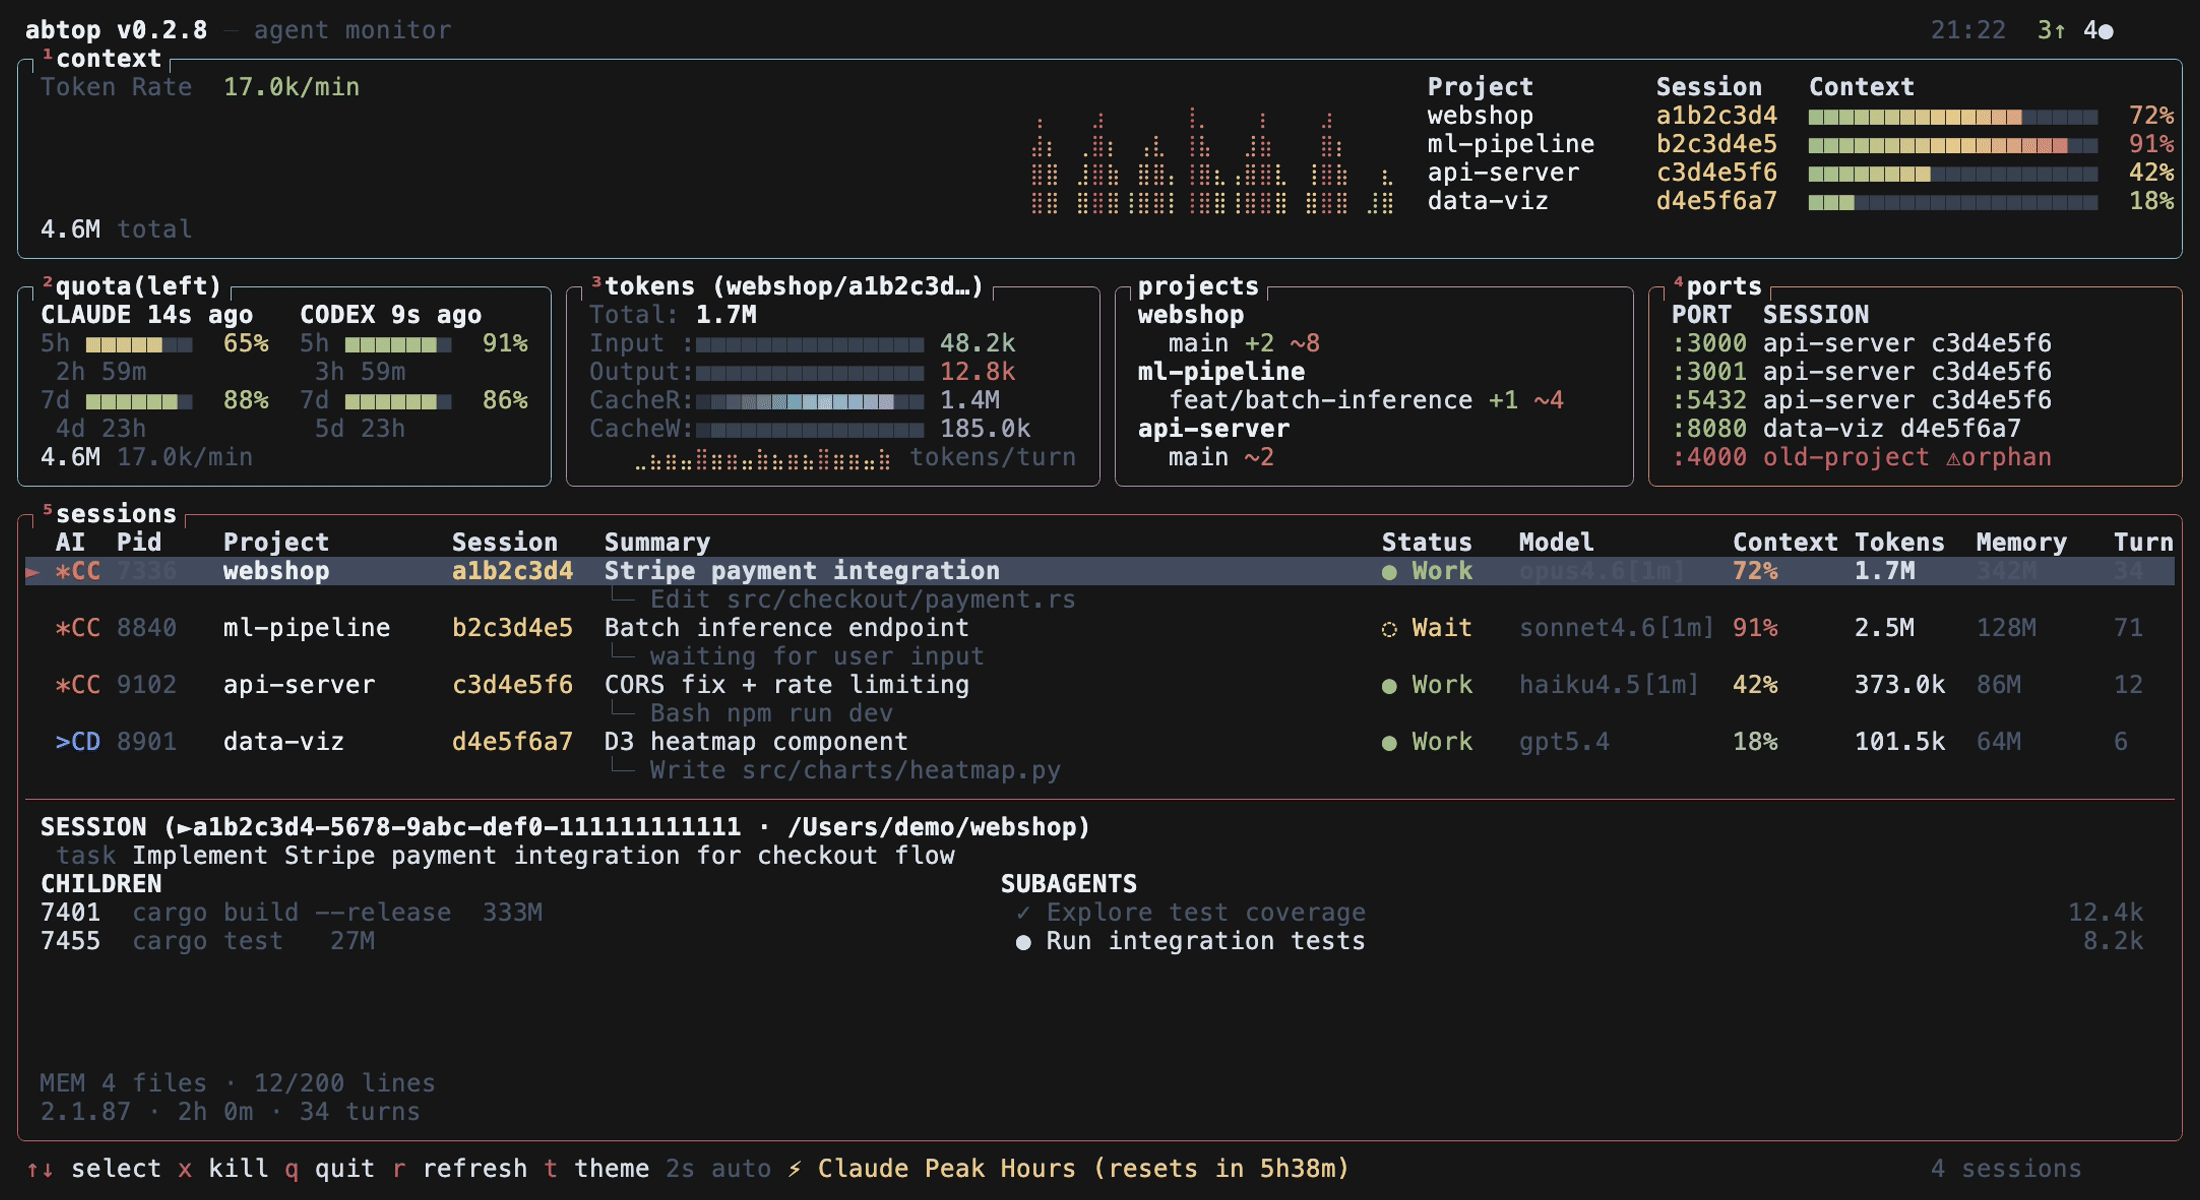 |
|
||||
|
||||
Colorblind-friendly themes:
|
||||
|
||||
| high-contrast | protanopia |
|
||||
|:-:|:-:|
|
||||
| 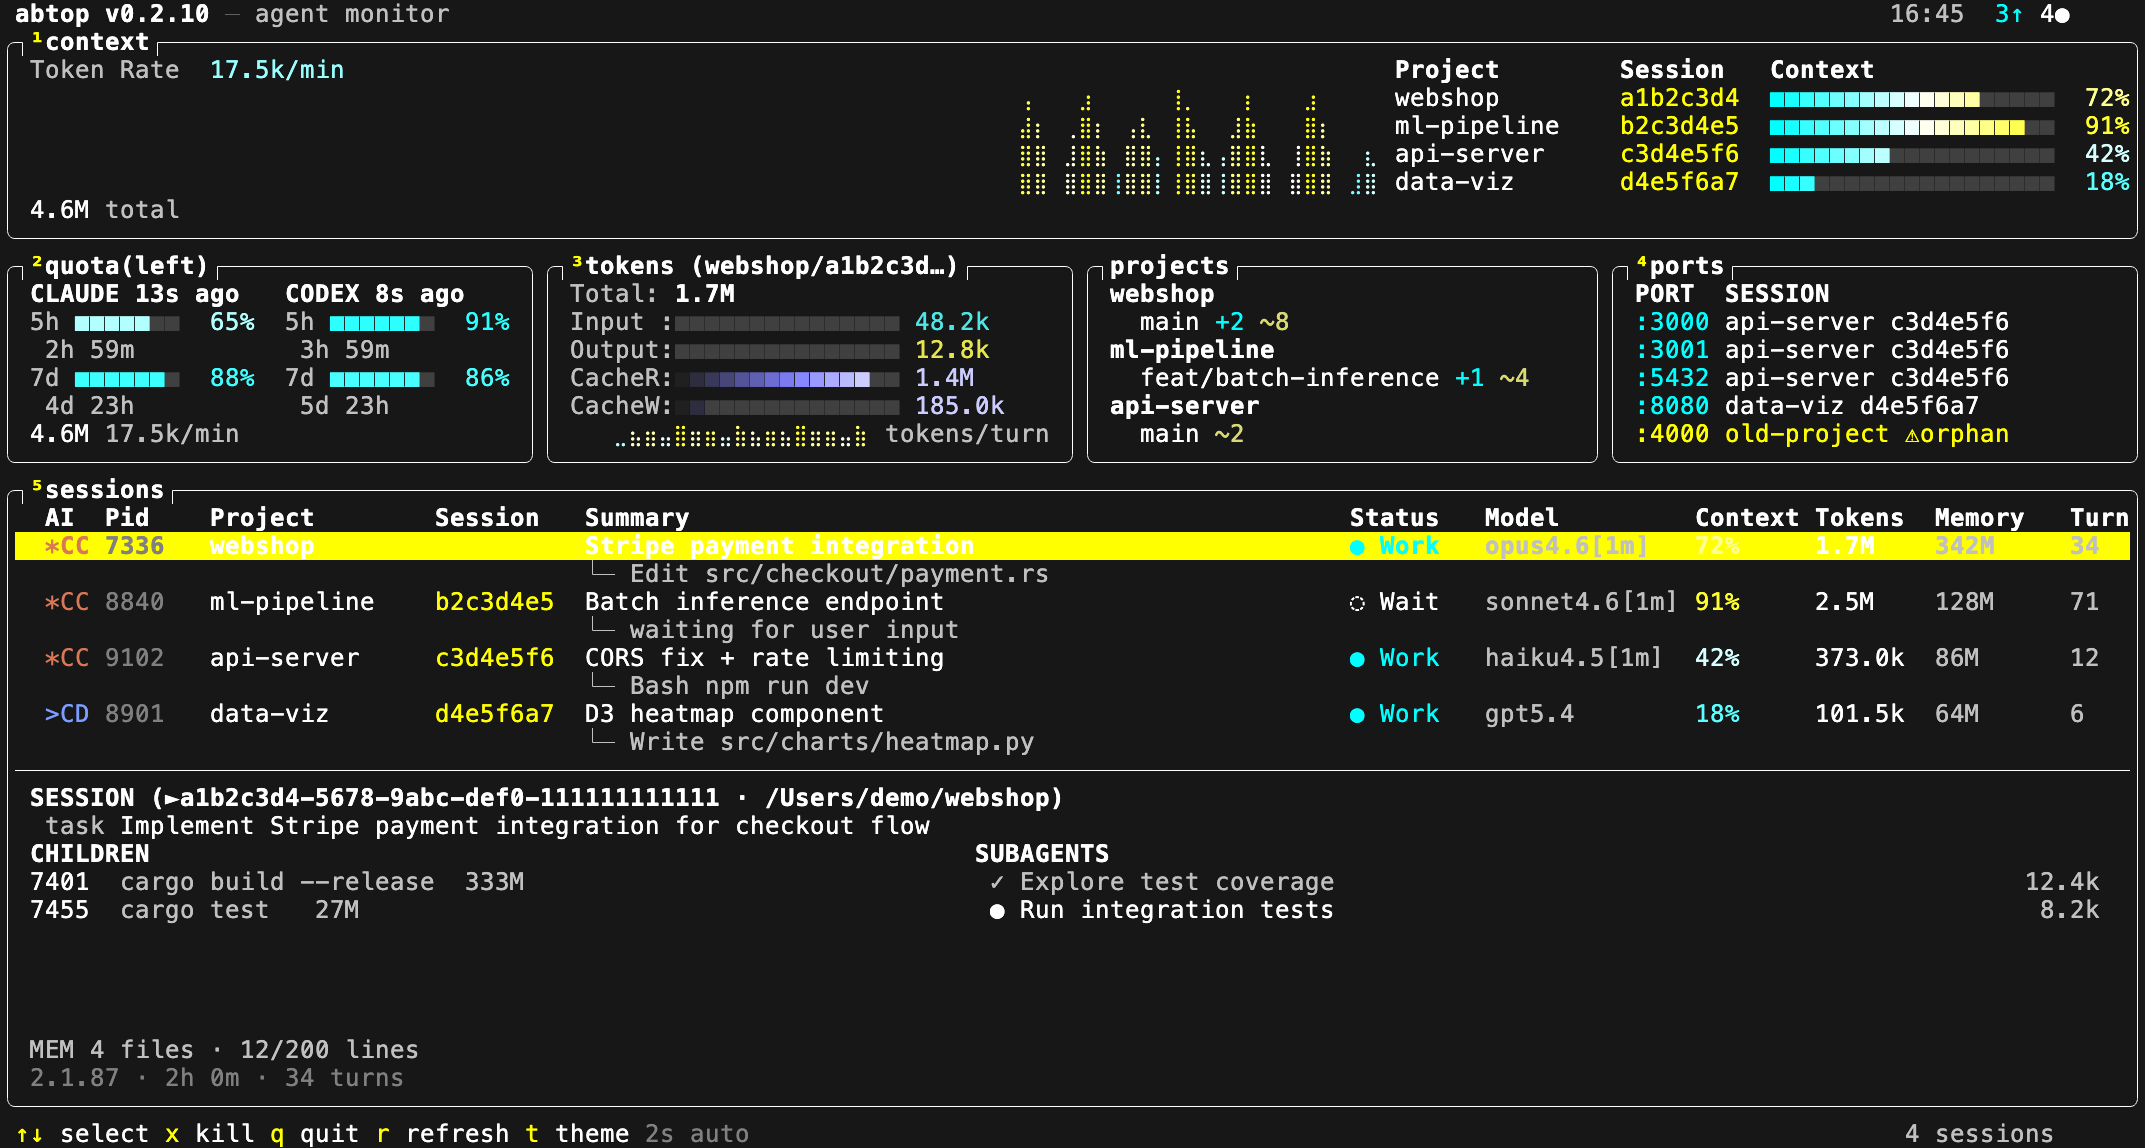 | 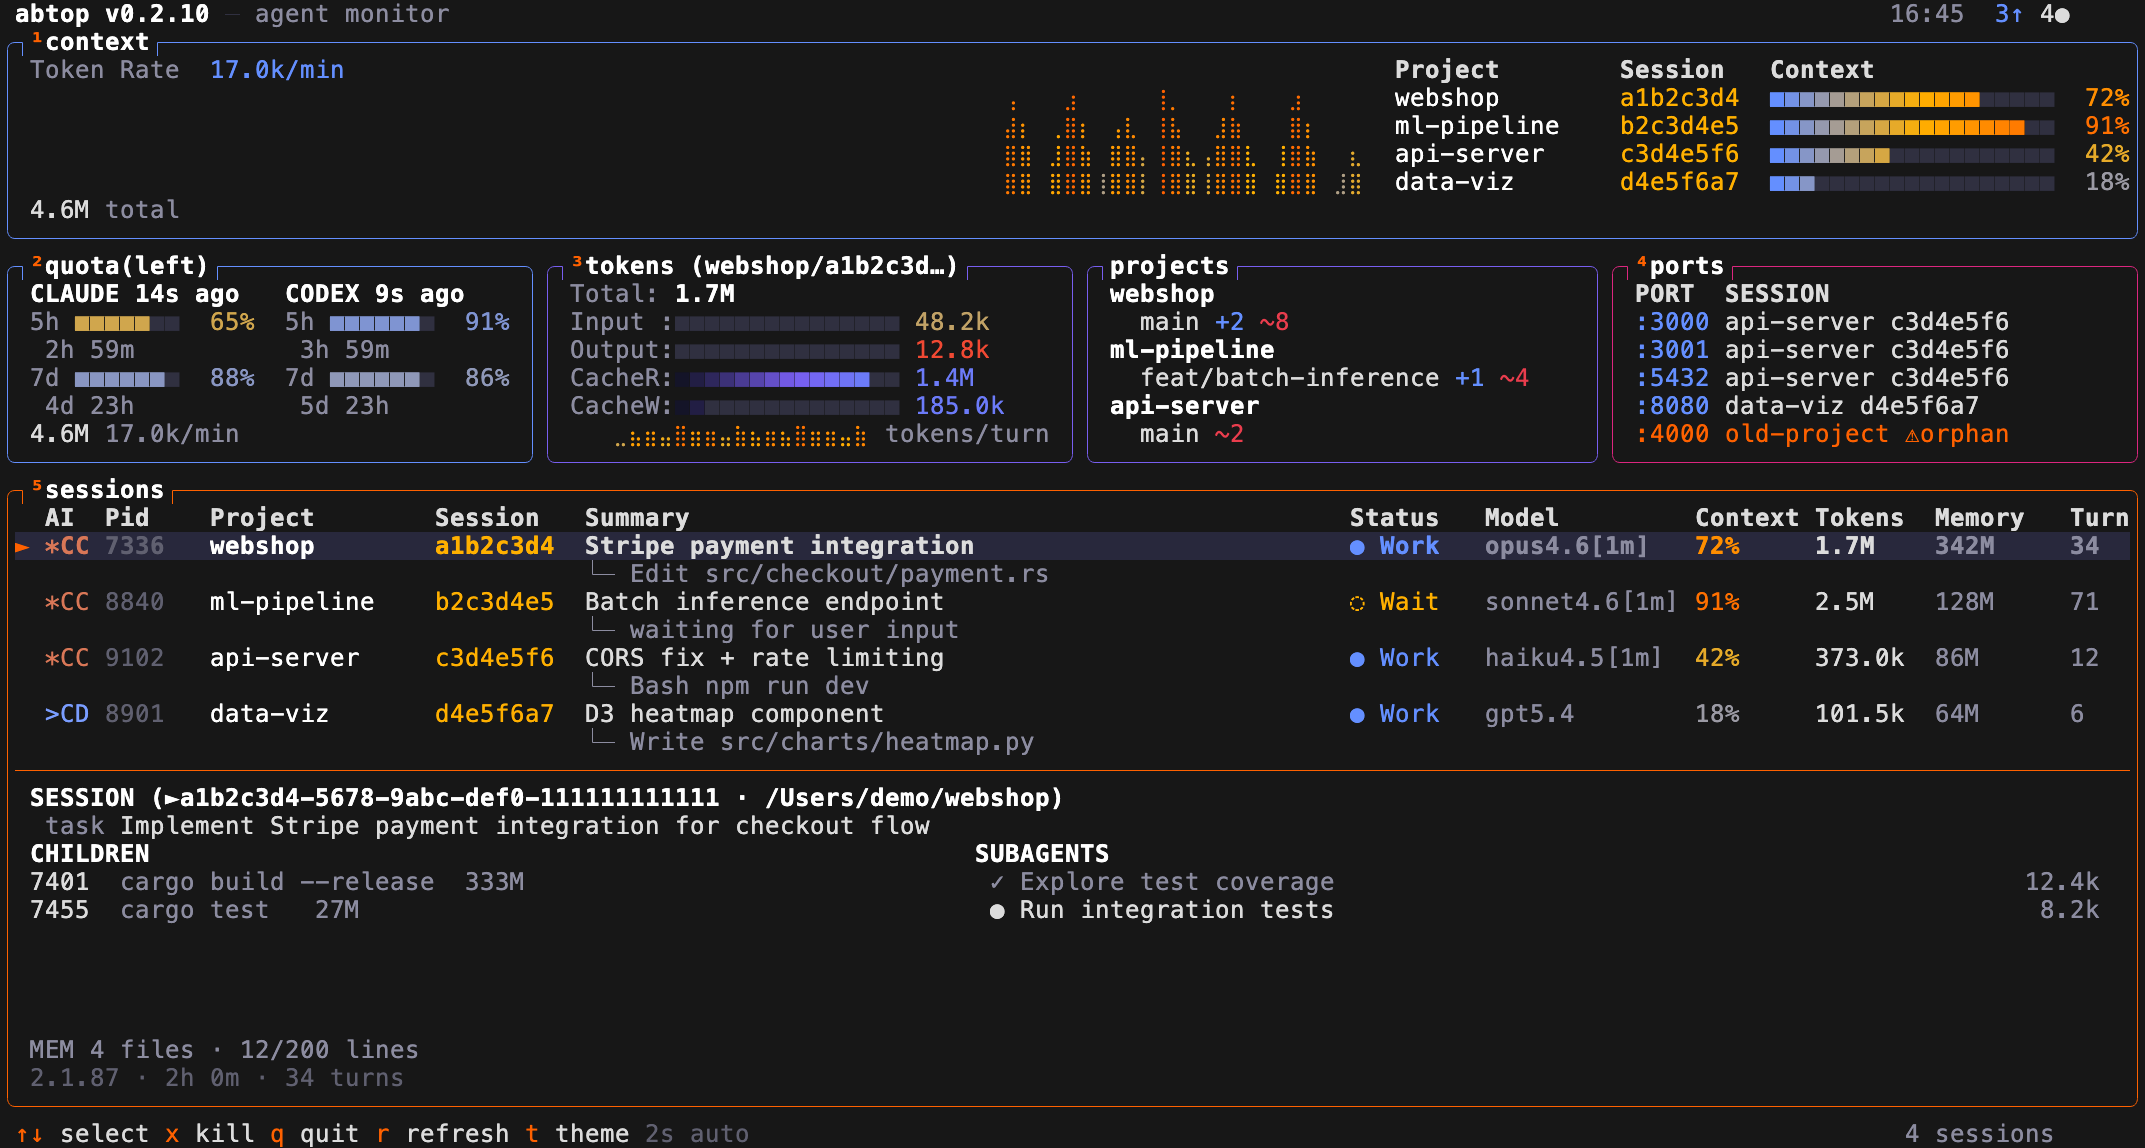 |
|
||||
|
||||
| deuteranopia | tritanopia |
|
||||
|:-:|:-:|
|
||||
| 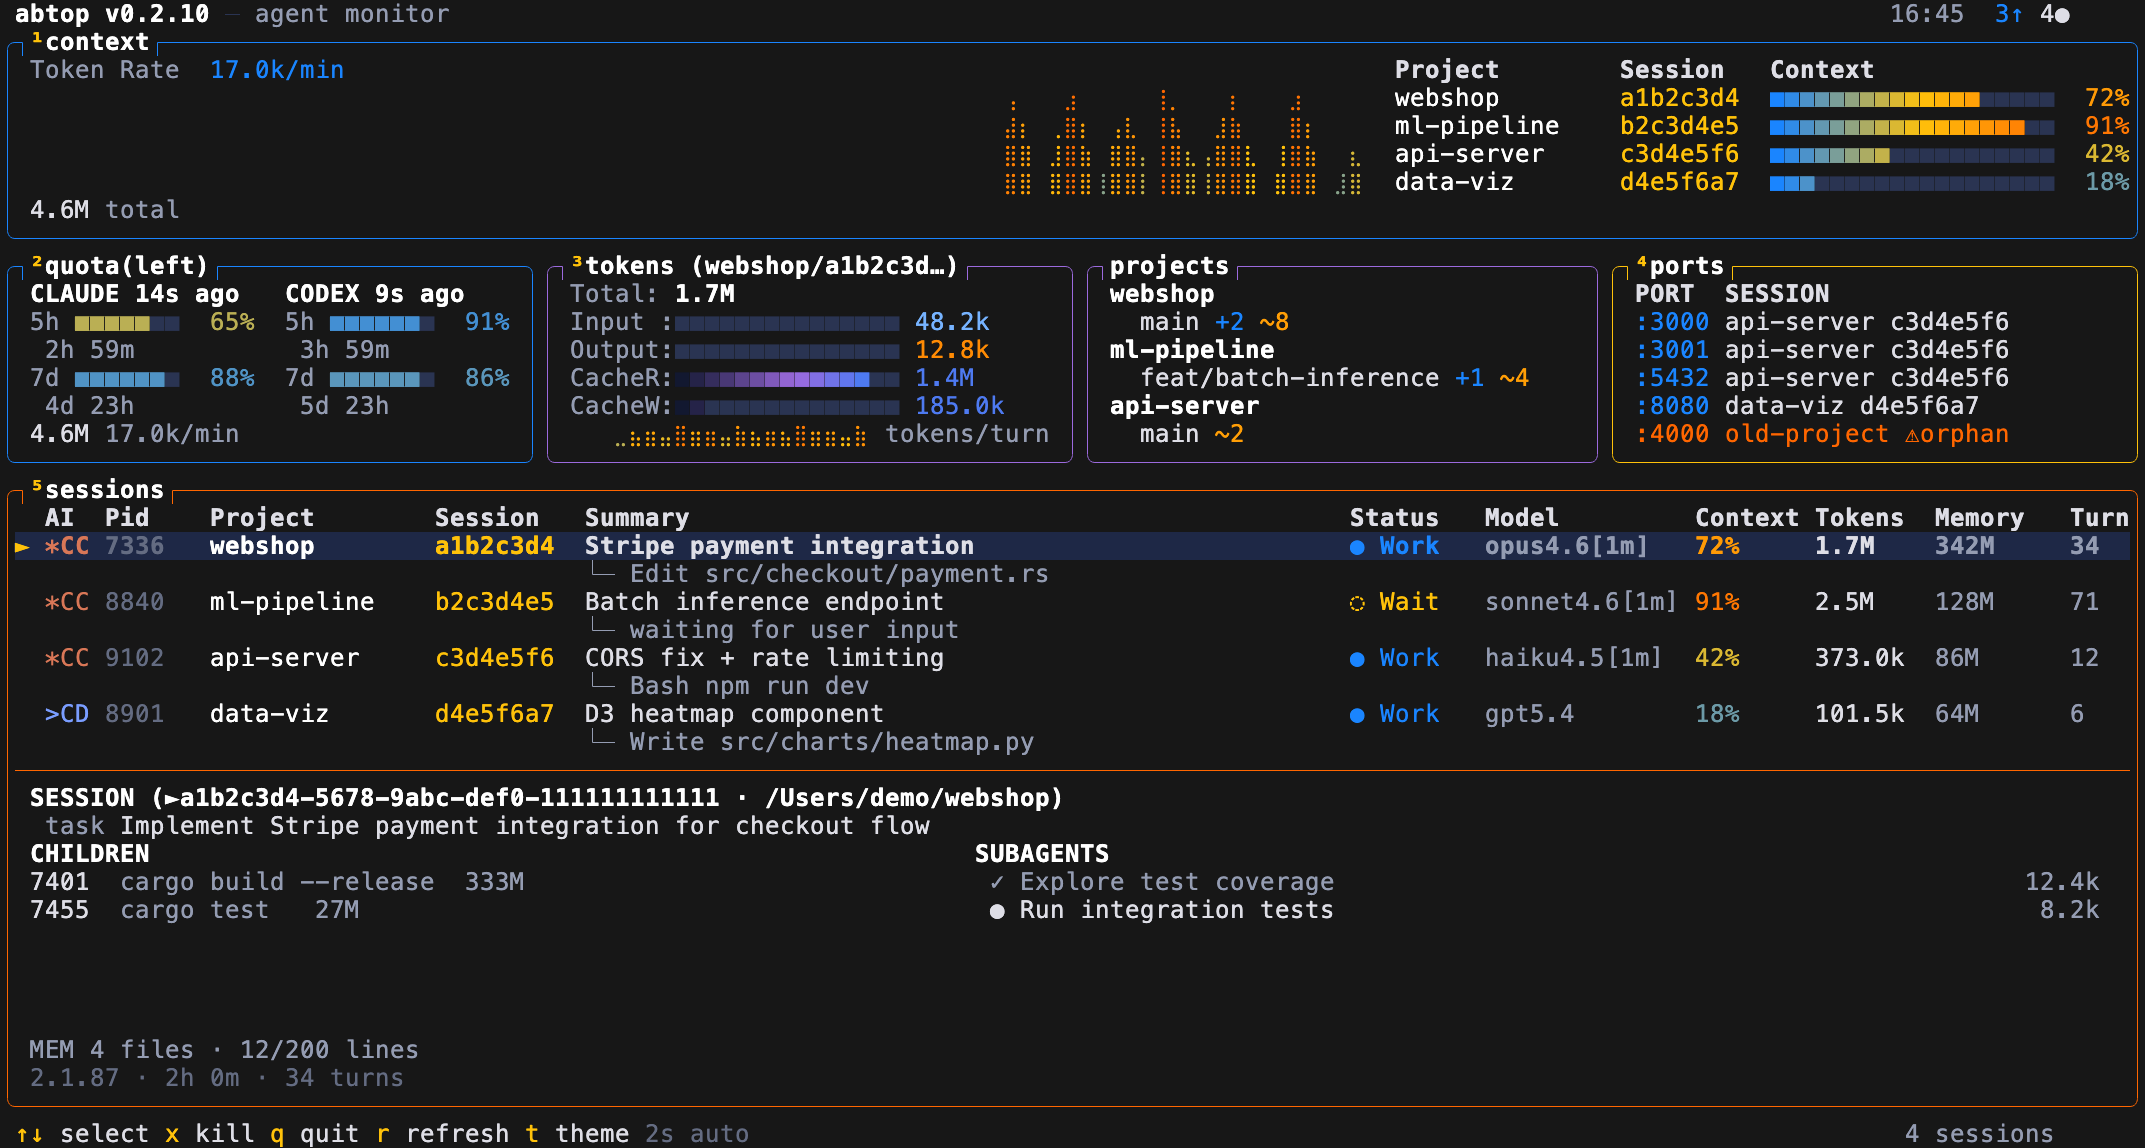 | 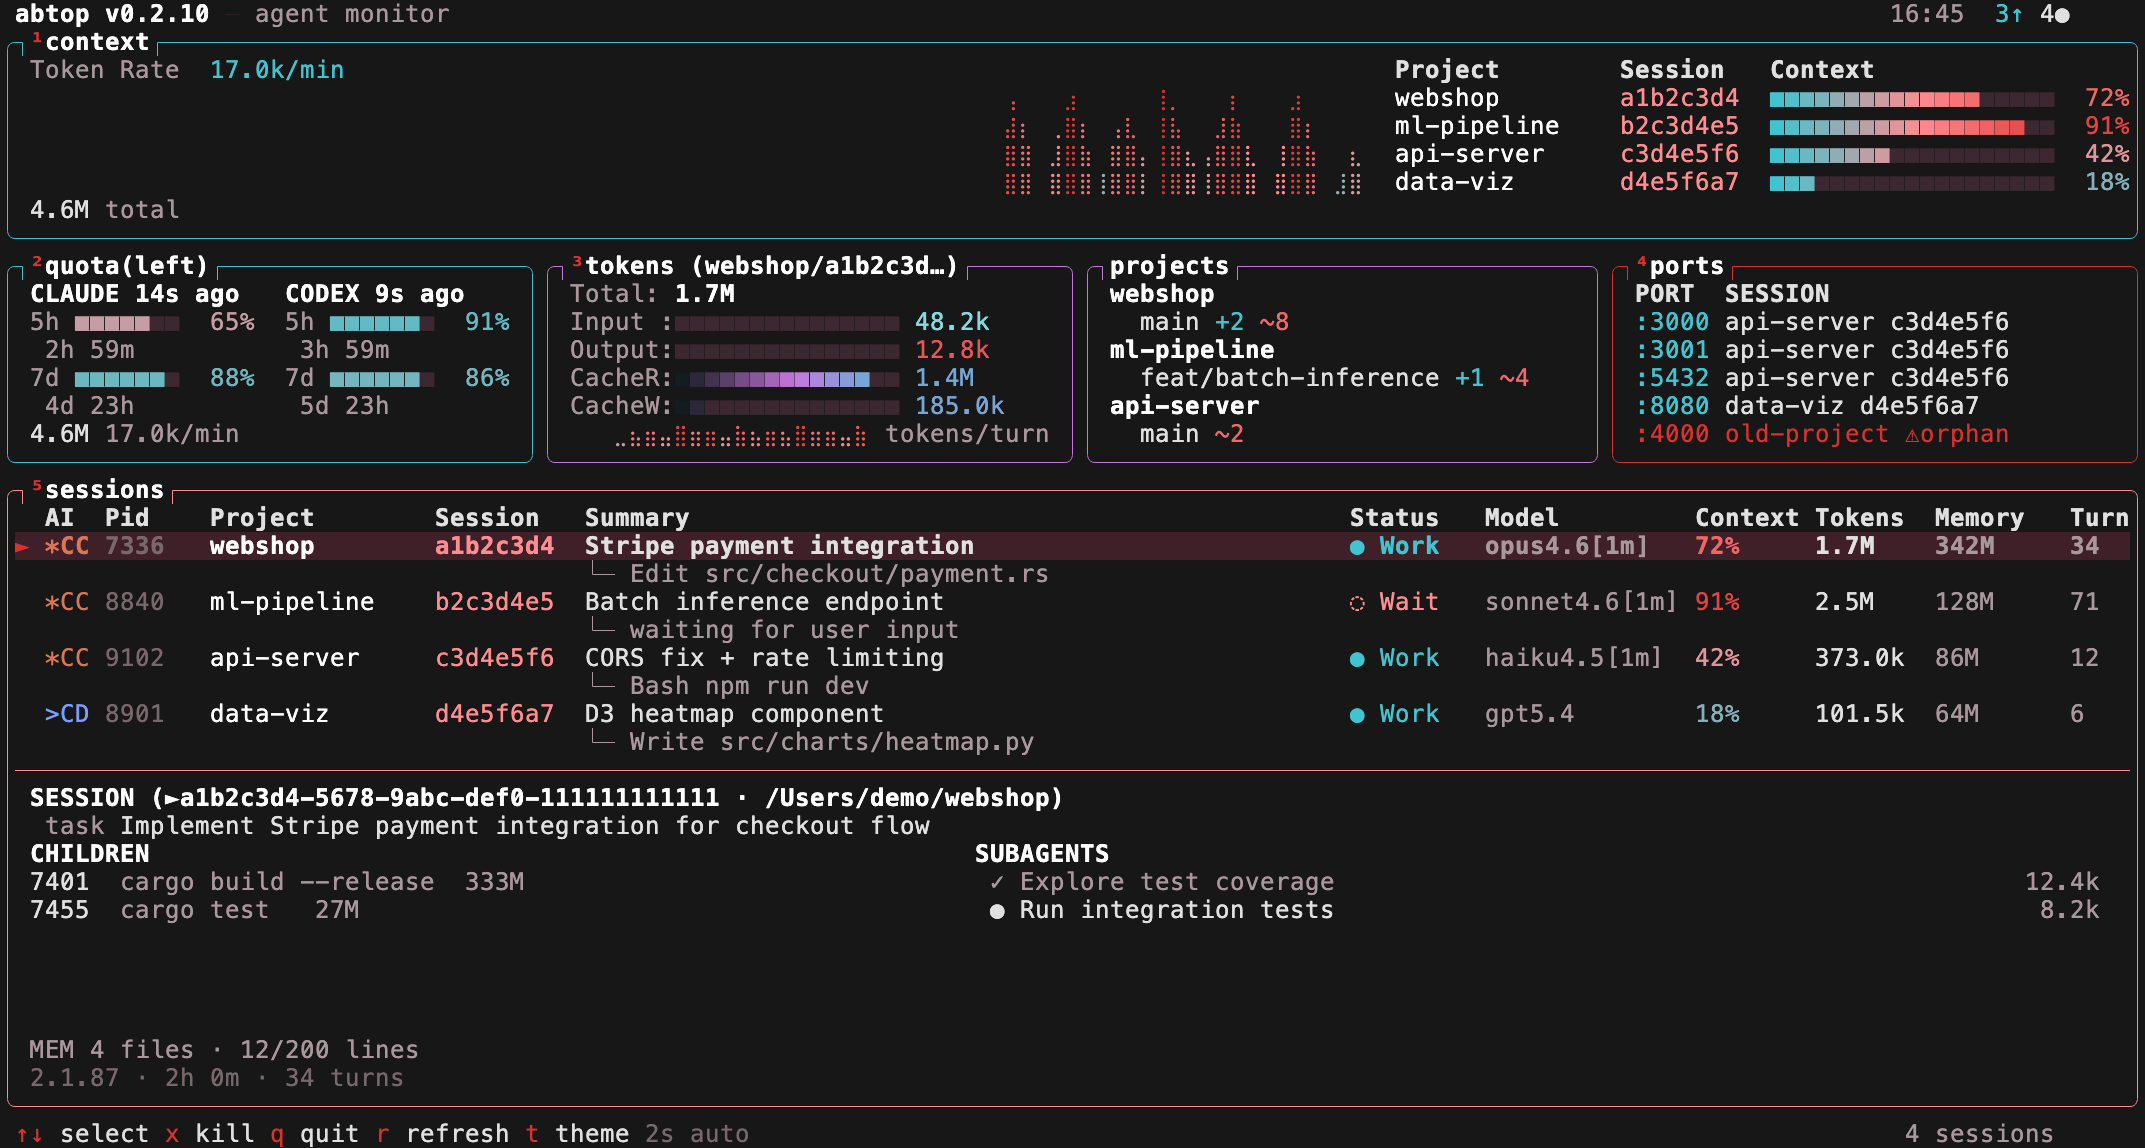 |
|
||||
|
||||
Light themes (`light` — Solarized cream, `white` — GitHub-style pure white) for bright terminals:
|
||||
|
||||
| light | white |
|
||||
|:-:|:-:|
|
||||
| 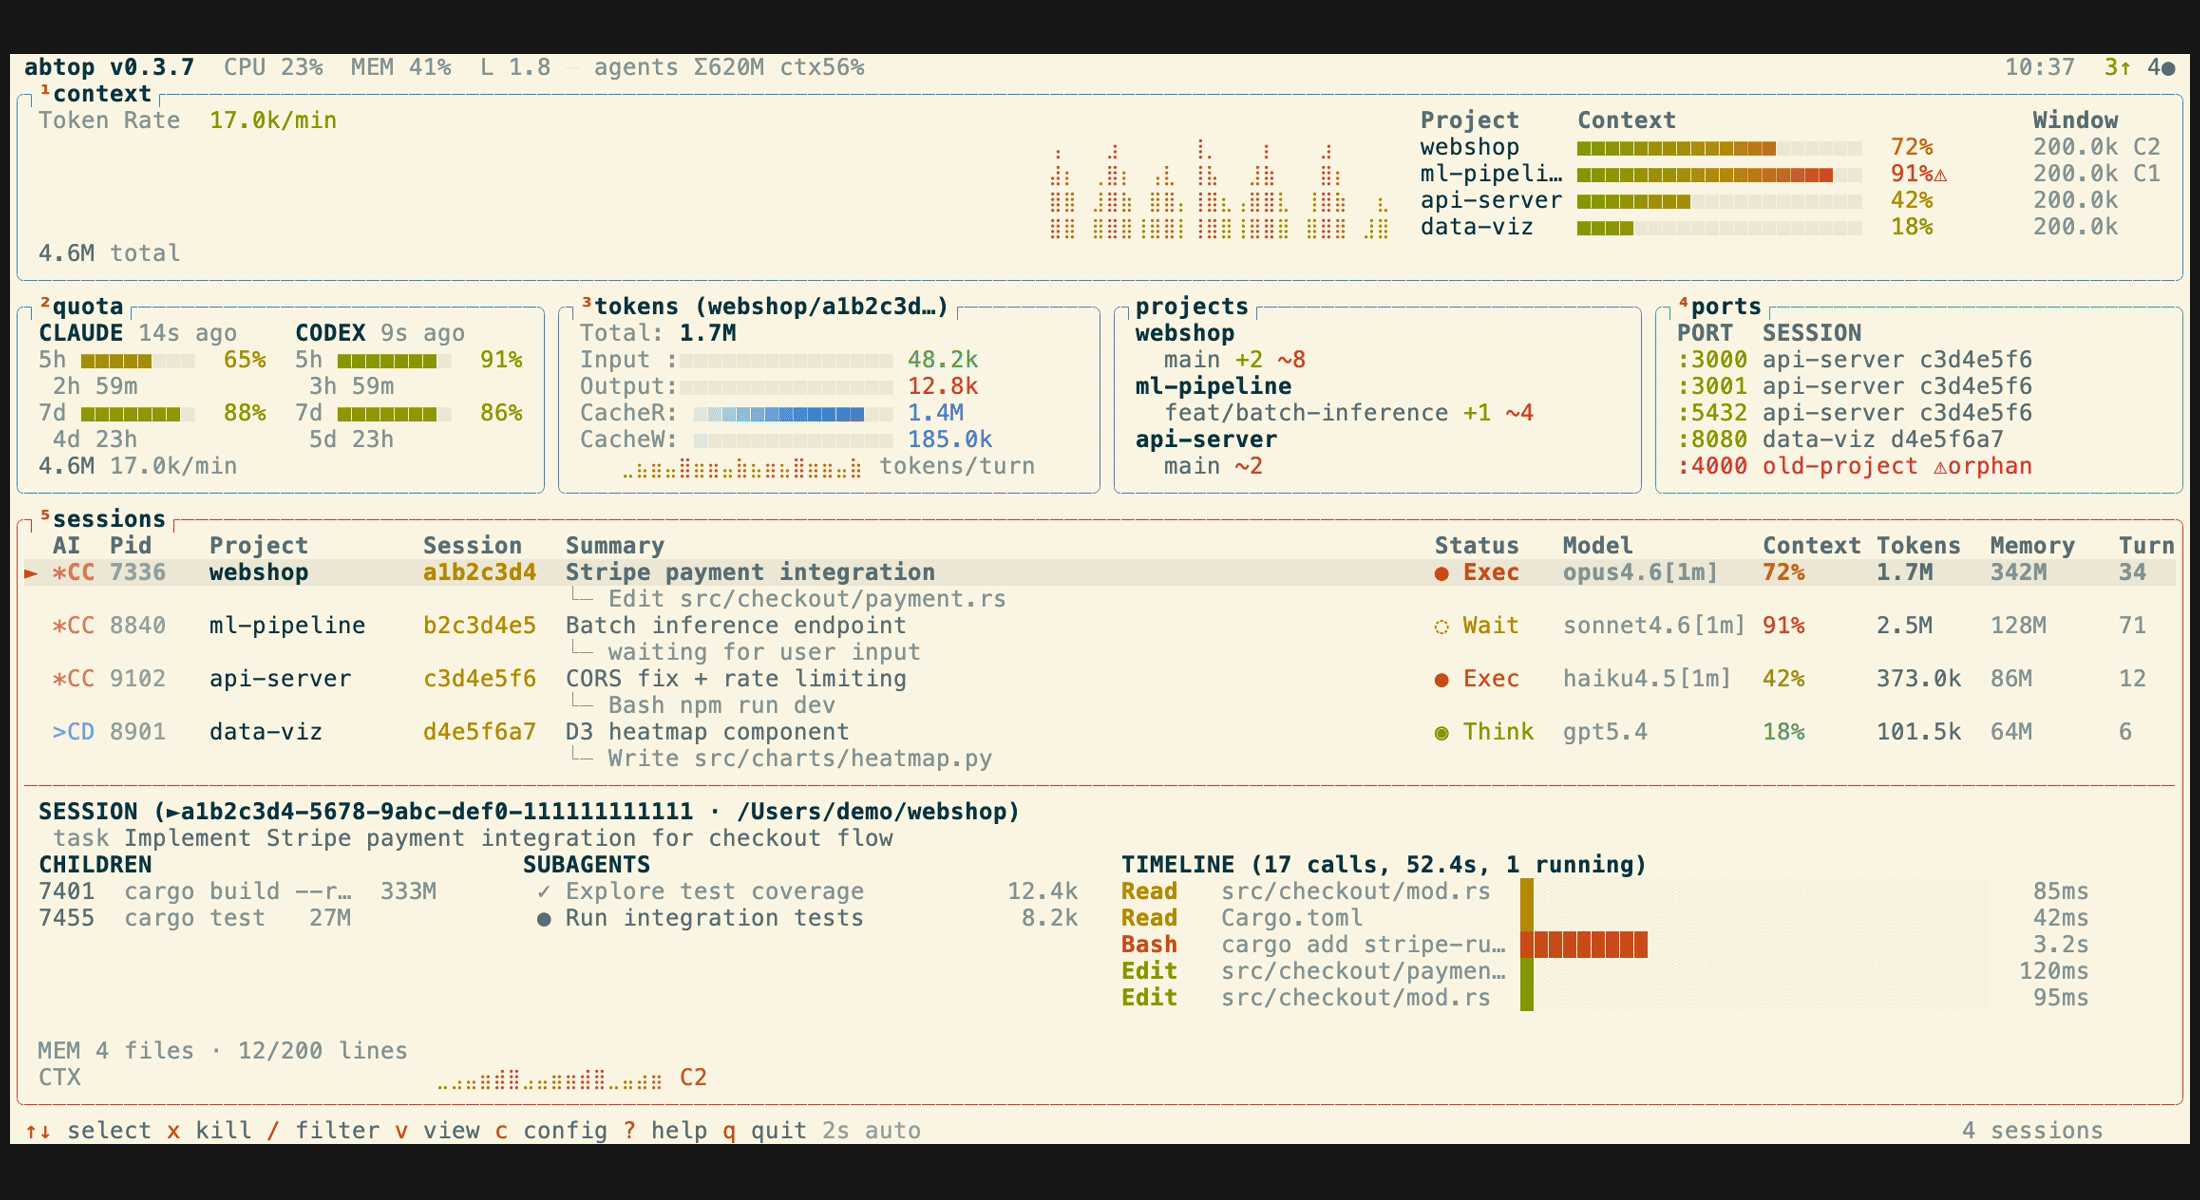 | 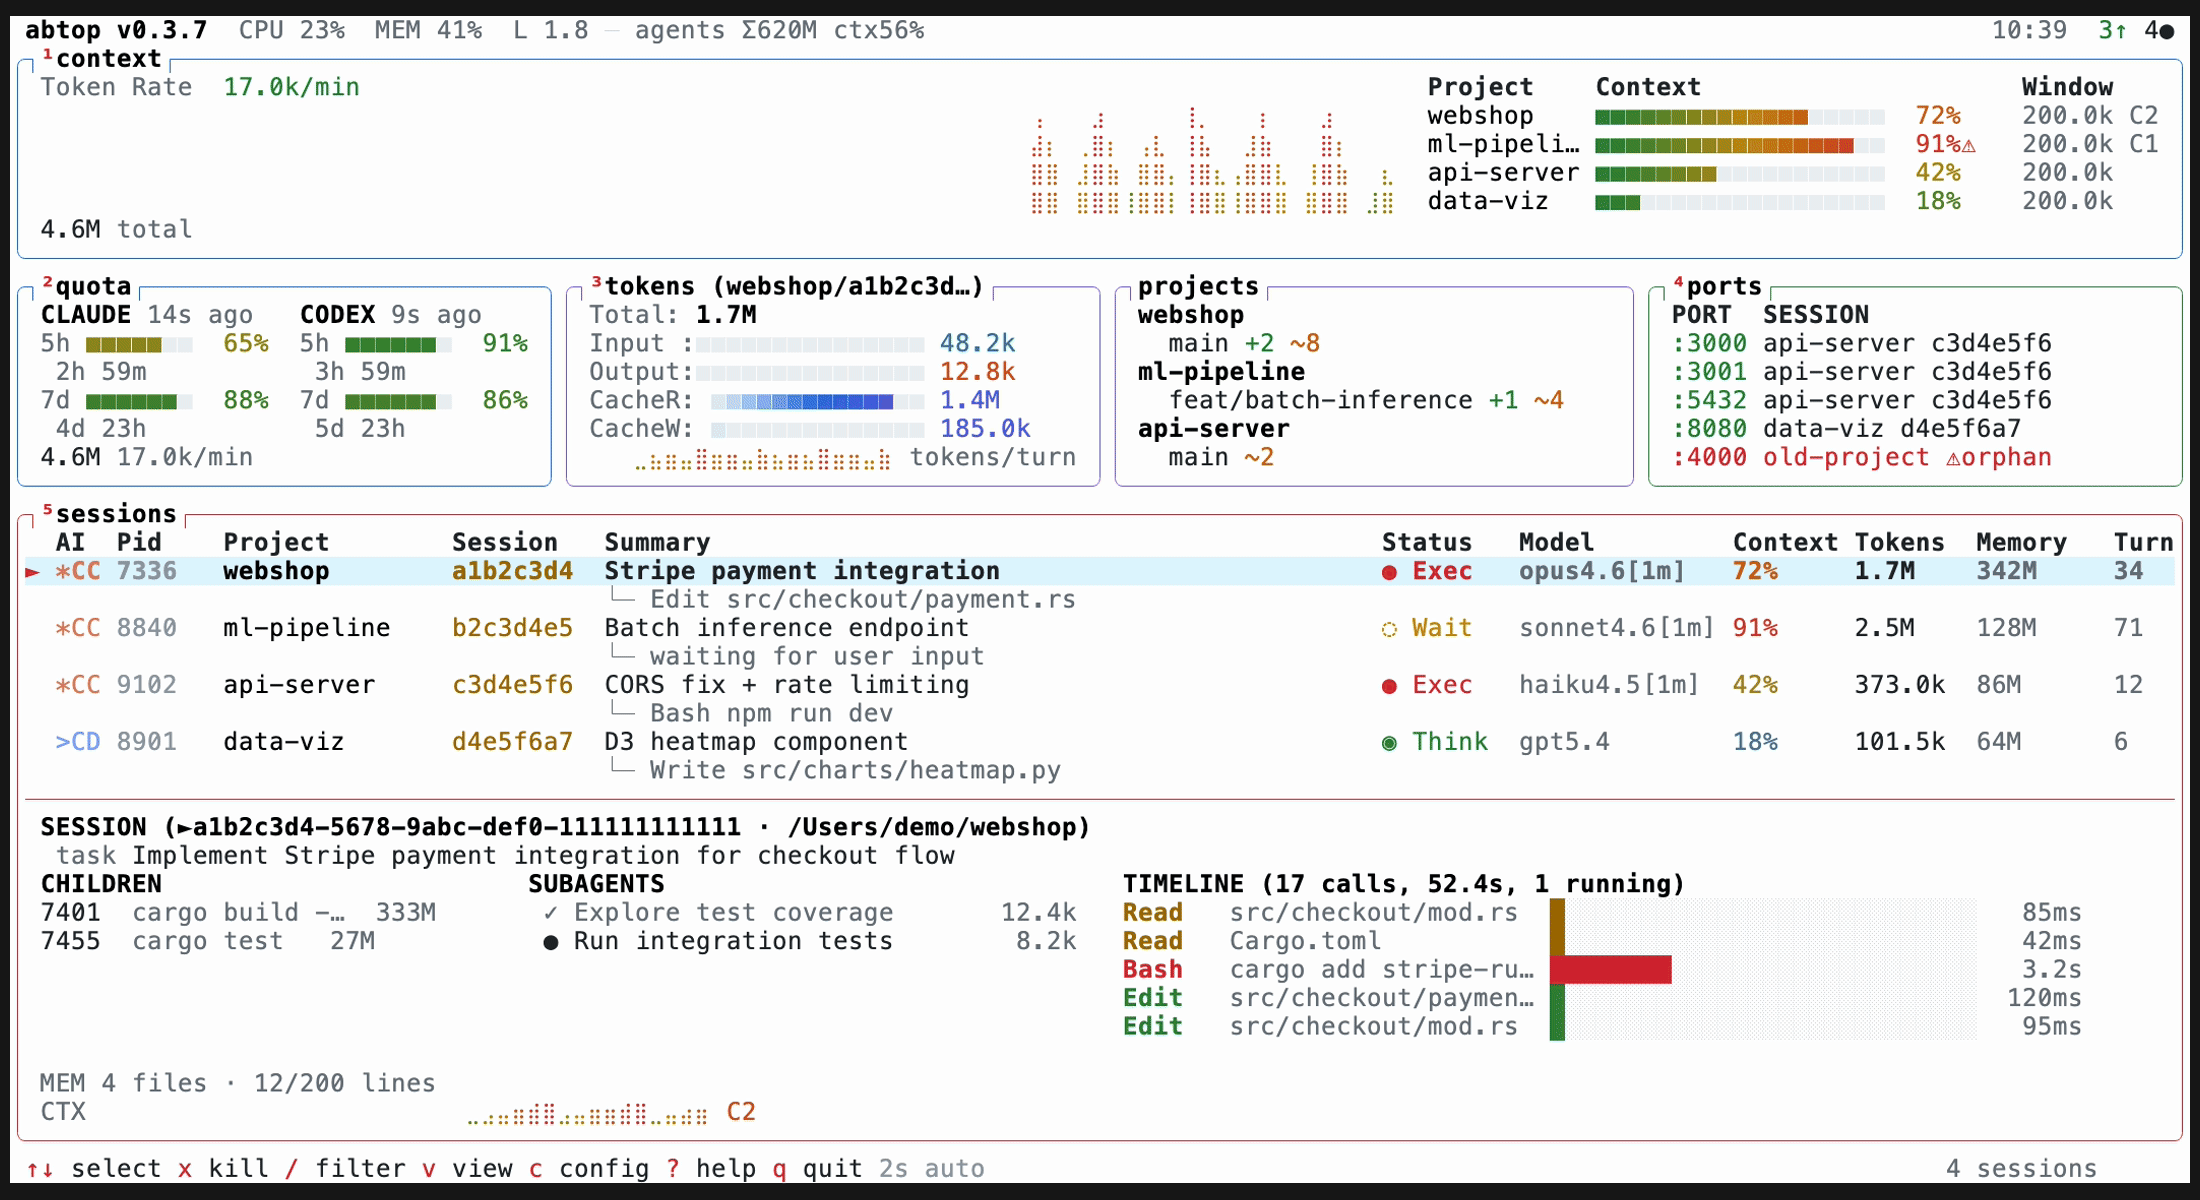 |
|
||||
|
||||
## Configuration
|
||||
|
||||
`~/.config/abtop/config.toml` supports:
|
||||
|
||||
```toml
|
||||
theme = "btop"
|
||||
# Hide specific agent CLIs from the TUI (case-insensitive).
|
||||
# Useful if you only use one agent and want a cleaner view.
|
||||
hidden_agents = ["codex"]
|
||||
# Additional Claude Code profile roots to scan.
|
||||
# abtop also auto-discovers ~/.claude and ~/.claude-* roots that contain
|
||||
# both sessions/ and projects/.
|
||||
claude_config_dirs = ["~/.claude-personal", "~/.claude-work-team"]
|
||||
# UI language. Omit or leave empty to auto-detect from LANG.
|
||||
language = "zh"
|
||||
```
|
||||
|
||||
### Supported Languages
|
||||
|
||||
| Code | Language |
|
||||
| ---- | ------------------- |
|
||||
| `en` | English (default) |
|
||||
| `zh` | Simplified Chinese |
|
||||
|
||||
When `language` is unset, abtop auto-detects from `LANG` — any value starting with `zh` switches to Simplified Chinese, otherwise English.
|
||||
|
||||
## Key Bindings
|
||||
|
||||
| Key | Action |
|
||||
| ------------------ | ------------------------------------ |
|
||||
| `↑`/`↓` or `k`/`j` | Select session |
|
||||
| `Enter` | Jump to session terminal |
|
||||
| `x` | Kill selected session |
|
||||
| `X` | Kill all orphan ports |
|
||||
| `t` | Cycle theme |
|
||||
| `1`–`5` | Toggle panel visibility |
|
||||
| `Esc` | Open/close config page |
|
||||
| `q` | Quit |
|
||||
| `r` | Force refresh |
|
||||
|
||||
## Library / JSON snapshot
|
||||
|
||||
abtop is also a library crate, so local tools can reuse its data-collection
|
||||
layer in-process — no re-scanning, no subprocesses — and serialize the same
|
||||
state the TUI renders.
|
||||
|
||||
```bash
|
||||
abtop --json # one-shot JSON snapshot for scripts
|
||||
```
|
||||
|
||||
For long-running consumers, build an `App`, refresh it with
|
||||
`App::tick_no_summaries()` (which never spawns `claude --print`, so it doesn't
|
||||
touch your Claude quota), and call `App::to_snapshot(interval_ms)` to get a
|
||||
JSON-serializable [`Snapshot`]:
|
||||
|
||||
```rust,no_run
|
||||
use abtop::app::App;
|
||||
use abtop::{config, theme::Theme};
|
||||
|
||||
let cfg = config::load_config();
|
||||
let mut app = App::new_with_config_and_claude_dirs(
|
||||
Theme::default(), &cfg.hidden_agents, cfg.panels, &cfg.claude_config_dirs,
|
||||
);
|
||||
app.tick_no_summaries();
|
||||
let json = serde_json::to_string(&app.to_snapshot(2_000)).unwrap();
|
||||
```
|
||||
|
||||
`App` is not `Send` (it owns the collectors), so keep it on one thread and pass
|
||||
the serialized JSON elsewhere. [abtop-web-ui](https://github.com/XKHoshizora/abtop-web-ui)
|
||||
is a reference consumer: a local-first web dashboard built on exactly this API.
|
||||
|
||||
## Privacy
|
||||
|
||||
abtop reads local files and local process/open-file metadata only. No API keys, no auth. In the TUI and `--once` output, tool names and file paths are shown, but file contents and prompt text are never displayed. Session summaries are generated via `claude --print`, which makes its own API call — this is the only indirect network usage.
|
||||
|
||||
The JSON snapshot includes richer local dashboard data, including `summary`, `chat_messages`, working directories, config roots, tool-call previews, child process commands, token counts, and port metadata. Chat text is bounded and redacted by the collectors, but it is still derived from local transcripts and may contain sensitive project context. Treat JSON snapshots as local/private data and avoid writing them to shared logs or exposing them on a network without your own access controls.
|
||||
|
||||
## Acknowledgements
|
||||
|
||||
Huge thanks to [@tbouquet](https://github.com/tbouquet) for driving much of abtop's recent shape — themes, config overlay and panel toggles, session filtering, subagent tree view, the context window gauge with compaction detection, plus a steady stream of fixes and security hardening along the way.
|
||||
|
||||
## License
|
||||
|
||||
MIT
|
||||
|
||||
@@ -0,0 +1,239 @@
|
||||
---
|
||||
source_url: "https://a11y-chiba.com/2026/"
|
||||
ingested: 2026-06-30
|
||||
sha256: e1c8b2c11b375a9c3b6a425f3ba68301877aa39b7f0e455b00cb863e230ed4d1
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521445609318649867"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T09:21:40.354000000Z"
|
||||
message_excerpt: "Accessibility Conference CHIBA page with Ontenna and Ekimatope examples: sound converted to vibration, light, text, sign-language, and onomatopoeia."
|
||||
score: 4
|
||||
---
|
||||
|
||||
|
||||
|
||||
2026年9月5日(土)開催決定! スポンサー申込受付中です!
|
||||
|
||||
|
||||
|
||||
## 開催テーマ
|
||||
|
||||
変わるものと 変わらないもの
|
||||
|
||||
アクセシビリティを取り巻く環境は、テクノロジーの飛躍的な進化と社会的な認知の広がりにより、激しい変化の中にあります。
|
||||
|
||||
昨日の「驚き」が今日の「当たり前」となるほど、私たちの生活は日々便利に、
|
||||
|
||||
そして多様にアップデートされ続けています。
|
||||
|
||||
しかし、どれほど技術や環境が変化しても、「年齢や障害の有無、国籍などに関わらず、
|
||||
|
||||
誰もが必要な情報にたどり着き、利用できる」というアクセシビリティの本質は揺るぎません。
|
||||
|
||||
本イベントでは、この「変わるもの」と「変わらないもの」をテーマに、未知の技術や視点に触れることで、
|
||||
|
||||
参加者の皆様の中に新たな気づきや道が拓かれる――そんな機会を、ここ千葉から創出します。
|
||||
|
||||
## 開催概要
|
||||
|
||||
日程
|
||||
|
||||
2026年9月5日(土曜日) 11:00〜18:30
|
||||
|
||||
参加費
|
||||
|
||||
無料
|
||||
|
||||
会場
|
||||
|
||||
幕張メッセ 国際会議場2階 国際会議室 [千葉県千葉市美浜区中瀬2丁目1-1](https://maps.app.goo.gl/2r62FVoQ4byM3fGfA)
|
||||
|
||||
会場定員
|
||||
|
||||
150名
|
||||
|
||||
オンライン配信
|
||||
|
||||
YouTubeにて通常版・情報保障版同時ライブ配信予定
|
||||
|
||||
セッション
|
||||
|
||||
- メインセッション2コマ
|
||||
- ライトニングトーク2コマ
|
||||
- スポンサーセッション2コマ
|
||||
|
||||
主催
|
||||
|
||||
株式会社ノベルティ アクセシビリティカンファレンスCHIBA実行委員会
|
||||
|
||||
[参加申込](https://a11y-chiba.connpass.com/event/389386/)
|
||||
|
||||
 
|
||||
|
||||
## 会場マップ
|
||||
|
||||
- ### 座席エリア
|
||||
セッション時間 13時から17時
|
||||
椅子に腰掛けてセッションを聞くことができます。 各座席にはテーブルの用意があるため、PCやノートにメモをとる際も安心。
|
||||
- ### 体験ブースエリア
|
||||
ブース展示時間 11時から18時30分
|
||||
さまざまなプロダクトを実際に見て触って体験することができます。 気になるプロダクトはあるかな?
|
||||
- ### 休憩エリア
|
||||
利用可能時間 11時から18時30分
|
||||
疲れたらひとやすみ。 椅子とテーブルがあります。 気軽に遊べるゲームや参加型のコーナーもご用意しています。(飲食可能)
|
||||

|
||||
|
||||
会場マップ。入り口から入ると、正面に受付があります。左側には休憩エリアがあり、椅子とテーブルがあります。奥に進むと、体験ブースエリアとスポンサーブースエリアがあります。さらに奥に進むと、メインステージのある座席エリアがあり、多数の椅子が並んでいます。座席エリアには手話通訳とUDトークのサポートがあります。
|
||||
|
||||
- 照明により、会場内は明るい環境です
|
||||
- 会場内は来場者が多く、時間帯により混雑します
|
||||
- メイン導線は平坦ですが、一部に段差・凹凸があります
|
||||
|
||||
### 会場周辺案内
|
||||
|
||||

|
||||
|
||||
トイレ
|
||||
|
||||
女子トイレ内ベビーシート
|
||||
|
||||
バリアフリートイレ
|
||||
|
||||
オストメイトトイレ
|
||||
|
||||
会場フロア内に2箇所ずつございます
|
||||
|
||||

|
||||
|
||||
喫煙所
|
||||
|
||||
建物外1階にございます
|
||||
|
||||

|
||||
|
||||
エレベーター
|
||||
|
||||
建物内に1箇所(2基)ございます
|
||||
|
||||
[PDFダウンロード](https://a11y-chiba.com/docs/map.pdf)
|
||||
|
||||
## タイムテーブル
|
||||
|
||||
11:00-
|
||||
|
||||
開場、受付開始
|
||||
|
||||
11:00-
|
||||
|
||||
スポンサーブース、体験ブース展示(ブースの展示は18:30まで)
|
||||
|
||||
11:00-13:00
|
||||
|
||||
自由見学・交流
|
||||
|
||||
13:00-13:15
|
||||
|
||||
セッションオープニング
|
||||
|
||||
13:20-16:35
|
||||
|
||||
トークセッション
|
||||
|
||||
- メインセッション2コマ
|
||||
- ライトニングトーク2コマ
|
||||
- スポンサーセッション2コマ
|
||||
|
||||
16:45-17:00
|
||||
|
||||
セッションクロージング
|
||||
|
||||
17:00-18:30
|
||||
|
||||
会場交流会
|
||||
|
||||
18:30
|
||||
|
||||
閉場
|
||||
|
||||
## スポンサー募集
|
||||
|
||||
スポンサー様向け企画概要資料をご確認いただき、フォームよりお申し込みください。
|
||||
|
||||
各スポンサー種別にはお申し込み上限を設けております。先着順での受付となりますため、ご希望に添いかねる場合がございます。
|
||||
|
||||
あらかじめご了承ください。
|
||||
|
||||
[スポンサー募集概要資料はこちら(PDF)](https://drive.google.com/file/d/1lk7nOEa1QcpkeVc3MB9RXfoS3iWUYE9i/view?usp=drive_link)
|
||||
|
||||
[お申込みフォーム](https://forms.gle/AiYat4bj1doWJnN79)
|
||||
|
||||
## インクルーシブパートナー
|
||||
|
||||
[](https://playworks-inclusivedesign.com/)[ ](https://kankaku.cloudfree.jp/)[ ](https://www.ashirase.com/)[ ](https://global.fujitsu/ja-jp)[](https://www.kokuyo.com/)
|
||||
|
||||
### 体験ブース紹介
|
||||
|
||||
 
|
||||
|
||||
PLAYWORKS株式会社
|
||||
|
||||
視覚障害者歩行テープ「ココテープ」・ロービジョン体験キット・指差しコミュニケーションパンフレット
|
||||
|
||||
[https://playworks-inclusivedesign.com](https://playworks-inclusivedesign.com/)
|
||||
|
||||
PLAYWORKS株式会社は、障害者など多様なリードユーザーとの共創からイノベーションを創出する、インクルーシブデザイン・アクセシビリティのコンサルティングファームです。 本ブースでは、必要な場所に簡単に設置できる点字ブロック「ココテープ」、弱視の多様な見えにくさを体験する「ロービジョン体験キット」をご体験いただけるほか、「指差しコミュニケーションパンフレット」「白杖ステッカー」の配布を行います!
|
||||
|
||||
 
|
||||
|
||||
ちょっとずつ違う
|
||||
|
||||
感覚で遊ぶ、アナログゲーム
|
||||
|
||||
[https://kankaku.cloudfree.jp/](https://kankaku.cloudfree.jp/)
|
||||
|
||||
厚み・大きさ・色・音のわずかな違いを感じ取る「感覚ゲーム」シリーズ。知識や言語に頼らないため、子どもから高齢者まで、視覚・言語に障がいのある方や日本語を話さない方も一緒に楽しめます。家庭・学校・福祉の場など、多様なシーンで活用されています。本ブースでは、実際にゲームを手に取って体験いただけます。キッズデザイン賞(経済産業大臣賞)受賞、朝日新聞「天声人語」など多数のメディアに掲載されています。
|
||||
|
||||
 
|
||||
|
||||
株式会社Ashirase
|
||||
|
||||
あしらせ2・Indoorflow
|
||||
|
||||
[https://www.ashirase.com/](https://www.ashirase.com/)
|
||||
|
||||
世界初、靴に装着して振動でナビゲーションする視覚障害者向けデバイス「あしらせ2」と、GPSが届かない屋内・地下空間でもスマホで正確に位置を特定しナビゲーションできるサービス「IndoorFlow」を展示しています。「一人で、どこへでも」を叶える2つのプロダクトを、ぜひ体験・ご覧ください!あしらせ2の振動体験コーナーと、屋内ナビのデモ映像もご用意しています。
|
||||
|
||||
  
|
||||
|
||||
富士通株式会社
|
||||
|
||||
Ontenna・エキマトペ
|
||||
|
||||
[https://ontenna.jp/](https://ontenna.jp/) [https://ekimatopeia.jp/](https://ekimatopeia.jp/)
|
||||
|
||||
Ontenna(オンテナ)は、振動と光で音の特徴をからだで感じるデバイス。ろう・難聴者と聴者が、スポーツや音楽イベントでの臨場感や一体感を共有できます。昨年のデフリンピックでも使用されました。 エキマトペは、駅にあふれる音をAIで識別し、文字や手話、オノマトペで可視化する装置。川崎市立聾学校の生徒たちと一緒にアイデアを考えました。
|
||||
|
||||
 
|
||||
|
||||
コクヨ株式会社
|
||||
|
||||
Coming Soon...
|
||||
|
||||
## 素材ひろば
|
||||
|
||||
   
|
||||
|
||||
[素材ひろば](https://drive.google.com/drive/folders/1CYFmlxwlle9Vac33CuMLqa72Jvv4IxDd)
|
||||
|
||||
## お問い合わせ
|
||||
|
||||
事務局へのお問い合わせはこちら
|
||||
|
||||
[お問い合わせ](https://forms.gle/CiTVjnVbNQ2gD1vK6)
|
||||
|
||||
[行動規範](https://a11y-chiba.com/2026/coc/) の違反などを受けた、またはそのような状況を目撃した場合は、 [お問合わせフォーム](https://forms.gle/CiTVjnVbNQ2gD1vK6) までご連絡ください。
|
||||
|
||||
 
|
||||
@@ -0,0 +1,51 @@
|
||||
---
|
||||
source_url: https://www.itmedia.co.jp/news/articles/2606/30/news133.html
|
||||
ingested: 2026-06-30
|
||||
sha256: c9621fed9d6b1f833326eaab96a8e3528f2979fd3af3dfaf4ef110a0db2bf643
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: 1477793137064935675
|
||||
channel_name: tw
|
||||
message_id: 1521415419896922153
|
||||
author_id: 1477793167486226708
|
||||
posted_at: 2026-06-30T07:21:42.635000000Z
|
||||
message_excerpt: Aflac personal data breach affecting about 4.38 million customers and about 230k bank-account records.
|
||||
---
|
||||
|
||||
[](https://www.itmedia.co.jp/news/subtop/security/)
|
||||
|
||||
## アフラックに不正アクセス、約438万人分の個人情報漏えい 口座情報23万件も(1/2 ページ)
|
||||
|
||||
» 2026年06月30日 14時34分 公開
|
||||
|
||||
\[, ITmedia\]
|
||||
|
||||
アフラック生命保険は6月30日、顧客専用サイト「アフラック よりそうネット」などのシステムが第三者による不正アクセスを受け、顧客の個人情報を含む一部の情報が漏えいしたと発表した。漏えいの対象は約438万人分にのぼる。現時点において、漏えいした情報の不正利用などは確認していないという。
|
||||
|
||||
[](https://image.itmedia.co.jp/l/im/news/articles/2606/30/l_yh_260630aflac01.jpg) 不正アクセスの発生から漏えい判明までの経緯(出典:プレスリリースより、以下同)
|
||||
|
||||
漏えいした顧客の個人情報は、氏名や生年月日、性別、住所、電話番号、証券番号、保障内容など。これに加え、金融機関名・支店名・預金種別・口座番号・口座名義などの保険料振替口座情報も漏えいした顧客数は約23万人分におよぶ。マイナンバーとクレジットカード情報は含まれないとしている。顧客分とは別に、代理店約4万店についても代表者氏名や住所、電話番号などが漏えいした。
|
||||
|
||||
[](https://image.itmedia.co.jp/l/im/news/articles/2606/30/l_yh_260630aflac02.jpg) 漏えいした個人情報の項目と件数の内訳(一部画像加工)
|
||||
|
||||
情報の漏えいが判明したのは6月25日で、同日に当該の不正アクセスを遮断するとともに、被害拡大を防ぐため関連するシステムを停止した。その後の調査で、不正アクセスが最初に発生したのは6月15日で、以降25日までに複数回にわたって不正にアクセスされていたことが分かったという。原因の詳細は調査中としている。
|
||||
|
||||
保険金・給付金の請求をはじめとする各種問い合わせや手続きは、コールセンターなどで通常どおり受け付ける。アフラック生命保険は今回の件について、既に金融庁・警察などの関係機関へ報告したと説明。今後も調査を継続し、システムの早期復旧に取り組むとしている。
|
||||
|
||||
対象となる顧客には、順次おわびと知らせの文書を送付するという。
|
||||
|
||||
[【画像2枚】不正アクセスの発生と情報漏えいを公表する文書全文](https://www.itmedia.co.jp/news/articles/2606/30/news133_2.html)
|
||||
|
||||
**1** | [2](https://www.itmedia.co.jp/news/articles/2606/30/news133_2.html) [次のページへ](https://www.itmedia.co.jp/news/articles/2606/30/news133_2.html)
|
||||
|
||||
Special
|
||||
|
||||
PR
|
||||
|
||||
## アイティメディアからのお知らせ
|
||||
|
||||
- [キャリア採用の応募を受け付けています](https://hrmos.co/pages/itmedia/jobs?jobType=FULL)
|
||||
|
||||
Special PR
|
||||
|
||||
あなたにおすすめの記事 PR
|
||||
@@ -0,0 +1,135 @@
|
||||
---
|
||||
source_url: "https://zenn.dev/chot/articles/dca4889fa27d27"
|
||||
ingested: 2026-06-30
|
||||
sha256: 61ba17cb1e95b943c26f777987b2778df6cd0c9c050c4a03ddcbbd6ba6b52c53
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1028287639918497822"
|
||||
channel_name: "chat"
|
||||
message_id: "1521485941267763221"
|
||||
author_id: "890908900520505354"
|
||||
posted_at: "2026-06-30T12:01:56.240000000Z"
|
||||
message_excerpt: "https://zenn.dev/chot/articles/dca4889fa27d27"
|
||||
---
|
||||
|
||||
# はじめて AI エージェント向けの CLI ツールを作ってみて気づいたこと
|
||||
|
||||
最近、Claude Code から使うことを前提にした小さな CLI ツールを Go でつくりました。
|
||||
きっかけは「過去に似た実装がないか、複数のリポジトリを横断して探したい」という場面がちょこちょこ出てきたことです。
|
||||
GitHub を毎回探しに行くのが地味に大変だったので、自然言語で投げたら良い感じに探してくれるとうれし〜と思ったのがはじまりでした。
|
||||
で、実際につくってみると人間向けの CLI とは違う設計判断があり面白いな〜と思ったので、気づいたことをまとめてみます。
|
||||
##
|
||||
1. Skill の内容は CLI への参照だけに留めて、使い方は CLI に同梱する
|
||||
Claude Code 用に Skill を書くとき、ツールの説明をこんな感じで Skill ファイルに書きたくなります。
|
||||
`---
|
||||
name: super-cli-tool
|
||||
description: ...
|
||||
---
|
||||
super-cli-tool は以下のように使います
|
||||
- `super-cli-tool search <query>` で検索
|
||||
- `--limit N` で件数指定
|
||||
- `super-cli-tool read <id>` で詳細取得
|
||||
- 結果の JSON は results[] に入っていて...
|
||||
`
|
||||
これだと、CLI 側の更新によって情報が古くなる場合があります。
|
||||
Skill はリポジトリに含めてコミットされる可能性もあるので、今度はどうメンテするかを考える必要が出てきますね。
|
||||
結論として、「使い方は CLI に同梱して、Skill はこの CLI ツールの存在と使い方の見方のみにする」のが賢いかも!と個人的には思いました。
|
||||
ヘルプの見方を載せるだけでも十分ですが、`agent-browser` のように、CLI 側に「AI エージェント向けの詳細ガイドを出すサブコマンド」を生やすとより良さそうです。
|
||||
`$ super-cli-tool skill
|
||||
# super-cli-tool AI エージェント向け使い方ガイド
|
||||
あなたは Claude Code セッション内で動くアシスタント。
|
||||
複数のデータソースから「過去に似た実装事例があるか」を super-cli-tool で調べる。
|
||||
## 基本フロー
|
||||
1. クエリを英語化(必要に応じて複数試行)
|
||||
- "サムネ helper" → "thumbnail" "thumbnail helper" "thumbnail renderer"
|
||||
2. super-cli-tool search "<query>" --limit 5
|
||||
- 結果 JSON の results[].id / title / snippet を読む
|
||||
- 詳細が必要な候補だけ super-cli-tool read "<id>" で取得する
|
||||
...
|
||||
`
|
||||
Skill ファイル本体に書くのは「このツールがあるよ、詳細は `super-cli-tool skill` を読んでね」という内容だけです。
|
||||
`---
|
||||
name: super-cli-tool
|
||||
description: 複数のデータソースを横断検索する CLI。過去の実装事例や関連情報を探したいときに使う。
|
||||
---
|
||||
super-cli-tool CLI が使えます。 詳しい使い方は `super-cli-tool skill` を実行して読んでください。
|
||||
`
|
||||
この形にすると、CLI のバージョンアップで使い方が自動的に同期されるので、Skill 側を直す必要がほぼなくなります。
|
||||
CLI 側に寄るのが良い感じですね。
|
||||
description は Skill の選択に使われるので、丁寧目に書くとなおよしです。
|
||||
##
|
||||
2. JSON 出力をデフォルトにする + 結果に「AI エージェントが判断に使う情報」を埋め込む
|
||||
たとえば GitHub CLI だと、テキスト出力がデフォルトで `--json` はオプション扱いです。
|
||||
`# デフォルトはテキスト
|
||||
gh repo list
|
||||
# JSON が欲しいときだけ明示する
|
||||
gh repo list --json name,url
|
||||
`
|
||||
人間が使うならこれが自然ですが、AI エージェントに使ってもらうことを前提にすると、逆の方が便利でした。
|
||||
加えて、結果には「AI エージェントが次のアクションを決める材料」を一緒に埋めておくのがポイントでした。
|
||||
`{
|
||||
"query": "...",
|
||||
"file_results": [
|
||||
{
|
||||
"id": "example-1",
|
||||
"title": "FooBar の実装例",
|
||||
"path": "src/foo/bar.tsx",
|
||||
"snippet": "export const FooBar = ...",
|
||||
"source_url": "https://github.com/.../src/foo/bar.tsx",
|
||||
"last_updated_at": "2026-05-28"
|
||||
}
|
||||
],
|
||||
"synced_at": "2026-06-26T15:49:13+09:00",
|
||||
"is_stale": false
|
||||
}
|
||||
`
|
||||
-
|
||||
`synced_at`: いつ同期されたか
|
||||
-
|
||||
`is_stale`: 7 日以上経っていたら `true`(Skill 側で、古かったら「sync した方がいいですよ」と促してねって書いてます)
|
||||
-
|
||||
`source_url`: ユーザーに回答するときにそのまま貼れるリンク
|
||||
「これを見たエージェントが次に何をするか」を見据えて、必要な情報を先に渡しておくという感じです。
|
||||
##
|
||||
3. エラーメッセージに「次のコマンド」を書く
|
||||
CLI ツールに限らず AI エージェントに見せるエラーメッセージには、具体的な次のアクションを書くようにしています。
|
||||
人間なら以下のメッセージでも「インデックスを作り直せばよさそう」と察しがつきます。
|
||||
`[super-cli-tool ERROR] index is missing or outdated
|
||||
`
|
||||
なんですが AI エージェントだと、ここから「じゃあどのコマンドを叩けばいいのか」を毎回推測することになります。
|
||||
なので、直し方のコマンドまでそのまま書いてあげると、推測のステップを 1 つ減らせてやさしいかなと思います。
|
||||
`[super-cli-tool ERROR] index is missing or outdated
|
||||
→ run `super-cli-tool sync` to rebuild the index
|
||||
`
|
||||
Claude Opus などのフロンティアモデルではなく、小さいモデルに使わせてみて改善を重ねると、LLM にやさしいツールが作れるのでおすすめです。
|
||||
特に広く公開しないものだとエラーメッセージは適当にしてしまいがちなんですが、たとえ人間が使う場合でも丁寧である分には困らないのでこれからはちゃんと書こうと思いました…。
|
||||
##
|
||||
4. 重い処理と軽い処理を分ける
|
||||
AI エージェント向けの CLI では、1 つのコマンドで全部を返そうとするより、軽い確認と重い取得を分けた方が扱いやすいなと思いました。
|
||||
検索系の CLI ならこんな感じです。
|
||||
-
|
||||
search: ローカルのインデックスを検索して、候補だけ返す
|
||||
-
|
||||
read: 必要になったファイルや詳細情報だけ取得する
|
||||
最初から本文や詳細データを全部返すと、遅くなるうえに出力も大きくなります。
|
||||
AI エージェントにとっても読む情報が増えすぎて、どこを見ればいいのか判断しづらくなりがちです。
|
||||
一方で、「まず search で候補を絞る → 必要なものだけ read する」という形にしておくと、各コマンドの責務がシンプルになります。
|
||||
AI エージェントはこういう小さなステップの繰り返しが得意なので、CLI 側が 1 ショットで完璧な答えを返さなくても意外となんとかなります。
|
||||
むしろ、段階的に探索できる余地を残しておく方が良さそうでした。
|
||||
##
|
||||
5. フラグは増やさず、なるべくデフォルトで完結するように
|
||||
最初は `sync --discover` `--sources a,b` `--owner my-org` と、複数のフラグを用意していました。
|
||||
ただ、AI エージェントに使わせる前提だと、毎回細かいオプションを選ばせるより、よく使う設定をデフォルトに寄せた方が安定しました。
|
||||
`# 必要なデータを同期する
|
||||
super-cli-tool sync
|
||||
# 強制的に同期し直す
|
||||
super-cli-tool sync --full
|
||||
`
|
||||
フラグが多いとヘルプの出力も長くなって、その分トークンも消費します。
|
||||
選択肢が少ない方が AI エージェントも判断に迷わないので、オプションはミニマムに保つのが良さそうです。
|
||||
オプションをモリモリ増やしたくなる気持ちを抑えるのが難しいところです。
|
||||
##
|
||||
さいごに
|
||||
「AI エージェント専用とはいえ、賢いし人間向けと同じでええやろ〜」と思っていたのですが、実際につくってみると意外とうまくいかないことがありました。
|
||||
人間向けに作るときとは違う設計判断がいくつも出てきて、なかなか面白かったです。
|
||||
AI エージェントがつよくなってきた今、こういった CLI ツールをつくる機会もふえていきそうですね 🤖
|
||||
@@ -0,0 +1,40 @@
|
||||
---
|
||||
source_url: https://unit.aist.go.jp/rihsa/daax/d_cns_standardization.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 49ef29faf663a9ff50cd20811a3a44dc47762fb54d0e17cc3f1ac0d4209e3740
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: 1477793137064935675
|
||||
channel_name: tw
|
||||
message_id: 1521415419896922153
|
||||
author_id: 1477793167486226708
|
||||
posted_at: 2026-06-30T07:21:42.635000000Z
|
||||
message_excerpt: AIST avatar standardization domestic committee for avatar UI standards in XR/metaverse services.
|
||||
---
|
||||
|
||||
1. [人間社会拡張研究部門](https://unit.aist.go.jp/rihsa/)
|
||||
2. [拡張体験デザイン協会 コンソーシアム](https://unit.aist.go.jp/rihsa/daax/d_cns_index.html)
|
||||
3. 標準化活動
|
||||
|
||||
## 標準化活動
|
||||
|
||||
## アバター国際標準化の国内検討委員会
|
||||
|
||||
##### *本委員会の目的
|
||||
|
||||
メタバースやXRを利用した製品・コンテンツ・サービス等は、現実の自分の身体に変わる仮想の身体(アバター)を使って体験されます。そのため、どのような設計のアバターを利用したコンテンツやサービスであるかは、ユーザの体験に影響する重要な情報です。本委員会は、国際標準化委員会ISO IEC/JTC1/SC35における、ユーザインターフェースとしてのアバターの規格の開発が、よりユーザ側および開発側に有意義な規格となることを目指して、国内の業界やユーザの声を収集し、規格開発に提言やアドバイスを行うことを目的とした各分野各業界の専門家による委員会です。
|
||||
|
||||
|
||||
##### *委員(五十音順)
|
||||
|
||||
岩城進之介 (VRMコンソーシアム/株式会社バーチャルキャスト)
|
||||
大山潤爾 (産業技術総合研究所/筑波大学/SC35)
|
||||
川本大功 (KDDI株式会社)
|
||||
杉本麻樹 (慶応義塾大学/SC35)
|
||||
武富貴史 (株式会社サイバーエージェント)
|
||||
豊田啓介 (株式会社ノイズ/一般社団法人Metaverse Japan/東京大学)
|
||||
仲田朝彦 (株式会社三越伊勢丹)
|
||||
バーチャル美少女ねむ (有識者)
|
||||
原田佑規 (京都先端科学大学/SC35)
|
||||
平木剛史 (クラスター株式会社)
|
||||
目黒慎吾 (博報堂DYホールディングス/拡張体験デザイン協会)
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,37 @@
|
||||
---
|
||||
source_url: https://techcrunch.com/2026/06/29/arena-the-ai-leaderboard-everyone-uses-is-now-a-100m-business/
|
||||
ingested: 2026-06-30
|
||||
sha256: 57309d52c250bb21db2b24a62a0ae1e4155da94b6bd85212f5c7bad715bdf9c3
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521400285082419262'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T06:21:34.214000000Z
|
||||
message_excerpt: 'AIランキングサイト「Arena」が商用サービス開始から8カ月で年換算収益160億円を突破。AIの評価レイヤー自体が産業になる流れ。'
|
||||
---
|
||||
|
||||
Just eight months after launching its commercial service, AI leaderboard provider [Arena](https://arena.ai/leaderboard), which originated as a research project at UC Berkeley in 2023, has reached $100 million in annualized run-rate revenue.
|
||||
|
||||
Arena is best known for its popular crowdsourced AI model performance leaderboard, generated from over 10 million user evaluations. Its consumer website lets a user type a prompt it sends to two models; afterward, the user chooses which model did a better job.
|
||||
|
||||
While Arena’s popular AI model leaderboard is free for public use, the company began generating revenue from its platform in September when it introduced [AI Evaluations](https://news.lmarena.ai/ai-evaluations/), a service that provides model labs and enterprises with deep-dive performance analytics gathered from its community.
|
||||
|
||||
Arena’s rapid revenue growth shows that its commercial offerings are as popular with customers as they are with its community of evaluators, who are frequently drawn to the platform for early access to the latest, often unreleased, AI models.
|
||||
|
||||
“A lot of people don’t even understand that our business is making any money at all; people still see us as an open source project,” Anastasios Angelopoulos, Arena’s co-founder and CEO, told TechCrunch.
|
||||
|
||||
While Arena calls its revenue milestone ARR, a term that traditionally stood for [annualized recurring revenue](https://techcrunch.com/2026/05/22/how-vcs-and-founders-use-inflated-arr-to-kingmake-ai-startups/), Angelopoulos clarified that the company charges customers for “consumption,” which means that its revenue is not recurring.
|
||||
|
||||
While Arena doesn’t have direct competitors — Yupp, another crowdsourced AI model-picking startup, [shut down](https://techcrunch.com/2026/03/31/yupp-ai-shuts-down-33m-a16z-crypto-chris-dixon/) in March— Angelopoulos said the company competes “for the same dollar” with human labeling startups like Mercor, Surge, and Scale AI, all of which assist model makers in refining their AI during post-training.
|
||||
|
||||
As AI providers strive to maximize model performance, their appetite for post-training optimization services continues to surge. When Arena announced in January that it raised a $150 million Series A at a post-money valuation of $1.7 billion, its annualized revenue was [$30 million](https://techcrunch.com/2026/01/06/lmarena-lands-1-7b-valuation-four-months-after-launching-its-product/).
|
||||
|
||||
Elsewhere, Handshake’s gross annualized revenue from AI training has nearly doubled since January, climbing from $550 million to nearly $1 billion, The Information [reported](https://www.theinformation.com/articles/handshake-mercor-revenue-surges-demand-human-contractors-train-ai?rc=em6blq) in April. Mercor’s annualized revenue also topped $1 billion earlier this year, up from $500 million last September, [according](https://www.theinformation.com/briefings/exclusive-mercor-hit-1-billion-annualized-revenue-breach) to The Information.
|
||||
|
||||
Arena ranks models on a variety of tasks such as text, coding, vision, and image generation, as well as complex, long-running workflows through its recently introduced Agent Mode.
|
||||
|
||||
Along with Angelopoulos (pictured left), Arena was co-founded by fellow UC Berkeley postdoctoral student Wei-Lin Chiang (pictured center), who serves as the startup’s CTO. The startup was also co-founded by Ion Stoica (pictured right), the renowned UC Berkeley professor and Databricks co-founder who advised the project before it incorporated as a company in April 2025.
|
||||
|
||||
Arena has raised a total of $250 million from investors, including Felicis, Andreessen Horowitz, The House Fund, LDVP, Kleiner Perkins, Lightspeed Venture Partners, Laude Ventures, and UC Investments.
|
||||
@@ -0,0 +1,234 @@
|
||||
---
|
||||
source_url: https://dev.classmethod.jp/articles/aws-finops-agent-preview/
|
||||
ingested: 2026-06-30
|
||||
sha256: c9742a257d2b63c96feb1174a626b5e10c98b3ea7ebeb9645b130f21b2a1a172
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521355038830624930'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T03:21:46.667000000Z
|
||||
message_excerpt: 'AWS FinOps Agent public preview setup and automation test.'
|
||||
score: 2
|
||||
---
|
||||
|
||||
いわさです。
|
||||
|
||||
AWS には様々なコスト分析サービスが用意されていますよね。
|
||||
AI を使った分析だと最近では Amazon Q を使った分析機能が提供されていました。
|
||||
|
||||
今朝アナウンスがありましたが新たに AWS FinOps Agent がプレビューとしてリリースされたみたいです。
|
||||
|
||||
DevOps Agent や Security Agent に続く「フロンティアエージェント」シリーズって感じですかね。作ってみようかなと思ってたのですが先に出てしまったわ。
|
||||
|
||||
自然言語でコストに関する質問をしたり、コスト異常の自動調査、定期レポートの生成(HTML / PDF / PPT 形式)、最適化レコメンデーションの集約と Jira チケット化などを行ってくれるエージェントとのこと。
|
||||
組織固有のコンテキストファイルをアップロードするとセッション間で記憶してくれる機能もあるようです。
|
||||
|
||||
> AWS FinOps Agent is a frontier agent that makes it easy for customers to continuously monitor costs, investigate anomalies, and surface optimization opportunities across their cloud environments.
|
||||
|
||||
Amazon Q Developer のコスト分析機能とは別のサービスとして登場しました。
|
||||
今回こちらを確認してみたので紹介します。
|
||||
|
||||
## セットアップしてみる
|
||||
|
||||
まずはエージェントの作成からです。
|
||||
AWS マネジメントコンソールから AWS FinOps Agent のページにアクセスすると、5 ステップのウィザードでエージェントを作成できます。
|
||||
|
||||
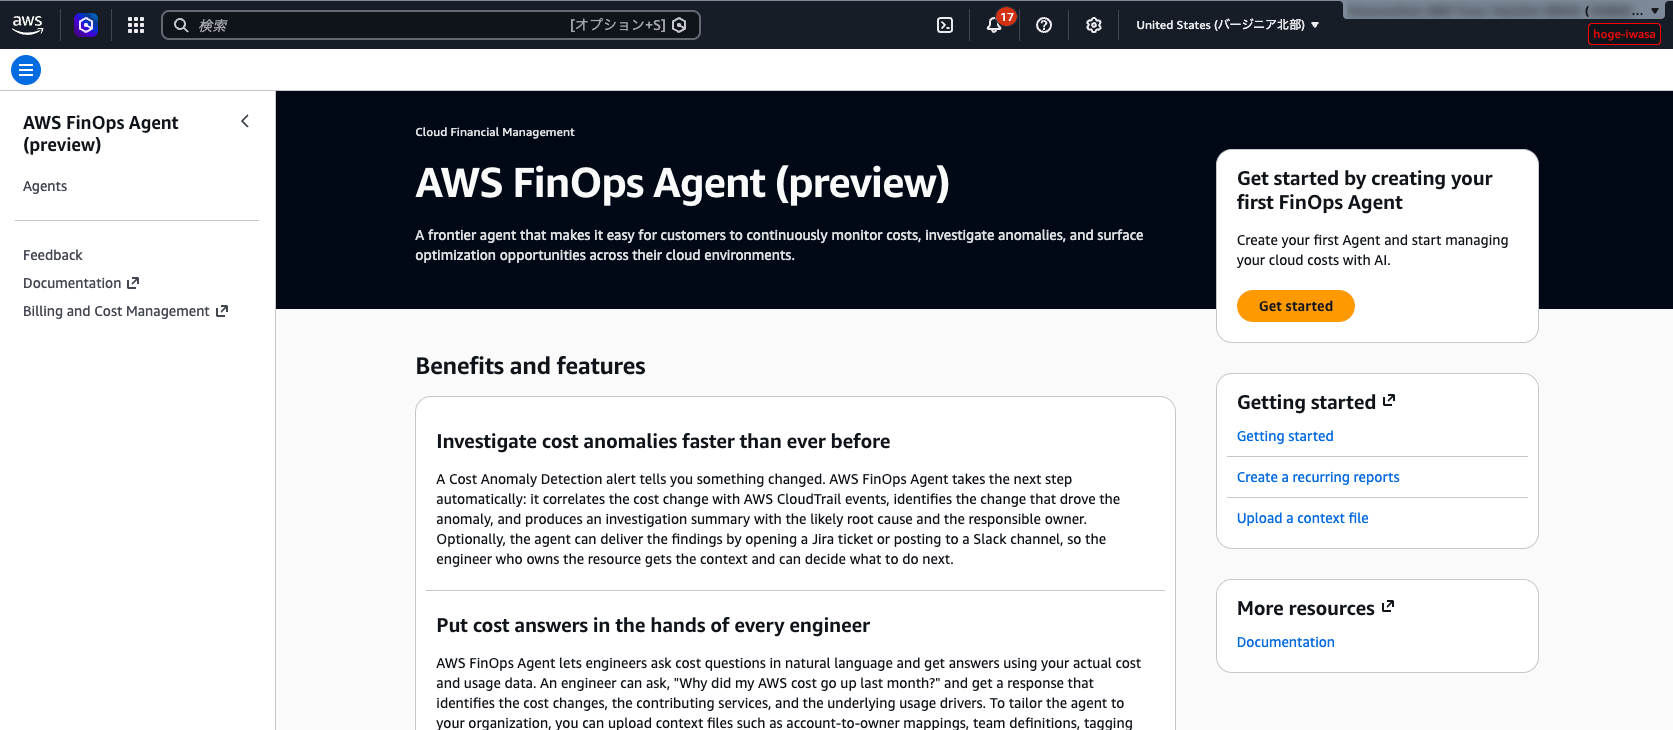
|
||||
|
||||
なお、本日時点では本機能はまだ東京リージョンでは利用できないみたいなので、今回はバージニア北部リージョンで検証してみます。
|
||||
|
||||
まずエージェントの名前と説明(オプション)を設定します。
|
||||
|
||||
|
||||
|
||||
次に、エージェントが AWS リソースにアクセスするための IAM ロールを設定します。
|
||||
自動作成が推奨されており、 `FinOpsAgentRole-xxxxx` のような名前でサービスロールが作成されます。
|
||||
|
||||
|
||||
|
||||
続いて、Web アプリ(操作画面)にアクセスするための Operator ロールを設定します。
|
||||
こちらも自動作成が推奨で、 `FinOpsAgentOperatorRole-xxxxx` という名前で作成されます。
|
||||
|
||||
|
||||
|
||||
DevOps Agent と同様に、Agent ロール(エージェントが AWS API を叩く用)と Operator ロール(Web アプリがエージェントを操作する用)の 2 ロール構成ですね。
|
||||
|
||||
次にサードパーティ連携です。
|
||||
Jira と Slack の連携を設定できます。
|
||||
今回は Slack 連携を試してみました。
|
||||
|
||||
|
||||
|
||||
Slack 連携を選ぶと OAuth 認証のフローに入ります。
|
||||
なお、AWS コンソールがマルチセッションモードだと設定できないようで、「Switch out of multi-session」という警告が表示されました。
|
||||
シングルセッションに切り替えてから再度設定すると認証画面に遷移します。
|
||||
|
||||
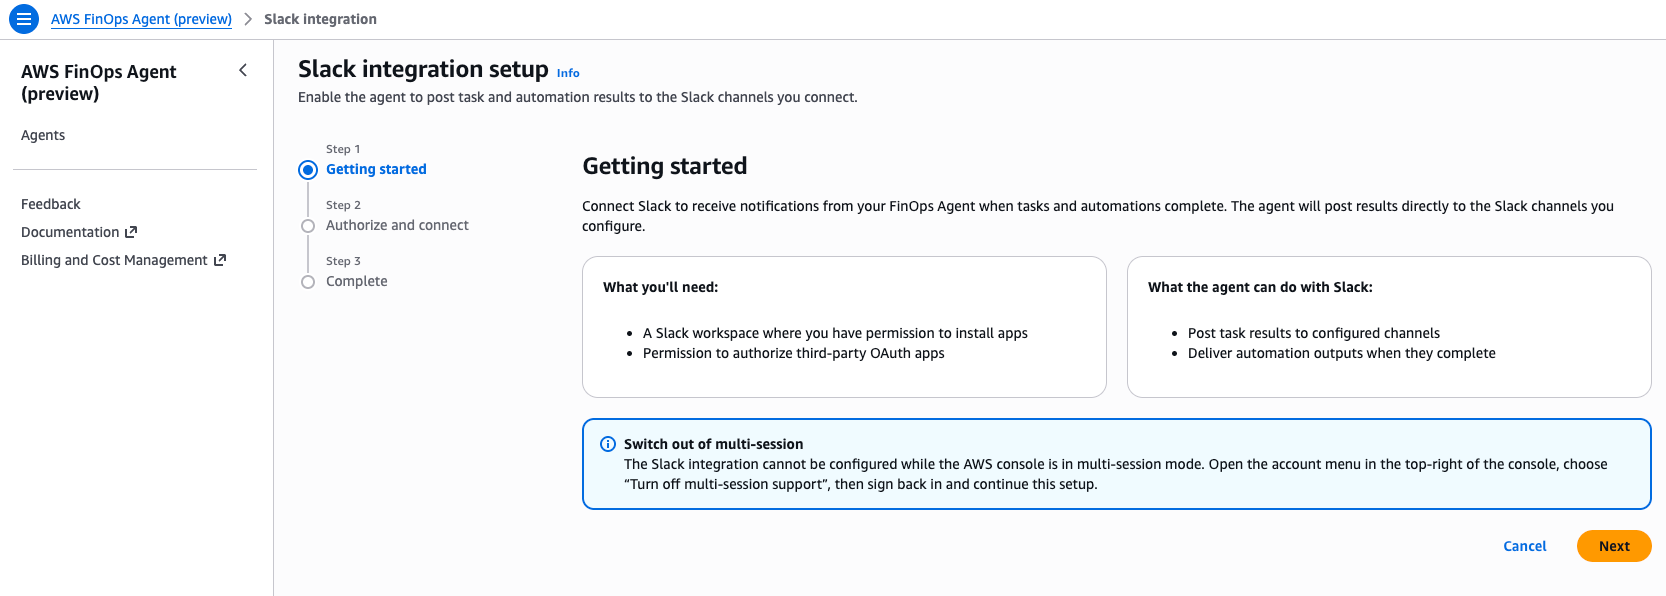
|
||||
|
||||
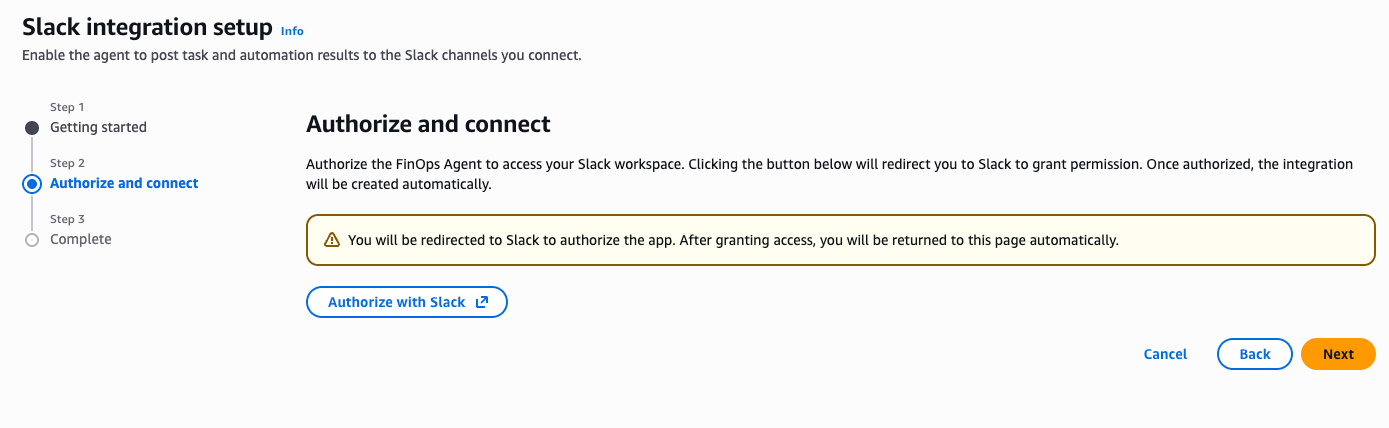
|
||||
|
||||
Slack 側の認証画面では「AWS FinOps Agent - US East (N. Virginia)」というアプリ名でアクセスを許可します。
|
||||
Slack Marketplace の承認は受けていないアプリとの表示がありますが、プレビューなのでまぁそうかという感じです。
|
||||
|
||||
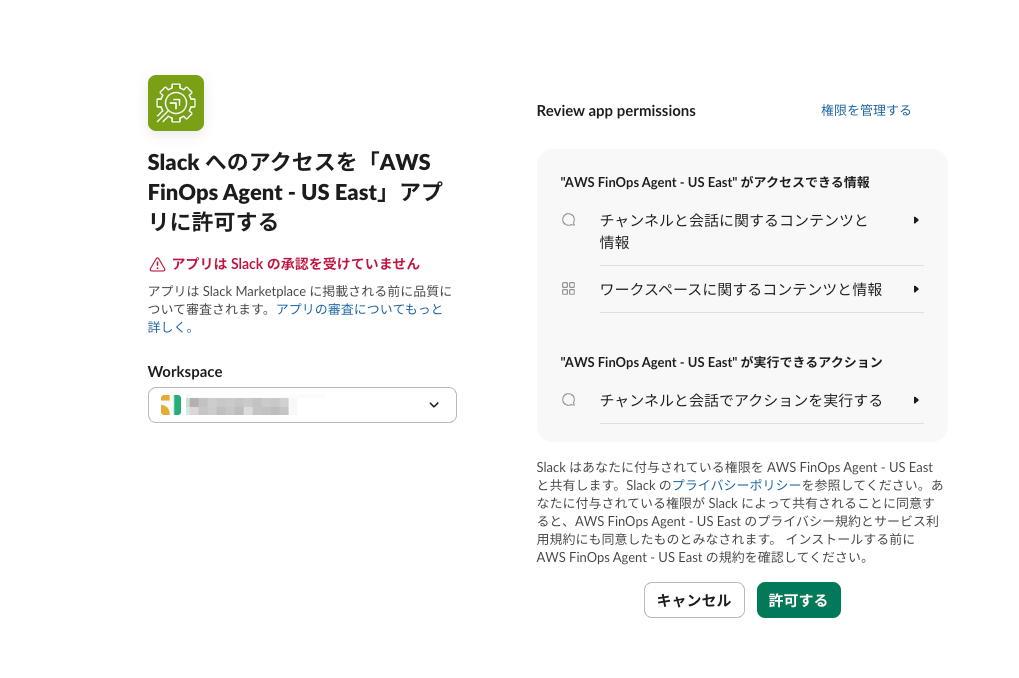
|
||||
|
||||
認証が完了したら、投稿先チャンネルの ID を入力する必要があります。
|
||||
|
||||
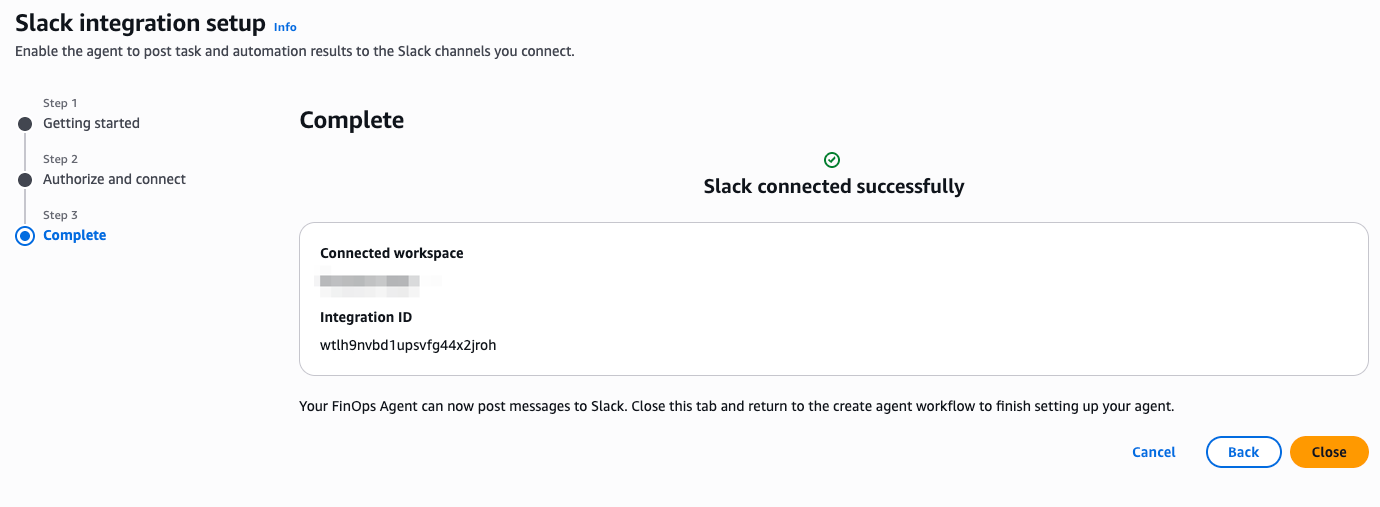
|
||||
|
||||
チャンネル ID は Slack で対象チャンネルを右クリック → チャンネル詳細 → 一番下にある ID をコピーして入力します。
|
||||
|
||||
|
||||
|
||||
設定内容を確認して「Create agent」を押します。
|
||||
画面表記によると IAM ロールの伝播待ちに90 秒ほどかかるみたいです。
|
||||
|
||||
|
||||
|
||||
作成完了後、エージェント一覧に表示されました。
|
||||
ただし Slack 連携で「Failed to connect Slack Integration. Bot is not a member of this channel. Please add AWS FinOps Agent to the channel first.」というエラーが出ました。
|
||||
|
||||
|
||||
|
||||
これは Slack チャンネルに FinOps Agent のボットをメンバーとして追加していなかったためです。
|
||||
Slack チャンネルの「インテグレーション」タブで「AWS FinOps Agent - US East (N. Virginia)」アプリを追加しておきます。
|
||||
|
||||
|
||||
|
||||
そしてエージェントの Integrationタブからコネクションの追加を再度行うことができまして、これで解決しました。
|
||||
|
||||
|
||||
|
||||
エージェントの設定画面から Connections に Slack の接続が確認できます。
|
||||
|
||||
|
||||
|
||||
## エージェントの Web コンソールにアクセスして使ってみる
|
||||
|
||||
エージェント作成後、コンソールの「Open agent」ボタンから専用の Web アプリにアクセスできます。
|
||||
|
||||
|
||||
|
||||
ダークテーマの ChatGPT 的な UI ですね。
|
||||
|
||||
|
||||
|
||||
### チャットでコスト質問
|
||||
|
||||
まず「あなたは何ができるのですか?」と聞いてみたところ、「I only support responses in English.」と前置きしたうえで、できることの一覧を表示してくれました。
|
||||
|
||||
|
||||
|
||||
次に「このアカウントのコスト最適化余地を調べてください」と日本語で聞いてみました。
|
||||
|
||||
|
||||
|
||||
日本語は理解してくれて、内部で `cost-optimization-recommendations` スキルを呼び出し、Cost Optimization Hub と Compute Optimizer に問い合わせてくれました。
|
||||
|
||||
結果として「東京リージョンでは推奨事項なし」で、Cost Optimization Hub や Compute Optimizer が未登録の可能性が高いとのこと。
|
||||
未登録の場合は有効化リンク付きで案内してくれます。
|
||||
|
||||
Cost Optimization Hub や Compute Optimizer は有効化していた気がするのですがどうもちゃんと動かない。でももっと絞った別の聞き方をしたところちゃんと回答してくれました。
|
||||
弊社では週次で検証用 AWS アカウントのコストを自動チェックし、ある程度の利用料金が発生している場合はアカウントや料金情報とともに Slack で通知される仕組みがあります。
|
||||
この通知タイミングで各自が棚おろしすることが多いのですが、先週ランキングに載ってしまいました。へへ。
|
||||
|
||||
|
||||
|
||||
FinOps Agent にそれについて聞いてみると的確に原因を分析して対策を提案してくれました。良いな。
|
||||
|
||||
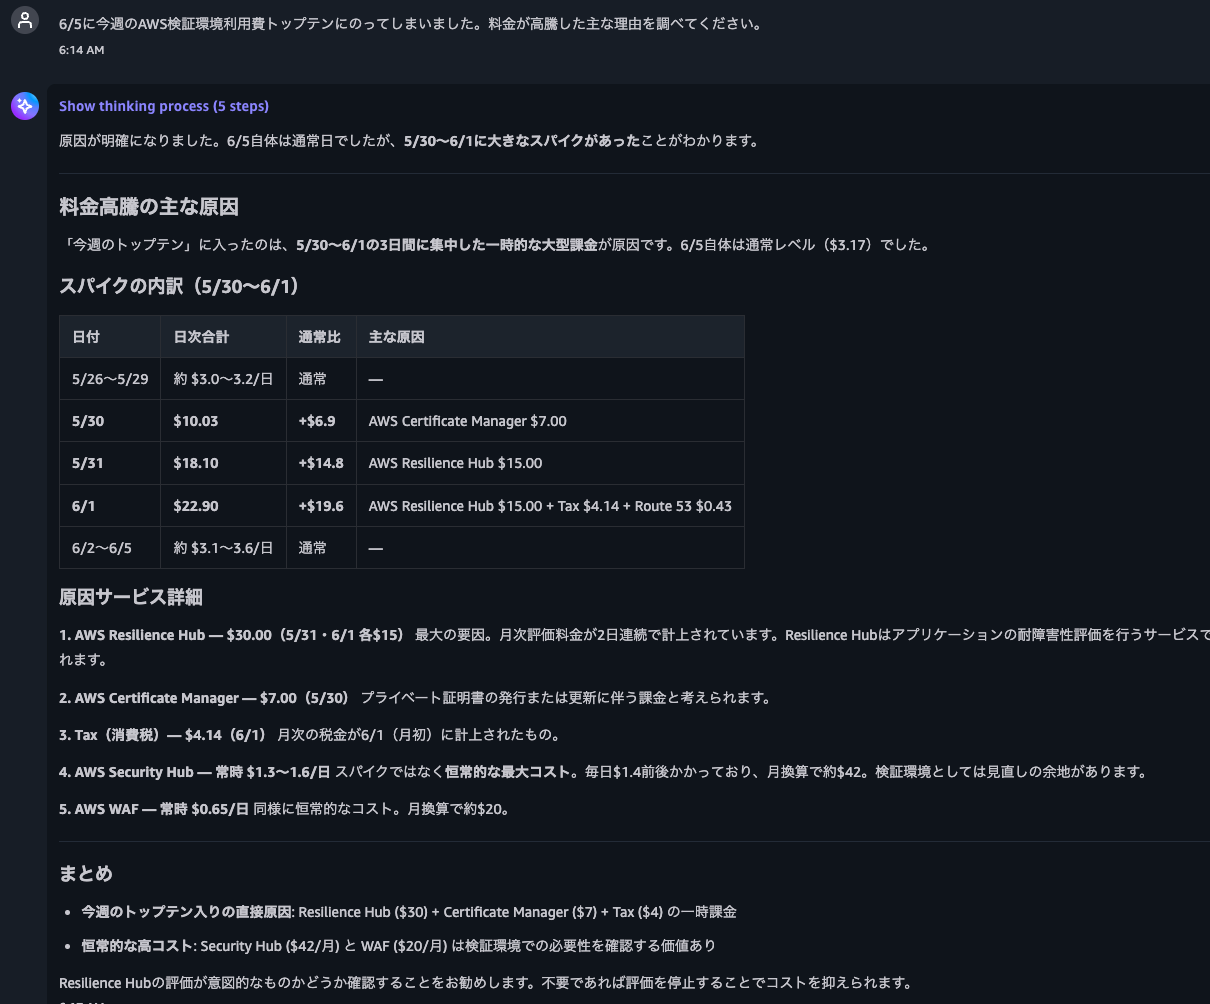
|
||||
|
||||
そう、Resilience Hub v2 でおもわぬ料金が発生しちゃったんですよね。それはまたブログで供養したいと思います。
|
||||
|
||||
### タスクを使ってみる
|
||||
|
||||
このあたりからがかなり良いなと思ったのですが、FinOps Agent ではタスクや自動化の機能がありましてコスト分析や通知、レポート作成などをタスクとして定期実行させたりイベント駆動で実行させたりすることができます。
|
||||
|
||||
左メニューの「Tasks」からタスクを作成できます。
|
||||
チャットとは別に、明示的にタスクとしてエージェントに仕事を依頼する機能です。
|
||||
|
||||
|
||||
|
||||
Instructions に自然言語で指示を書き、「Run once」「Run on a schedule」「Run when an event occurs」から実行タイミングを選びます。
|
||||
|
||||
|
||||
|
||||
なお、ここで Run Once 以外を選択すると、後述の Automation という扱いに切り替わっていました。
|
||||
|
||||
今回は「KMS の料金が発生していないかチェックしてください」というタスクを作成してみました。
|
||||
|
||||
|
||||
|
||||
1 分ほどで完了し、かなり結果が返ってきました。こちらも英語ですね。
|
||||
|
||||
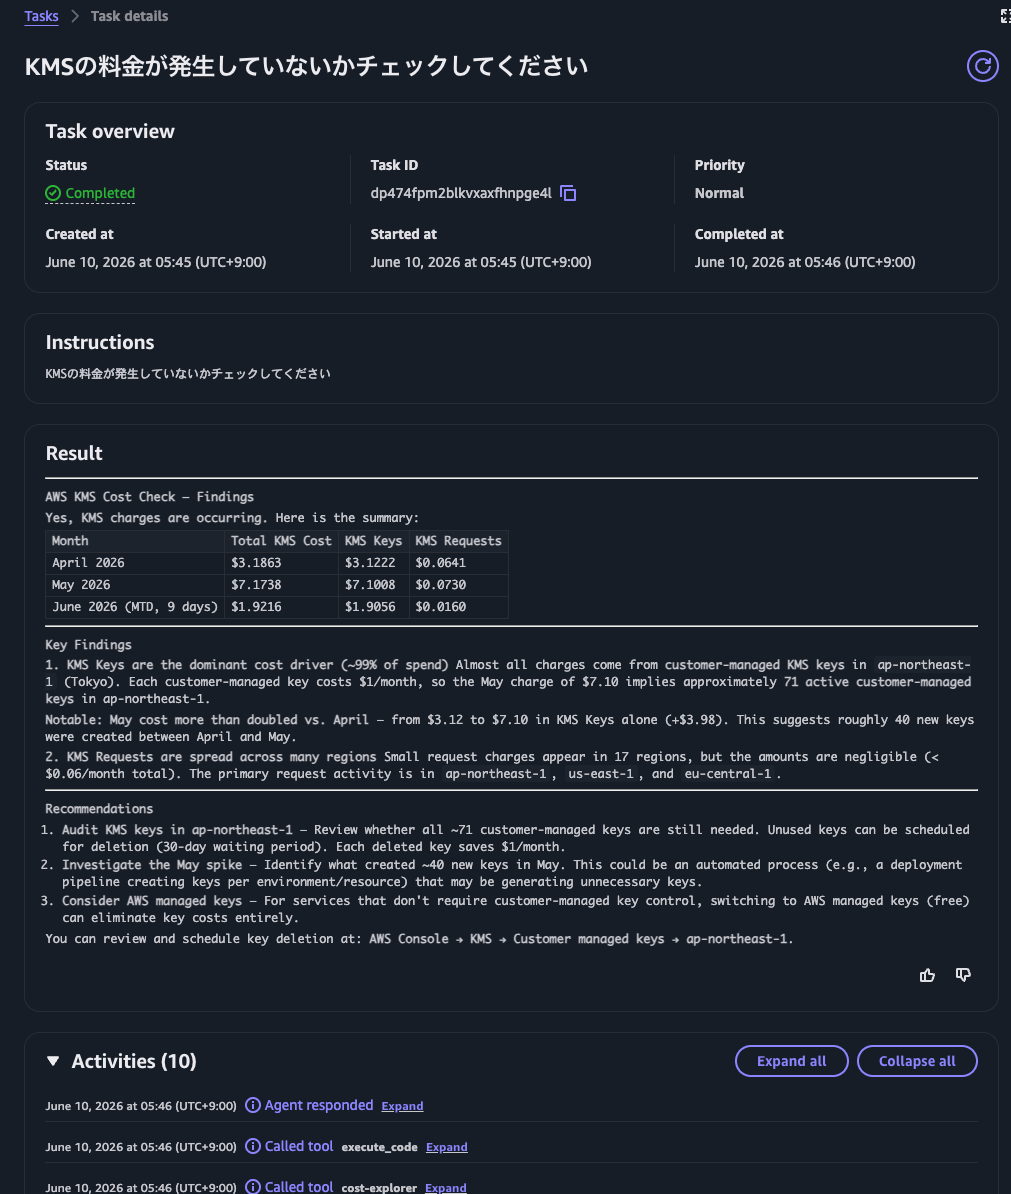
|
||||
|
||||
結果を見ると:
|
||||
|
||||
- ap-northeast-1 で約 71 個の CMK(カスタマーマネージドキー)が稼働中で月 $7 程度
|
||||
- 4 月→5 月で KMS Keys のコストが $3.12→$7.10 に倍増(約 40 個の新しいキーが作成された可能性)
|
||||
- KMS Requests は 17 リージョンに分散しているが金額は無視できるレベル
|
||||
|
||||
推奨事項として、不要なキーの棚卸し、5 月のスパイクの原因調査(デプロイパイプラインが自動生成していないか)、AWS マネージドキーへの切り替え検討を提案してくれています。
|
||||
Activities の一覧を見ると、 `get_current_date_time` 、 `cost-explorer` (複数回)、 `execute_code` などのツールを内部で呼び出していることがわかります。
|
||||
|
||||
### Automations
|
||||
|
||||
左メニューの「Automations」から、定期実行やイベント駆動のワークフローを設定できます。
|
||||
|
||||
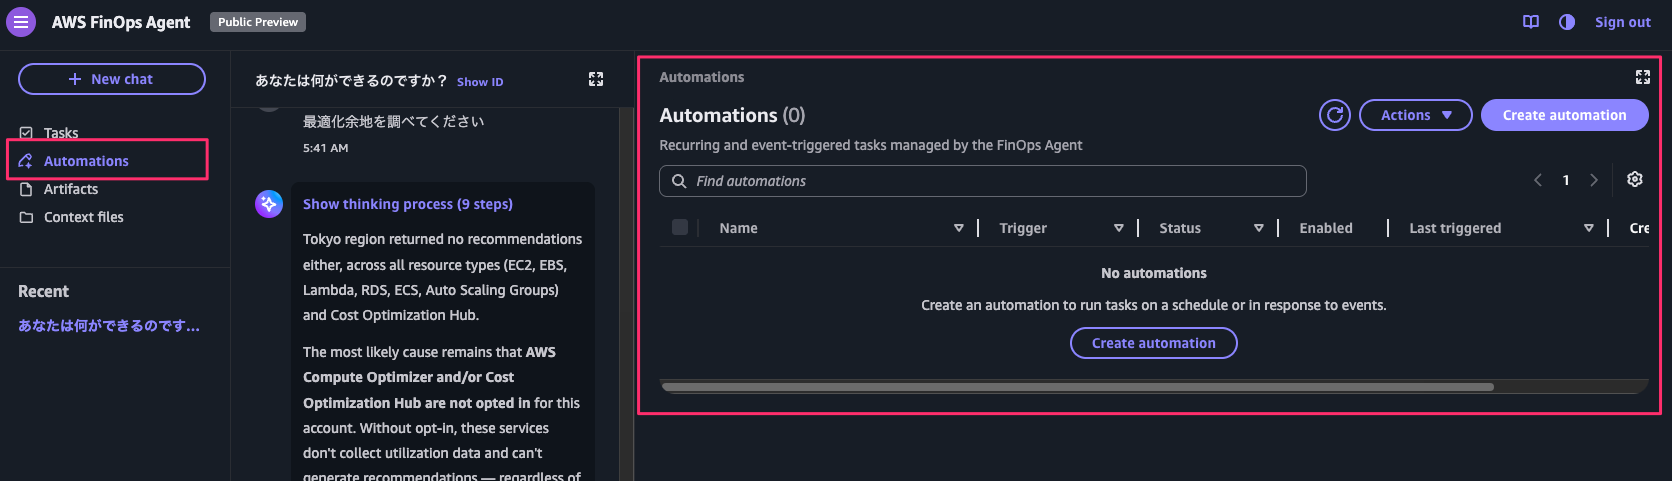
|
||||
|
||||
Automation の作成画面では、Instructions に指示を書いて、スケジュール(Daily / Weekly / Monthly)やイベントトリガー(コスト異常検出時)を設定します。
|
||||
配信曜日・時間も細かく指定でき、タイムゾーンも選べます。
|
||||
|
||||
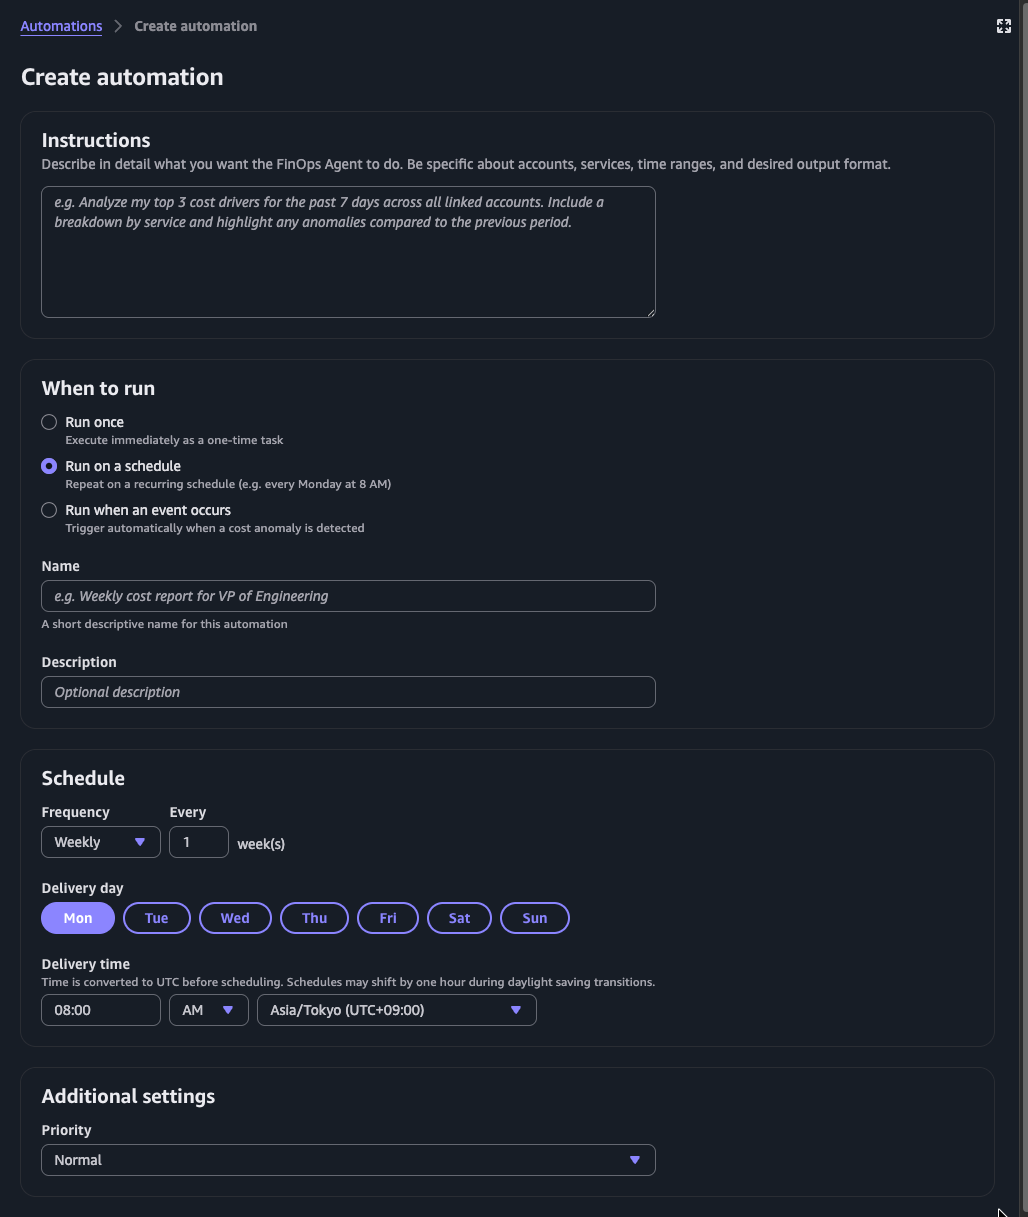
|
||||
|
||||
サンプルプロンプトとして表示されていた例を見ると、Slack チャンネルへの投稿は Instructions の中にチャンネル名を含める形式のようです。
|
||||
|
||||
> Automate Cost Anomaly Detection events for anomalies over $100 and post to Slack #cost-alerts.
|
||||
|
||||
### アーティファクトの生成
|
||||
|
||||
チャットの中で「先ほどチェックした内容です」と伝えたうえで「レポートとしてまとめてください」と頼んだところ、HTML レポートを生成してくれました。
|
||||
|
||||
|
||||
|
||||
2.2 MB の HTML ファイルが Artifacts に保存され、ダウンロードできます。
|
||||
レポートには調査サマリー、調査スコープ、原因の考察、次のステップが含まれていました。
|
||||
|
||||
ちなみに、アーティファクトへの出力指示のあたりから日本語で回答してくれるようになりました。
|
||||
最初は「I only respond in English」と言っていたのに、やり取りを重ねると日本語対応してくれるのは面白いですね。
|
||||
プレビューなので言語サポートの境界がまだ曖昧なのかもしれません。
|
||||
|
||||
### Slack への通知
|
||||
|
||||
「先ほどの結果を Slack に通知してください」と頼むと、「どの Slack チャンネルに送信しますか?」と確認が入りました。
|
||||
チャンネル名を答えると、送信前にプレビューを見せて「以下の内容を Slack チャンネル hoge0610finopsagent に送信してよろしいでしょうか?」と確認してくれます。
|
||||
投稿前に確認が入るので、意図しない投稿を防げる仕組みになっています。
|
||||
|
||||
|
||||
|
||||
Slack 側に投稿された内容もきれいに構造化されていました。
|
||||
|
||||
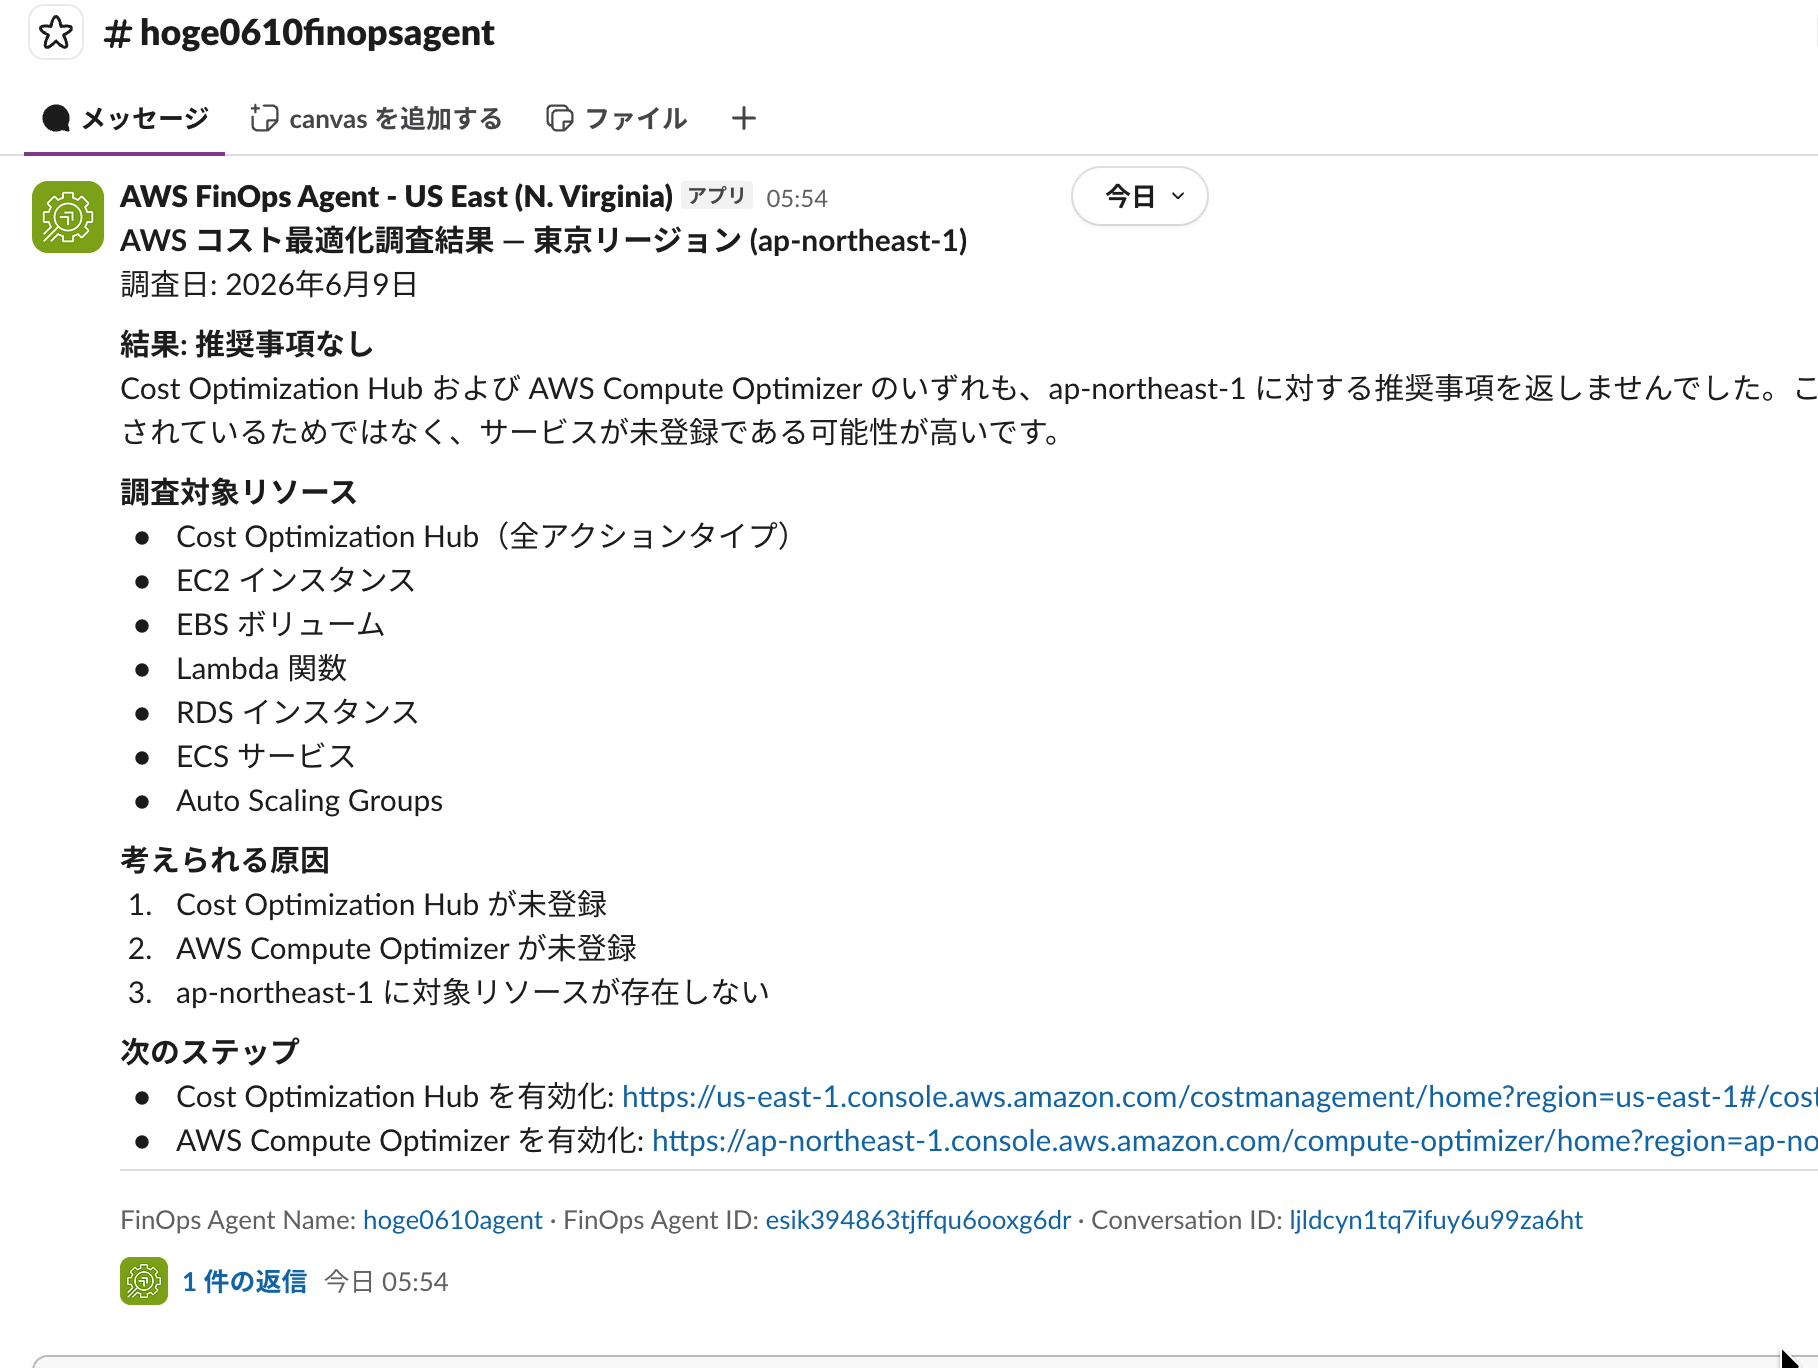
|
||||
|
||||
フッターに Agent Name、Agent ID、Conversation ID がリンク付きで入るので、どのエージェントのどの会話から投稿されたか追跡できるようになっています。
|
||||
|
||||
## このサービスの利用料金
|
||||
|
||||
公式ドキュメントによると、プレビュー期間中はエージェント自体の利用料金は無料で、裏で呼ばれる AWS API の標準料金のみ発生するようです。
|
||||
|
||||
> AWS FinOps Agent is offered at no charge during preview, but the agent calls AWS APIs on your behalf and you pay the standard per-request rate for those APIs.
|
||||
|
||||
## さいごに
|
||||
|
||||
本日は AWS FinOps Agent がプレビューリリースされたのでセットアップして使ってみました。
|
||||
|
||||
DevOps Agent や Security Agent と同様にマネジメントコンソールでエージェントをセットアップし Web コンソールにアクセスして操作する流れです。セットアップはそこまで大変ではなかったですね。
|
||||
|
||||
チャットだけだと Amazon Q のコスト分析と対して変わらないかな?と思ったのですが、コスト異常検出時に分析タスク実行して Slack にレポート通知させたりとか、自動化周りがかなり強そうだなと思いました。利用料金にもよるのですがかなり使えそう。
|
||||
|
||||
他のフロンティアエージェントと同様におそらく GA 時は東京リージョンでもサポートされそうな気がしますね。
|
||||
コスト管理されている方はぜひためしてみてください。
|
||||
@@ -0,0 +1,29 @@
|
||||
---
|
||||
source_url: "https://www.imes.boj.or.jp/research/abstracts/japanese/kk45-1-2.html"
|
||||
ingested: 2026-06-30
|
||||
sha256: c825c1c003ecfc3fd79e45401ce8999f1969b8af66a927a81683f4d937cc0af3
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521490855561793599"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T12:21:27.899000000Z"
|
||||
message_excerpt: "日本銀行のAIエージェント契約自動化に関する論考 は、単なるAI活用ではなく、日本法にどう接続するかを考える入口として実務価値があります。"
|
||||
---
|
||||
|
||||
金融研究 第45巻第1号 要旨 金融機関におけるAI利用に伴う私法上のリスクと管理
|
||||
金融研究
|
||||
第45巻第1号
|
||||
(2026年1月発行)
|
||||
本文[578 KB PDF]
|
||||
金融機関におけるAI利用に伴う私法上のリスクと管理
|
||||
金融機関におけるAIの利用を巡る法律問題研究会
|
||||
本稿は、日本銀行金融研究所が設置した「金融機関におけるAIの利用を巡る法律問題研究会」(メンバー〈50音順、敬称略〉:井上聡、加毛明、神作裕之、神田秀樹〈座長〉、宍戸常寿、事務局:日本銀行金融研究所)の報告書である。Artificial Intelligence(人工知能。以下、「AI」という。)技術の急速な進展とともに、AIの利用に対する期待も高まりを見せている。金融分野でも、さまざまなデータを利用したAIの導入が進んでいる。そこで、本報告書では、金融機関のAI利用を巡る法的な課題を明らかにすることを目的として、AIの利用に伴う法的リスクとその管理のあり方について分析を行った。主な指摘事項は次のとおりである。(i)AIモデルまたはシステムの開発・導入等の局面については、金融機関がAI開発者・AI提供者に対する契約責任を追及する場合の問題点と望ましい契約上の定めについて検討を行った。(ii)金融機関がAIを用いたサービスを顧客に提供する局面については、顧客に対する金融機関の責任の内容を確認し、一定の場合にはあらかじめAI利用にかかる契約を顧客との間で締結する必要があることを指摘した。(iii)組織内部のリスク管理の局面については、AIの利用に伴うリスク管理の必要性と取締役のAIガバナンス体制構築義務を前提に具体的なリスク管理のあり方を示した。AIは技術の進展が非常に速く、法的リスクについても不断の見直しを行っていく必要性が高い。本報告書で示した視点を契機として、金融機関におけるAIの利用にかかわる利害関係者が法的リスクにどのように対応していくべきかという観点での議論が深まっていくことが期待される。
|
||||
金融研究
|
||||
第45巻第1号
|
||||
:全文
|
||||
[1,215 KB PDF]
|
||||
掲載論文等の内容や意見は、執筆者個人に属し、日本銀行あるいは金融研究所の公式見解を示すものではありません。
|
||||
Copyright © 2026 Bank of Japan All Rights Reserved. 注意事項
|
||||
ホーム
|
||||
@@ -0,0 +1,81 @@
|
||||
---
|
||||
source_url: https://github.com/CachyOS/ananicy-rules
|
||||
ingested: 2026-06-29
|
||||
sha256: 44778e0ab5372b0641846e0efbd735016f6a85cd558f2b465f02a75bacd1eb77
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1028287639918497822'
|
||||
channel_name: "chat"
|
||||
message_id: '1521161015553691800'
|
||||
author_id: '890908900520505354'
|
||||
posted_at: 2026-06-29T14:30:47.913000000Z
|
||||
message_excerpt: "<@1394873980376322108> tldr https://github.com/CachyOS/ananicy-rules"
|
||||
---
|
||||
|
||||
# Ananicy-cpp-rules for CachyOS
|
||||
This is a ananicy-cpp-rules collection for ananicy-cpp maintained by the CachyOS team and the community.
|
||||
|
||||
## Ananicy-cpp & ananicy-cpp-rules
|
||||
- **[ananicy-cpp](https://gitlab.com/ananicy-cpp/ananicy-cpp)** - daemon that automatically adjusts the nice levels of processes.
|
||||
- **ananicy-cpp-rules** - list of rules used to assign specific nice values to specific processes.
|
||||
> The nice value determines the priority of a process, with higher values indicating lower priority and making the process "nicer" to other processes. By default, on Linux workstations, the nice value is set to 0.
|
||||
|
||||
## How to contribute
|
||||
|
||||
You can add your favorite games, apps, and more. Any help would be greatly appreciated!
|
||||
**For example, let's say you want to add a game:**
|
||||
1. Go to [00-default](https://github.com/CachyOS/ananicy-rules/tree/master/00-default)
|
||||
2. Go to [Games](https://github.com/CachyOS/ananicy-rules/tree/master/00-default/Games)
|
||||
3. Navigate to the desired folder depending on:
|
||||
- Game is meant to be ran under with Proton: [`wine_proton`](https://github.com/CachyOS/ananicy-rules/tree/master/00-default/Games/wine_proton) - *Open the corresponding file depending on the letter.*
|
||||
- Provides a native version for Linux: [`linux-native`](https://github.com/CachyOS/ananicy-rules/tree/master/00-default/Games/linux-native) - *Open the corresponding file depending on the letter.*
|
||||
4. Open the corresponding file depending on the letter.
|
||||
5. Follow the examples from below.
|
||||
|
||||
### Examples of rules
|
||||
The **first example** is simple. In the **second example**, it is different because some games generate multiple processes. In such cases, you need to add all the processes related to the game.
|
||||
|
||||
Please also add the name of the game next to the url, which you get the name of said game from the Steam store.
|
||||
|
||||
If not from any store add name you think it needs.
|
||||
|
||||
#### 1. [Example rule for Just Cause 2](https://github.com/CachyOS/ananicy-rules/blob/b3bf685c267cdc817a7067c6c16c9725cd5c5250/00-default/Games/wine_proton/wine_proton_j.rules#L168)
|
||||
|
||||
```
|
||||
# Just Cause 2 https://store.steampowered.com/app/8190/Just_Cause_2/
|
||||
{ "name": "JustCause2.exe", "type": "Game" }
|
||||
```
|
||||
|
||||
#### 2. [Example rules for The Outer Worlds](https://github.com/CachyOS/ananicy-rules/blob/b3bf685c267cdc817a7067c6c16c9725cd5c5250/00-default/Games/wine_proton/wine_proton_the.rules#L759)
|
||||
|
||||
```
|
||||
# The Outer Worlds https://store.steampowered.com/app/578650/The_Outer_Worlds/
|
||||
{ "name": "Indiana-Win64-Shipping.exe", "type": "Game" }
|
||||
{ "name": "TheOuterWorlds.exe", "type": "Game" }
|
||||
```
|
||||
|
||||
#### 3. [Example rules for Portal 2 which is Linux native game](https://github.com/CachyOS/ananicy-rules/blob/b3bf685c267cdc817a7067c6c16c9725cd5c5250/00-default/Games/linux-native/linux-native_p.rules#L157)
|
||||
|
||||
```
|
||||
# Portal 2 https://store.steampowered.com/app/620/Portal_2/
|
||||
{ "name": "portal2_linux", "type": "Game" }
|
||||
```
|
||||
|
||||
Duplicate entries can be detected with this command: ```grep -rhoP --include='*.rules' '"name"\s*:\s*"\K[^"]+' . | sort | uniq -d```
|
||||
|
||||
Games can be sorted with sort-games.sh, for more information run this in terminal ```./sort-games.sh --help```
|
||||
|
||||
### <u>You can also contribute by opening an [issue](https://github.com/CachyOS/ananicy-rules/issues) and providing information about the application </u>
|
||||
**Make sure the app is not already in the repository before opening an issue.**
|
||||
## How to find out proper process name?
|
||||
Here is a list of tools
|
||||
### CLI
|
||||
- [htop](https://htop.dev/)
|
||||
- [btop](https://github.com/aristocratos/btop)
|
||||
### GUI
|
||||
- System Monitor [KDE Plasma](https://apps.kde.org/plasma-systemmonitor/) or [GNOME](https://help.gnome.org/users/gnome-system-monitor/)
|
||||
|
||||
**Don't use absolute paths for the executables. Process name alone is enough.**
|
||||
|
||||
## [GameMode](https://github.com/FeralInteractive/gamemode) + [ananicy-cpp](https://gitlab.com/ananicy-cpp/ananicy-cpp) = bad idea
|
||||
GameMode and ananicy-cpp both adjust the nice levels of processes. However, combining both tools is not recommended, and we strongly advise against doing so.
|
||||
@@ -0,0 +1,121 @@
|
||||
---
|
||||
source_url: https://github.com/cicd-sensor/cicd-sensor
|
||||
ingested: 2026-06-30
|
||||
sha256: 08058a397765b7e6a7bf7d3d5018ee10cf4a016e082943576f6dee56c5d8a72a
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521355038830624930'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T03:21:46.667000000Z
|
||||
message_excerpt: 'CI/CD runtime security sensor mentioned with Betterleaks in development pipeline security context.'
|
||||
score: 4
|
||||
---
|
||||
|
||||
> 🚧 **Pre-release: Active development.**cicd-sensor is currently in pre-release and under active development. Feedback is very welcome.
|
||||
|
||||
[](https://github.com/cicd-sensor/cicd-sensor/blob/main/cicd-sensor.png)
|
||||
|
||||
## cicd-sensor
|
||||
|
||||
**Think EDR, but for CI/CD Pipelines.**
|
||||
Open-source eBPF-powered runtime security sensor for GitHub Actions and GitLab CI/CD.
|
||||
→ [Full documentation](https://cicd-sensor.github.io/)
|
||||
|
||||
[](https://github.com/cicd-sensor/cicd-sensor/blob/main/LICENSE) [](https://camo.githubusercontent.com/920759ad0fbe78e3c756bb908f771cfc9b9f332bfd6d757330dc1473c9aca9a9/68747470733a2f2f696d672e736869656c64732e696f2f62616467652f4c616e67756167652d476f2d3030414444383f6c6f676f3d676f) [](https://camo.githubusercontent.com/fefe06c66905a8f773dffed48997bf85b135765e4d0c73eb768d70276abfebac/68747470733a2f2f696d672e736869656c64732e696f2f62616467652f506c6174666f726d2d4c696e75782d4643433632343f6c6f676f3d6c696e7578) [](https://camo.githubusercontent.com/be0329c07c65d567c874f00316fc1716017dd065e6dd16b9c20be29760d58d93/68747470733a2f2f696d672e736869656c64732e696f2f62616467652f4f70656e253230536f757263652d5965732d627269676874677265656e)
|
||||
|
||||
---
|
||||
|
||||
## Demo
|
||||
|
||||
| [](https://github.com/cicd-sensor/cicd-sensor/blob/main/docs/assets/demo.gif) |
|
||||
| --- |
|
||||
|
||||
<sub>Example: cicd-sensor added to a GitHub Actions workflow. The resulting reports are viewable in the GitHub job summary.</sub>
|
||||
|
||||
## What cicd-sensor does
|
||||
|
||||
When a compromised dependency in a CI/CD job steals your cloud credentials and leaks them, would you catch it? Would you have the logs to investigate afterward? cicd-sensor is an open-source sensor that lets every team answer both.
|
||||
|
||||
**Detection:** Detects supply-chain attacks at runtime using process ancestry (e.g. credential access from a process descended from `npm install`) and correlation across signals (e.g. multiple credential categories read in one job). Baseline rules target patterns seen in real CI/CD attacks, and are opt-out: turn them off if you only want the logs and evidence below.
|
||||
|
||||
**Logs and evidence:** Per run, cicd-sensor can emit logs for review, alerting, and forensics, routed through cicd-sensor Manager to cloud sinks like S3, GCS, and Pub/Sub. The cicd-sensor-action can also produce a graphical report and a build attestation per run. Your data stays under your control. cicd-sensor never sends anything to servers operated by the cicd-sensor project.
|
||||
|
||||
## Quick start
|
||||
|
||||
On GitHub-hosted runners, add the cicd-sensor action as the first step in your workflow.
|
||||
|
||||
```
|
||||
jobs:
|
||||
build:
|
||||
runs-on: ubuntu-24.04
|
||||
steps:
|
||||
- uses: cicd-sensor/cicd-sensor-action@777ddaafc9ec2e09c9779cdb860e75906adc19c2 # v0.0.34
|
||||
```
|
||||
|
||||
For self-hosted GitHub Actions or GitLab CI/CD, see the [User Guide](https://cicd-sensor.github.io/user-guide/overview.html).
|
||||
|
||||
## Why CI/CD runtime needs this
|
||||
|
||||
CI/CD pipelines build, release, deploy, and manage cloud infrastructure, and they hold the cloud credentials, signing keys, and registry tokens to do it. Supply-chain attackers run inside those jobs and disappear with the evidence when the job ends.
|
||||
|
||||
Most other runtimes have their open-source defenders: Falco, Tetragon, Tracee, Wazuh, OSQuery. Open-source coverage for CI/CD runtime has lagged behind. Sigstore proved *where* and *how* artifacts were built; cicd-sensor preserves *what actually ran* so teams can detect, respond, and audit.
|
||||
|
||||
## Feature comparison
|
||||
|
||||
| Capability | cicd-sensor | Harden-Runner (Free) | Comment |
|
||||
| --- | --- | --- | --- |
|
||||
| **Licensing & deployment** | | | |
|
||||
| Open source | ✅ Yes | ✅ Yes | |
|
||||
| Data privacy | ✅ Self-hosted | SaaS backend | cicd-sensor runs entirely in your infrastructure, so logs and events stay in your environment. |
|
||||
| **Platform coverage** | | | |
|
||||
| Private repos | ✅ Yes | ❌ No | |
|
||||
| Self-hosted runners | ✅ Yes | ❌ No | Enforcing self-hosted runners enables organization-wide log collection across every job. |
|
||||
| GitHub Actions support | ✅ Yes | ✅ Yes | |
|
||||
| GitLab CI/CD support | ✅ Yes | ❌ No | |
|
||||
| **Capabilities** | | | |
|
||||
| Detection rules | ✅ Yes | ✅ Yes | |
|
||||
| Flexible custom rules | ✅ Yes | 🔶 Limited | cicd-sensor rules cover process ancestry, file access, and correlation across signals; Harden-Runner is mainly a network egress allowlist. |
|
||||
| Network blocking | 🔶 Partial | ✅ Yes | cicd-sensor kills the process and stops the job on detection instead of filtering traffic like a firewall. |
|
||||
| Log export | ✅ Yes | ❌ No | |
|
||||
|
||||
<sub>This table compares the free version of Harden-Runner. StepSecurity's paid platform adds more, such as private repository and self-hosted runner support, dashboards, and policy management.</sub>
|
||||
|
||||
<sub>Based on public information as of May 2026. Corrections welcome.</sub>
|
||||
|
||||
## Supported CI/CD pipelines
|
||||
|
||||
| Platform | Environment | Status |
|
||||
| --- | --- | --- |
|
||||
| GitHub Actions | GitHub-hosted runner | ✅ Supported |
|
||||
| GitHub Actions | Self-hosted runner on a machine | ✅ Supported |
|
||||
| GitHub Actions | Actions Runner Controller on Kubernetes | 🧪 Preview support |
|
||||
| GitLab CI/CD | GitLab Runner Docker executor | ✅ Supported |
|
||||
| GitLab CI/CD | GitLab Runner Kubernetes executor | 🧪 Preview support |
|
||||
| GitLab CI/CD | GitLab-hosted runner | ❌ Not supported (technical constraints) |
|
||||
|
||||
Works on both public and private repositories, with no third-party SaaS dependency.
|
||||
|
||||
Linux kernel: 5.15 or later on `amd64`, 6.1 or later on `arm64`.
|
||||
|
||||
## Rules
|
||||
|
||||
cicd-sensor ships with a set of baseline rules. See the [Baseline Rules guide](https://cicd-sensor.github.io/user-guide/baseline-rules.html) for how they work; the rule definitions themselves live in [`rules/`](https://github.com/cicd-sensor/cicd-sensor/blob/main/rules). You can also write your own rules, or turn the baseline off entirely.
|
||||
|
||||
## Documentation
|
||||
|
||||
- [Getting Started](https://cicd-sensor.github.io/): what cicd-sensor is and how to start.
|
||||
- [User Guide](https://cicd-sensor.github.io/user-guide/overview.html): deployment paths for GitHub Actions and GitLab CI/CD.
|
||||
- [Rules](https://cicd-sensor.github.io/user-guide/rules.html): write detection, collection, and correlation rules.
|
||||
- [Logging](https://cicd-sensor.github.io/user-guide/logging.html): log format delivered by the manager.
|
||||
- [Attestation predicate](https://cicd-sensor.github.io/user-guide/attestation-predicate.html): runtime-trace predicate for CI/CD runtime evidence.
|
||||
- [Developer Guide](https://cicd-sensor.github.io/developer-guide/overview.html): agent, eBPF runtime, manager, and rule engine internals.
|
||||
|
||||
## About the project
|
||||
|
||||
A read-only official mirror is published at [gitlab.com/cicd-sensor/cicd-sensor](https://gitlab.com/cicd-sensor/cicd-sensor). GitHub is the canonical source; the GitLab mirror is synced periodically.
|
||||
|
||||
## License
|
||||
|
||||
Apache License 2.0 ([LICENSE](https://github.com/cicd-sensor/cicd-sensor/blob/main/LICENSE)). BPF source under `internal/agent/bpf/` is dual-licensed `GPL-2.0-only OR BSD-2-Clause` ([details](https://github.com/cicd-sensor/cicd-sensor/blob/main/internal/agent/bpf/README.md#licensing)).
|
||||
@@ -0,0 +1,65 @@
|
||||
---
|
||||
source_url: https://gihyo.jp/article/2026/06/cursor-for-ios
|
||||
ingested: 2026-06-30
|
||||
sha256: 1c43584c4586c139950975b1d0b50802f6f760062aea4683b59c1b77245136af
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521355038830624930'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T03:21:46.667000000Z
|
||||
message_excerpt: 'Cursor iOS mobile interface for AI coding agents.'
|
||||
score: 2
|
||||
---
|
||||
|
||||
Anysphereは2026年6月29日、コーディングエージェントCursorのiOSアプリをパブリックベータとしてリリースした。現在すべてのCursor有料プランで利用可能となっている。
|
||||
|
||||
- [Cursor for iOS でどこからでも開発 -Cursor](https://cursor.com/ja/blog/ios-mobile-app)
|
||||
- [CursorApp -App Store](https://apps.apple.com/us/app/cursor/id6767085653)
|
||||
|
||||
> Introducing Cursor for iOS.
|
||||
>
|
||||
> Build from anywhere by launching always-on cloud agents. Or remotely control agents running on your computer from the app.
|
||||
>
|
||||
> Composer 2. 5 is 75% off in the app now through July 5. [pic. twitter. com/ dFxQyrgmBb](https://t.co/dFxQyrgmBb)
|
||||
>
|
||||
> — Cursor (@cursor\_ai) [June 29, 2026](https://x.com/cursor_ai/status/2071641103191998810?ref_src=twsrc%5Etfw)
|
||||
|
||||
CursorのiOSアプリは、クラウド上やローカルのコンピュータで実行されるエージェントを操作するためのネイティブ モバイルアプリ。iPhoneからエージェントを起動し、作業をリアルタイムで追いながらプルリクエストの確認やマージを行うことができる。
|
||||
|
||||
iPhoneなどからCursorのiOSアプリを開いてリポジトリを選べば、デスクトップアプリと同じようにエージェントが起動する。好きなAIモデルを選び、音声入力を使ってアプリに要望を伝えたり、スラッシュコマンドを使ってCursorを操作することもできる。これによりクラウドで常時稼働するエージェントを起動したり、レビュー可能になったプロジェクトの通知を受け取り、外出先からプルリクエストをマージすることができる。
|
||||
|
||||
またコンピュータで実行中のエージェントにRemote Controlを使ってiOS Cursorアプリからの指示を継続することも可能で、デスクを離れている間もマシンに接続できる状態を保つため、コンピュータをスリープさせない設定を有効にできる。一度エージェントが動き始めたらCursorアプリを閉じても動作を続け、ロック画面のライブアクティビティやエージェントからのプッシュ通知で状況が随時通知される。
|
||||
|
||||
そしてクラウドエージェントを使うと、エージェントを完全な開発環境を備えた隔離された仮想マシン上で実行でき、非同期で長時間の作業を続けることが可能。使用を開始するにはローカルのプランをクラウドエージェントに送信するか、アクティブなエージェントをクラウドに移動させる。マージ前に変更をローカルでテストできるよう、クラウドセッションを自分のコンピュータに戻すこともできる。
|
||||
|
||||
一方、以下の作業はiOSアプリから行うことはできず、 [cursor. com](https://cursor.com/agents) および [Cursorダッシュボード](https://cursor.com/dashboard) で操作、設定する必要がある。
|
||||
|
||||
エディタ 、 ターミナル 、 ファイルブラウザのフル操作
|
||||
|
||||
モバイルアプリではdiffビューで変更されたファイルのみが表示される。
|
||||
|
||||
シークレットとクラウドエージェントの環境設定
|
||||
|
||||
Webでまず設定を行った後、モバイルのエージェントは、セットアップ後の環境を使用する。
|
||||
|
||||
MCPサーバーの管理
|
||||
|
||||
モバイルからは実行ごとにサーバーの選択のみが可能。MCPサーバーの追加と管理はWebで行う。
|
||||
|
||||
リポジトリの設定
|
||||
|
||||
GitHubやGitLabとの接続・ 再接続はダッシュボードから行う。
|
||||
|
||||
自動化 、 ルール 、 スキルの設定
|
||||
|
||||
これらはWebで管理される。エージェントはリポジトリにすでに設定されたものを検出して利用する。
|
||||
|
||||
Cursorの管理 、 支払い 、 利用状況確認
|
||||
|
||||
Webからのみ可能。
|
||||
|
||||
その他、Cursor for iOSの詳しい操作等は [ドキュメント](https://cursor.com/ja/docs/cloud-agent/mobile) を参照。
|
||||
|
||||
なおCursor for iOSのリリースにともない、2026年7月5日までiOSアプリからのComposer 2. 5の実行が75%オフになるキャンペーンが実施されている。
|
||||
@@ -0,0 +1,168 @@
|
||||
---
|
||||
source_url: https://github.com/hawkymisc/daida-ai/blob/main/README_JA.md
|
||||
ingested: 2026-06-29
|
||||
sha256: bde165d558ecf520bf15b6c2617d297323c5b707207f001bbdfc381d68bf51a4
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1028287639918497822'
|
||||
channel_name: "chat"
|
||||
message_id: '1521180733090037850'
|
||||
author_id: '890908900520505354'
|
||||
posted_at: 2026-06-29T15:49:08.940000000Z
|
||||
message_excerpt: "https://github.com/hawkymisc/daida-ai/blob/main/README_JA.md"
|
||||
---
|
||||
|
||||
[English](./README.md) | [日本語](./README_JA.md) | [简体中文](./README_ZH.md) | [한국어](./README_KO.md)
|
||||
|
||||
# 代打AI
|
||||
|
||||
LT登壇を代打してくれる Claude Code Plugin.
|
||||
|
||||
## 機能概要
|
||||
|
||||
1. 登壇テーマを入力したら、発表のアウトラインをMarkdownで出力・保存する
|
||||
2. 当該Markdownに基づき、スライド資料を作成する
|
||||
- スライド資料はPowerPointで作成する
|
||||
- 事前に定義されたスライドテンプレートのデザインに従い作成する
|
||||
- スライドは白紙からではなく、スライドレイアウトを選択して作成する
|
||||
- スライドタイトルやテキスト本文はアウトライン表示で確認できるように設定する
|
||||
3. スライド資料のnote欄にトークスクリプト(台本)を記入する
|
||||
- スクリプトは、カジュアル、キーノートなど複数のスタイルで文体を選べる
|
||||
4. トークスクリプトを読み上げた音声を合成する
|
||||
- 読み辞書による誤読の自動修正に対応
|
||||
- TTSスクリプトをエクスポートして手動修正も可能
|
||||
5. 上記音声合成をスライドに埋め込む
|
||||
6. スライドショーの自動再生を設定する
|
||||
|
||||
## 対応フォーマット
|
||||
|
||||
pptx および odp(Open Document Presentation)
|
||||
|
||||
## インストール
|
||||
|
||||
### 前提条件
|
||||
|
||||
- [Claude Code](https://docs.anthropic.com/en/docs/claude-code) がインストール済み
|
||||
- Python 3.11以上
|
||||
|
||||
### Step 1: マーケットプレイスを追加
|
||||
|
||||
Claude Code 内で以下を実行:
|
||||
|
||||
```
|
||||
/plugin marketplace add hawkymisc/daida-ai
|
||||
```
|
||||
|
||||
### Step 2: プラグインをインストール
|
||||
|
||||
```
|
||||
/plugin install daida-ai@hawkymisc-daida-ai
|
||||
```
|
||||
|
||||
### Step 3: セットアップ
|
||||
|
||||
初回使用時、`/daida-ai:daida-ai` を実行するとセットアップスクリプトの実行を求められます。
|
||||
Claude の指示に従い、以下のコマンドを承認してください:
|
||||
|
||||
```bash
|
||||
bash <plugin-dir>/skills/daida-ai/scripts/setup.sh
|
||||
```
|
||||
|
||||
これにより Python 仮想環境の作成と依存パッケージのインストールが行われます。
|
||||
|
||||
## 使い方
|
||||
|
||||
Claude Code で以下のように呼び出します:
|
||||
|
||||
```
|
||||
/daida-ai:daida-ai
|
||||
```
|
||||
|
||||
または、自然言語で依頼できます:
|
||||
|
||||
- 「LTの資料を作って」
|
||||
- 「プレゼンを作成して」
|
||||
- 「代打で登壇資料を作って」
|
||||
|
||||
### ワークフロー
|
||||
|
||||
対話形式で以下を聞かれます:
|
||||
|
||||
1. **テーマ**: 何について話すか
|
||||
2. **対象者**: 誰に向けたLTか
|
||||
3. **持ち時間**: 何分か(デフォルト5分)
|
||||
4. **テンプレート**: `tech` / `casual` / `formal`
|
||||
5. **TTSエンジン**: `edge`(デフォルト) / `voicevox`
|
||||
|
||||
全自動で、アウトライン → スライド → トークスクリプト → 音声合成 → 音声埋め込み → スライドショー設定 まで実行されます。
|
||||
|
||||
### ヘルプ
|
||||
|
||||
「ヘルプ」「使い方」「流れを教えて」と聞くと、パイプライン全体の図が表示されます。
|
||||
|
||||
### ステップ再開
|
||||
|
||||
途中でPPTXや読み上げテキストを修正した場合、「Step 4 からやり直して」のように指定すると、そのステップから再開できます。
|
||||
|
||||
よくある例:
|
||||
- PPTXを手動修正した後 → 「Step 4 から」で音声を再生成
|
||||
- 読みを修正した後 → 「Step 4c から」で音声合成のみ再実行
|
||||
- テンプレートを変えたい → 「Step 2 から」でスライド再生成
|
||||
|
||||
### 読み上げテキストの修正
|
||||
|
||||
TTSが誤った読みを生成する場合(例: 「生成」→「せいしげる」)、以下の方法で修正できます:
|
||||
|
||||
- **読み辞書**: `skills/daida-ai/assets/pronunciation_dict.tsv` に置換ルールを定義(エクスポート時に自動適用)
|
||||
- **手動修正**: TTSスクリプトをエクスポートし、テキストエディタで直接修正
|
||||
|
||||
## テンプレート
|
||||
|
||||
| テンプレート | 特徴 | 日本語フォント |
|
||||
|------------|------|--------------|
|
||||
| `tech` | ダークテーマ、シアンアクセント | Noto Sans CJK JP |
|
||||
| `casual` | ウォーム系、丸みのあるデザイン | Noto Sans CJK JP |
|
||||
| `formal` | ホワイトベース、ビジネス向け | Noto Serif CJK JP / Noto Sans CJK JP |
|
||||
|
||||
## 音声合成エンジン
|
||||
|
||||
| エンジン | 特徴 | 備考 |
|
||||
|----------|------|------|
|
||||
| edge-tts | Microsoft Edge TTS。インストール不要 | デフォルト |
|
||||
| VOICEVOX | ずんだもん等のキャラクター音声 | [VOICEVOX Engine](https://voicevox.hiroshiba.jp/) の起動が必要 |
|
||||
|
||||
## バリデーション
|
||||
|
||||
スライド仕様JSON(LLMが生成)に対して、以下のバリデーションを自動実行します:
|
||||
|
||||
- スライド枚数(1〜20枚)
|
||||
- レイアウトとフィールドの整合性(例: `two_content`には`left`/`right`が必須)
|
||||
- テキスト長の上限(タイトル100字、本文項目200字 等)
|
||||
- 音声ファイルの形式(MP3/WAV)とサイズ(50MB以下)
|
||||
- 推定発話時間の上限チェック
|
||||
|
||||
## 注意事項
|
||||
|
||||
### LibreOffice Impress での再生について
|
||||
|
||||
自動ページ送り(スライドショー中に音声終了後に自動で次のスライドに進む機能)は **PowerPoint(Windows / macOS)でのみ動作** します。
|
||||
|
||||
**LibreOffice Impress では自動ページ送りが動作しません**。これは LibreOffice が PPTX 内のタイミング設定(`advTm`)を正しく処理しない既知の制限によるものです([Bug 101527](https://bugs.documentfoundation.org/show_bug.cgi?id=101527))。
|
||||
|
||||
LibreOffice で再生する場合は、以下のいずれかで対応してください:
|
||||
- **手動**でスライドを送る(クリックまたは矢印キー)
|
||||
- LibreOffice 上で「スライド切り替え」パネルから各スライドの自動切り替え時間を手動設定する
|
||||
|
||||
### フォントについて
|
||||
|
||||
テンプレートの日本語フォントには [Noto CJK](https://github.com/googlefonts/noto-cjk) を使用しています。
|
||||
Windows / macOS / Linux いずれでも利用可能ですが、未インストールの場合はOSのデフォルトフォントで代替されます。
|
||||
最適な表示のため、事前に Noto Sans CJK JP のインストールを推奨します。
|
||||
|
||||
## ライセンス
|
||||
|
||||
MIT
|
||||
|
||||
---
|
||||
|
||||
> 本ドキュメントは [README.md](./README.md) の日本語版です。内容に相違がある場合は英語版が正となります。
|
||||
@@ -0,0 +1,530 @@
|
||||
---
|
||||
source_url: https://github.com/yutakobayashidev/edcb-tools
|
||||
ingested: 2026-06-29
|
||||
sha256: f9f2d326d774a922b3a96b590a9b49734bd847a60099d869a3fc3adf223164ed
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1028287639918497822'
|
||||
channel_name: chat
|
||||
message_id: '1521200608739332257'
|
||||
author_id: '890908900520505354'
|
||||
posted_at: 2026-06-29T17:08:07.664000000Z
|
||||
message_excerpt: 'https://github.com/yutakobayashidev/edcb-tools'
|
||||
score: 2
|
||||
---
|
||||
# edcb-tools
|
||||
|
||||
[](https://deepwiki.com/yutakobayashidev/edcb-tools)
|
||||
|
||||
Rust client library, command line interface, and MCP server for EDCB/EpgTimer
|
||||
CtrlCmd.
|
||||
|
||||
This crate currently provides a Tokio-based TCP client, binary codec, `edcb`
|
||||
CLI, and `edcb-mcp` stdio MCP server for CtrlCmd APIs used by EDCB
|
||||
integrations. The implementation is ported from `xtne6f/edcb.py`, with
|
||||
KonomiTV's async usage used as a secondary reference.
|
||||
|
||||
## Distribution
|
||||
|
||||
Nix flake is the primary distribution surface. The default package builds both
|
||||
first-class binaries:
|
||||
|
||||
- `edcb`
|
||||
- `edcb-mcp`
|
||||
|
||||
Run the CLI directly from GitHub:
|
||||
|
||||
```sh
|
||||
nix run github:yutakobayashidev/edcb-tools#edcb -- --host 127.0.0.1 services
|
||||
```
|
||||
|
||||
Run the stdio MCP server directly from GitHub:
|
||||
|
||||
```sh
|
||||
nix run github:yutakobayashidev/edcb-tools#edcb-mcp -- --host 127.0.0.1 --port 4510
|
||||
```
|
||||
|
||||
Install both binaries into a Nix profile:
|
||||
|
||||
```sh
|
||||
nix profile install github:yutakobayashidev/edcb-tools#edcb-tools
|
||||
```
|
||||
|
||||
Use the package from another flake:
|
||||
|
||||
```nix
|
||||
{
|
||||
inputs.edcb-tools.url = "github:yutakobayashidev/edcb-tools";
|
||||
|
||||
outputs = { edcb-tools, ... }: {
|
||||
# edcb-tools.packages.${system}.default
|
||||
# edcb-tools.packages.${system}.edcb-tools
|
||||
# edcb-tools.apps.${system}.edcb
|
||||
# edcb-tools.apps.${system}.edcb-mcp
|
||||
};
|
||||
}
|
||||
```
|
||||
|
||||
The Rust client library is intended to be consumed from this repository, not
|
||||
published to crates.io:
|
||||
|
||||
```toml
|
||||
[dependencies]
|
||||
edcb-tools = { git = "https://github.com/yutakobayashidev/edcb-tools" }
|
||||
```
|
||||
|
||||
## Supported in v1
|
||||
|
||||
- TCP transport
|
||||
- `edcb` command line interface
|
||||
- stdio MCP server surface
|
||||
- EDCB primitive, string, vector, struct, and `SYSTEMTIME` codec
|
||||
- Service, EPG, reserve, recorded-file, tuner, plugin, auto-add, manual-add,
|
||||
and notify-status read APIs
|
||||
- Program search, timetable retrieval, recorded item detail retrieval,
|
||||
reservation detail retrieval, and event-based reservation
|
||||
preview/create/update/delete with recording options
|
||||
- Utility parsers for `ChSet5.txt`, `LogoData.ini`, logo directory indexes, and
|
||||
program extended text
|
||||
|
||||
## Architecture
|
||||
|
||||
`EdcbClient` is a raw CtrlCmd client: its methods map closely to EDCB commands
|
||||
and wire data structures. Application-level operations such as program search
|
||||
and event-based reservation preview/create are exported from the crate root. The
|
||||
CLI and MCP server call these operations instead of embedding CtrlCmd
|
||||
orchestration directly. TCP transport is isolated behind an internal transport
|
||||
boundary so additional transports can be added without rewriting command
|
||||
encoding.
|
||||
|
||||
## To Do
|
||||
|
||||
- [ ] Unix domain socket transport
|
||||
- [ ] Windows named pipe transport
|
||||
- [ ] View app stream / SrvPipe stream helpers
|
||||
- [ ] Recorded-file, auto-add, and manual-add mutation APIs
|
||||
- [x] MCP server surface
|
||||
- [ ] HTTP MCP transport
|
||||
|
||||
## Example
|
||||
|
||||
```rust
|
||||
use std::time::Duration;
|
||||
|
||||
use edcb_tools::{ConnectionConfig, EdcbClient};
|
||||
|
||||
#[tokio::main]
|
||||
async fn main() -> edcb_tools::Result<()> {
|
||||
let client = EdcbClient::new(
|
||||
ConnectionConfig::new("127.0.0.1", 4510).with_timeout(Duration::from_secs(5)),
|
||||
);
|
||||
|
||||
let services = client.enum_service().await?;
|
||||
for service in services {
|
||||
println!("{}: {}", service.sid, service.service_name);
|
||||
}
|
||||
|
||||
Ok(())
|
||||
}
|
||||
```
|
||||
|
||||
## Command Line Interface
|
||||
|
||||
Run the `edcb` CLI through the flake:
|
||||
|
||||
```sh
|
||||
nix run .#edcb -- --host 127.0.0.1 --port 4510 services
|
||||
```
|
||||
|
||||
During development, the same CLI can be run with Cargo:
|
||||
|
||||
```sh
|
||||
cargo run --bin edcb -- --host 127.0.0.1 --port 4510 services
|
||||
```
|
||||
|
||||
The same connection settings can be supplied through environment variables:
|
||||
|
||||
```sh
|
||||
EDCB_HOST=127.0.0.1 EDCB_PORT=4510 EDCB_TIMEOUT_SECONDS=15 cargo run --bin edcb -- services
|
||||
```
|
||||
|
||||
CLI options take precedence over environment variables. Defaults are
|
||||
`127.0.0.1`, port `4510`, and a 15 second timeout.
|
||||
|
||||
Output is a stable line-based summary by default. Use `--json` for full
|
||||
structured output.
|
||||
|
||||
Run `edcb --help`, `edcb help`, or `edcb help <command>` for clap-generated
|
||||
usage, options, and examples from the current build.
|
||||
|
||||
Available commands:
|
||||
|
||||
- `services`
|
||||
- `reserves`
|
||||
- `recorded list`
|
||||
- `recorded get <info-id>`
|
||||
- `programs search [search options]`
|
||||
- `programs timetable [timetable options]`
|
||||
- `channels`
|
||||
- `recording defaults`
|
||||
- `recording presets`
|
||||
- `reservation-conditions`
|
||||
- `reservation-conditions get <condition-id>`
|
||||
- `reservation-conditions create [search options] [recording options] --yes`
|
||||
- `reservation-conditions update <condition-id> [search options] [recording options] --yes`
|
||||
- `reservation-conditions delete <condition-id> --yes`
|
||||
- `reserves get <reserve-id>`
|
||||
- `reserves preview --event <onid:tsid:sid:eid> [recording options]`
|
||||
- `reserves create --event <onid:tsid:sid:eid> [recording options] --yes`
|
||||
- `reserves update <reserve-id> [recording options] --yes`
|
||||
- `reserves delete <reserve-id> --yes`
|
||||
- `tuner-reserves`
|
||||
- `tuner-processes`
|
||||
- `plugins <write|rec_name>`
|
||||
- `notify-status`
|
||||
|
||||
`reserves preview` is a client-side preview that fetches the EDCB default
|
||||
reservation settings and the target event, then builds the `ReserveData` that
|
||||
would be sent. EDCB does not expose a reservation dry-run command. Use
|
||||
`reserves create ... --yes` to send the actual add-reservation command. After
|
||||
creation, the CLI fetches reservations again and returns the newly assigned
|
||||
reservation ID when it can be resolved from the before/after difference.
|
||||
`reserves update ... --yes` fetches the existing reservation, applies recording
|
||||
option changes, sends the full updated reservation to EDCB, and returns the
|
||||
updated reservation data.
|
||||
`reserves delete ... --yes` first fetches the reservation by ID, then sends the
|
||||
delete command and returns the deleted reservation data.
|
||||
`programs search` prints event keys as `onid:tsid:sid:eid`, which can be passed
|
||||
to `reserves preview` or `reserves create`.
|
||||
|
||||
Preview JSON has the same `ReserveData` shape that create/get return. The
|
||||
previewed reservation has not been sent to EDCB yet. Abridged example:
|
||||
|
||||
```json
|
||||
{
|
||||
"reserve_id": 0,
|
||||
"onid": 32736,
|
||||
"tsid": 32736,
|
||||
"sid": 1024,
|
||||
"eid": 4208,
|
||||
"start_time": "2026-06-29T22:00:00+09:00",
|
||||
"duration_second": 1800,
|
||||
"station_name": "Example Service",
|
||||
"title": "Example Program",
|
||||
"rec_setting": {
|
||||
"rec_mode": 1,
|
||||
"priority": 2
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
Useful reservation preview selectors:
|
||||
|
||||
```sh
|
||||
edcb --json reserves preview --event 32736:32736:1024:4208 \
|
||||
| jq '{event: "\(.onid):\(.tsid):\(.sid):\(.eid)", start_time, title, priority: .rec_setting.priority}'
|
||||
```
|
||||
|
||||
Program search uses EDCB's `SearchKeyInfo`/`SearchPg` semantics. Date ranges are
|
||||
recurring weekday/time-of-day ranges, not absolute datetimes. If no service is
|
||||
specified, the CLI first fetches EDCB's service list and searches those services.
|
||||
Use `programs timetable` when you want the program table for services/time
|
||||
windows instead of keyword search.
|
||||
`reservation-conditions` manages EDCB keyword auto reservations (`AutoAddData`)
|
||||
with the same search options and recording options. EDCB does not return the
|
||||
newly assigned AutoAdd ID from the add command, so create returns the condition
|
||||
payload that was sent with `id` set to `0`; list or get conditions afterwards to
|
||||
see assigned IDs.
|
||||
|
||||
Program search options:
|
||||
|
||||
- `--keyword <text>`
|
||||
- `--exclude-keyword <text>`
|
||||
- `--title-only`
|
||||
- `--case-sensitive`
|
||||
- `--regex`
|
||||
- `--fuzzy`
|
||||
- `--service <onid:tsid:sid>` (repeatable)
|
||||
- `--genre <major:middle[:user_nibble]>` (repeatable)
|
||||
- `--exclude-genre-ranges`
|
||||
- `--date-range <start-dow:HH:MM-end-dow:HH:MM>` (repeatable, `0` is Sunday)
|
||||
- `--exclude-date-ranges`
|
||||
- `--duration-min <minutes>` and `--duration-max <minutes>`
|
||||
- `--free-ca <all|free|paid>`
|
||||
- `--search-enable` / `--search-disable`
|
||||
- `--duplicate-title-check <none|same-channel|all-channels>`
|
||||
- `--duplicate-title-check-days <days>`
|
||||
|
||||
Examples:
|
||||
|
||||
```sh
|
||||
edcb programs search --keyword news --title-only
|
||||
edcb programs search --keyword news --genre 0:1
|
||||
edcb programs search --keyword news --date-range 1:19:00-1:23:00
|
||||
edcb programs search --keyword news --duration-min 30 --duration-max 120 --free-ca free
|
||||
edcb reservation-conditions create --keyword news --genre 0:1 --priority 4 --yes
|
||||
edcb reservation-conditions update 77 --keyword news --duplicate-title-check same-channel --yes
|
||||
```
|
||||
|
||||
Program timetable uses EDCB's `EnumPgInfoEx` semantics. It returns programs
|
||||
grouped by service, nests short same-TS subchannels under their main channel,
|
||||
and attaches reservation metadata when a matching reservation can be found.
|
||||
JSON output includes `reservation_metadata_status`; if reservation lookup fails,
|
||||
programs are still returned and the status contains the failure message.
|
||||
|
||||
Timetable options:
|
||||
|
||||
- `--service <onid:tsid:sid>` (repeatable)
|
||||
- `--start-time <RFC3339 datetime>`
|
||||
- `--end-time <RFC3339 datetime>`
|
||||
- `--channel-type <gr|bs|cs|catv|sky|bs4k>`
|
||||
|
||||
Examples:
|
||||
|
||||
```sh
|
||||
edcb programs timetable --channel-type gr
|
||||
edcb programs timetable --service 32736:32736:1024 --start-time 2026-06-29T19:00:00+09:00 --end-time 2026-06-29T23:00:00+09:00
|
||||
```
|
||||
|
||||
Timetable JSON nests program details under `channels[].programs[].event`.
|
||||
Reservation metadata is optional per program; check
|
||||
`reservation_metadata_status` before treating `reservation: null` as definitive.
|
||||
Abridged example:
|
||||
|
||||
```json
|
||||
{
|
||||
"channels": [
|
||||
{
|
||||
"service": {
|
||||
"onid": 32736,
|
||||
"tsid": 32736,
|
||||
"sid": 1024,
|
||||
"service_name": "Example Service"
|
||||
},
|
||||
"programs": [
|
||||
{
|
||||
"event": {
|
||||
"onid": 32736,
|
||||
"tsid": 32736,
|
||||
"sid": 1024,
|
||||
"eid": 4208,
|
||||
"start_time": "2026-06-29T22:00:00+09:00",
|
||||
"short_info": {
|
||||
"event_name": "Example Program"
|
||||
}
|
||||
},
|
||||
"reservation": {
|
||||
"id": 77,
|
||||
"status": "Reserved",
|
||||
"recording_availability": "Full"
|
||||
}
|
||||
}
|
||||
],
|
||||
"subchannels": null
|
||||
}
|
||||
],
|
||||
"date_range": {
|
||||
"earliest": "2026-06-29T19:00:00+09:00",
|
||||
"latest": "2026-06-29T23:00:00+09:00"
|
||||
},
|
||||
"reservation_metadata_status": "Ok"
|
||||
}
|
||||
```
|
||||
|
||||
Useful timetable selectors:
|
||||
|
||||
```sh
|
||||
edcb --json programs timetable --channel-type gr \
|
||||
| jq -r '.channels[].programs[] | [.event.onid, .event.tsid, .event.sid, .event.eid, .event.start_time, .event.short_info.event_name, (.reservation != null)] | @tsv'
|
||||
|
||||
edcb --json programs timetable --channel-type gr \
|
||||
| jq -r '.channels[].programs[] | select(.reservation == null) | "\(.event.onid):\(.event.tsid):\(.event.sid):\(.event.eid)\t\(.event.start_time)\t\(.event.short_info.event_name)"'
|
||||
```
|
||||
|
||||
`channels` returns a DB-free KonomiTV-style channel snapshot built from
|
||||
`ChSet5.txt` and `EnumService`. It includes `display_channel_id`, channel type,
|
||||
service key, remocon ID, subchannel/radio flags, and watchability flags. Because
|
||||
it is stateless, it does not preserve recorded-only historical channels, pinned
|
||||
channels, jikkyo state, or viewer counts. Plain output is still one line per
|
||||
channel; JSON output wraps the list in `channels` and includes
|
||||
`epg_service_status` so callers can distinguish missing EPG metadata from an
|
||||
empty channel list.
|
||||
|
||||
```sh
|
||||
edcb channels
|
||||
edcb --json channels
|
||||
```
|
||||
|
||||
`recording defaults` decodes the EDCB default reservation settings returned by
|
||||
`GetReserve2(0x7fffffff)`. `recording presets` reads `EpgTimerSrv.ini` through
|
||||
`FileCopy2` and returns global defaults plus recording presets, including ID 0.
|
||||
If EDCB returns an empty `EpgTimerSrv.ini`, use `recording defaults` for the
|
||||
effective reservation default.
|
||||
|
||||
```sh
|
||||
edcb recording defaults
|
||||
edcb --json recording presets
|
||||
```
|
||||
|
||||
Common recording options:
|
||||
|
||||
- `--priority <1-5>`
|
||||
- `--enable` / `--disable`
|
||||
- `--recording-mode <all|all-without-decoding|specified|specified-without-decoding|view>`
|
||||
- `--start-margin <seconds>` and `--end-margin <seconds>`
|
||||
- `--caption <default|enable|disable>` and `--data <default|enable|disable>`
|
||||
- `--post-recording <default|nothing|standby|standby-and-reboot|suspend|suspend-and-reboot|shutdown>`
|
||||
|
||||
## MCP Server
|
||||
|
||||
Run the `edcb-mcp` stdio MCP server through the flake:
|
||||
|
||||
```sh
|
||||
nix run .#edcb-mcp -- --host 127.0.0.1 --port 4510 --timeout-seconds 15
|
||||
```
|
||||
|
||||
During development, the same server can be run with Cargo:
|
||||
|
||||
```sh
|
||||
cargo run --bin edcb-mcp -- --host 127.0.0.1 --port 4510 --timeout-seconds 15
|
||||
```
|
||||
|
||||
The same connection settings can be supplied through environment variables:
|
||||
|
||||
```sh
|
||||
EDCB_HOST=127.0.0.1 EDCB_PORT=4510 EDCB_TIMEOUT_SECONDS=15 cargo run --bin edcb-mcp
|
||||
```
|
||||
|
||||
CLI options take precedence over environment variables. Defaults are
|
||||
`127.0.0.1`, port `4510`, and a 15 second timeout.
|
||||
|
||||
Run `edcb-mcp --help` for clap-generated server options from the current build.
|
||||
|
||||
Exposed MCP tools:
|
||||
|
||||
- `list_services`
|
||||
- `list_reserves`
|
||||
- `get_reservation`
|
||||
- `list_recorded`
|
||||
- `get_recorded_info`
|
||||
- `list_channels`
|
||||
- `get_recording_defaults`
|
||||
- `get_recording_presets`
|
||||
- `search_programs`
|
||||
- `get_timetable`
|
||||
- `list_reservation_conditions`
|
||||
- `get_reservation_condition`
|
||||
- `create_reservation_condition`
|
||||
- `update_reservation_condition`
|
||||
- `delete_reservation_condition`
|
||||
- `preview_reservation`
|
||||
- `create_reservation`
|
||||
- `update_reservation`
|
||||
- `delete_reservation`
|
||||
- `list_tuner_reserves`
|
||||
- `list_tuner_processes`
|
||||
- `list_plugins`
|
||||
- `get_notify_status`
|
||||
|
||||
`preview_reservation` does not mutate EDCB state. `create_reservation` creates
|
||||
one reservation from an event key and the server's default reservation settings.
|
||||
Both accept an optional `options` object using KonomiTV-style recording setting
|
||||
names:
|
||||
|
||||
```json
|
||||
{
|
||||
"event": "32737:32737:1032:9285",
|
||||
"options": {
|
||||
"priority": 4,
|
||||
"recording_start_margin": 60,
|
||||
"recording_end_margin": 120
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
`update_reservation` accepts `reserve_id` and required `options`.
|
||||
`delete_reservation` fetches the reservation before deleting it and returns the
|
||||
deleted reservation data.
|
||||
|
||||
`search_programs` accepts KonomiTV-style search condition fields:
|
||||
|
||||
```json
|
||||
{
|
||||
"is_enabled": true,
|
||||
"keyword": "news",
|
||||
"exclude_keyword": "sports",
|
||||
"is_title_only": true,
|
||||
"is_case_sensitive": false,
|
||||
"is_fuzzy_search_enabled": true,
|
||||
"is_regex_search_enabled": false,
|
||||
"service_ranges": [
|
||||
{
|
||||
"network_id": 32736,
|
||||
"transport_stream_id": 32736,
|
||||
"service_id": 1024
|
||||
}
|
||||
],
|
||||
"genre_ranges": [
|
||||
{
|
||||
"major": 0,
|
||||
"middle": 1,
|
||||
"user_nibble": null
|
||||
}
|
||||
],
|
||||
"is_exclude_genre_ranges": false,
|
||||
"date_ranges": [
|
||||
{
|
||||
"start_day_of_week": 1,
|
||||
"start_hour": 19,
|
||||
"start_minute": 0,
|
||||
"end_day_of_week": 1,
|
||||
"end_hour": 23,
|
||||
"end_minute": 0
|
||||
}
|
||||
],
|
||||
"is_exclude_date_ranges": false,
|
||||
"duration_range_min": 30,
|
||||
"duration_range_max": 120,
|
||||
"broadcast_type": "FreeOnly",
|
||||
"duplicate_title_check_scope": "None",
|
||||
"duplicate_title_check_period_days": 6
|
||||
}
|
||||
```
|
||||
|
||||
`create_reservation_condition` accepts a required `condition` object with the
|
||||
same fields as `search_programs` and an optional `options` object with recording
|
||||
settings. `update_reservation_condition` accepts `condition_id`, optional
|
||||
`condition`, and optional `options`.
|
||||
|
||||
`get_timetable` accepts service/time/channel filters and returns channels with
|
||||
programs, optional nested subchannels, and best-effort reservation metadata. The
|
||||
response includes `reservation_metadata_status` so callers can distinguish "no
|
||||
matching reservation" from "reservation lookup failed":
|
||||
|
||||
```json
|
||||
{
|
||||
"start_time": "2026-06-29T19:00:00+09:00",
|
||||
"end_time": "2026-06-29T23:00:00+09:00",
|
||||
"channel_type": "GR",
|
||||
"services": [
|
||||
{
|
||||
"network_id": 32736,
|
||||
"transport_stream_id": 32736,
|
||||
"service_id": 1024
|
||||
}
|
||||
]
|
||||
}
|
||||
```
|
||||
|
||||
## Development
|
||||
|
||||
Use the Nix dev shell through direnv, then run:
|
||||
|
||||
```sh
|
||||
nix fmt
|
||||
nix build
|
||||
nix run .#edcb -- --version
|
||||
cargo test
|
||||
cargo fmt --check
|
||||
cargo clippy --all-targets -- -D warnings
|
||||
```
|
||||
@@ -0,0 +1,251 @@
|
||||
---
|
||||
source_url: https://forest.watch.impress.co.jp/docs/topic/special/2119037.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 55d912d17ac5eedb47d2515bca8c5fc6b6d36558f98aa8367193d0dfbfd72b27
|
||||
discovered_from:
|
||||
platform: 'discord'
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: 'tw'
|
||||
message_id: '1521370067432902777'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: '2026-06-30T04:21:29.765000000Z'
|
||||
message_excerpt: 'EmEditor のローカルAI対応アップデートは、個人環境でAIを閉じて回したい需要の受け皿として共有された。'
|
||||
score: 2
|
||||
---
|
||||
|
||||
提供:
|
||||
|
||||
Emurasoft, Inc.
|
||||
|
||||
2026年6月30日 13:05
|
||||
|
||||
[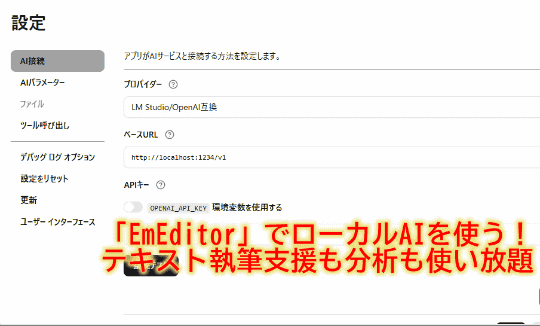](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/image-top.png.html)
|
||||
|
||||
AI使いたい放題なら遠慮は無用! 「EmEditor」でローカルAIを使えばメリットたくさん
|
||||
|
||||
「窓の杜」編集部でも愛用者が多い定番のテキストエディター [「EmEditor」](https://jp.emeditor.com/) は、最近のバージョンにて、生成AIを呼び出してテキストを扱う機能を取り入れている。
|
||||
|
||||
「EmEditor」v26.2では、このAI機能の「AIによる支援執筆」で、AIプロバイダー(AIモデルのサービス)として、「LM Studio」で動作するローカルAIモデルに対応した。そのほか、AnthropicやGoogleなどにも対応している。
|
||||
|
||||
……と書いても、「EmEditor」のAI機能を使い慣れている人でないとわかりづらいかもしれない。そこでまず「EmEditor」のAI機能について改めて紹介しよう。これは大きく分けて2系統ある。
|
||||
|
||||
1つ目は、「EmEditor」のウィンドウ内にチャットを開いてChatGPTなどのようなチャット形式でAIと対話したり、AIへのプロンプトをボタンにしておいて「EmEditor」で開いているテキストを処理したりできる機能だ。たとえば[校正][要約]などのボタンが最初から用意されている。
|
||||
|
||||
2つ目の「AIによる支援執筆」は、文章をタイピング中にAIが次に入力する内容を予測し、自動補完する機能だ。たとえば文章を書いていて、文末を「と言った」にしようか「と語った」にしようかと考えて手が止まると、AIがグレーで続きのテキストを提案してくれる。
|
||||
|
||||
なお、これらのAI機能は [「ChatAI」プラグイン](https://jp.emeditor.com/download-chatai/) に分けられており、AIを使う人は追加インストールする必要がある。
|
||||
|
||||
こうしたAI機能は、もともとAIプロバイダーとして、OpenAIのAPIを呼び出して動く方式で作られていた。そこへv25.2ではチャット系のAI機能が、OpenAI以外のAIプロバイダーを呼び出して動く方式に対応した。
|
||||
|
||||
そしてv26.2では、「AIによる支援執筆」も、OpenAI以外のAIプロバイダーに対応したわけだ。
|
||||
|
||||
そこでこの記事では、実際に「LM Studio」でAIモデルをローカルで動かして「EmEditor」v26.2から呼び出し、「AIによる支援執筆」やチャット系のAI機能を試してみる。
|
||||
|
||||
実行環境としては、以下のようなスペックのPCを用意した。
|
||||
|
||||
- **CPU** :Intel Core Ultra 7-265KF
|
||||
- **メモリ** :32GB
|
||||
- **GPU** :GeForce RTX 5070(VRAM 12.0GB)
|
||||
- **OS** :Windows 11 Pro 25H2
|
||||
|
||||
## 「LM Studio」とAIモデルをセットアップ
|
||||
|
||||
「LM Studio」は、AIモデル(LLM)を自分のPC上で実行できるデスクトップアプリケーションだ。GUIの操作で、「Hugging Face」からオープンなAIモデルをダウンロードして、それを使ったチャットを動かしたり、ほかのアプリケーションからAPIで呼び出せるようにしたりできる。
|
||||
|
||||
ローカルでAIを動かすメリットには、お金と安全性がある。
|
||||
|
||||
OpenAIなどクラウドのAPIプロバイダーを使うと、トークン単位で料金がかかる。1回あたりの料金は大きくなくても、文章を書きながらトークン節約が気になると少しストレスを感じることもある。
|
||||
|
||||
また、また、多くのプロバイダーでは、プロンプトがAIモデルの学習には使用されないという規定があるが、クラウドのAPIに、個人情報などを含んだテキストを送って処理させることについて、安全性が気になるユーザーもいるだろう。
|
||||
|
||||
ローカルでAIを動かせば、こうした心配はなくなるわけだ。そのかわり、もちろん、AIを動かすだけの性能のPCは必要になる。
|
||||
|
||||
「LM Studio」をインストールするには、 [公式サイト](https://lmstudio.ai/) からインストーラーをダウンロードして実行する。インストール時のオプションを聞かれるので、筆者は[このコンピューターを使用しているすべてのユーザー用にインストールする]を選んだ。
|
||||
|
||||
インストールが完了すると、デフォルトでは「LM Studio」の起動に進み、初期設定が実行される。初期設定の中でモデルが提案されて、ダウンロードすることもできるが、ここでは一旦スキップした。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-01.png.html)
|
||||
|
||||
「LM Studio」公式サイト
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-02.png.html)
|
||||
|
||||
インストールで[このコンピューターを使用しているすべてのユーザー用にインストールする]を選んだ
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-03.png.html)
|
||||
|
||||
初期設定が実行される
|
||||
|
||||
「LM Studio」のデフォルトではUIが英語表示だが、日本語に設定可能だ。ウィンドウ左下の歯車アイコンをクリックして設定ダイアログを表示し、[General]の中の[User Interface]の[App Language]の項で[日本語]を選べばよい。ただし、日本語化は完全ではなく、英語のままの項目も多い。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-04.png.html)
|
||||
|
||||
「LM Studio」のUIを日本語に
|
||||
|
||||
次に「LM Studio」で使うモデルを選ぼう。モデルは、チャット系のAI機能と「AIによる支援執筆」とで違う方向性で選ぶのがよいだろう。チャット系のAI機能では、自分のPCのスペックで無理なく動く中で賢いモデルがいい。一方で「AIによる支援執筆」ではレスポンス速度を重視して、思考(リーズニング)型ではない軽量なモデルのほうが適している。
|
||||
|
||||
チャット系のAI機能のために、自分のPCのGPUやメモリなどのスペックにあったモデルを選ぶには、 [「CanIRun.ai」](https://www.canirun.ai/) が便利だ。アクセスするだけで、PCスペックにあったモデルを推薦してくれる。
|
||||
|
||||
筆者が試したPCの場合、「Qwen 3.5 9B」の「Q4\_K\_M」量子化のモデルがよさそうだ。「Qwen」は日本語処理など性能に定評があり、かつ多くのモデルがオープンソースライセンスなこともあってサイズなどのバリエーションが豊富でローカルAIとして使いやすい。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-05.png.html)
|
||||
|
||||
「CanIRun.ai」でAIモデルを探す
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-06.png.html)
|
||||
|
||||
「CanIRun.ai」で各AIモデルの情報を見る
|
||||
|
||||
一方、「AIによる支援執筆」のためには、「EmEditor」公式サイトの [「\[AIとチャット\] プラグインの使い方」](https://help.emeditor.com/ja/howto/plugin/plugin_chat_with_ai.html) で名前が挙がっている「Qwen3 VL 8B」を選んだ。
|
||||
|
||||
使うモデルが決まったら、「LM Studio」でモデルをダウンロードしよう。ウィンドウ左端の[Model Search]をクリックすると、モデルを検索するダイアログが表示される。筆者の場合は「Qwen 3.5 9B」を選び、[Download Options]の項で「GGUF」版の「Q4\_K\_M」マークが付いているモデルを選んで、ダウンロードを実行した。
|
||||
|
||||
回線速度によるが、ダウンロードには少し時間がかかり、完了するとウィンドウ右下にメッセージが表示される。ここで[Load Model]をクリックして、ダウンロードしたモデルを読み込む。
|
||||
|
||||
同様にして「Qwen3 VL 8B」もダウンロードする。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-07.png.html)
|
||||
|
||||
モデルをダウンロードする
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-08.png.html)
|
||||
|
||||
ダウンロードが完了した
|
||||
|
||||
AIモデルが用意できたら、「LM Studio」上でのチャットを試してみる。ウィンドウ左端の[Chat]をクリックして、チャット画面から[New chat]をクリックする。あとはプロンプトを入力すると、回答が返ってくる。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-01-09.png.html)
|
||||
|
||||
「LM Studio」上でのチャットを試す
|
||||
|
||||
## 「EmEditor」からAIプロバイダーとして「LM Studio」を使うよう設定する
|
||||
|
||||
ではいよいよ、「EmEditor」と「LM Studio」を接続して使ってみよう。
|
||||
|
||||
なお、「EmEditor」v26.2と「ChatAI」プラグインはすでにインストールしてあるものとする。
|
||||
|
||||
### 「LM Studio」の設定
|
||||
|
||||
まず「LM Studio」の設定の[Developer]で、[Developer mode]を[ON]にする。なお、初回起動時に[Developer mode]を有効化した場合は、この設定は不要だ。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-01.png.html)
|
||||
|
||||
[Developer mode]を[ON]にする
|
||||
|
||||
続いて、ウィンドウ左端の[Developer]をクリックして[Developer]画面を表示する。そして上部の[Status: Stopped]となっているトグルスイッチをクリックして[Status: Running]になれば、APIサーバーが起動している。さらに、その右にある[Server Settings]をクリックして表示されたメニューから[CORSを有効にする]をONにしておく。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-02.png.html)
|
||||
|
||||
APIサーバーを起動
|
||||
|
||||
[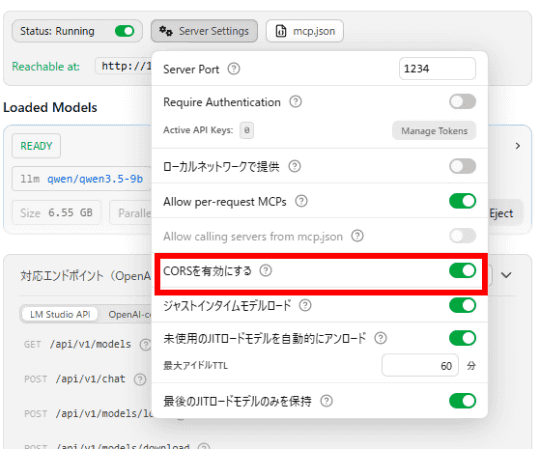](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-03.png.html)
|
||||
|
||||
CORSを有効にする
|
||||
|
||||
### 「EmEditor」の設定
|
||||
|
||||
「LM Studio」側の用意ができたら、「EmEditor」から接続して使おう。
|
||||
|
||||
「EmEditor」のメニューから、[AI]-[カスタマイズ]-[AIオプション](または[ツール]-[カスタマイズ]で開いたカスタマイズダイアログから[AIオプション])で、AIオプションの設定が表示される。ここでまず[AIを有効にする]のチェックマークを付ける。警告が表示されたら[継続する]をクリックする。
|
||||
|
||||
[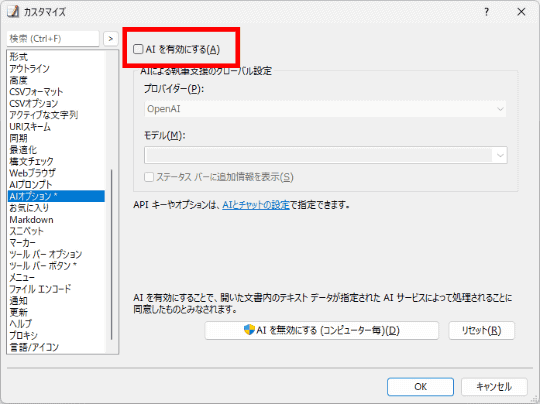](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-04.png.html)
|
||||
|
||||
AIを有効にする
|
||||
|
||||
ここで一旦[OK]をクリックしてカスタマイズダイアログを閉じ、先にチャット系のAI機能を設定する。
|
||||
|
||||
チャット系のAI機能は、[AIとチャット]パネルから設定する。メニューの[AI]-[AIとチャット]で、[AIとチャット]パネルが表示される。ここで歯車アイコンから表示されるメニューで[設定]を選ぶ。表示された設定ダイアログにて、[プロバイダー]の項で[LM Studio / OpenAI互換]を選ぶ。
|
||||
|
||||
さらに左から[APIパラメーター]をクリックし、[モデル]で自分の使うモデルを選択する。
|
||||
|
||||
[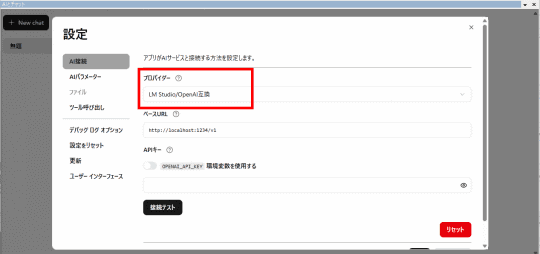](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-05.png.html)
|
||||
|
||||
AIプロバイダーで[LM Studio / OpenAI互換]を選ぶ
|
||||
|
||||
[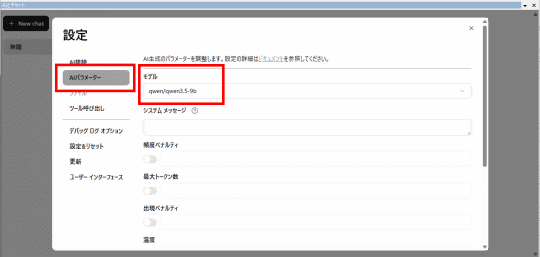](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-06.png.html)
|
||||
|
||||
モデルを選ぶ
|
||||
|
||||
この設定ダイアログには[接続テスト]があるので、クリックしてみよう。[接続成功]と表示されたら、設定が成功だ。[OK]で設定ダイアログを閉じる。
|
||||
|
||||
[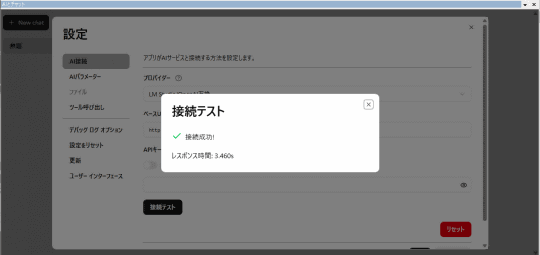](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-07.png.html)
|
||||
|
||||
接続テストが成功
|
||||
|
||||
ここで再び、AIオプションの設定に戻る。v26.1と比較すると、v26.2では[AIによる執筆支援のグローバル設定]に[プロバイダー]という項目が増えていることがわかる。ここで[LM Studio / OpenAI compatible]を選び、[モデル]の項目も選択して、[OK]でカスタマイズダイアログを閉じる。
|
||||
|
||||
[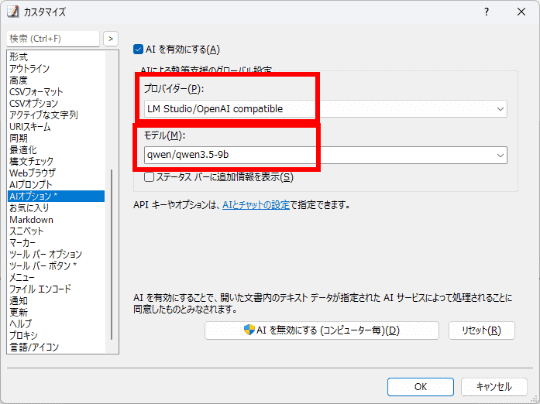](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-08.png.html)
|
||||
|
||||
AIによる執筆支援の設定で、AIプロバイダーとモデルを選ぶ
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-02-09.png.html)
|
||||
|
||||
参考:v26.1のダイアログ
|
||||
|
||||
## 入力している文章の続きをローカルAIが提案
|
||||
|
||||
設定ができたら、まず「AIによる支援執筆」機能を使ってみよう。前述のとおり、ここではモデルとして、レスポンス速度を重視して軽量な「Qwen3 VL 8B」を使うことにする。
|
||||
|
||||
[AIを有効にする]を有効にしてあれば、Textファイルでは「AIによる支援執筆」機能がデフォルトでONになっている。
|
||||
|
||||
そこでTextファイルでテキストを入力して途中で手を止めると、入力したテキストの後に、提案されるテキストが灰色で表示される。OpenAIのAPIを指定したときと同じだ。
|
||||
|
||||
提案されるテキストが表示された状態で、[Tab]または[End]キーを押すと、全部確定する。また、[→]キーで1文字ずつ確定、[Ctrl]+[→]で1単語確定となる。ほかの候補を表示するには[Ctrl]+[Space]キーを押す。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-03-01b.png.html)
|
||||
|
||||
AIによる支援執筆を試す
|
||||
|
||||
もともとタイピングが止まったときに働く機能ということもあり、ローカルのAIだからといって、特にレスポンスの遅さは感じなかった。「LM Studio」の[Developer]画面を見ているとけっこう小まめにレスポンスが送信されていることがわかるが、Windowsのタスクマネージャーを見ても、それほどGPUやCPUに大きな負荷がかかっているということはなさそうだ。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-03-02.png.html)
|
||||
|
||||
AIによる支援執筆を使っているときのGPUやCPUの動作状況
|
||||
|
||||
なお、このテストのあと、「Qwen 3.5 9B」でもテストしたが、体感的なレスポンスにはあまり差がなかった。環境によるものもあると思うが、このあたりは色々テストしてみるのもいいかもしれない。
|
||||
|
||||
## 大きなCSVファイルをローカルAIで分析
|
||||
|
||||
続いて、個人情報や機密情報を「EmEditor」で開き、チャット系AI機能でローカルAIを使って処理する例を試してみよう。こちらの機能では「Qwen 3.5 9B」を使った。
|
||||
|
||||
ここでは、架空のフィットネスジムの入退室記録を4,500件ほど用意して(ちなみにこのデータはChatGPTで作成した)、AIに会員ランクごとの利用時間の傾向を分析させてみる。けっこう大きなデータで手のこんだ分析をするが、ローカルAIなので利用料金はかからない。もちろん、データをクラウドに送信することはないので、機密情報でも安心だ。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-04-01.png.html)
|
||||
|
||||
分析対象のCSVファイルを「EmEditor」で開く
|
||||
|
||||
「EmEditor」で開いている内容をAIチャットから直接扱うためには、「EmEditor」の[AIとチャット]にある、AIから「EmEditor」の機能を呼び出す[ツール呼び出し]機能を使うので、有効にしておく。
|
||||
|
||||
[AIとチャット]パネルの歯車アイコンから[設定]を選んで設定ダイアログを開き、左列から[ツール呼び出し]を選んで、[ツール呼び出しを有効にする]をONにする。『現在選択されているプロバイダーではツール呼び出しはサポートされていません』とメッセージが表示されるが、とりあえず気にせず続ける。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-04-02.png.html)
|
||||
|
||||
[ツール呼び出し]機能を有効にする。サポートされていないとメッセージが表示されているが、ここではそのまま続ける
|
||||
|
||||
そして[AIとチャット]パネルのプロンプト入力エリアで、分析を依頼するプロンプトを入力する。すると、AIがいろいろ考えたあと、分析結果を表示した。
|
||||
|
||||
結果を見ると、会員ランクごとの行動パターン分析のほか、全体的な利用スタイルの分析、さらには推奨施策まで考えてくれていた。思っていた以上に本格的なレポートが得られた。
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-04-03.png.html)
|
||||
|
||||
分析を依頼するプロンプトを入力
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-04-04.png.html)
|
||||
|
||||
分析結果(1)
|
||||
|
||||
[](https://forest.watch.impress.co.jp/img/wf/docs/2119/037/html/emeditor-localai-04-05.png.html)
|
||||
|
||||
分析結果(2)
|
||||
|
||||
## ローカルAIとクラウドAIをケースによって使い分けられる
|
||||
|
||||
以上、「EmEditor」でAIプロバイダーとして、PC上のローカルAIである「LM Studio」を使う例を見てきた。
|
||||
|
||||
ローカルAIを使えば、料金や秘密を気にすることなく、AIを使える。意外とサクサク動くし、能力的にも思っていた以上のことをやってくれた。
|
||||
|
||||
とはいえ、PC上で動かすAIは、どうしてもモデルの大きさや機能などに限界がある。また、「EmEditor」から使えるAI機能も、開発が順次進んでいるとはいえ、クラウドAIに比べてローカルAIは若干未対応のものがある。
|
||||
|
||||
ローカルAIが使えるからといって、なにもローカルAIだけを使う必要はない。「EmEditor」ではAIプロバイダーを切り替えて使える。そのため、ローカルAIとクラウドAIをケースによって使い分けるのがいいだろう。
|
||||
|
||||
こうした [「EmEditor」](https://jp.emeditor.com/) の全機能は、「EmEditor Professional」のライセンスを購入することで、フルに使える。AI連携のほかにも、強力なCSVツールや、巨大ファイルのサポート、各種プラグインなど、Professionalには豊富な機能が備わっている。まずは「EmEditor Free」で基本機能を使ってみて、そこで気に入って高度な機能を使ってみたくなった人は、ライセンスを購入するといいだろう。
|
||||
@@ -0,0 +1,57 @@
|
||||
---
|
||||
source_url: "https://github.blog/changelog/2026-06-26-github-desktop-3-6-worktrees-and-deeper-copilot-integration/"
|
||||
ingested: 2026-06-30
|
||||
sha256: 46756b1456efba876ab7ea13b75f2ef8cec948b0923285b7089a118bf29a13fd
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521475790607224992"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T11:21:36.134000000Z"
|
||||
message_excerpt: "#tw digest highlighted GitHub Desktop worktree support as useful for AI-assisted multi-branch work."
|
||||
score: 3
|
||||
---
|
||||
[Back to changelog](https://github.blog/changelog/)
|
||||
|
||||

|
||||
|
||||
GitHub Desktop 3.6 brings more of your day-to-day Git flow into one place with GitHub Copilot now powering commit authoring and merge conflict resolution, plus new Git worktree support.
|
||||
|
||||
### The problem
|
||||
|
||||
More and more development happens with the help of AI and coding agents, which raises the bar for the everyday Git moments in between. A few of those moments still pull you away from your flow: commit authoring needs more control and better alignment with repository standards, merge conflicts remain one of the most intimidating Git workflows, and working across multiple branches at once often means stashing changes, switching branches repeatedly, or creating extra clones.
|
||||
|
||||
### A new foundation for Copilot
|
||||
|
||||
Copilot in GitHub Desktop now runs on the [Copilot SDK](https://github.com/github/copilot-sdk), the shared foundation behind both the enhanced commit message experience and the new merge conflict workflow.
|
||||
|
||||
Beyond those features, the SDK also unlocks more flexibility in how Copilot runs. Every Copilot feature in GitHub Desktop now includes a model picker so you can choose from the models available to you through GitHub. You can also use bring your own key (BYOK) to connect a third-party provider or a model running locally on your machine.
|
||||
|
||||
### Author commits with more control
|
||||
|
||||
GitHub Desktop’s commit message generation feature is now more powerful and customizable. It picks up custom instructions from your `.github/copilot-instructions.md` and `AGENTS.md` files, and honors [commit metadata rules](https://docs.github.com/repositories/configuring-branches-and-merges-in-your-repository/managing-rulesets/creating-rulesets-for-a-repository#adding-metadata-restrictions) defined for your repository. This way generated messages match your style and stay within your repository’s standards.
|
||||
|
||||

|
||||
|
||||

|
||||
|
||||
### Resolve conflicts with Copilot
|
||||
|
||||
Merge conflicts are now easier to navigate with AI-assisted resolution in GitHub Desktop. When you hit a conflict, Desktop can help explain the conflicting changes and suggest a resolution that you can review, accept, or edit before completing the merge.
|
||||
|
||||
<video controls="" width="100%" src="https://github.com/user-attachments/assets/4be1b011-599b-450d-a0ed-c76209234872"></video>
|
||||
|
||||
### Work across branches in parallel
|
||||
|
||||
GitHub Desktop now supports [Git worktrees](https://github.blog/ai-and-ml/github-copilot/what-are-git-worktrees-and-why-should-i-use-them/), so you can work across multiple branches at once without repeatedly stashing changes, switching branches, or cloning the same repository. This is especially handy alongside coding agents, which often spin up worktrees to run isolated, parallel sessions.
|
||||
|
||||

|
||||
|
||||
### Getting started
|
||||
|
||||
is available now for macOS and Windows. GitHub Desktop is free to download and use, and Copilot-powered features require access to GitHub Copilot.
|
||||
|
||||
Automatic updates roll out progressively, or you can download the latest release from [github.com/apps/desktop](https://github.com/apps/desktop). To learn more about these workflows, see the [GitHub Desktop documentation](https://docs.github.com/desktop).
|
||||
|
||||
Have feedback or found an issue? [Open an issue in the desktop/desktop repository](https://github.com/desktop/desktop/issues/new/choose).
|
||||
@@ -0,0 +1,739 @@
|
||||
---
|
||||
source_url: https://github.blog/engineering/issueops-automate-ci-cd-and-more-with-github-issues-and-actions/
|
||||
ingested: 2026-06-29
|
||||
sha256: 2e8329f5ebe11bb7a961f81315c292b4435e21aa07d6bb6898e1a94989159360
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1028287639918497822'
|
||||
channel_name: "chat"
|
||||
message_id: '1520785437768159414'
|
||||
author_id: '890908900520505354'
|
||||
posted_at: 2026-06-28T13:38:23.191000000Z
|
||||
message_excerpt: "<@1394873980376322108> tldr https://github.blog/engineering/issueops-automate-ci-cd-and-more-with-github-issues-and-actions/"
|
||||
---
|
||||
|
||||
Software development is filled with repetitive tasks—managing issues, handling approvals, triggering CI/CD workflows, and more. But what if you could automate these types of tasks directly within GitHub Issues? That’s the promise of **IssueOps**, a methodology that turns GitHub Issues into a command center for automation.
|
||||
|
||||
Whether you’re a solo developer or part of an engineering team, IssueOps helps you streamline operations without ever leaving your repository.
|
||||
|
||||
In this article, I’ll explore the concept of IssueOps using state-machine terminology and strategies to help you work more efficiently on GitHub. After all, who doesn’t love automation?
|
||||
|
||||
## What is IssueOps?
|
||||
|
||||
IssueOps is the practice of using GitHub Issues, GitHub Actions, and pull requests (PR) as an interface for automating workflows. Instead of switching between tools or manually triggering actions, you can use issue comments, labels, and state changes to kick off CI/CD pipelines, assign tasks, and even deploy applications.
|
||||
|
||||
Much like the various other *\*Ops* paradigms ([ChatOps](https://github.blog/engineering/infrastructure/using-chatops-to-help-actions-on-call-engineers/), ClickOps, and so on), IssueOps is a collection of tools, workflows, and concepts that, when applied to [GitHub Issues](https://github.com/features/issues), can automate mundane, repetitive tasks. The flexibility and power of issues, along with their relationship to pull requests, create a near limitless number of possibilities, such as managing approvals and deployments. All of this can really help to simplify your workflows on GitHub. I’m speaking from personal experience here.
|
||||
|
||||
It’s important to note that IssueOps isn’t just a DevOps thing! Where DevOps offers a methodology to bring developers and operations into closer alignment, IssueOps is a workflow automation practice centered around GitHub Issues. IssueOps lets you run anything from [complex CI/CD pipelines](https://github.blog/engineering/engineering-principles/enabling-branch-deployments-through-issueops-with-github-actions/) to a [bed and breakfast reservation system](https://github.com/issue-ops/bear-creek-honey-farm). If you can interact with it via an API, there’s a good chance you can build it with IssueOps!
|
||||
|
||||
## So, why use IssueOps?
|
||||
|
||||
There are lots of benefits to utilizing IssueOps. Here’s how it’s useful in practice:
|
||||
|
||||
- **It’s event driven, so you can automate the boring stuff:** IssueOps lets you automate workflows directly from GitHub Issues and pull requests, turning everyday interactions—from kicking off a CI/CD pipeline and managing approvals to updating project boards—into powerful triggers for GitHub Actions.
|
||||
- **It’s customizable, so you can tailor workflows to your needs:** No two teams work the same way, and IssueOps is flexible enough to adapt. Whether you’re automating bug triage or triggering deployments, you can customize workflows based on event type and data provided.
|
||||
- **It’s transparent, so you can keep a record:** All actions taken on an issue are logged in its timeline, creating an easy-to-follow record of what happened and when.
|
||||
- **It’s immutable, so you can audit whenever you need:** Because IssueOps uses GitHub Issues and pull requests as a source of truth, every action leaves a record. No more chasing approvals in Slack or manually triggering workflows: IssueOps keeps everything structured, automated, and auditable right inside GitHub.
|
||||
|
||||
## Defining IssueOps workflows and how they’re like finite-state machines
|
||||
|
||||
Most IssueOps workflows follow the same basic pattern:
|
||||
|
||||
1. A user opens an issue and provides information about a request
|
||||
2. The issue is validated to ensure it contains the required information
|
||||
3. The issue is submitted for processing
|
||||
4. Approval is requested from an authorized user or team
|
||||
5. The request is processed and the issue is closed
|
||||
|
||||
Suppose you’re an administrator of an organization and want to reduce the overhead of managing team members. In this instance, you could use IssueOps to build an automated membership request and approval process. Within a workflow like this, you’d have several core steps:
|
||||
|
||||
1. A user creates a request to be added to a team
|
||||
2. The request is validated
|
||||
3. The request is submitted for approval
|
||||
4. An administrator approves or denies this request
|
||||
5. The request is processed
|
||||
1. If *approved*, the user is added to the team
|
||||
2. If *denied*, the user is not added to the team
|
||||
6. The user is notified of the outcome
|
||||
|
||||
When designing your own IssueOps workflows, it can be very helpful to think of them as a [finite-state machine](https://web.stanford.edu/class/cs123/lectures/CS123_lec07_Finite_State_Machine.pdf): a model for how objects move through a series of states in response to external events. Depending on certain rules defined within the state machine, a number of different actions can take place in response to state changes. If this is a little too complex, you can also think of it like a flow chart.
|
||||
|
||||
To apply this comparison to IssueOps, an issue is the *object* that is processed by a state machine. It changes *state* in response to *events*. As the object changes state, certain *actions* may be performed as part of a *transition*, provided any required conditions (*guards*) are met. Once an *end state* is reached, the issue can be closed.
|
||||
|
||||
This breaks down into a few key concepts:
|
||||
|
||||
- **State**: A point in an object’s lifecycle that satisfies certain condition(s).
|
||||
- **Event**: An external occurrence that triggers a state change.
|
||||
- **Transition**: A link between two states that, when traversed by an object, will cause certain action(s) to be performed.
|
||||
- **Action**: An atomic task that is performed when a transition is taken.
|
||||
- **Guard**: A condition that is evaluated when a trigger event occurs. A transition is taken only if all associated guard condition(s) are met.
|
||||
|
||||
Here’s a simple state diagram for the example I discussed above.
|
||||
|
||||
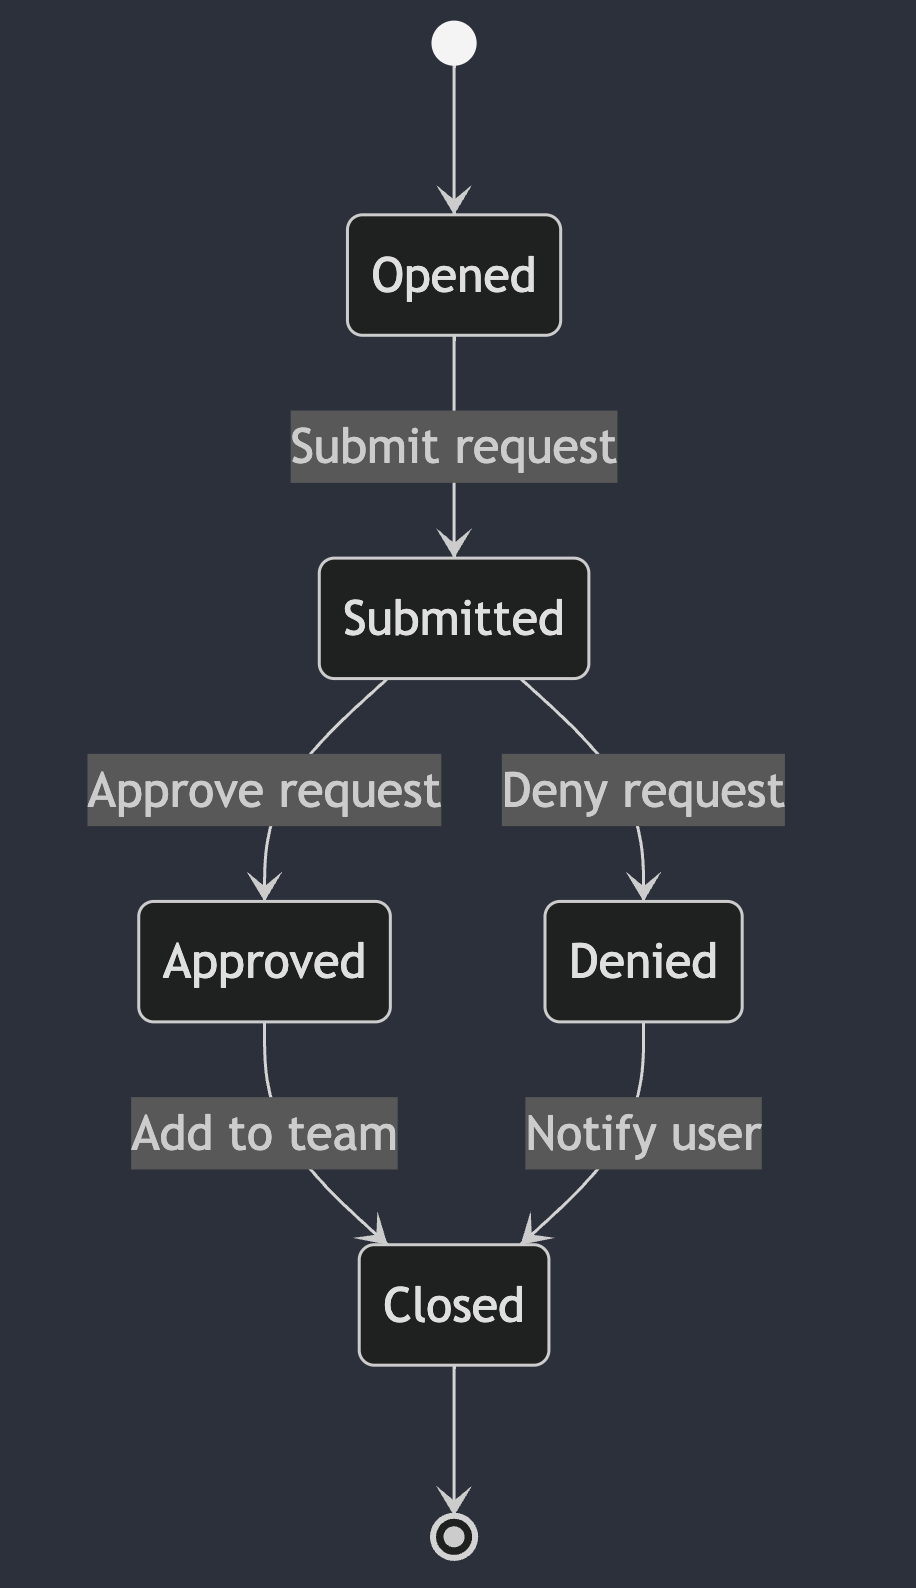
|
||||
|
||||
Now, let’s dive into the state machine in more detail!
|
||||
|
||||
## Key concepts behind state machines
|
||||
|
||||
The benefit of breaking your workflow down into these components is that you can look for edge cases, enforce conditions, and create a robust, reliable result.
|
||||
|
||||
### States
|
||||
|
||||
Within a state machine, a *state* defines the current status of an object. As the object transitions through the state machine, it will change states in response to external events. When building IssueOps workflows, common states for issues include opened, submitted, approved, denied, and closed.
|
||||
|
||||
These should suffice as the core states to consider when building our workflows in our team membership example above.
|
||||
|
||||
### Events
|
||||
|
||||
In a state machine, an *event* can be any form of interaction with the object and its current state. When building your own IssueOps, you should consider events from both the user and GitHub points of view.
|
||||
|
||||
In our team membership request example, there are several events that can trigger a change in state. The request can be created, submitted, approved, denied, or processed.
|
||||
|
||||
In this example, a user interacting with an issue—such as adding labels, commenting, or updating milestones—can also change its state. In GitHub Actions, there are many events that can trigger your workflows (see [events that trigger workflows](https://docs.github.com/en/actions/writing-workflows/choosing-when-your-workflow-runs/events-that-trigger-workflows)).
|
||||
|
||||
Here are a few interactions, or events, that would affect our example IssueOps workflow when it comes to managing team members:
|
||||
|
||||
| **Request** | **Event** | **State** |
|
||||
| --- | --- | --- |
|
||||
| Request is created | `issues` | `opened` |
|
||||
| Request is approved | `issue_comment` | `created` |
|
||||
| Request is denied | `issue_comment` | `created` |
|
||||
|
||||
As you can see, the same GitHub workflow trigger can apply to multiple events in our state machine. Because of this, validation is key. Within your workflows, you should check both the type of event and the information provided by the user. In this case, we can conditionally trigger different workflow steps based on the content of the `issue_comment` event.
|
||||
|
||||
```
|
||||
jobs:
|
||||
approve:
|
||||
name: Process Approval
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
if: ${{ startsWith(github.event.comment.body, '.approve') }}
|
||||
|
||||
# ...
|
||||
|
||||
deny:
|
||||
name: Process Denial
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
if: ${{ startsWith(github.event.comment.body, '.deny') }}
|
||||
|
||||
# ...
|
||||
```
|
||||
|
||||
### Transitions
|
||||
|
||||
A *transition* is simply the change from one state to another. In our example, for instance, a transition occurs when someone opens an issue. When a request meets certain conditions, or guards, the change in state can take place. When the transition occurs, some actions or processing may take place, as well.
|
||||
|
||||
With our example workflow, you can think of the transitions themselves as the lines connecting different nodes in the state diagram. Or the lines connecting boxes in a flow chart.
|
||||
|
||||
### Guards
|
||||
|
||||
*Guards* are conditions that must be verified before an event can trigger a transition to a different state. In our case, we know the following guards must be in place:
|
||||
|
||||
- A request should not transition to an Approved state unless an administrator comments `.approve` on the issue.
|
||||
- A request should not transition to a Denied state unless an administrator comments `.deny` on the issue.
|
||||
|
||||
What about after the request is approved and the user is added to the team? This is referred to as an *unguarded transition*. There are no conditions that must be met, so the transition happens immediately!
|
||||
|
||||
### Actions
|
||||
|
||||
Lastly, *actions* are specific tasks that are performed during a transition. They may affect the object itself, but this is not a requirement in our state machine. In our example, the following actions may take place at different times:
|
||||
|
||||
- Administrators are notified that a request has been submitted
|
||||
- The user is added to the requested team
|
||||
- The user is notified of the outcome
|
||||
|
||||
## A real-world example: Building a team membership workflow with IssueOps
|
||||
|
||||
Now that all of the explanation is out of the way, let’s dive into building our example! For reference, we’ll focus on the GitHub Actions workflows involved in building this automation. There are some additional repository and permissions settings involved that are discussed in more detail [in these IssueOps docs](https://issue-ops.github.io/docs/setup).
|
||||
|
||||
### Step 1: Issue form template
|
||||
|
||||
[GitHub issue forms](https://docs.github.com/en/communities/using-templates-to-encourage-useful-issues-and-pull-requests/syntax-for-issue-forms) let you create standardized, formatted issues based on a set of form fields. Combined with the [issue-ops/parser](https://github.com/issue-ops/parser) action, you can get reliable, machine-readable JSON from issue body Markdown. For our example, we are going to create a simple form that accepts a single input: the team where we want to add the user.
|
||||
|
||||
```
|
||||
name: Team Membership Request
|
||||
description: Submit a new membership request
|
||||
title: New Team Membership Request
|
||||
labels:
|
||||
- team-membership
|
||||
body:
|
||||
- type: input
|
||||
id: team
|
||||
attributes:
|
||||
label: Team Name
|
||||
description: The team name you would like to join
|
||||
placeholder: my-team
|
||||
validations:
|
||||
required: true
|
||||
```
|
||||
|
||||
When issues are created using this form, they will be parsed into JSON, which can then be passed to the rest of the IssueOps workflow.
|
||||
|
||||
```
|
||||
{
|
||||
"team": "my-team"
|
||||
}
|
||||
```
|
||||
|
||||
### Step 2: Issue validation
|
||||
|
||||
With a machine-readable issue body, we can run additional validation checks to ensure the information provided follows any rules we might have in place. For example, we can’t automatically add a user to a team if the team doesn’t exist yet! That is where the [issue-ops/validator](https://github.com/issue-ops/validator) action comes into play. Using an issue form template and a custom validation script, we can confirm the existence of the team ahead of time.
|
||||
|
||||
```javascript
|
||||
module.exports = async (field) => {
|
||||
const { Octokit } = require('@octokit/rest')
|
||||
const core = require('@actions/core')
|
||||
|
||||
const github = new Octokit({
|
||||
auth: core.getInput('github-token', { required: true })
|
||||
})
|
||||
|
||||
try {
|
||||
// Check if the team exists
|
||||
core.info(\`Checking if team '${field}' exists\`)
|
||||
|
||||
await github.rest.teams.getByName({
|
||||
org: process.env.GITHUB_REPOSITORY_OWNER ?? '',
|
||||
team_slug: field
|
||||
})
|
||||
|
||||
core.info(\`Team '${field}' exists\`)
|
||||
return 'success'
|
||||
} catch (error) {
|
||||
if (error.status === 404) {
|
||||
// If the team does not exist, return an error message
|
||||
core.error(\`Team '${field}' does not exist\`)
|
||||
return \`Team '${field}' does not exist\`
|
||||
} else {
|
||||
// Otherwise, something else went wrong...
|
||||
throw error
|
||||
}
|
||||
}
|
||||
}
|
||||
```
|
||||
|
||||
When included in our IssueOps workflow, this adds any validation error(s) to the comment on the issue.
|
||||
|
||||
### Step 3: Issue workflows
|
||||
|
||||
The main “entrypoint” of this workflow occurs when a user creates or edits their team membership request issue. This workflow should focus heavily on validating any user inputs! For example, what should happen if the user inputs a team that does not exist?
|
||||
|
||||
In our state machine, this workflow is responsible for handling everything up to the *opened* state. Any time an issue is created, edited, or updated, it will re-run validation to ensure the request is ready to be processed. In this case, an additional guard condition is introduced. Before the request can be submitted, the user must comment with `.submit` after validation has passed.
|
||||
|
||||
```
|
||||
name: Process Issue Open/Edit
|
||||
|
||||
on:
|
||||
issues:
|
||||
types:
|
||||
- opened
|
||||
- edited
|
||||
- reopened
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
validate:
|
||||
name: Validate Request
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
# This job should only be run on issues with the \`team-membership\` label.
|
||||
if: ${{ contains(github.event.issue.labels.*.name, 'team-membership') }}
|
||||
|
||||
steps:
|
||||
# This is required to ensure the issue form template and any validation
|
||||
# scripts are included in the workspace.
|
||||
- name: Checkout
|
||||
id: checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
# Since this workflow includes custom validation scripts, we need to
|
||||
# install Node.js and any dependencies.
|
||||
- name: Setup Node.js
|
||||
id: setup-node
|
||||
uses: actions/setup-node@v4
|
||||
|
||||
# Install dependencies from \`package.json\`.
|
||||
- name: Install Dependencies
|
||||
id: install
|
||||
run: npm install
|
||||
|
||||
# GitHub App authentication is required if you want to interact with any
|
||||
# resources outside the scope of the repository this workflow runs in.
|
||||
- name: Get GitHub App Token
|
||||
id: token
|
||||
uses: actions/create-github-app-token@v1
|
||||
with:
|
||||
app-id: ${{ vars.ISSUEOPS_APP_ID }}
|
||||
private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
|
||||
owner: ${{ github.repository_owner }}
|
||||
|
||||
# Remove any labels and start fresh. This is important because the
|
||||
# issue may have been closed and reopened.
|
||||
- name: Remove Labels
|
||||
id: remove-label
|
||||
uses: issue-ops/labeler@v2
|
||||
with:
|
||||
action: remove
|
||||
github_token: ${{ steps.token.outputs.token }}
|
||||
labels: |
|
||||
validated
|
||||
approved
|
||||
denied
|
||||
issue_number: ${{ github.event.issue.number }}
|
||||
repository: ${{ github.repository }}
|
||||
|
||||
# Parse the issue body into machine-readable JSON, so that it can be
|
||||
# processed by the rest of the workflow.
|
||||
- name: Parse Issue Body
|
||||
id: parse
|
||||
uses: issue-ops/parser@v4
|
||||
with:
|
||||
body: ${{ github.event.issue.body }}
|
||||
issue-form-template: team-membership.yml
|
||||
workspace: ${{ github.workspace }}
|
||||
|
||||
# Validate early and often! Validation should be run any time an issue is
|
||||
# interacted with, to ensure that any changes to the issue body are valid.
|
||||
- name: Validate Request
|
||||
id: validate
|
||||
uses: issue-ops/validator@v3
|
||||
with:
|
||||
add-comment: true
|
||||
github-token: ${{ steps.token.outputs.token }}
|
||||
issue-form-template: team-membership.yml
|
||||
issue-number: ${{ github.event.issue.number }}
|
||||
parsed-issue-body: ${{ steps.parse.outputs.json }}
|
||||
workspace: ${{ github.workspace }}
|
||||
|
||||
# If validation passes, add the validated label to the issue.
|
||||
- if: ${{ steps.validate.outputs.result == 'success' }}
|
||||
name: Add Validated Label
|
||||
id: add-label
|
||||
uses: issue-ops/labeler@v2
|
||||
with:
|
||||
action: add
|
||||
github_token: ${{ steps.token.outputs.token }}
|
||||
labels: |
|
||||
validated
|
||||
issue_number: ${{ github.event.issue.number }}
|
||||
repository: ${{ github.repository }}
|
||||
|
||||
# The \`issue-ops/validator\` action will automatically notify the user that
|
||||
# the request was validated. However, you can optionally add instruction
|
||||
# on what to do next.
|
||||
- if: ${{ steps.validate.outputs.result == 'success' }}
|
||||
name: Notify User (Success)
|
||||
id: notify-success
|
||||
uses: peter-evans/create-or-update-comment@v4
|
||||
with:
|
||||
issue-number: ${{ github.event.issue.number }}
|
||||
body: |
|
||||
Hello! Your request has been validated successfully!
|
||||
|
||||
Please comment with \`.submit\` to submit this request.
|
||||
```
|
||||
|
||||
### Step 4: Issue comment workflows
|
||||
|
||||
Once the issue is created, any further processing is triggered using issue comments—and this can be done with one workflow. However, to make things a bit easier to follow, we’ll break this into a few separate workflows.
|
||||
|
||||
#### Submit workflow
|
||||
|
||||
The first workflow handles the user submitting the request. The main task it performs is validating the issue body against the form template to ensure it hasn’t been modified.
|
||||
|
||||
```
|
||||
name: Process Submit Comment
|
||||
|
||||
on:
|
||||
issue_comment:
|
||||
types:
|
||||
- created
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
submit:
|
||||
name: Submit Request
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
# This job should only be run when the following conditions are true:
|
||||
#
|
||||
# - A user comments \`.submit\` on the issue.
|
||||
# - The issue has the \`team-membership\` label.
|
||||
# - The issue has the \`validated\` label.
|
||||
# - The issue does not have the \`approved\` or \`denied\` labels.
|
||||
# - The issue is open.
|
||||
if: |
|
||||
startsWith(github.event.comment.body, '.submit') &&
|
||||
contains(github.event.issue.labels.*.name, 'team-membership') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'approved') == false &&
|
||||
contains(github.event.issue.labels.*.name, 'denied') == false &&
|
||||
github.event.issue.state == 'open'
|
||||
|
||||
steps:
|
||||
# First, we are going to re-run validation. This is important because
|
||||
# the issue body may have changed since the last time it was validated.
|
||||
|
||||
# This is required to ensure the issue form template and any validation
|
||||
# scripts are included in the workspace.
|
||||
- name: Checkout
|
||||
id: checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
# Since this workflow includes custom validation scripts, we need to
|
||||
# install Node.js and any dependencies.
|
||||
- name: Setup Node.js
|
||||
id: setup-node
|
||||
uses: actions/setup-node@v4
|
||||
|
||||
# Install dependencies from \`package.json\`.
|
||||
- name: Install Dependencies
|
||||
id: install
|
||||
run: npm install
|
||||
|
||||
# GitHub App authentication is required if you want to interact with any
|
||||
# resources outside the scope of the repository this workflow runs in.
|
||||
- name: Get GitHub App Token
|
||||
id: token
|
||||
uses: actions/create-github-app-token@v1
|
||||
with:
|
||||
app-id: ${{ vars.ISSUEOPS_APP_ID }}
|
||||
private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
|
||||
owner: ${{ github.repository_owner }}
|
||||
|
||||
# Remove the validated label. This will be re-added if validation passes.
|
||||
- name: Remove Validated Label
|
||||
id: remove-label
|
||||
uses: issue-ops/labeler@v2
|
||||
with:
|
||||
action: remove
|
||||
github_token: ${{ steps.token.outputs.token }}
|
||||
labels: |
|
||||
validated
|
||||
issue_number: ${{ github.event.issue.number }}
|
||||
repository: ${{ github.repository }}
|
||||
|
||||
# Parse the issue body into machine-readable JSON, so that it can be
|
||||
# processed by the rest of the workflow.
|
||||
- name: Parse Issue Body
|
||||
id: parse
|
||||
uses: issue-ops/parser@v4
|
||||
with:
|
||||
body: ${{ github.event.issue.body }}
|
||||
issue-form-template: team-membership.yml
|
||||
workspace: ${{ github.workspace }}
|
||||
|
||||
# Validate early and often! Validation should be run any time an issue is
|
||||
# interacted with, to ensure that any changes to the issue body are valid.
|
||||
- name: Validate Request
|
||||
id: validate
|
||||
uses: issue-ops/validator@v3
|
||||
with:
|
||||
add-comment: false # Don't add another validation comment.
|
||||
github-token: ${{ steps.token.outputs.token }}
|
||||
issue-form-template: team-membership.yml
|
||||
issue-number: ${{ github.event.issue.number }}
|
||||
parsed-issue-body: ${{ steps.parse.outputs.json }}
|
||||
workspace: ${{ github.workspace }}
|
||||
|
||||
# If validation passed, add the validated and submitted labels to the issue.
|
||||
- if: ${{ steps.validate.outputs.result == 'success' }}
|
||||
name: Add Validated Label
|
||||
id: add-label
|
||||
uses: issue-ops/labeler@v2
|
||||
with:
|
||||
action: add
|
||||
github_token: ${{ steps.token.outputs.token }}
|
||||
labels: |
|
||||
validated
|
||||
submitted
|
||||
issue_number: ${{ github.event.issue.number }}
|
||||
repository: ${{ github.repository }}
|
||||
|
||||
# If validation succeeded, alert the administrator team so they can
|
||||
# approve or deny the request.
|
||||
- if: ${{ steps.validate.outputs.result == 'success' }}
|
||||
name: Notify Admin (Success)
|
||||
id: notify-success
|
||||
uses: peter-evans/create-or-update-comment@v4
|
||||
with:
|
||||
issue-number: ${{ github.event.issue.number }}
|
||||
body: |
|
||||
👋 @issue-ops/admins! The request has been validated and is
|
||||
ready for your review. Please comment with \`.approve\` or \`.deny\`
|
||||
to approve or deny this request.
|
||||
```
|
||||
|
||||
#### Deny workflow
|
||||
|
||||
If the request is denied, the user should be notified and the issue should close.
|
||||
|
||||
```
|
||||
name: Process Denial Comment
|
||||
|
||||
on:
|
||||
issue_comment:
|
||||
types:
|
||||
- created
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
submit:
|
||||
name: Deny Request
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
# This job should only be run when the following conditions are true:
|
||||
#
|
||||
# - A user comments \`.deny\` on the issue.
|
||||
# - The issue has the \`team-membership\` label.
|
||||
# - The issue has the \`validated\` label.
|
||||
# - The issue has the \`submitted\` label.
|
||||
# - The issue does not have the \`approved\` or \`denied\` labels.
|
||||
# - The issue is open.
|
||||
if: |
|
||||
startsWith(github.event.comment.body, '.deny') &&
|
||||
contains(github.event.issue.labels.*.name, 'team-membership') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'submitted') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'validated') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'approved') == false &&
|
||||
contains(github.event.issue.labels.*.name, 'denied') == false &&
|
||||
github.event.issue.state == 'open'
|
||||
|
||||
steps:
|
||||
# This time, we do not need to re-run validation because the request is
|
||||
# being denied. It can just be closed.
|
||||
|
||||
# However, we do need to confirm that the user who commented \`.deny\` is
|
||||
# a member of the administrator team.
|
||||
# GitHub App authentication is required if you want to interact with any
|
||||
# resources outside the scope of the repository this workflow runs in.
|
||||
- name: Get GitHub App Token
|
||||
id: token
|
||||
uses: actions/create-github-app-token@v1
|
||||
with:
|
||||
app-id: ${{ vars.ISSUEOPS_APP_ID }}
|
||||
private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
|
||||
owner: ${{ github.repository_owner }}
|
||||
|
||||
# Check if the user who commented \`.deny\` is a member of the
|
||||
# administrator team.
|
||||
- name: Check Admin Membership
|
||||
id: check-admin
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ steps.token.outputs.token }}
|
||||
script: |
|
||||
try {
|
||||
await github.rest.teams.getMembershipForUserInOrg({
|
||||
org: context.repo.owner,
|
||||
team_slug: 'admins',
|
||||
username: context.actor,
|
||||
})
|
||||
core.setOutput('member', 'true')
|
||||
} catch (error) {
|
||||
if (error.status === 404) {
|
||||
core.setOutput('member', 'false')
|
||||
}
|
||||
throw error
|
||||
}
|
||||
|
||||
# If the user is not a member of the administrator team, exit the
|
||||
# workflow.
|
||||
- if: ${{ steps.check-admin.outputs.member == 'false' }}
|
||||
name: Exit
|
||||
run: exit 0
|
||||
|
||||
# If the user is a member of the administrator team, add the denied label.
|
||||
- name: Add Denied Label
|
||||
id: add-label
|
||||
uses: issue-ops/labeler@v2
|
||||
with:
|
||||
action: add
|
||||
github_token: ${{ steps.token.outputs.token }}
|
||||
labels: |
|
||||
denied
|
||||
issue_number: ${{ github.event.issue.number }}
|
||||
repository: ${{ github.repository }}
|
||||
|
||||
# Notify the user that the request was denied.
|
||||
- name: Notify User
|
||||
id: notify
|
||||
uses: peter-evans/create-or-update-comment@v4
|
||||
with:
|
||||
issue-number: ${{ github.event.issue.number }}
|
||||
body: |
|
||||
This request has been denied and will be closed.
|
||||
|
||||
# Close the issue as not planned.
|
||||
- name: Close Issue
|
||||
id: close
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
script: |
|
||||
await github.rest.issues.update({
|
||||
issue_number: ${{ github.event.issue.number }},
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
state: 'closed',
|
||||
state_reason: 'not_planned'
|
||||
})
|
||||
```
|
||||
|
||||
#### Approve workflow
|
||||
|
||||
Finally, we need to handle request approval. In this case, we need to add the user to the team, notify them, and close the issue.
|
||||
|
||||
```
|
||||
name: Process Approval Comment
|
||||
|
||||
on:
|
||||
issue_comment:
|
||||
types:
|
||||
- created
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
issues: write
|
||||
|
||||
jobs:
|
||||
submit:
|
||||
name: Approve Request
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
# This job should only be run when the following conditions are true:
|
||||
#
|
||||
# - A user comments \`.approve\` on the issue.
|
||||
# - The issue has the \`team-membership\` label.
|
||||
# - The issue has the \`validated\` label.
|
||||
# - The issue has the \`submitted\` label.
|
||||
# - The issue does not have the \`approved\` or \`denied\` labels.
|
||||
# - The issue is open.
|
||||
if: |
|
||||
startsWith(github.event.comment.body, '.approve') &&
|
||||
contains(github.event.issue.labels.*.name, 'team-membership') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'submitted') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'validated') == true &&
|
||||
contains(github.event.issue.labels.*.name, 'approved') == false &&
|
||||
contains(github.event.issue.labels.*.name, 'denied') == false &&
|
||||
github.event.issue.state == 'open'
|
||||
|
||||
steps:
|
||||
# This time, we do not need to re-run validation because the request is
|
||||
# being approved. It can just be processed.
|
||||
|
||||
# This is required to ensure the issue form template is included in the
|
||||
# workspace.
|
||||
- name: Checkout
|
||||
id: checkout
|
||||
uses: actions/checkout@v4
|
||||
|
||||
# We do need to confirm that the user who commented \`.approve\` is a member
|
||||
# of the administrator team. GitHub App authentication is required if you
|
||||
# want to interact with any resources outside the scope of the repository
|
||||
# this workflow runs in.
|
||||
- name: Get GitHub App Token
|
||||
id: token
|
||||
uses: actions/create-github-app-token@v1
|
||||
with:
|
||||
app-id: ${{ vars.ISSUEOPS_APP_ID }}
|
||||
private-key: ${{ secrets.ISSUEOPS_APP_PRIVATE_KEY }}
|
||||
owner: ${{ github.repository_owner }}
|
||||
|
||||
# Check if the user who commented \`.approve\` is a member of the
|
||||
# administrator team.
|
||||
- name: Check Admin Membership
|
||||
id: check-admin
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ steps.token.outputs.token }}
|
||||
script: |
|
||||
try {
|
||||
await github.rest.teams.getMembershipForUserInOrg({
|
||||
org: context.repo.owner,
|
||||
team_slug: 'admins',
|
||||
username: context.actor,
|
||||
})
|
||||
core.setOutput('member', 'true')
|
||||
} catch (error) {
|
||||
if (error.status === 404) {
|
||||
core.setOutput('member', 'false')
|
||||
}
|
||||
throw error
|
||||
}
|
||||
|
||||
# If the user is not a member of the administrator team, exit the
|
||||
# workflow.
|
||||
- if: ${{ steps.check-admin.outputs.member == 'false' }}
|
||||
name: Exit
|
||||
run: exit 0
|
||||
|
||||
# Parse the issue body into machine-readable JSON, so that it can be
|
||||
# processed by the rest of the workflow.
|
||||
- name: Parse Issue body
|
||||
id: parse
|
||||
uses: issue-ops/parser@v4
|
||||
with:
|
||||
body: ${{ github.event.issue.body }}
|
||||
issue-form-template: team-membership.yml
|
||||
workspace: ${{ github.workspace }}
|
||||
|
||||
- name: Add to Team
|
||||
id: add
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
github-token: ${{ steps.token.outputs.token }}
|
||||
script: |
|
||||
const parsedIssue = JSON.parse('${{ steps.parse.outputs.json }}')
|
||||
|
||||
await github.rest.teams.addOrUpdateMembershipForUserInOrg({
|
||||
org: context.repo.owner,
|
||||
team_slug: parsedIssue.team,
|
||||
username: '${{ github.event.issue.user.login }}',
|
||||
role: 'member'
|
||||
})
|
||||
|
||||
- name: Notify User
|
||||
id: notify
|
||||
uses: peter-evans/create-or-update-comment@v4
|
||||
with:
|
||||
issue-number: ${{ github.event.issue.number }}
|
||||
body: |
|
||||
This request has been processed successfully!
|
||||
|
||||
- name: Close Issue
|
||||
id: close
|
||||
uses: actions/github-script@v7
|
||||
with:
|
||||
script: |
|
||||
await github.rest.issues.update({
|
||||
issue_number: ${{ github.event.issue.number }},
|
||||
owner: context.repo.owner,
|
||||
repo: context.repo.repo,
|
||||
state: 'closed',
|
||||
state_reason: 'completed'
|
||||
})
|
||||
```
|
||||
|
||||
## Take this with you
|
||||
|
||||
And there you have it! With a handful of standardized workflows, you have an end-to-end, issue-driven process in place to manage team membership. This can be extended as far as you want, including support for removing users, auditing access, and more. With IssueOps, the sky is the limit!
|
||||
|
||||
Here’s the best thing about IssueOps: It brings another level of automation to a surface I’m constantly using—and that’s GitHub. By using issues and pull requests as control centers for workflows, teams can reduce friction, improve efficiency, and keep everything transparent. Whether you want to automate deployments, approvals, or bug triage, IssueOps makes it all possible, without ever leaving your repo.
|
||||
|
||||
For more information and examples, check out the open source [IssueOps documentation repository](https://github.com/issue-ops/docs), and if you want a deeper dive, you can head over to the open source [IssueOps documentation](https://issue-ops.github.io/docs/).
|
||||
|
||||
In my experience, it’s always best to start small and experiment with what works best for you. With just a bit of time, you’ll see your workflows get smoother with every commit (I know I have). Happy coding! ✨
|
||||
@@ -0,0 +1,270 @@
|
||||
---
|
||||
source_url: https://arxiv.org/html/2606.28279v1
|
||||
ingested: 2026-06-30
|
||||
sha256: fd47a13e40cf5f245e7c0a7104fde7c1adbf0fbdfe72a111d5f78767ab73bf84
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521324829314125956'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T01:21:44.157000000Z
|
||||
context_url: https://x.com/dair_ai/status/2071748305416253676
|
||||
message_excerpt: >-
|
||||
HORIZON paper: NVIDIA agentic hardware design; Markdown harness plus executable verification.
|
||||
---
|
||||
|
||||
Cunxi Yu
|
||||
NVIDIA Research
|
||||
&Chenhui Deng
|
||||
NVIDIA Research
|
||||
&Nathaniel Pinckney
|
||||
NVIDIA Research
|
||||
&Brucek Khailany
|
||||
NVIDIA Research
|
||||
Corresponding author: cunxiy@nvidia.com
|
||||
|
||||
###### Abstract
|
||||
|
||||
We present HORIZON, a self-evolving agent framework that treats hardware design as repository-level code evolution. A Markdown harness is compiled into a project pack containing domain knowledge, an executable evaluator, an acceptance predicate, and a git/runtime policy; a hands-free agent loop then evolves an isolated git worktree, using repository operations for state management, tracing, and replay. This extends prior works of repository-scale self-evolution from EDA software systems, to hardware-design artifacts themselves. We evaluate our approach on ChipBench, RTLLM, Verilog-Eval, and nine CVDP categories, achieving 100% benchmark completion across all suites with a fully hands-free agentic loop. However, we do not claim that agentic AI for hardware design is solved: these benchmarks are controlled proxies for a much broader engineering problem in chip design. Section examines the limitations of the current study and highlights open research challenges.
|
||||
|
||||
## 1 Introduction
|
||||
|
||||
Executable design tasks expose a limitation of single-turn code generation. A useful agent must place candidate artifacts inside a runnable workspace, invoke domain tools, interpret failures, and revise the artifacts until an explicit acceptance condition is satisfied. RTL design is a sharp test case: correctness depends on cycle-level behavior, reset and interface conventions, bit widths, and simulator feedback, so plausible Verilog is not enough.
|
||||
|
||||
Our motivation comes from repository-scale code self-evolution. AlphaEvolve showed that LLMs with automated evaluators can improve algorithmic kernels (Novikov et al., ); SATLUTION scaled the idea to full SAT-solver repositories (Yu et al., ); and ABCEvo applied it to the ABC logic-synthesis system (Yu et al., ). In all cases, the agent evolves a version-controlled software artifact and admits changes only when executable evidence supports them. The missing step is hardware: prior repository-level self-evolution changes the programs that engineers run, not the hardware designs engineers create.
|
||||
|
||||
Here, we ask “whether hardware design itself can be managed as repository-level code evolution“. Inspired by prior work (Yu et al., , ), HORIZON turns a design problem into a self-contained git worktree with an executable acceptance gate. A structured Markdown harness specifies the objective, domain knowledge, evaluator, and acceptance predicate; a bootstrap agent compiles it into a project pack; and a hands-free agent loop edits, evaluates, commits, or rejects candidate versions. Git is not incidental bookkeeping in this design. It provides the isolated evolving environment and the trace substrate: diffs expose state changes, commits define accepted checkpoints, logs and notes store evaluator evidence, and the repository history becomes a replayable record of the agent’s search.
|
||||
|
||||
This framing is broader than the benchmarks in this paper. Agentic AI for hardware design includes architecture exploration, microarchitecture, verification planning, physical-design interaction, EDA software, and methodology development; we do not claim that RTL agents are solved. We use RTL benchmarks as controlled, executable proxies for studying whether repository-managed feedback can drive convergence. The evaluation spans ChipBench, RTLLM, Verilog-Eval, and nine CVDP categories, including completion, modification, reuse, testbench stimulus, checker and assertion generation, and debugging (Pinckney et al., ).
|
||||
|
||||
This paper makes three contributions. First, we introduce HORIZON, a framework that hosts hardware design tasks as isolated, version-controlled, automatically evaluated repositories rather than as one-shot prompts. Second, we show that this git-native self-evolution loop can sweep complete RTL benchmark suites to a 100% pass rate, with the only residual failure traced to a known specification-harness mismatch. Third, we analyze the resulting traces, including token consumption and test-generation coverage, and show that once executable feedback makes correctness converge, the main research bottleneck becomes convergence efficiency and verification quality.
|
||||
|
||||
## 2 Background and Related Work
|
||||
|
||||
#### Why RTL is hard for language models.
|
||||
|
||||
RTL generation differs from ordinary code completion because the output defines hardware that must satisfy temporal and bit-accurate behavior. A model must infer datapath widths, finite-state-machine transitions, reset conventions, ready-valid protocols, memory behavior, and corner cases that are often underspecified in natural language. A syntactically valid module is only a starting point; useful automation must connect generation to compilation, simulation, waveform or trace inspection, and repair.
|
||||
|
||||
#### RTL-specialized models and data.
|
||||
|
||||
One body of work improves the generator itself. Early studies fine-tuned open models on Verilog corpora and established that domain adaptation matters: VeriGen curated large HDL training data and benchmarked open and closed models (Thakur et al., ), RTLCoder released an open dataset and a lightweight model that surpassed GPT-3.5 on RTL generation (Liu et al., ), and ChipNeMo domain-adapted LLMs across chip-design tasks (Liu et al., ). More recent efforts target data quality and reasoning: OriGen uses code-to-code augmentation with self-reflection (Cui et al., ), CraftRTL constructs correct-by-construction synthetic data including non-textual representations (Liu et al., ), and ScaleRTL scales RTL reasoning data and adds test-time reasoning, improving Verilog-Eval and RTLLM (Deng et al., ). These approaches strengthen first-attempt accuracy but do not, by themselves, define how an agent should iterate against an executable harness.
|
||||
|
||||
#### Iterative and agentic RTL.
|
||||
|
||||
A complementary body of work adds tool use and iteration on top of a generator. AutoChip drives a generate-compile-simulate feedback loop (Thakur et al., ); RTLFixer repairs syntax errors with retrieval-augmented, ReAct-style debugging (Tsai et al., ); VerilogCoder plans with a task-and-circuit-relation graph and traces waveforms via an AST-based tool to localize functional bugs (Ho et al., ); MAGE decomposes a design across cooperating agents with high-temperature sampling and checkpoint-based debugging (Zhao et al., ); and ACE-RTL pairs an RTL-specialized generator with a frontier-model reflector and coordinator that evolves the prompting context over repair steps (Deng et al., ). These systems show that verification feedback substantially improves correctness, but each is built around a generation-and-repair pipeline for individual modules. HORIZON is complementary and more general: it is agnostic to the underlying generator and instead specifies how to *host the entire problem as a versioned repository*, organize and gate the repair loop with native git operations, and drive a whole benchmark suite to completion, so any backbone can be evaluated on convergence rather than only on first-attempt accuracy.
|
||||
|
||||
#### Benchmarks for RTL design and verification.
|
||||
|
||||
Verilog-Eval and RTLLM are widely used RTL generation benchmarks and remain useful for measuring basic specification-to-RTL ability (Liu et al., ; Lu et al., ); ChipBench and consolidated suites such as OpenLLM-RTL aggregate further generation problems (Liu et al., ). However, the CVDP paper argues that earlier suites are increasingly saturated and too narrow to represent real hardware design workflows (Pinckney et al., ). CVDP contains 783 human-authored problems across 13 task categories. Its code-generation side includes RTL code completion, natural-language-specification to RTL, code modification, module reuse, linting or quality improvement, testbench stimulus generation, checker generation, assertion generation, and debugging. Its comprehension side includes RTL/specification correspondence, testbench/test-plan correspondence, and technical question answering.
|
||||
|
||||
CVDP also distinguishes non-agentic and agentic settings. Non-agentic problems provide the prompt and relevant context in a single turn, while agentic problems are packaged as mini-repositories intended for Dockerized agents that can inspect files and invoke tools. The benchmark reports 617 non-agentic and 166 agentic problems after quality filtering. The authors emphasize that state-of-the-art single-shot models struggle particularly on verification-oriented tasks such as testbench generation, checker generation, assertion generation, and bug fixing. This makes CVDP a strong fit for evaluating whether an agent can improve beyond first-attempt model accuracy through execution feedback.
|
||||
|
||||
#### Self-evolving agents over code repositories.
|
||||
|
||||
A separate line of work treats the codebase itself as the object that an agent evolves. AlphaEvolve coupled an LLM with automated evaluators and an evolutionary loop to discover and refine algorithms at the scale of isolated kernels (Novikov et al., ). SATLUTION extended this to the full repository scale, evolving entire C/C++ SAT-solver repositories under strict correctness guarantees and distributed runtime feedback while also self-evolving its own evolution rules, ultimately outperforming the human-designed SAT-competition winners (Yu et al., ). ABCEvo carried the idea into EDA, using coordinated LLM agents to autonomously rewrite the million-line ABC logic-synthesis system under a correctness- and QoR-driven evaluation loop (Yu et al., ). All three evolve EDA or scientific *software*, the programs that engineers run, under the shared principle that a candidate change is useful only when it survives executable correctness checks and improves measured behavior. HORIZON carries the same repository-self-contained, evidence-gated principle to the *hardware* side: rather than evolving a solver or synthesis kernel, it evolves the design under test, RTL sources, testbenches, and verification artifacts, as an automatically constructed task over a git worktree. This lets one protocol cover per-task RTL generation, completion, and repair, and is what allows HORIZON to treat an RTL benchmark problem “as is” rather than reformulating it into a software-engineering surrogate.
|
||||
|
||||
#### Git as an agent substrate.
|
||||
|
||||
Closely related to our implementation is a recent trend of using version control itself as the scaffolding for LLM agents. EvoGit coordinates a population of decentralized coding agents purely through a Git-based phylogenetic graph that records the full version lineage, with no shared memory or explicit message passing (Huang et al., ). Git Context Controller elevates an agent’s context from a transient token stream to a persistent, version-controlled memory with explicit commit, branch, and merge operations for long-horizon software tasks (Wu et al., ). Both demonstrate that git semantics, branching, lineage, and checkpointing, are a natural fit for organizing agentic exploration, but both target *software* engineering: collaborative code generation and context management, respectively. HORIZON shares the conviction that git is the right substrate, and likewise records every attempt as a commit with attached evaluator evidence, but applies it to a different end, hosting an individual hardware-design problem as a self-contained, verification-gated repository whose history doubles as a replayable experience trace, which we view as convergent evidence that repository-native agents are an emerging paradigm rather than a single-domain trick.
|
||||
|
||||
## 3 The HORIZON Framework
|
||||
|
||||
#### System overview.
|
||||
|
||||
Figure summarizes HORIZON. The central idea is to manage a hardware-design problem like a software-evolution problem: the design, context, harness, and evaluator with correctness gate live in an isolated git worktree, and progress is expressed as repository state changes rather than as disconnected chat turns. A user provides a structured Markdown harness; a bootstrap agent compiles it into a *project pack*, the control plane that fixes the mission, domain skills, executable evaluator, correctness gate, and git/runtime policy. From then on, a self-contained agent loop evolves the worktree without further human input. Each cycle generates or edits candidate artifacts, runs the evaluator, scores the result, and either commits the new version or logs the failure. Native git functions provide both isolation and traceability: diffs expose proposed state changes, commits define accepted checkpoints, logs recover the trajectory, and notes/runtime summaries attach evaluator evidence. The same machinery is intended to host versatile chip-design work, including RTL, EDA-software research, and methodology or flow exploration. In this paper we exercise the RTL instantiation; the broader design-space claim is a framework goal rather than a completed empirical validation.
|
||||
|
||||
#### From harness to executable task.
|
||||
|
||||
HORIZON views language-model agents as policies acting on executable workspaces. The framework is not specific to RTL or to EDA self-evolution: any task with a persistent git worktree, machine-checkable feedback, and versioned artifacts can be organized in the same way. The only required user input is a structured Markdown harness, which may contain high-level intent, repository context, expected artifacts, evaluation criteria, and domain knowledge. Domain-aware harnesses are especially useful because they expose invariants, tool conventions, and failure modes that are difficult to infer from files alone.
|
||||
|
||||
The bootstrap agent converts this harness into a project pack. Let $m$ denote the input harness. A bootstrap tool loop $G_{\phi}$ constructs
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><mrow><mrow><mi>p</mi> <mo>=</mo> <mrow><msub><mi>G</mi> <mi>ϕ</mi></msub> <mo></mo><mrow><mo>(</mo><mi>m</mi><mo>)</mo></mrow></mrow></mrow><mo>,</mo><mrow><mi>p</mi> <mo>=</mo> <mrow><mo>(</mo><msub><mi>π</mi> <mi>agent</mi></msub><mo>,</mo><msub><mi>E</mi> <mi>p</mi></msub><mo>,</mo><msub><mi>A</mi> <mi>p</mi></msub><mo>,</mo><msub><mi>Γ</mi> <mi>p</mi></msub><mo>,</mo><msub><mi>Ω</mi> <mi>p</mi></msub><mo>)</mo></mrow></mrow></mrow><mo>,</mo></mrow><annotation>p=G_{\phi}(m),\qquad p=(\pi_{\mathrm{agent}},E_{p},A_{p},\Gamma_{p},\Omega_{p}),</annotation></semantics></math></td><td></td><td rowspan="1"><span>(1)</span></td></tr></tbody></table>
|
||||
|
||||
where $\pi_{\mathrm{agent}}$ is the agent policy prompt and tool contract, $E_{p}$ is an executable evaluator or harness, $A_{p}$ is the acceptance predicate, $\Gamma_{p}$ is the version-control and artifact policy, and $\Omega_{p}$ contains domain skills and repository instructions. For RTL, $E_{p}$ may include compilation, simulation, coverage extraction, and assertion or testbench checks. In other domains, the same slot may be filled by unit tests, theorem provers, profilers, security scanners, synthesis tools, or human-review gates. Problems are therefore defined over git worktrees rather than over a fixed target repository type.
|
||||
|
||||

|
||||
|
||||
Refer to caption
|
||||
|
||||
#### Repository-traced formulation.
|
||||
|
||||
HORIZON is an agentic system: the underlying policy is a free-form, history-dependent LLM agent, and we make no claim that its behavior is Markovian. We borrow the vocabulary of a semi-Markov decision process for one narrow purpose, to give precise, replayable names to the objects we record, not as a behavioral or optimization assumption. Because each accepted version follows a temporally extended episode of many edits, tool calls, and partial repairs, it is natural to label the boundaries: a “state” is a versioned snapshot of the repository (a bookkeeping checkpoint, not a sufficient statistic of the agent’s reasoning), and an “option” is one such episode between two checkpoints. With that caveat, the objects below are simply definitions of what each trace stores. At outer checkpoint $t$, the recorded state is
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><mrow><msub><mi>s</mi> <mi>t</mi></msub> <mo>=</mo> <mrow><mo>(</mo><mrow><mi>tree</mi> <mo></mo><mrow><mo>(</mo><msub><mi>w</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow><mo>,</mo><mi>p</mi><mo>,</mo><msub><mi>z</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>ℓ</mi> <mrow><mo>≤</mo> <mi>t</mi></mrow></msub><mo>,</mo><msub><mi>μ</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow><mo>,</mo></mrow><annotation>s_{t}=\big(\mathrm{tree}(w_{t}),\,p,\,z_{t},\,\ell_{\leq t},\,\mu_{t}\big),</annotation></semantics></math></td><td></td><td rowspan="1"><span>(2)</span></td></tr></tbody></table>
|
||||
|
||||
where $\mathrm{tree}(w_{t})$ is the git tree of the current worktree, $p$ is the project pack, $z_{t}$ is campaign state, $\ell_{\leq t}$ are accumulated logs and evaluator artifacts, and $\mu_{t}$ is any declared memory that the policy is allowed to condition on. The agent samples a variable-length option
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><mrow><msub><mi>a</mi> <mi>t</mi></msub> <mo>=</mo> <mrow><mo>(</mo><msub><mi>Δ</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>u</mi> <mrow><mrow><mi>t</mi><mo>,</mo><mn>1</mn></mrow><mo>:</mo><msub><mi>K</mi> <mi>t</mi></msub></mrow></msub><mo>,</mo><msub><mi>ρ</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow><mo>,</mo></mrow><annotation>a_{t}=(\Delta_{t},\,u_{t,1:K_{t}},\,\rho_{t}),</annotation></semantics></math></td><td></td><td rowspan="1"><span>(3)</span></td></tr></tbody></table>
|
||||
|
||||
where $\Delta_{t}$ is the proposed patch or generated artifact set, $u_{t,1:K_{t}}$ are the $K_{t}$ tool calls and observations inside the option, and $\rho_{t}$ is the final review or submission decision. The evaluator produces evidence
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><mrow><msub><mi>y</mi> <mi>t</mi></msub> <mo>=</mo> <mrow><msub><mi>E</mi> <mi>p</mi></msub> <mo></mo><mrow><mo>(</mo><mrow><msub><mi>w</mi> <mi>t</mi></msub> <mo>⊕</mo> <msub><mi>Δ</mi> <mi>t</mi></msub></mrow><mo>)</mo></mrow></mrow></mrow><mo>,</mo></mrow><annotation>y_{t}=E_{p}(w_{t}\oplus\Delta_{t}),</annotation></semantics></math></td><td></td><td rowspan="1"><span>(4)</span></td></tr></tbody></table>
|
||||
|
||||
and the acceptance predicate determines whether the trace advances:
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><msub><mi>s</mi> <mrow><mi>t</mi> <mo>+</mo> <mn>1</mn></mrow></msub> <mo>=</mo> <mrow><mo>{</mo> <mtable><mtr><mtd><mrow><mrow><mi>Commit</mi> <mo></mo><mrow><mo>(</mo><mrow><msub><mi>w</mi> <mi>t</mi></msub> <mo>⊕</mo> <msub><mi>Δ</mi> <mi>t</mi></msub></mrow><mo>,</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>Γ</mi> <mi>p</mi></msub><mo>)</mo></mrow></mrow><mo>,</mo></mrow></mtd><mtd><mrow><mrow><mrow><msub><mi>A</mi> <mi>p</mi></msub> <mo></mo><mrow><mo>(</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow> <mo>=</mo> <mn>1</mn></mrow><mo>,</mo></mrow></mtd></mtr><mtr><mtd><mrow><mrow><mi>RejectLog</mi> <mo></mo><mrow><mo>(</mo><msub><mi>s</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>Δ</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow><mo>,</mo></mrow></mtd><mtd><mrow><mrow><mrow><msub><mi>A</mi> <mi>p</mi></msub> <mo></mo><mrow><mo>(</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow> <mo>=</mo> <mn>0</mn></mrow><mo>.</mo></mrow></mtd></mtr></mtable></mrow></mrow><annotation>s_{t+1}=\begin{cases}\mathrm{Commit}(w_{t}\oplus\Delta_{t},\,y_{t},\,\Gamma_{p}),&A_{p}(y_{t})=1,\\[2.0pt] \mathrm{RejectLog}(s_{t},\,\Delta_{t},\,y_{t}),&A_{p}(y_{t})=0.\end{cases}</annotation></semantics></math></td><td></td><td rowspan="1"><span>(5)</span></td></tr></tbody></table>
|
||||
|
||||
The reward can be scalar or vector-valued, for example,
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><mrow><msub><mi>r</mi> <mi>t</mi></msub> <mo>=</mo> <mrow><msub><mi>R</mi> <mi>p</mi></msub> <mo></mo><mrow><mo>(</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>)</mo></mrow></mrow> <mo>=</mo> <mrow><mo>[</mo><mrow><mi>Δ</mi> <mo></mo><mi>pass</mi></mrow><mo>,</mo><mrow><mi>Δ</mi> <mo></mo><mi>coverage</mi></mrow><mo>,</mo><mrow><mi>Δ</mi> <mo></mo><mi>QoR</mi></mrow><mo>,</mo><mrow><mo>−</mo> <mi>tokens</mi></mrow><mo>,</mo><mrow><mo>−</mo> <mi>time</mi></mrow><mo>]</mo></mrow></mrow><mo>,</mo></mrow><annotation>r_{t}=R_{p}(y_{t})=\big[\Delta\mathrm{pass},\,\Delta\mathrm{coverage},\,\Delta\mathrm{QoR},\,-\mathrm{tokens},\,-\mathrm{time}\big],</annotation></semantics></math></td><td></td><td rowspan="1"><span>(6)</span></td></tr></tbody></table>
|
||||
|
||||
and an individual coordinate is populated only when the evaluator emits the corresponding signal; in this paper we report the $\Delta\mathrm{pass}$, $\Delta\mathrm{coverage}$, and $-\mathrm{tokens}$ components and leave synthesis quality-of-results ($\Delta\mathrm{QoR}$) to future work. An execution trace of depth $D$ is then
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><mrow><msub><mi>τ</mi> <mrow><mn>0</mn><mo>:</mo><mi>D</mi></mrow></msub> <mo>=</mo> <msubsup><mrow><mo>{</mo> <mrow><mo>(</mo><msub><mi>s</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>a</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>r</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>s</mi> <mrow><mi>t</mi> <mo>+</mo> <mn>1</mn></mrow></msub><mo>,</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>)</mo></mrow> <mo>}</mo></mrow> <mrow><mi>t</mi> <mo>=</mo> <mn>0</mn></mrow> <mrow><mi>D</mi> <mo>−</mo> <mn>1</mn></mrow></msubsup></mrow><mo>.</mo></mrow><annotation>\tau_{0:D}=\{(s_{t},a_{t},r_{t},s_{t+1},y_{t})\}_{t=0}^{D-1}.</annotation></semantics></math></td><td></td><td rowspan="1"><span>(7)</span></td></tr></tbody></table>
|
||||
|
||||
The depth $D$ is not fixed by the benchmark; it is determined by the campaign budget, convergence, or stopping rule. This makes the trace suitable for policy analysis, reward modeling, curriculum construction, or offline agent-RL training. We stress that we use this formulation only to structure and record the search; we do not train or update an RL policy in this work, and our agent backbone is fixed throughout a campaign.
|
||||
|
||||
#### Agent loop and trace buffer.
|
||||
|
||||
Once the user supplies the initial Markdown harness, the loop is completely hands-free: bootstrap, generation, evaluation, acceptance, logging, and the next iteration all run automatically, and a campaign proceeds for many iterations with no further human intervention. Each outer transition contains an internal trajectory of depth $K_{t}$, the agent reads the current state, plans a target, edits the worktree, invokes tools, interprets failures, and either repairs or submits, and this inner trajectory is not assumed to be Markov and can differ in length at every step. We deliberately build the trace buffer on top of native git so that tracing is dynamic and essentially free to maintain: staged edits are inspected with git diff --cached, each accepted attempt becomes a git commit whose message and attached git notes carry the evaluator verdict and reward, the full version history is recovered with git log, and an independent review step diffs the candidate before it is allowed to submit. Successful commits become positive examples of repair strategies while rejected attempts are logged as negative examples of edits or tool-use paths that failed the evaluator, so the repository’s own history *is* the experience buffer rather than a separate datastore.
|
||||
|
||||
#### Memory and session reuse.
|
||||
|
||||
Because there is no true Markov state, the process is just a sequence of agent actions and LLM responses, memory is handled pragmatically rather than as a state variable, and the operative objective is to maximize the share of *cached* tokens relative to freshly billed input and output tokens. HORIZON reuses a persistent model session across iterations so that the harness, project pack, stable sources, and accumulated debugging context are served from the provider’s prompt cache instead of being re-sent every turn; the newly billed tokens are then dominated by the current diff, the latest evaluator output, and the agent’s response. This keeps the marginal cost of an additional repair iteration low even when a campaign runs for dozens of iterations, and it is the main reason cumulative token usage is overwhelmingly cached input (Section ). The agent may still condition on session memory $h_{t}$,
|
||||
|
||||
<table><tbody><tr><td></td><td><math><semantics><mrow><msub><mi>a</mi> <mi>t</mi></msub> <mo>∼</mo> <msub><mi>π</mi> <mi>θ</mi></msub> <mrow><mo>(</mo><mo>⋅</mo> <mo>∣</mo> <msub><mi>s</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>h</mi> <mi>t</mi></msub><mo>)</mo></mrow><mo>,</mo><msub><mi>h</mi> <mrow><mi>t</mi> <mo>+</mo> <mn>1</mn></mrow></msub> <mo>=</mo> <mi>M</mi> <mrow><mo>(</mo><msub><mi>h</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>s</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>a</mi> <mi>t</mi></msub><mo>,</mo><msub><mi>y</mi> <mi>t</mi></msub><mo>)</mo></mrow><mo>,</mo></mrow><annotation>a_{t}\sim\pi_{\theta}(\cdot\mid s_{t},h_{t}),\qquad h_{t+1}=M(h_{t},s_{t},a_{t},y_{t}),</annotation></semantics></math></td><td></td><td rowspan="1"><span>(8)</span></td></tr></tbody></table>
|
||||
|
||||
but the source of truth remains the git worktree, the project pack, the evaluator outputs, and the versioned trace; campaign and review memories are kept separate so that review remains an independent check.
|
||||
|
||||
## 4 Experiments
|
||||
|
||||
#### Setup and protocol.
|
||||
|
||||
Model: we use GPT-5.3 as the agent backbone for all experiments, fixed throughout; Benchmarks: ChipBench, RTLLM-2.0, and Verilog-Eval, together with all CVDP code- and verification-generation categories (CID 002 to 016) spanning completion, specification-to-RTL, modification, reuse, linting/QoR, and stimulus, checker, and assertion generation as well as debugging. Host environment: all campaigns run on an AMD EPYC 9334 32-Core processor with 512 GB of RAM, with evaluators invoking each suite’s native open-source and, where required, commercial-EDA flows. Task construction: for each problem the bootstrap agent builds a project pack whose evaluator wraps the suite’s native harness (compilation, simulation, and where available coverage or assertion checks), with the acceptance predicate set to the harness pass condition. Protocol: an *iteration* is one automated outer step in which the agent edits the worktree, runs the evaluator, and either commits a passing version or logs a rejection; we report best-so-far pass rate, the fraction of tasks for which a passing version has been committed by a given iteration, and define the *earliest-best* iteration as the first iteration that attains a benchmark’s maximum observed pass rate. The entire loop is hands-free, and all results presented in this paper are obtained in single-agent mode.
|
||||
|
||||
| Suite/category | Evaluation focus | EDA | Iter. 0 <sup><span>b</span></sup> | Final iter. | HORIZON |
|
||||
| --- | --- | --- | --- | --- | --- |
|
||||
| ChipBench | Mixed RTL generation tasks | Open | 20.0 | 5 | 100.0 <sup><span>a</span></sup> |
|
||||
| RTLLM-2.0 | Natural-language spec to RTL | Open | 78.0 | 2 | 100.0 |
|
||||
| Verilog-Evalv2 | HDLBits-style Verilog generation | Open | 86.2 | 2 | 100.0 |
|
||||
| CVDP CID 002 | RTL code completion | Open | 3.2 | 82 | 100.0 |
|
||||
| CVDP CID 003 | Natural-language spec to RTL | Open | 19.2 | 24 | 100.0 |
|
||||
| CVDP CID 004 | RTL code modification | Open | 10.9 | 36 | 100.0 |
|
||||
| CVDP CID 005 | Spec-to-RTL module reuse | Open | 9.1 | 14 | 100.0 |
|
||||
| CVDP CID 007 | Linting / QoR improvement | Open | 0.0 | 24 | 100.0 |
|
||||
| CVDP CID 012 | Test-plan to stimulus generation | Comm. | 47.8 | 32 | 100.0 |
|
||||
| CVDP CID 013 | Test-plan to checker generation | Comm. | 3.8 | 19 | 100.0 |
|
||||
| CVDP CID 014 | Test-plan to assertion generation | Comm. | 79.1 | 1 | 100.0 |
|
||||
| CVDP CID 016 | Debugging and bug fixing | Open | 25.7 | 13 | 100.0 |
|
||||
| Overall | All evaluated RTL benchmarks | | 47.8 | | 100.0 |
|
||||
|
||||
Table 1: Pass rates (%) from a single HORIZON run. *Final iter.* denotes the iteration at which HORIZON converges. *EDA* indicates the evaluation backend, open-source (Open) or commercial (Comm.); only CID 012–014 require a commercial simulator. HORIZON achieves 100% completion on every suite. <sup><span>a</span></sup> One non-passing ChipBench task is due to a specification–harness defect in the original benchmark; counting it as resolved yields 100%. <sup><span>b</span></sup> *Iter. 0* is the pass rate after the first agent iteration, not the standalone LLM Pass@1.
|
||||
|
||||
Table starts from the benchmark surface rather than only the final score. The evaluated tasks span compact RTL generation suites, legacy specification-to-RTL benchmarks, and nine CVDP categories that exercise completion, specification implementation, modification, module reuse, code improvement, testbench stimulus generation, checker generation, assertion generation, and debugging.
|
||||
|
||||
### 4.1 Benchmark completion and pass-rate progression
|
||||
|
||||
Run as a single hands-free agentic loop per benchmark set, HORIZON drives every benchmark suite to a 100% pass rate (Table ); the only residual miss is a single ChipBench task, which we trace to a specification–harness mismatch in the original benchmark rather than to agent failure. What varies across suites is therefore not the destination but the path to it. At the agent’s first iteration, the aggregate pass rate is 47.8%, and it is substantially lower on the hardest CVDP categories, including 3.2% on code completion (CID 002) and 3.8% on checker generation (CID 013), before the same loop eventually closes the gap to 100%. We emphasize that the iteration-0 results are not standalone model Pass@1 measurements. Instead, they reflect the state of the repository after the first step of the agentic evolution process, executed under the same prompting strategy and workflow used throughout the run. As a result, the agent may defer substantial exploration, debugging, and repair to later iterations rather than attempting to maximize first-pass success. This first-iteration aggregate is buoyed by Verilog-Eval-v2, which already reaches 86.2% at iteration 0, whereas the CVDP subset starts at 23.9%. We therefore report not merely that the suites are completed, but also how the agentic loop reaches completion.
|
||||
|
||||

|
||||
|
||||
(a) Simple RTL generation suites.
|
||||
|
||||
Figure shows the qualitative difference between the benchmark families. RTLLM-2.0 and Verilog-Eval reach 100% within two iterations; ChipBench climbs from 20.0% to 100% over five iterations, where the single task not passed under the original harness is the benchmark defect noted in Table . CVDP categories require more varied repair budgets. CID 014 reaches 100% after one iteration, CID 016 and CID 005 reach 100% in 13 and 14 iterations, CID 013 requires 19 iterations, CID 003 and CID 007 require 24 iterations, CID 012 requires 32 iterations, CID 004 requires 36 iterations, and CID 002 requires 82 iterations. The long tail in CID 002 is especially informative: it is not a one-shot modeling failure, but a convergence problem where the agent gradually converts many failing completions into passing designs.
|
||||
|
||||
The two extremes of difficulty are also the two most informative trajectories. CID 013 (adding reference-model checker logic to a testbench, evaluated under commercial-EDA simulation) rounds out the verification-generation family alongside stimulus generation (CID 012) and assertion generation (CID 014), and has the lowest first-iteration pass rate of any category, 3.8%, consistent with the CVDP finding that checker writing is especially hard for single-shot models. Yet despite this weak start it reaches 100% by iteration 19 along a strikingly steady, near-linear trajectory, climbing at a near-constant rate with almost no plateau. CID 013 and CID 002 thus bracket the behavior of the loop: a very low first-iteration rate does not by itself imply slow or unstable convergence (CID 013), while a long tail on a few stubborn designs is what actually drives cost (CID 002).
|
||||
|
||||
### 4.2 Token Consumption Result
|
||||
|
||||
We next report how much agent work each completion requires, measured as the cumulative tokens consumed through a run’s earliest-best iteration. This is not a normalized economic cost, model pricing, parallelism, and infrastructure are excluded, but it is a useful first-order measure of effort, and (per the session-reuse design) it is overwhelmingly cached input rather than freshly billed tokens.
|
||||
|
||||

|
||||
|
||||
Table 2: Token consumption through the earliest-best iteration, as cumulative tokens recorded in the agent launch logs. Left: tokens (millions) and share of the total per benchmark, with the convergence iteration. Right: the same shares as a donut, with the three legacy suites grouped. Cost is dominated by a few hard CVDP categories. Note that approximately 91% of all tokens are cached input, which significantly lowered the API cost. Shares may not sum to 100.0% due to rounding.
|
||||
|
||||

|
||||
|
||||
(a) Normalized cumulative token usage.
|
||||
|
||||
Table and Figure show that token consumption is concentrated in the most challenging CVDP categories. The three legacy suites together consume 6.0M tokens, whereas the nine CVDP categories consume 203.9M tokens, accounting for 97.1% of the total. Among these, CID 002 alone uses 56.0M tokens, CID 003 uses 38.0M, and CID 012 uses 32.2M. CID 013 is comparatively efficient given its difficulty: despite having the lowest first-iteration pass rate, it converges after consuming only 14.2M tokens, consistent with its steady, plateau-free trajectory.
|
||||
|
||||
The practical takeaway is that benchmark completion should be reported together with token consumption. Although HORIZON clears every suite, the final few percentage points on the most difficult categories absorb a disproportionate share of the budget. Consequently, we view token efficiency, rather than final pass rate, as the metric most in need of improvement. Notably, approximately 91% of all tokens are cached input tokens.
|
||||
|
||||
### 4.3 Detailed discussion on test-generation tasks
|
||||
|
||||
The test-generation categories deserve a closer look because they expose what HORIZON is and is not optimizing. For the two categories with parsed coverage data (CID 012 stimulus and CID 014 assertion generation), we additionally measure design coverage of the generated tests, reported as the average coverage percentage over designs with parsed coverage logs at each iteration. The crucial point is that HORIZON’s acceptance gate is the *CVDP pass condition*, not a coverage target: the loop is driven to make the benchmark’s own harness pass, and once a design passes, the gate is satisfied and the loop stops refining it. Coverage is therefore a secondary, observational signal here, it reports how much of the design the passing tests happen to exercise, rather than the objective being maximized.
|
||||
|
||||
| Category | Iter. 0 pass <sup><span>a</span></sup> | Iter. 0 cov.<sup><span>a</span></sup> | Best iter. | Best pass | Best cov. |
|
||||
| --- | --- | --- | --- | --- | --- |
|
||||
| CVDP CID 012 | 47.8% | 86.5% | 32 | 100.0% | 97.9% |
|
||||
| CVDP CID 014 | 79.1% | 98.1% | 1 | 100.0% | 100.0% |
|
||||
|
||||
Table 3: Coverage summary for the CVDP verification-generation categories. CID 012 is test-plan to testbench stimulus generation; CID 014 is test-plan to assertion generation. CID 014 has seven designs without parsed coverage rows at the best iteration, so its best-coverage average is computed over the remaining 60 parsed logs. <sup><span>a</span></sup> Similarly as Table , Iter. 0 denotes the first agent iteration and should not be interpreted as a standalone model Pass@1 or one-shot generation result; it reflects the repository state after the first step of the agentic evolution process.
|
||||
|
||||

|
||||
|
||||
Figure 4: Coverage and pass rate for CID 012 (testbench stimulus generation), both truncated at iteration 32, where the pass rate first reaches 100% (the convergence-point convention of Figures – ). Left: average design coverage rises gradually from 86.5% to 97.9% while the pass rate climbs from 47.8% to 100% over the same iterations; the two move together but coverage plateaus below 100% because the acceptance gate stops each design once it passes. Right: per-design coverage curves with their mean (bold). The improvement comes from lifting a low-coverage tail up toward full coverage, rather than only nudging already-high-coverage designs.
|
||||
|
||||
Table and Figure make the stopping behavior concrete. CID 012 reaches a 100% pass rate at iteration 32, but its average per-design coverage at that point is 97.9%, not 100%. This gap is expected and is a direct consequence of the acceptance gate: the loop halts on each design as soon as the CVDP harness passes, so coverage simply reflects the tests that were sufficient to pass rather than the maximum achievable. The per-design view (Figure , right) shows the loop lifting a low-coverage tail, several designs that begin near 20% to 40% coverage are pulled up toward full coverage, rather than only nudging already-high-coverage designs. CID 014 is the opposite regime: it starts near 98% coverage and saturates immediately, so we report it only in Table ; its 100.0% best value is computed over the 60 designs with parsed coverage logs and should be read as coverage over those logs, not as evidence that every design emitted a usable report. We emphasize that we did *not* attempt to drive coverage to 100%: doing so would mean replacing the pass-based acceptance predicate with a coverage target, which HORIZON supports in principle but we leave to future work. Coverage here is thus a diagnostic that the generated tests are substantive, not a claim of exhaustive verification.
|
||||
|
||||
## 5 Discussion and Limitations
|
||||
|
||||
The main takeaway of this work is that repository-managed executable feedback can make many RTL benchmark tasks converge. It is not that agentic hardware design is solved. The results should be read as *benchmark convergence under the feedback made available to the agent*. Real chip projects involve incomplete specifications, changing constraints, downstream integration, human review, PPA tradeoffs, and validation targets that are not fully represented by current RTL benchmarks Liu et al. (); Lu et al. (); Liu et al. (); Pinckney et al. ().
|
||||
|
||||
The most important limitation is the reward-feedback interface. In the current HORIZON setup, the agent can inspect the outputs of each iterative evaluation. In CVDP Pinckney et al. (), for example, this includes simulator messages, evaluation logs, failure traces, and other task-local artifacts exposed by the benchmark harness. This mirrors a realistic debug workflow: engineers normally inspect logs and counterexamples, and rich feedback is what makes long-horizon repair feasible. At the same time, full access to these signals can create an *over-solving* or reward-hacking failure mode. The agent may customize the generated RTL to match the observed failures, deterministic tests, or evaluator idiosyncrasies rather than implement the intended design semantics robustly. A passing result can therefore mean “satisfies the visible harness under the exposed traces” rather than “satisfies the specification under all reasonable tests.” This risk is especially relevant when benchmarks reveal detailed failure information or when the final acceptance test is the same harness used throughout the repair loop.
|
||||
|
||||
This raises a broader benchmarking issue. Existing RTL-agent benchmarks generally do not include a mechanism to detect over-solving or reward hacking Liu et al. (); Lu et al. (); Liu et al. (); Pinckney et al. (). They measure whether the submitted artifact passes the provided harness, but they usually do not separate debugging feedback from final hidden scoring, test robustness under randomized or perturbed stimuli, or audit whether a solution has specialized to artifacts of the evaluator. This is an open problem for the community. Future benchmarks for agentic hardware design should consider a two-level protocol: expose useful diagnostic feedback during repair, but reserve hidden randomized tests, independent reference models, formal equivalence checks, property suites, or held-out simulator configurations for final scoring. Reporting robustness to harness perturbations, coverage closure, and traces of what feedback the agent consumed would also make it easier to distinguish genuine design repair from benchmark-specific adaptation.
|
||||
|
||||
This tension has a direct parallel in software-engineering benchmarks. SWE-bench addresses it through structural test withholding Jimenez et al. (); Wang et al. (). Agents receive a GitHub issue description and a repository snapshot at a fixed commit, while the fail-to-pass and pass-to-pass tests used for evaluation are withheld during inference and executed only after a final patch is submitted. This separation between repair-time information and evaluation-time scoring reduces opportunities for reward hacking and benchmark-specific adaptation. Subsequent analyses have shown that benchmark design choices such as solution leakage and weak test suites can substantially inflate measured performance Aleithan et al. (), and that patches deemed successful by benchmark tests may still diverge from developer-intended behavior or contain latent correctness issues pengfeigao1 (). These findings suggest that future RTL-agent benchmarks should similarly separate diagnostic feedback from final scoring and incorporate robustness checks beyond the visible repair loop, such as hidden randomized tests, independent reference models, formal equivalence checking, or held-out verification environments.
|
||||
|
||||
Another major limitation is feedback turnaround. The RTL pass/fail benchmarks in this paper are relatively favorable because most evaluations complete quickly enough for iterative repair. In broader chip-design self-evolution, reward evaluation can be far slower. We have also studied PPA optimization in RTL design loops and PPA-oriented EDA-tool evolution, including the ABCEvo-style setting Yu et al. (), where the reward may require synthesis, placement, routing, timing analysis, power estimation, or large regression suites. SATLUTION already illustrates the cost of accurate repository-level reward: evaluating an entire SAT-competition benchmark required roughly a two-hour turnaround even with about 800 nodes running in parallel Yu et al. (). For RTL PPA optimization or EDA-tool self-evolution, the turnaround can grow to days or weeks depending on design size, evaluation stage, and signoff fidelity. Long-latency reward fundamentally changes the agentic system problem: naive edit-evaluate-repair loops become too slow, and the agent must reason under delayed, sparse, and expensive feedback. Addressing long-turnaround reward is therefore a key research challenge for agentic chip design.
|
||||
|
||||
## 6 Conclusion
|
||||
|
||||
We presented HORIZON, a self-evolving agent framework that treats hardware design as repository-level code evolution. A human-written Markdown harness is compiled into a project pack containing domain knowledge, an executable evaluator, an acceptance predicate, and a git/runtime policy; a hands-free agent loop then evolves an isolated repository worktree until the acceptance criterion is satisfied. Building on prior repository-scale self-evolution systems for EDA software, HORIZON extends the same paradigm to hardware-design artifacts themselves.
|
||||
|
||||
Across ChipBench, RTLLM, Verilog-Eval, and nine CVDP categories, HORIZON achieves 100% benchmark completion with a fully hands-free agentic loop. To our knowledge, this is the first agentic system to complete all evaluated RTL benchmark suites end-to-end without human intervention. With correctness largely saturated on these benchmarks, the more informative signal becomes the cost of reaching that outcome. We find that token consumption is concentrated in a small number of difficult categories and that approximately 91% of all tokens are cached input tokens, making token efficiency a more meaningful target for future improvement than final pass rate.
|
||||
|
||||
At the same time, we do not claim that agentic hardware design is solved. Current RTL benchmarks are controlled proxies for a much broader engineering problem and leave open important questions around reward hacking, robustness, long-horizon design planning, and deployment in production design flows. We hope this work helps establish a path from benchmark-scale RTL generation toward reliable agentic systems for real-world chip design.
|
||||
|
||||
## References
|
||||
|
||||
[^1]: Alexander Novikov, Ngân Vũ, Marvin Eisenberger, Emilien Dupont, Po-Sen Huang, et al.AlphaEvolve: A Coding Agent for Scientific and Algorithmic Discovery.arXiv preprint arXiv:2506.13131, 2025.
|
||||
|
||||
[^2]: Cunxi Yu, Rongjian Liang, Chia-Tung Ho, and Haoxing Ren.Autonomous Code Evolution Meets NP-Completeness.arXiv preprint arXiv:2509.07367, 2025.
|
||||
|
||||
[^3]: Cunxi Yu, Rongjian Liang, Chia-Tung Ho, and Haoxing Ren.Autonomous Evolution of EDA Tools: Multi-Agent Self-Evolved ABC.arXiv preprint arXiv:2604.15082, 2026.
|
||||
|
||||
[^4]: Nathaniel Pinckney, Chenhui Deng, Chia-Tung Ho, Yun-Da Tsai, Mingjie Liu, Wenfei Zhou, Brucek Khailany, and Haoxing Ren.Comprehensive Verilog Design Problems: A Next-Generation Benchmark Dataset for Evaluating Large Language Models and Agents on RTL Design and Verification.arXiv preprint arXiv:2506.14074, 2025.
|
||||
|
||||
[^5]: Chenhui Deng, Zhongzhi Yu, Guan-Ting Liu, Nathaniel Pinckney, Brucek Khailany, and Haoxing Ren.ACE-RTL: When Agentic Context Evolution Meets RTL-Specialized LLMs.arXiv preprint arXiv:2602.10218, 2026.
|
||||
|
||||
[^6]: Chenhui Deng, Yun-Da Tsai, Guan-Ting Liu, Zhongzhi Yu, and Haoxing Ren.ScaleRTL: Scaling LLMs with Reasoning Data and Test-Time Compute for Accurate RTL Code Generation.arXiv preprint arXiv:2506.05566, 2025.
|
||||
|
||||
[^7]: Mingjie Liu, Nathaniel Pinckney, Brucek Khailany, and Haoxing Ren.VerilogEval: Evaluating Large Language Models for Verilog Code Generation.In *Proceedings of the IEEE/ACM International Conference on Computer-Aided Design (ICCAD)*, 2023. arXiv:2309.07544.
|
||||
|
||||
[^8]: Yao Lu, Shang Liu, Qijun Zhang, and Zhiyao Xie.RTLLM: An Open-Source Benchmark for Design RTL Generation with Large Language Model.In *Proceedings of the Asia and South Pacific Design Automation Conference (ASP-DAC)*, 2024. arXiv:2308.05345.
|
||||
|
||||
[^9]: Shang Liu, Yao Lu, Wenji Fang, Mengming Li, and Zhiyao Xie.OpenLLM-RTL: Open Dataset and Benchmark for LLM-Aided Design RTL Generation.In *Proceedings of the IEEE/ACM International Conference on Computer-Aided Design (ICCAD)*, 2024. arXiv:2503.15112.
|
||||
|
||||
[^10]: Shailja Thakur, Baleegh Ahmad, Hammond Pearce, Benjamin Tan, Brendan Dolan-Gavitt, Ramesh Karri, and Siddharth Garg.VeriGen: A Large Language Model for Verilog Code Generation.*ACM Transactions on Design Automation of Electronic Systems*, 2024. arXiv:2308.00708.
|
||||
|
||||
[^11]: Shang Liu, Wenji Fang, Yao Lu, Jing Wang, Qijun Zhang, Hongce Zhang, and Zhiyao Xie.RTLCoder: Fully Open-Source and Efficient LLM-Assisted RTL Code Generation Technique.*IEEE Transactions on Computer-Aided Design of Integrated Circuits and Systems*, 2025. arXiv:2312.08617.
|
||||
|
||||
[^12]: Mingjie Liu, Teodor-Dumitru Ene, Robert Kirby, Chris Cheng, Nathaniel Pinckney, et al.ChipNeMo: Domain-Adapted LLMs for Chip Design.arXiv preprint arXiv:2311.00176, 2023.
|
||||
|
||||
[^13]: Fan Cui, Chenyang Yin, Kexing Zhou, Youwei Xiao, Guangyu Sun, et al.OriGen: Enhancing RTL Code Generation with Code-to-Code Augmentation and Self-Reflection.arXiv preprint arXiv:2407.16237, 2024.
|
||||
|
||||
[^14]: Mingjie Liu, Yun-Da Tsai, Wenfei Zhou, and Haoxing Ren.CraftRTL: High-quality Synthetic Data Generation for Verilog Code Models with Correct-by-Construction Non-Textual Representations and Targeted Code Repair.arXiv preprint arXiv:2409.12993, 2024.
|
||||
|
||||
[^15]: Shailja Thakur, Jason Blocklove, Hammond Pearce, Benjamin Tan, Siddharth Garg, and Ramesh Karri.AutoChip: Automating HDL Generation Using LLM Feedback.arXiv preprint arXiv:2311.04887, 2023.
|
||||
|
||||
[^16]: Yun-Da Tsai, Mingjie Liu, and Haoxing Ren.RTLFixer: Automatically Fixing RTL Syntax Errors with Large Language Models.In *Proceedings of the 61st ACM/IEEE Design Automation Conference (DAC)*, 2024. arXiv:2311.16543.
|
||||
|
||||
[^17]: Chia-Tung Ho, Haoxing Ren, and Brucek Khailany.VerilogCoder: Autonomous Verilog Coding Agents with Graph-based Planning and Abstract Syntax Tree (AST)-based Waveform Tracing Tool.In *Proceedings of the AAAI Conference on Artificial Intelligence*, 2025. arXiv:2408.08927.
|
||||
|
||||
[^18]: Yujie Zhao, Hejia Zhang, Hanxian Huang, Zhongming Yu, and Jishen Zhao.MAGE: A Multi-Agent Engine for Automated RTL Code Generation.In *Proceedings of the 62nd ACM/IEEE Design Automation Conference (DAC)*, 2025. arXiv:2412.07822.
|
||||
|
||||
[^19]: Beichen Huang, Ran Cheng, and Kay Chen Tan.EvoGit: Decentralized Code Evolution via Git-Based Multi-Agent Collaboration.arXiv preprint arXiv:2506.02049, 2025.
|
||||
|
||||
[^20]: Junde Wu, Jiayuan Zhu, and Yuyuan Liu.Git Context Controller: Manage the Context of LLM-based Agents like Git.arXiv preprint arXiv:2508.00031, 2025.
|
||||
|
||||
[^21]: Carlos E. Jimenez, John Yang, Alexander Wettig, Shunyu Yao, Kexin Pei, Ofir Press, and Karthik R. Narasimhan.SWE-bench: Can Language Models Resolve Real-World GitHub Issues?In *Proceedings of the International Conference on Learning Representations (ICLR)*, 2024. arXiv:2310.06770.
|
||||
|
||||
[^22]: Reem Aleithan, Haoran Xue, Mohammad Mahdi Mohajer, Elijah Nnorom, Gias Uddin, and Song Wang.SWE-Bench+: Enhanced Coding Benchmark for LLMs.arXiv preprint arXiv:2410.06992, 2024.
|
||||
|
||||
[^23]: You Wang, Michael Pradel, and Zhongxin Liu.Are “Solved Issues” in SWE-bench Really Solved Correctly? An Empirical Study.In *Proceedings of the International Conference on Software Engineering (ICSE)*, 2026. Preprint available as arXiv:2503.15223.
|
||||
|
||||
[^24]: pengfeigao1, “Whether using test patch is allowed,” *SWE-bench/experiments*, GitHub issue #16, Jun. 7, 2024. Accessed: Jun. 23, 2026. \[Online\]. Available: [https://github.com/SWE-bench/experiments/issues/16](https://github.com/SWE-bench/experiments/issues/16)
|
||||
@@ -0,0 +1,30 @@
|
||||
---
|
||||
source_url: https://www.sbbit.jp/article/cont1/177512
|
||||
ingested: 2026-06-30
|
||||
sha256: 008cd267d3d4aa158f48a7522a555ed62701d1afa49048c3568e0878fdbfb37f
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521340022077395035'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T02:22:06.394000000Z
|
||||
original_url: https://t.co/hpPNVXOXqf
|
||||
original_context_url: https://x.com/id5763222/status/2071764418531316183
|
||||
message_excerpt: 国産AIを44社連合で開発へ、官民でフィジカルAI推進
|
||||
---
|
||||
- 2025/12/21 掲載
|
||||
|
||||
|
||||
|
||||
19日、政府のAI戦略本部ではフィジカルAIに不可欠な信頼性の高い国産の汎用基盤モデル開発を進める方針が示された。首相は、質の高い産業データを日本の競争力につなげるため、意欲ある企業との連携を強化するよう経済産業相に指示した。
|
||||
|
||||
これを受け経済産業省は、国産AIの研究開発力を強化するため、2026年度から5年間で総額約1兆円規模の公的支援を行う計画を進めている。政府は近く、有識者会議で政策方針の大枠を公表する予定で、2026年度予算案には関連経費として約3000億円を計上する方向だ。財源にはGX経済移行債を充て、低消費電力で稼働するAI基盤モデルの開発を支援する。
|
||||
|
||||
この取り組みの中核として、ソフトバンクを中心に日本企業10社以上が出資する新会社の設立構想が浮上している。新会社は汎用性のある基盤モデルを開発し、その後、民間企業が求める用途に応じて応用する形を想定している。開発したAIは利用料を得る事業モデルとし、投資規模に見合う収益確保を目指す。またソフトバンクは、26年度から6年間でAIの学習・開発に使うデータセンターに2兆円を投じる見込み。
|
||||
|
||||
開発体制には、ソフトバンクやプリファードネットワークスなどから約100人規模の技術者が関与する計画で、AI性能の指標となるパラメーター数は国内最大級となる約1兆を目標に掲げる。開発に必要な高性能半導体や計算資源などの多額の投資については、国が一定部分を補助する。
|
||||
|
||||
政府は、日本が強みを持つ製造業などの現場に蓄積された産業データをAI開発に活用することを重視している。米国や中国の企業が投資規模と技術力で先行する中、日本の産業データが海外勢に流出しかねないとの危機感が背景にある。こうしたデータを国内で活用し、ロボットや機械を自律的に制御する「フィジカルAI」の実現につなげる狙いだ。
|
||||
|
||||
支援は一括ではなく段階的に行われ、2026年度以降は毎年、開発状況を確認した上で、技術水準が一定に達していると判断された場合に追加投資を行う仕組みを採用する。国産AIの開発・提供に必要なデータセンターについては、ソフトバンクが2026年度までの稼働を予定している北海道苫小牧市および大阪府堺市の施設が候補とされている。
|
||||
@@ -0,0 +1,98 @@
|
||||
---
|
||||
source_url: https://gigazine.net/news/20250630-oracle-deno-javascript/
|
||||
ingested: 2026-06-30
|
||||
sha256: 47144881e8db54b4a87c3421a5c036c9fa8d78488658e3eb06b7dca0f87c05b9
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: 1477793137064935675
|
||||
channel_name: tw
|
||||
message_id: 1521415419896922153
|
||||
author_id: 1477793167486226708
|
||||
posted_at: 2026-06-30T07:21:42.635000000Z
|
||||
message_excerpt: JavaScript trademark cancellation dispute involving Oracle evidence based on Node.js images.
|
||||
---
|
||||
|
||||
2025年06月30日 19時00分 [メモ](https://gigazine.net/news/C7/)
|
||||
|
||||
[](https://i.gzn.jp/img/2025/06/30/oracle-deno-javascript/00.jpg)
|
||||
|
||||
|
||||
プログラミング言語「JavaScript」の商標を保有しているOracleに対し、多数のエンジニアらが商標の取り消しを求めた審判で、Oracleは第三者が立ち上げたプロジェクトの画像を商用利用の証拠として提出しました。この点について当該プロジェクトの当事者が「Oracleの行為は欺瞞(ぎまん)的である」と指摘していたのですが、当局はこの主張を証拠不十分で却下しました。
|
||||
|
||||
**JavaScript™ Trademark Update | Deno**
|
||||
**[https://deno.com/blog/deno-v-oracle4](https://deno.com/blog/deno-v-oracle4)**
|
||||
|
||||
JavaScriptはOracleが商標を保有していますが、JavaScriptという言葉は一般的な用語として広く認識されているとして、エンジニアら1万4000人以上の署名をもって商標を開放するよう求める運動が展開されています。
|
||||
|
||||
|
||||
JavaScriptの実行環境である「Deno」や「Node.js」を開発したライアン・ダール氏らが申立人となり、「1:一般名称化」「2:詐欺」「3:放棄」の3点を申し立ての根拠としています。
|
||||
|
||||
**・1:JavaScriptは汎用的である**
|
||||
「JavaScript」という用語は、プログラミング言語の一般的な名前になりました。これは、Oracleとはまったく関係ない場所で、世界中の何百万もの開発者や組織によって使用されています。法律により、一般名称となった商標は商標のままではいられません。JavaScriptはブランドではなく、現代のプログラミングの基礎です。
|
||||
|
||||
**・2:Oracleは過去に虚偽の申請をした**
|
||||
Oracleは2019年にJavaScriptの商標を更新した際、Oracleとはまったく無関係な、ダール氏が立ち上げたプロジェクト「Node.js」のスクリーンショットをUSPTOに提出しました。Node.jsをOracleの「商用利用」の証拠として提示することは、商標法の完全性に違反します。USPTOが商標を更新するためにこの虚偽の証拠に依拠した場合は、商標の更新が無効になる可能性があります。
|
||||
|
||||
**・3:商標は放棄された**
|
||||
Oracleは長年にわたり「JavaScript」という名前で重要な製品やサービスを提供していません。アメリカの法律では、3年連続で使用されていない商標は放棄されたものとみなされ、Oracleの不作為は明らかにこの基準を満たしています。
|
||||
|
||||
**[「JavaScript」の商標を持つOracleが商標の開放を求められるも「自主的に取り下げるつもりはない」と拒否 - GIGAZINE](https://gigazine.net/news/20250109-trademark-javascript/)**
|
||||
|
||||
[](https://gigazine.net/news/20250109-trademark-javascript/)
|
||||
|
||||
|
||||
2025年6月18日、商標審判・控訴委員会(TTAB)は、上記のうち「詐欺」の主張を却下しました。TTABは、「詐欺の主張が法的に十分ではない」と指摘しています。
|
||||
|
||||
申立人には、詐欺の主張を修正して再提出する機会が認められ、2025年7月8日までに修正申立書を提出することが許されています。
|
||||
|
||||
この判断についてダール氏は異議を唱えましたが、詐欺の主張を修正すると申し立ての進行が数カ月遅れてしまうとして、修正はしない方針です。
|
||||
|
||||
[](https://i.gzn.jp/img/2025/06/30/oracle-deno-javascript/01.jpg)
|
||||
|
||||
|
||||
ダール氏は「JavaScriptが商用利用されているということを証明するために、Oracleは無関係なNode.jsのウェブサイトの画像を提出し、アメリカ特許商標庁を故意にだまそうとしました。Node.jsの創始者として、この行為は特に許しがたいものです。Node.jsはOracleの製品やブランドではありません。Oracleはそれを開発せず、運営せず、商用利用の証拠として使用する権限もありませんでした。第三者のオープンソースサイトを証拠として提出したことは、彼らがもっと良い証拠を持っていなかったことを証明しています」と指摘しました。
|
||||
|
||||
ダール氏は、本件の本質は詐欺ではなく、JavaScriptを開放すること(一般名称化と放棄)にあるとして、詐欺の主張は修正せず、申し立てを続行することにしました。Oracleは2025年8月7日までに一般名称化及び放棄に関する主張を認めるか否かを回答しなければなりません。
|
||||
|
||||
ダール氏は「この取消しに勝訴するか、Oracleが正しいことを行い商標を開放すれば、JavaScriptは自由になります」と述べました。
|
||||
|
||||
インターネットユーザーは「Oracleはエンジニアリング部門より法務部門の方が規模がデカい」と **[揶揄](https://newsletter.pragmaticengineer.com/p/code-review-on-printed-paper-an-excerpt)** しています。
|
||||
|
||||
[](https://i.gzn.jp/img/2025/06/30/oracle-deno-javascript/02.jpg)
|
||||
|
||||
**・関連記事**
|
||||
**[「JavaScript」はここから始まった、1995年のJavaScriptリリースはこんな感じ - GIGAZINE](https://gigazine.net/news/20201216-javascript-initial-release)**
|
||||
|
||||
**[Googleに1兆円の損害賠償請求したOracleが控訴審で逆転勝訴 - GIGAZINE](https://gigazine.net/news/20180329-oracle-beat-google)**
|
||||
|
||||
**[Googleが「コードが著作権の対象になる」という裁判所判断はソフトウェア開発の未来を左右するとして対Oracle訴訟について嘆願書を提出 - GIGAZINE](https://gigazine.net/news/20190125-oracle-google-code-copyright)**
|
||||
|
||||
**[GoogleとOracleが繰り広げる訴訟で「APIは著作権保護対象か否か」について最高裁判所が審理に乗り出すことに - GIGAZINE](https://gigazine.net/news/20191118-supreme-court-api-copyright-lawsuit)**
|
||||
|
||||
**[GoogleとOracleが「APIの著作権」を巡って最高裁判所の口頭弁論で対決、Googleが不利との見方 - GIGAZINE](https://gigazine.net/news/20201009-google-oracle-supreme-court-api)**
|
||||
|
||||
**[約1兆円の賠償金を巡るGoogleとOracleの10年にわたる訴訟が決着、「APIのコピー」は結局違法なのか? - GIGAZINE](https://gigazine.net/news/20210406-supremecourt-google-oracle)**
|
||||
|
||||
|
||||
**・関連コンテンツ**
|
||||
|
||||
- [](https://gigazine.net/news/20250109-trademark-javascript/)
|
||||
[「JavaScript」の商標を持つOracleが商標の開放を求められるも「自主的に取り下げるつもりはない」と拒否](https://gigazine.net/news/20250109-trademark-javascript/)
|
||||
- [](https://gigazine.net/news/20210210-prepear-apple-settle-dispute/)
|
||||
[「ロゴがそっくりだ」として問題になっていたAppleとPrepearの商標権争いが無事解決](https://gigazine.net/news/20210210-prepear-apple-settle-dispute/)
|
||||
- [](https://gigazine.net/news/20171130-starbucks-loses-trademark-lawsuit/)
|
||||
[スタバが森永の「マウントレーニア」のロゴが似ていると訴訟を起こすも、類似性はないと判決](https://gigazine.net/news/20171130-starbucks-loses-trademark-lawsuit/)
|
||||
- [](https://gigazine.net/news/20251217-x-sues-operation-bluebird-twitter-brand/)
|
||||
[あの頃のTwitterを取り戻すべく立ち上がった「Operation Bluebird」をイーロン・マスクのXが訴える](https://gigazine.net/news/20251217-x-sues-operation-bluebird-twitter-brand/)
|
||||
- [](https://gigazine.net/news/20180112-violating-website-terms-not-crime/)
|
||||
[「ウェブサイトの利用規約に反することは犯罪ではない」と判決](https://gigazine.net/news/20180112-violating-website-terms-not-crime/)
|
||||
- [](https://gigazine.net/news/20090826_google_top10_myths/)
|
||||
[「Googleのインデックスやランク付けなどに関する10の誤解」をGoogleが公式ブログにて公開](https://gigazine.net/news/20090826_google_top10_myths/)
|
||||
- [](https://gigazine.net/news/20210406-supremecourt-google-oracle/)
|
||||
[約1兆円の賠償金を巡るGoogleとOracleの10年にわたる訴訟が決着、「APIのコピー」は結局違法なのか?](https://gigazine.net/news/20210406-supremecourt-google-oracle/)
|
||||
- [](https://gigazine.net/news/20191118-supreme-court-api-copyright-lawsuit/)
|
||||
[GoogleとOracleが繰り広げる訴訟で「APIは著作権保護対象か否か」について最高裁判所が審理に乗り出すことに](https://gigazine.net/news/20191118-supreme-court-api-copyright-lawsuit/)
|
||||
|
||||
2025年06月30日 19時00分00秒 in [メモ](https://gigazine.net/news/C7/), Posted by log1p\_kr
|
||||
|
||||
You can read the machine translated English article **[In a lawsuit seeking to free the 'JavaSc…](https://gigazine.net/gsc_news/en/20250630-oracle-deno-javascript)**.
|
||||
@@ -0,0 +1,116 @@
|
||||
---
|
||||
source_url: https://www.jaxa.jp/press/2026/06/20260630-1_j.html
|
||||
ingested: 2026-06-30
|
||||
sha256: ead6deaf9a0d2a51b00868373b598e2d9618dcd80b8e8f54cf4dd9e85f6b1280
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521355036448391169'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T03:21:46.099000000Z
|
||||
message_excerpt: 'JAXA AMSR3 data products for weather, fishery, and vessel support.'
|
||||
score: 2
|
||||
---
|
||||
|
||||
[組織情報](https://www.jaxa.jp/about/index_j.html)
|
||||
|
||||
[理事長挨拶](https://www.jaxa.jp/about/president/index_j.html)
|
||||
|
||||
[理事長定例記者会見](https://www.jaxa.jp/about/president/presslec/201902_j.html)
|
||||
|
||||
JAXA理念・ビジョン
|
||||
|
||||
事業計画
|
||||
|
||||
事業情報・報告
|
||||
|
||||
内部統制・コンプライアンスの取り組み
|
||||
|
||||
[寄附金](https://www.jaxa.jp/about/donations/index_j.html)
|
||||
|
||||
[採用情報](https://www.jaxa.jp/about/employ/index_j.html)
|
||||
|
||||
[ワーク・ライフ変革推進室](http://stage.tksc.jaxa.jp/geoffice/)
|
||||
|
||||
[事業内容](https://www.jaxa.jp/projects/index_j.html)
|
||||
|
||||
活動内容
|
||||
|
||||
アーカイブス
|
||||
|
||||
年間活動実績
|
||||
|
||||
過去のプロジェクトデータ
|
||||
|
||||
## プレスリリース・記者会見等
|
||||
|
||||
- [TOP](https://www.jaxa.jp/index_j.html) \>
|
||||
- [プレスリリース・記者会見等](https://www.jaxa.jp/press/) \>
|
||||
- 水循環を観測するセンサAMSR3のデータ提供開始 \>
|
||||
|
||||
## 水循環を観測するセンサAMSR3のデータ提供開始-気象予報精度向上や漁業・船舶航行を支援-
|
||||
|
||||
2026年(令和8年)6月30日
|
||||
|
||||
国立研究開発法人宇宙航空研究開発機構
|
||||
|
||||
宇宙航空研究開発機構(以下「JAXA」)は、気象予報精度向上などに貢献する次世代観測センサ「高性能マイクロ波放射計3(AMSR3)」のデータ(標準プロダクト <sup><a href="https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_01">※1</a></sup> )提供を、本日6月30日より開始します。AMSR3は、温室効果ガス・水循環観測技術衛星「いぶきGW」(GOSAT-GW)に搭載された観測センサです。本データは、日々の気象予報および水災害をもたらす豪雨・台風の進路予測の精度向上に貢献するほか、漁業における好漁場探索や、効率的な船舶航行の支援などにも役立てられます。
|
||||
|
||||
### 標準プロダクトの内容
|
||||
|
||||
2026年6月末をもってAMSR3の初期校正・検証作業 <sup><a href="https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_02">※2</a></sup> を完了し、標準プロダクトの提供を開始します。提供する標準プロダクトは、「輝度温度プロダクト」と「地球物理量プロダクト」の2種類で構成されます。
|
||||
|
||||
- 輝度温度プロダクト:AMSR3が捉えるマイクロ波の強さを、温度に変換した基礎となるもの
|
||||
- 地球物理量プロダクト:輝度温度プロダクトをもとに、「降水量」や「海面水温」など、地球の水に関する量を算出して情報化したもの
|
||||
|
||||
今回提供を開始するプロダクトの一例として、地球物理量プロダクトの一つである降水量プロダクトについて、 [図1](https://www.jaxa.jp/press/2026/06/20260630-1_j.html#figure_01) に示します。
|
||||
|
||||

|
||||
|
||||
©JAXA 図1: AMSR2(左)とAMSR3(右)による月平均降水量(2026年3月)の比較 白は降水量0mm/h、色付きは降水量の分布、グレーは欠損域を示す。 AMSR3では、高緯度域を含むより広い範囲で降水量を推定できている。
|
||||
|
||||
### 開発の背景とAMSR3の特徴
|
||||
|
||||
約25年の水循環変動観測の実績を持つAMSRシリーズ <sup><a href="https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_04">※4</a></sup> は、地球の表面(陸・海)や大気などから自然に発せられるマイクロ波を観測し、水循環に関する様々な情報(海面水温、降水量、海上風速、海氷密接度、積雪深、土壌水分量など)を捉えています。
|
||||
AMSR3を開発した背景として、先代にあたるAMSR2を設計寿命の5年を超えて運用している現状がありました。そのため、AMSR2のミッションを継続するとともに、利用者の新たなニーズに応えるためにAMSR3を開発しました。
|
||||
こうした経緯を踏まえAMSR3では、雪や高層の水蒸気などに感度がある5つの新しいチャネル <sup><a href="https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_05">※5</a></sup> を追加しております。新チャネルにより、高緯度帯を含む全球規模の降水(降雨・降雪)全容を詳細に観測することが可能になり、気象庁・各国気象機関が行う数値予報による日々の気象予報、および台風進路予測などの精度向上への貢献が期待されています。
|
||||
|
||||
### プロダクト活用例
|
||||
|
||||
① 気象予報
|
||||
雨だけでなく雪も含めた降水量の推定や水蒸気の情報の把握に役立ちます。新たに追加した高周波チャネル <sup><a href="https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_06">※6</a></sup> による輝度温度プロダクトは、気象庁や各国気象機関が日々の気象予報に用いる数値気象モデルに導入される予定です。現在その準備を進めており、豪雨の発生範囲や、台風の進路・勢力の予測精度が向上すると期待されています。
|
||||
また、このプロダクトは、豪雨や干ばつといった水に関する災害の監視などにも使われているJAXAの衛星全球降水マップ(GSMaP)にも活用されます。さらに「水災害・水資源管理」という重点テーマ <sup><a href="https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_07">※7</a></sup> のもとで目指している国際協力・産業上の便益創出に向けても、重要な役割を果たします。
|
||||
|
||||
② 漁業
|
||||
魚は種類ごとに、好む水温が異なります。雲を透過して定常的に観測できるAMSRシリーズの海面水温プロダクトは、魚が集まりやすい漁場を探すのに役立ちます。
|
||||
これまでのAMSR2では、沿岸に近い海域の海面水温を正確に把握することが難しく、主に沖合や遠洋での漁業に利用されてきました。AMSR3では、利用者の要望を踏まえて新しい周波数帯を追加したことで、従来よりも沿岸に近い海域の海面水温や海上の風速も把握できるようになりました。これによりイワシ・サバ・アジなどが多く生息する大陸棚の海域も観測できるようになり、魚の種類に応じた効率的な漁場探索に貢献します。また、漁業者の負担軽減や操業判断の高度化、さらには養殖業における環境管理にも役立ちます。
|
||||
|
||||
③ 航行支援
|
||||
船舶が安全かつ効率よく航行するためには、海面水温の把握が重要です。例えば日本周辺では、暖流である黒潮の流れを把握するために、海面水温の情報が使われています。可視光や赤外線のセンサで観測する「ひまわり」などの気象衛星は、雲に遮られると海面の様子を捉えにくくなることがあります。一方AMSR3は、雲の影響を受けにくいマイクロ波で観測できるため、黒潮の流れを安定して把握することができ、船舶の経済的な航行に役立ちます。
|
||||
さらに、南極観測船「しらせ」のように、極域や海氷域を航行する船舶では、海氷の情報が航路を決めるうえで欠かせません。極域では、冬になると太陽光が届かず、雲に覆われることも多いため一般的な観測手段では十分な情報を得ることが難しくなります。その点で、雲を透過し広い範囲を繰り返し観測できるAMSRシリーズのプロダクトは非常に重要です。AMSR3が提供する海氷密接度や海氷の移動情報のプロダクトは、こうした環境での航路判断を支え、極域における安全な航行に貢献します。
|
||||
|
||||
### 提供プロダクトの利用方法
|
||||
|
||||
以上
|
||||
|
||||
1. ※1 標準プロダクト
|
||||
プロダクトとは、衛星が取得した観測データを、ユーザが利用しやすいように処理・解析し、ファイル化したものです。標準プロダクトは、ミッションの目的達成に必要な基本的なプロダクトとして、これまでの観測実績や検証結果を踏まえてJAXAが提供するものです。
|
||||
2. ※2 初期校正・検証作業
|
||||
AMSR3が取得した観測データについて、センサ特性や地上処理系を評価し、必要な補正・調整を行うことで、輝度温度および地球物理量の精度向上を図る作業です。
|
||||
3. ※3 降雪
|
||||
地球物理量プロダクトの一つである降水量プロダクトには、降雨と降雪が含まれます。熱帯域では主に降雨を、地表面が0℃以下の高緯度帯では降雪を示します。
|
||||
4. ※4 AMSRシリーズ
|
||||
AMSRシリーズは、2002年打上げの米国Aqua衛星搭載のAMSR-E、同じく2002年打上げの「みどりII」(ADEOS-II)搭載のAMSR、2012年打上げの「しずく」(GCOM-W)搭載のAMSR2があります。
|
||||
5. ※5 雪や高層の水蒸気などに感度がある5つの新しいチャネル
|
||||
AMSR2には降雪や高層の水蒸気に感度のある周波数帯がなかったため、数値気象予報や台風進路予測などでの貢献が限定的でした。AMSR3の新規5チャネルのうちの165.5, 183.3±7, 183.3±3 GHzにより、この課題を克服しています。
|
||||
6. ※6 新たに追加した高周波チャネル
|
||||
[※5](https://www.jaxa.jp/press/2026/06/20260630-1_j.html#note_05) に記載した165.5, 183.3±7, 183.3±3 GHzの3つの高周波チャネルが該当します。これらの周波数は雲の中に漂う氷粒子や地上に降り注ぐ雪、中層・上層の水蒸気などにより高い感度を持ち、気象予測の精度向上に貢献できます。
|
||||
これら3チャネルを含め、新設の5チャネルの特徴については [2025年9月5日付プレスリリース『「いぶきGW」(GOSAT-GW)搭載 高性能マイクロ波放射計3(AMSR3)の初期観測結果』の図1](https://www.jaxa.jp/press/2025/09/20250905-1_j.html#pic_01) などをご参照ください。
|
||||
7. ※7 「水災害・水資源管理」という重点テーマ
|
||||
地球観測衛星データサイトEarth-graphy「 [重点テーマ:水災害・水資源管理](https://earth.jaxa.jp/ja/strategic-priorities/water/index.html) 」のウェブページをご参照ください。
|
||||
8. ※8 提供するプロダクトの利用例については、こちらをご参照ください。 [利用事例(G-Portal)](https://gportal.jaxa.jp/gpr/notice/case/list/2018)
|
||||
|
||||
[宇宙航空研究開発機構](https://www.jaxa.jp/index_j.html)
|
||||
|
||||
[PAGE TOP](https://www.jaxa.jp/press/2026/06/20260630-1_j.html#)
|
||||
@@ -0,0 +1,62 @@
|
||||
---
|
||||
source_url: https://forest.watch.impress.co.jp/docs/news/2120998.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 4d24971bba09bf7d55dc19cdfe9415fdaab3425bdb44e1487f0c05c0c8b6e07c
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521400285082419262'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T06:21:34.214000000Z
|
||||
message_excerpt: 'Amazon、AI統合開発環境「Kiro IDE 1.0」を公開。仕様駆動でエージェントに作らせる新UIという切り口。'
|
||||
---
|
||||
|
||||
2026年6月30日 14:20
|
||||
|
||||
[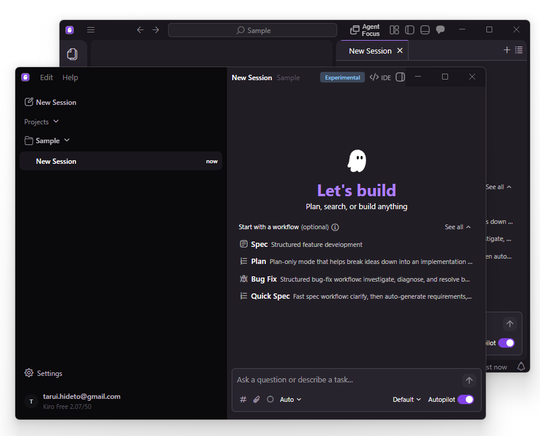](https://forest.watch.impress.co.jp/docs/2120/998/html/image1.png.html)
|
||||
|
||||
デスクトップ版「Kiro IDE」がv1.0に到達。エージェントファーストの新UI「Agent Focus」を導入
|
||||
|
||||
米Amazonは6月25日(現地時間)、「Kiro IDE 1.0」をリリースした。「Kiro」は“仕様駆動”型のAIコーディング環境。 [2025年7月](https://forest.watch.impress.co.jp/docs/news/2031398.html) にプレビュー公開され、同年11月17日に一般提供が開始されたが、今回ようやく統合開発環境(IDE)がv1.0の節目に到達した。
|
||||
|
||||
関連記事
|
||||
|
||||
- [](https://forest.watch.impress.co.jp/docs/news/2031398.html)
|
||||
- 生成AI
|
||||
- AIコーディング
|
||||
[米Amazon、AIエージェントを前提にした“仕様駆動”型の統合開発環境「Kiro」を発表](https://forest.watch.impress.co.jp/docs/news/2031398.html)
|
||||
|
||||
「Kiro」は、開発者が定めた仕様(スペック)をもとに、AIエージェントが実現に必要な大小さまざまなタスクを立案し、その実行を開発者が制御するという開発スタイルに特化したソリューション。デスクトップで動作する「Visual Studio Code」ベースの「Kiro IDE」(Windows/macOS/Linuxに対応)、ターミナルから利用する「Kiro CLI」、Webブラウザーから使える「Kiro Web」、さらにiOS向けのモバイルアプリがラインナップされており、さまざまな環境から利用できる。
|
||||
|
||||
[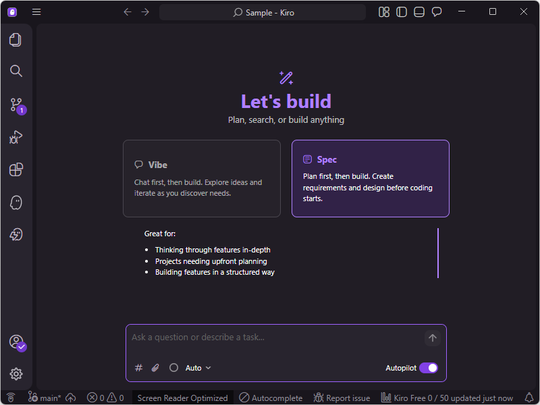](https://forest.watch.impress.co.jp/img/wf/docs/2120/998/html/image4.png.html)
|
||||
|
||||
開発者が定めた仕様(スペック)をもとに、AIエージェントが実現に必要な大小さまざまなタスクを立案し、その実行を開発者が制御する(v0.xの画面)
|
||||
|
||||
なお、「Kiro」でエージェントを実行するにはクレジットが必要。無償プランでは月に50クレジットが付与される。それを超えて利用するには、有償プランへのアップグレードが必要。有償プランであれば、上限を超えた分を追加クレジットとして購入することもできる。
|
||||
|
||||
[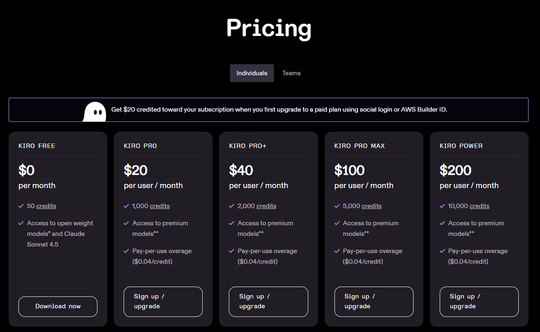](https://forest.watch.impress.co.jp/docs/2120/998/html/image2.png.html)
|
||||
|
||||
「Kiro」の料金体系
|
||||
|
||||
「Kiro IDE 1.0」における目玉は、エージェントファーストの実験的なウィンドウレイアウト「Agent Focus」だ。従来のレイアウトはコードやドキュメントが中心であったが、「Agent Focus」はその名の通り、エージェントを中心に据えている。セッションリストが左ペイン、会話がメインパネル、スペックや差分(Diff)が右側の補助パネルに表示され、開発者はコードを直接修正するのではなく、エージェントへの指示に専念する仕組みだ。
|
||||
|
||||
従来のエディター表示と「Agent Focus」は、画面右上のボタンでいつでも切り替えが可能。好みに応じて使い分けるとよいだろう。
|
||||
|
||||
[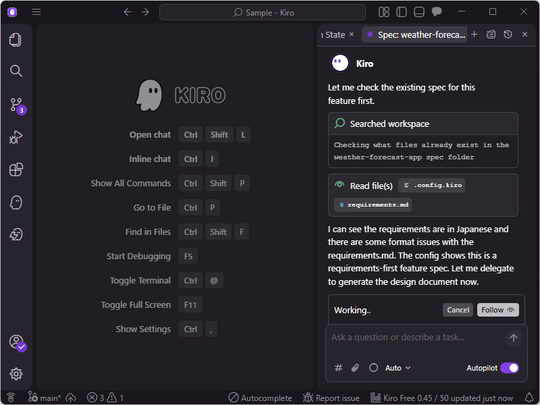](https://forest.watch.impress.co.jp/docs/2120/998/html/image3.png.html)
|
||||
|
||||
従来のレイアウトはコードやドキュメントが中心であった(v0.xの画面)
|
||||
|
||||
そのほかにも、以下の新機能や改善が加えられた。
|
||||
|
||||
- **エージェントの権限を細かく制御** :ケイパビリティ(capability)ベースの権限システムを導入。エージェントはファイルの書き込み、コマンドの実行、MCPツールの呼び出しといった操作ごとにユーザーへ承認を求めるが、「常に許可」「常に拒否」はルールとして保存され、ワークスペース単位、あるいはすべてのワークスペースに適用される
|
||||
- **カスタムエージェントをMarkdownで定義** :目的に応じた専用エージェントを手軽に作成。MCPサーバーや権限ルールをエージェントのプロフィールに直接埋め込める。ファイルはバージョン管理を通じてチームで共有することも可能
|
||||
- **自然言語でフックを作成** :「フック」とは、特定の処理をトリガーにタスクを自動実行すること。やりたいことを言葉で説明すると、「Kiro」がフックの構成を生成してくれる
|
||||
- **チャットのドッキングとセッションのエクスポート** :チャットのセッションを、幅いっぱいのエディタータブとして開いたり、ドッキングできるように。会話全体をZIP書庫ファイルとしてエクスポートすることも可能
|
||||
|
||||
なお、v0.xからフックやセッションの形式が変更されている。そのため、パネルから移行操作を行う必要がある点には注意したい。
|
||||
|
||||
Amazonで購入
|
||||
|
||||
- [](https://www.amazon.co.jp/s?k=Claude?tag=impresswatch-18-22&ref=nosim)
|
||||
[「Claude」関連商品](https://www.amazon.co.jp/s?k=Claude&tag=impresswatch-18-22&ref=nosim) [Amazonで購入](https://www.amazon.co.jp/s?k=Claude&tag=impresswatch-18-22&ref=nosim)
|
||||
@@ -0,0 +1,701 @@
|
||||
---
|
||||
source_url: https://github.com/sopaco/deepwiki-rs
|
||||
ingested: 2026-06-30
|
||||
sha256: 2eeb8dd3258b7700dfd5f47cb665752776b5e5b6e8f809bb5cfa499d9084a3ae
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: 1477793137064935675
|
||||
channel_name: tw
|
||||
message_id: 1521415419896922153
|
||||
author_id: 1477793167486226708
|
||||
posted_at: 2026-06-30T07:21:42.635000000Z
|
||||
message_excerpt: Litho / deepwiki-rs: Rust tool generating C4 architecture diagrams and wiki-like docs from source code.
|
||||
---
|
||||
|
||||
<p align="center">
|
||||
<img height="160" src="./assets/banner_litho.webp">
|
||||
</p>
|
||||
|
||||
<h3 align="center">Litho (deepwiki-rs)</h3>
|
||||
|
||||
<p align="center">
|
||||
<a href="./README.md">English</a>
|
||||
|
|
||||
<a href="./README_zh.md">中文</a>
|
||||
</p>
|
||||
<p align="center">💪🏻 High-performance <strong>AI-driven</strong> intelligent document generator (DeepWiki-like) built with <strong>Rust</strong></p>
|
||||
<p align="center">📚 Automatically generates high quality <strong>Repo-Wiki</strong> for any codebase</p>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://crates.io/crates/deepwiki-rs"><img src="https://img.shields.io/crates/v/deepwiki-rs?color=44a1c9" /></a>
|
||||
<a href="https://crates.io/crates/deepwiki-rs"><img src="https://img.shields.io/crates/d/deepwiki-rs.svg" /></a>
|
||||
<a href="https://github.com/sopaco/deepwiki-rs/tree/main/docs/en"><img alt="Litho Docs" src="https://img.shields.io/badge/Litho-Docs-green?logo=Gitbook&color=%23008a60"/></a>
|
||||
<a href="https://github.com/sopaco/deepwiki-rs/tree/main/docs/zh"><img alt="Litho Docs" src="https://img.shields.io/badge/Litho-中文-green?logo=Gitbook&color=%23008a60"/></a>
|
||||
<img alt="GitHub Actions Workflow Status" src="https://img.shields.io/github/actions/workflow/status/sopaco/deepwiki-rs/rust.yml">
|
||||
</p>
|
||||
|
||||
<hr />
|
||||
|
||||
# 👋 What's Litho
|
||||
|
||||
**Litho** is an AI-powered documentation generation engine that automatically analyzes your source code and generates comprehensive, professional architecture documentation in the C4 model format. No more manual documentation that falls behind code changes - Litho keeps your documentation perfectly in sync with your codebase.
|
||||
|
||||
Litho transforms raw code into beautifully structured documentation with context diagrams, container diagrams, component diagrams, and code-level documentation - all automatically generated from your source code.
|
||||
|
||||
Whether you're a developer, architect, or technical lead, Litho eliminates the burden of maintaining documentation and ensures your team always has accurate, up-to-date architectural information.
|
||||
|
||||
<p align="center">
|
||||
<strong>Transform your codebase into professional architecture documentation in minutes</strong>
|
||||
</p>
|
||||
|
||||
<div style="text-align: center; margin: 30px 0;">
|
||||
<table style="width: 100%; border-collapse: collapse; margin: 0 auto;">
|
||||
<tr>
|
||||
<th style="width: 50%; padding: 15px; background-color: #f8f9fa; border: 1px solid #e9ecef; text-align: center; font-weight: bold; color: #495057;">Before Litho</th>
|
||||
<th style="width: 50%; padding: 15px; background-color: #f8f9fa; border: 1px solid #e9ecef; text-align: center; font-weight: bold; color: #495057;">After Litho</th>
|
||||
</tr>
|
||||
<tr>
|
||||
<td style="padding: 15px; border: 1px solid #e9ecef; vertical-align: top;">
|
||||
<p style="font-size: 14px; color: #6c757d; margin-bottom: 10px;"><strong>Manual Documentation</strong></p>
|
||||
<ul style="font-size: 13px; color: #6c757d; line-height: 1.6;">
|
||||
<li>Outdated, incomplete, or missing documentation</li>
|
||||
<li>Manual updates that fall behind code changes</li>
|
||||
<li>Inconsistent formatting and structure</li>
|
||||
<li>Time-consuming to maintain</li>
|
||||
<li>Hard to navigate and understand</li>
|
||||
<li>Usually just a few markdown files</li>
|
||||
</ul>
|
||||
</td>
|
||||
<td style="padding: 15px; border: 1px solid #e9ecef; vertical-align: top;">
|
||||
<p style="font-size: 14px; color: #6c757d; margin-bottom: 10px;"><strong>AI-Generated Documentation</strong></p>
|
||||
<ul style="font-size: 13px; color: #6c757d; line-height: 1.6;">
|
||||
<li>Automatically generated from codebase</li>
|
||||
<li>Always up-to-date with code changes</li>
|
||||
<li>Professional C4 model structure</li>
|
||||
<li>Consistent formatting and styling</li>
|
||||
<li>Easy to navigate and understand</li>
|
||||
<li>Complete with diagrams, context, and relationships</li>
|
||||
</ul>
|
||||
</td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
<p align="center">
|
||||
<strong>🚀 Litho automatically transforms your messy codebase into beautiful, professional documentation</strong>
|
||||
</p>
|
||||
|
||||
<hr />
|
||||
|
||||
# 😺 Why use Litho
|
||||
|
||||
- **Automatically keep documentation in sync** with codebase changes - no more outdated docs
|
||||
- **Save hundreds of hours** on manual documentation creation and maintenance
|
||||
- **Improve onboarding** for new team members with comprehensive, up-to-date documentation
|
||||
- **Enhance code reviews** by providing clear architectural context
|
||||
- **Meet compliance requirements** with auditable, automated documentation
|
||||
- **Support for multiple programming languages** (Rust, Python, Java, Go, C#, JavaScript, etc.)
|
||||
- **Generate professional C4 model diagrams** with context, containers, components, and code
|
||||
- **Integrate with CI/CD pipelines** to automatically generate documentation on every commit
|
||||
|
||||
🌟 **For:**
|
||||
- Development teams of all sizes
|
||||
- Open source projects
|
||||
- Enterprise software developers
|
||||
- Anyone who hates maintaining outdated docs!
|
||||
|
||||
❤️ Like **Litho**? Star it 🌟 or [Sponsor Me](https://github.com/sponsors/sopaco)! ❤️
|
||||
|
||||
**Thanks to the kind people**
|
||||
|
||||
[](https://github.com/sopaco/deepwiki-rs/stargazers)
|
||||
|
||||
# 🌠 Features & Capabilities
|
||||
|
||||
### Core Capabilities
|
||||
- AI-driven architecture documentation generation from codebase analysis
|
||||
- Automatic C4 model diagram creation (Context, Container, Component, Code)
|
||||
- Intelligent extraction of code comments, structures, and relationships
|
||||
- Multi-language support for various programming languages
|
||||
- Customizable template system for documentation output
|
||||
|
||||
### Advanced Features
|
||||
- **External Knowledge Integration** - Mount external documentation (PDF, Markdown, SQL, etc.) as knowledge sources for enhanced analysis
|
||||
- **Database Documentation** - Auto-generate database schema documentation with ERD diagrams for SQL projects
|
||||
- Git history analysis for tracking architectural evolution
|
||||
- Cross-referencing between code elements and documentation
|
||||
- Interactive documentation with embedded diagrams and examples
|
||||
- Integration with CI/CD pipelines for automated documentation generation
|
||||
|
||||
## 💡 Problem Solved
|
||||
Litho solves the common problem of outdated and incomplete technical documentation by automatically generating up-to-date architecture documentation from your source code. No more manual documentation that falls behind code changes - Litho keeps your documentation in sync with your codebase.
|
||||
|
||||
# 🌐 Litho Eco Ecosystem
|
||||
Litho is part of a broader ecosystem of tools designed to enhance developer productivity and documentation quality. The Litho Eco ecosystem includes complementary tools that work seamlessly with Litho to provide a complete documentation workflow:
|
||||
|
||||
## 📘 Litho Book
|
||||
**Litho Book** is a high-performance markdown reader built with Rust and Axum, specifically designed to provide an elegant interface for browsing documentation generated by Litho.
|
||||
|
||||
### Key Features
|
||||
- Real-time markdown rendering with syntax highlighting
|
||||
- Full Mermaid chart support for architectural diagrams
|
||||
- Intelligent search with fuzzy matching for files and content
|
||||
- High-performance architecture with low memory usage
|
||||
- AI Intelligent Document Interpretation, Answering Questions
|
||||
|
||||
### 🌠 Snapshots
|
||||
<div style="text-align: center;">
|
||||
<table style="width: 100%; margin: 0 auto;">
|
||||
<tr>
|
||||
<td style="width: 50%;"><img src="https://github.com/sopaco/litho-book/blob/main/assets/snapshot-1.webp?raw=true" alt="snapshot-1" style="width: 100%; height: auto; display: block;"></td>
|
||||
<td style="width: 50%;"><img src="https://github.com/sopaco/litho-book/blob/main/assets/snapshot-2.webp?raw=true" alt="snapshot-2" style="width: 100%; height: auto; display: block;"></td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
### Integration with Litho
|
||||
Litho Book serves as the ideal companion application for consuming documentation generated by Litho. The typical workflow is:
|
||||
1. Use Litho to generate documentation from your codebase
|
||||
2. Use Litho Book to browse and explore the generated documentation with an elegant interface
|
||||
|
||||
[Learn more about Litho Book](https://github.com/sopaco/litho-book)
|
||||
|
||||
## 🔧 Mermaid Fixer
|
||||
**Mermaid Fixer** is a high-performance AI-driven tool that automatically detects and fixes syntax errors in Mermaid diagrams within Markdown files.
|
||||
|
||||
### Key Features
|
||||
- Automated scanning of directories for Markdown files
|
||||
- Precise detection of Mermaid syntax errors using JS sandbox validation
|
||||
- AI-powered intelligent fixing with LLM integration
|
||||
- Comprehensive reporting of before/after changes
|
||||
- Flexible configuration with support for multiple LLM providers
|
||||
|
||||
### Integration with Litho
|
||||
Mermaid Fixer enhances the quality of documentation generated by Litho by automatically fixing syntax errors in Mermaid diagrams. This ensures that all architectural diagrams in your documentation are valid and render correctly.
|
||||
|
||||
### 👀 Snapshots
|
||||
<div style="text-align: center;">
|
||||
<table style="width: 100%; margin: 0 auto;">
|
||||
<tr>
|
||||
<td style="width: 50%;"><img src="https://github.com/sopaco/mermaid-fixer/blob/main/assets/snapshot-1.webp?raw=true" alt="snapshot-1" style="width: 100%; height: auto; display: block;"></td>
|
||||
<td style="width: 50%;"><img src="https://github.com/sopaco/mermaid-fixer/blob/main/assets/snapshot-2.webp?raw=true" alt="snapshot-2" style="width: 100%; height: auto; display: block;"></td>
|
||||
</tr>
|
||||
</table>
|
||||
</div>
|
||||
|
||||
[Learn more about Mermaid Fixer](https://github.com/sopaco/mermaid-fixer)
|
||||
|
||||
## 🤖Agent Skills
|
||||
Run in Smithery! [](https://smithery.ai/skills?ns=sopaco&utm_source=github&utm_medium=badge)
|
||||
|
||||
# 🧠 How it works
|
||||
[](https://zread.ai/sopaco/deepwiki-rs)
|
||||
|
||||
## Four-Stage Processing Pipeline
|
||||
Litho's architecture is designed around a four-stage processing pipeline that transforms raw code into comprehensive documentation:
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Input: Source Code Repository] --> B[Phase 1: Preprocessing]
|
||||
B --> C[Phase 2: Intelligent Research & Analysis]
|
||||
C --> D[Phase 3: Documentation Generation]
|
||||
D --> E[Phase 4: Verification & Enhancement]
|
||||
E --> F[Output: High-Quality Technical Documentation]
|
||||
|
||||
subgraph Preprocessing Phase
|
||||
B1[Code Scanning & Discovery]
|
||||
B2[Multi-Language Syntax Analysis]
|
||||
B3[Structure & Dependency Extraction]
|
||||
B4[Code Insight Generation]
|
||||
B5[Agent Memory Chunk Initialization]
|
||||
B --> B1 --> B2 --> B3 --> B4 --> B5
|
||||
end
|
||||
|
||||
subgraph Intelligent Research & Analysis Phase
|
||||
C1[System Context Researcher]
|
||||
C2[Domain Module Detector]
|
||||
C3[Workflow Researcher]
|
||||
C4[Boundary Analyzer]
|
||||
C5[Key Module Insight Officer]
|
||||
C6[Agent Memory Chunk Read/Write]
|
||||
C7[ReAct Reasoning Loop]
|
||||
C --> C1 --> C2 --> C3 --> C4 --> C5 --> C6 --> C7
|
||||
end
|
||||
|
||||
subgraph Documentation Generation Phase
|
||||
D1[Overview Documentation Editor]
|
||||
D2[Architecture Documentation Editor]
|
||||
D3[Workflow Documentation Editor]
|
||||
D4[Boundary Documentation Editor]
|
||||
D5[Key Module Editor]
|
||||
D6[Agent Memory Chunk Reading]
|
||||
D7[High-Quality Documentation Assembly]
|
||||
D --> D1 --> D2 --> D3 --> D4 --> D5 --> D6 --> D7
|
||||
end
|
||||
|
||||
subgraph Verification & Enhancement Phase
|
||||
E1[Mermaid Syntax Verification]
|
||||
E2[Documentation Integrity Check]
|
||||
E3[Diagram Auto-Repair]
|
||||
E4[Quality Report Generation]
|
||||
E5[Final Documentation Output]
|
||||
E --> E1 --> E2 --> E3 --> E4 --> E5
|
||||
end
|
||||
|
||||
style B fill:#e3f2fd,stroke:#1976d2
|
||||
style C fill:#f3e5f5,stroke:#7b1fa2
|
||||
style D fill:#e8f5e8,stroke:#388e3c
|
||||
style E fill:#fff3e0,stroke:#e65100
|
||||
```
|
||||
|
||||
### Preprocessing Stage
|
||||
Litho begins by scanning your entire codebase to identify source files, extract metadata, and analyze project structure. This stage:
|
||||
- Discovers all source code files across multiple languages
|
||||
- Parses file structures and identifies key components
|
||||
- Extracts comments, documentation strings, and code annotations
|
||||
- Identifies dependencies between modules and components
|
||||
- Builds a comprehensive representation of your codebase
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Preprocessing Agent] --> B[Structure Extractor]
|
||||
A --> C[Original Document Extractor]
|
||||
A --> D[Code Analysis Agent]
|
||||
A --> E[Relationship Analysis Agent]
|
||||
B --> F[Project Structure]
|
||||
C --> G[Original Document Materials]
|
||||
D --> H[Core Code Insights]
|
||||
E --> I[Code Dependencies]
|
||||
F --> J[Store to Memory]
|
||||
G --> J
|
||||
H --> J
|
||||
I --> J
|
||||
```
|
||||
|
||||
### Research Stage
|
||||
In this AI-powered stage, Litho analyzes the code structure to understand the architectural intent:
|
||||
- Applies machine learning models to identify patterns and relationships
|
||||
- Infers architectural roles from code structure and naming conventions
|
||||
- Determines component boundaries and service responsibilities
|
||||
- Maps dependencies and data flow between components
|
||||
- Identifies potential architectural smells and anti-patterns
|
||||
- Generates context-aware documentation for each component
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Research Orchestrator] --> B[SystemContext Researcher]
|
||||
A --> C[Domain Module Detector]
|
||||
A --> D[Architecture Researcher]
|
||||
A --> E[Workflow Researcher]
|
||||
A --> F[Key Module Insights]
|
||||
B --> G[System Context Report]
|
||||
C --> H[Domain Module Report]
|
||||
D --> I[Architecture Analysis Report]
|
||||
E --> J[Workflow Analysis Report]
|
||||
F --> K[Module Deep Insights]
|
||||
G --> Memory
|
||||
H --> Memory
|
||||
I --> Memory
|
||||
J --> Memory
|
||||
K --> Memory
|
||||
```
|
||||
|
||||
### Composition and Output Stage
|
||||
Litho combines the analyzed information into a structured documentation format:
|
||||
- Generates C4 model diagrams (Context, Container, Component, Code)
|
||||
- Creates hierarchical documentation structure with clear navigation
|
||||
- Embeds relevant code examples and explanations
|
||||
- Applies consistent styling and formatting across all documentation
|
||||
- Adds cross-references between related components and diagrams
|
||||
|
||||
```mermaid
|
||||
flowchart TD
|
||||
A[Document Composer] --> B[Overview Editor]
|
||||
A --> C[Architecture Editor]
|
||||
A --> D[Module Insight Editor]
|
||||
B --> E[Overview Document]
|
||||
C --> F[Architecture Document]
|
||||
D --> G[Module Documents]
|
||||
E --> H[Document Tree]
|
||||
F --> H
|
||||
G --> H
|
||||
H --> I[Disk Outlet]
|
||||
I --> J[Output Directory]
|
||||
```
|
||||
|
||||
### Validation and Enhancement Stage
|
||||
The final stage ensures documentation quality and completeness:
|
||||
- Validates diagram syntax and consistency
|
||||
- Checks for completeness of documentation coverage
|
||||
- Identifies gaps in documentation and suggests improvements
|
||||
- Integrates with Mermaid Fixer to ensure all diagrams render correctly
|
||||
- Generates statistics and reports on documentation coverage
|
||||
- Creates an index and table of contents for easy navigation
|
||||
|
||||
# 🏗️ Architecture Overview
|
||||
|
||||
**Litho** features a sophisticated modular architecture designed for high performance, extensibility, and intelligent analysis. The system implements a multi-stage workflow with specialized AI agents and comprehensive caching mechanisms.
|
||||
|
||||
```mermaid
|
||||
graph LR
|
||||
subgraph Input Phase
|
||||
A[CLI Startup] --> B[Load Configuration]
|
||||
B --> C[Scan Structure]
|
||||
C --> D[Extract README]
|
||||
end
|
||||
subgraph Analysis Phase
|
||||
D --> E[Language Parsing]
|
||||
E --> F[AI-Enhanced Analysis]
|
||||
F --> G[Store in Memory]
|
||||
end
|
||||
subgraph Reasoning Phase
|
||||
G --> H[Orchestrator Startup]
|
||||
H --> I[System Context Analysis]
|
||||
H --> J[Domain Module Detection]
|
||||
H --> K[Workflow Analysis]
|
||||
H --> L[Key Module Insights]
|
||||
I --> M[Store in Memory]
|
||||
J --> M
|
||||
K --> M
|
||||
L --> M
|
||||
end
|
||||
subgraph Orchestration Phase
|
||||
M --> N[Orchestration Hub Startup]
|
||||
N --> O[Generate Project Overview]
|
||||
N --> P[Generate Architecture Diagram]
|
||||
N --> Q[Generate Workflow Documentation]
|
||||
N --> R[Generate Module Insights]
|
||||
O --> S[Write to DocTree]
|
||||
P --> S
|
||||
Q --> S
|
||||
R --> S
|
||||
end
|
||||
subgraph Output Phase
|
||||
S --> T[Persist Documents]
|
||||
T --> U[Generate Summary Report]
|
||||
end
|
||||
```
|
||||
|
||||
## Core Modules
|
||||
Litho's architecture consists of several interconnected modules that work together to deliver seamless documentation generation:
|
||||
|
||||
- **Code Scanner**: Discovers and analyzes source code files across multiple languages
|
||||
- **Language Parser**: Extracts structural information from code using language-specific parsers
|
||||
- **Architecture Analyzer**: AI-powered component that infers architectural patterns and relationships
|
||||
- **Diagram Generator**: Creates C4 model diagrams using Mermaid syntax
|
||||
- **Documentation Formatter**: Structures content into organized, navigable documentation
|
||||
|
||||
## Core Process
|
||||
The core processing flow follows a deterministic pipeline:
|
||||
1. **Scan** - Discover and analyze source code files
|
||||
2. **Parse** - Extract structural and semantic information
|
||||
3. **Analyze** - Apply AI models to infer architecture and relationships
|
||||
4. **Generate** - Create diagrams and documentation content
|
||||
5. **Format** - Structure content into organized documentation
|
||||
6. **Export** - Output in desired format(s)
|
||||
|
||||
```mermaid
|
||||
sequenceDiagram
|
||||
participant Main as main.rs
|
||||
participant Workflow as workflow.rs
|
||||
participant Context as GeneratorContext
|
||||
participant Preprocess as PreProcessAgent
|
||||
participant Research as ResearchOrchestrator
|
||||
participant Doc as DocumentationOrchestrator
|
||||
participant Outlet as DiskOutlet
|
||||
Main->>Workflow : launch(config)
|
||||
Workflow->>Context : Create context (LLM, Cache, Memory)
|
||||
Workflow->>Preprocess : execute(context)
|
||||
Preprocess->>Context : Store project structure and metadata
|
||||
Context-->>Workflow : Preprocessing complete
|
||||
Workflow->>Research : execute_research_pipeline(context)
|
||||
Research->>Research : Execute multiple research agents in parallel
|
||||
loop Each Research Agent
|
||||
Research->>StepForwardAgent : execute(context)
|
||||
StepForwardAgent->>Context : Validate data sources
|
||||
StepForwardAgent->>AgentExecutor : Call prompt or extract
|
||||
AgentExecutor->>LLMClient : Initiate LLM request
|
||||
LLMClient->>CacheManager : Check cache
|
||||
alt Cache hit
|
||||
CacheManager-->>LLMClient : Return cached result
|
||||
else Cache miss
|
||||
LLMClient->>LLM : Call LLM API
|
||||
LLM-->>LLMClient : Return raw response
|
||||
LLMClient->>CacheManager : Store result to cache
|
||||
end
|
||||
LLMClient-->>AgentExecutor : Return processed result
|
||||
AgentExecutor-->>StepForwardAgent : Return result
|
||||
StepForwardAgent->>Context : Store result to Memory
|
||||
end
|
||||
Research-->>Workflow : Research complete
|
||||
Workflow->>Doc : execute(context, doc_tree)
|
||||
Doc->>Doc : Call multiple composition agents to generate docs
|
||||
Doc-->>Workflow : Documentation generation complete
|
||||
Workflow->>Outlet : save(context)
|
||||
Outlet-->>Workflow : Storage complete
|
||||
Workflow-->>Main : Process finished
|
||||
```
|
||||
|
||||
# 🖥 Getting Started
|
||||
### Prerequisites
|
||||
- [**Rust**](https://www.rust-lang.org) (version 1.70 or later)
|
||||
- [**Cargo**](https://doc.rust-lang.org/cargo/)
|
||||
|
||||
### Installation
|
||||
#### Option 1: Install from crates.io (Recommended)
|
||||
```sh
|
||||
cargo install deepwiki-rs
|
||||
```
|
||||
|
||||
#### Option 2: Build from Source
|
||||
1. Clone the repository:
|
||||
```sh
|
||||
git clone https://github.com/sopaco/deepwiki-rs.git
|
||||
```
|
||||
2. Navigate to the project directory:
|
||||
```sh
|
||||
cd deepwiki-rs
|
||||
```
|
||||
3. Build the project:
|
||||
```sh
|
||||
cargo build --release
|
||||
```
|
||||
4. The compiled binary will be available in the `target/release` directory.
|
||||
|
||||
# 🚀 Usage
|
||||
**Litho** provides a simple command-line interface to generate documentation from your codebase. For more configuration parameters, refer to the [CLI Options Detail](https://github.com/sopaco/deepwiki-rs/blob/main/docs/5%E3%80%81%E8%BE%B9%E7%95%8C%E8%B0%83%E7%94%A8.md#litho).
|
||||
|
||||
### Basic Command
|
||||
```sh
|
||||
deepwiki-rs -p ./my-project -o ./docs
|
||||
|
||||
# Generate documentation in the target language.
|
||||
deepwiki-rs --target-language en -p ./my-project
|
||||
|
||||
deepwiki-rs --target-language ja -p ./my-project
|
||||
```
|
||||
|
||||
This command will:
|
||||
- Scan all files in `./my-project`
|
||||
- Analyze the code structure and relationships
|
||||
- Generate comprehensive C4 architecture documentation
|
||||
- Save the output to `./litho.docs` directory
|
||||
|
||||
### Documentation Generation
|
||||
Litho supports several options for generating documentation:
|
||||
|
||||
```sh
|
||||
# Generate documentation with default settings
|
||||
deepwiki-rs skip certain processing stages in the generation workflow
|
||||
deepwiki-rs --skip-preprocessing --skip-research
|
||||
```
|
||||
|
||||
### Advanced Options
|
||||
```sh
|
||||
# Turn off ReAct Mode to avoid auto-scanning project files via tool-calls
|
||||
deepwiki-rs -p ./src --disable-preset-tools --llm-api-base-url <your llm provider base-api> --llm-api-key <your api key> --model-efficient GPT-5-mini
|
||||
|
||||
# Set up both the efficient model and the powerful model simultaneously
|
||||
deepwiki-rs -p ./src --model-efficient GPT-5-mini --model-poweruful GPT-5-Pro --llm-api-base-url <your llm provider base-api> --llm_api_key <your api key> --model-efficient GPT-5-mini
|
||||
```
|
||||
|
||||
## 📚 External Knowledge Integration
|
||||
|
||||
Litho supports mounting external documentation as knowledge sources to enhance generated documentation with business context and architectural decisions.
|
||||
|
||||
### Supported Document Types
|
||||
- **PDF** - Architecture diagrams, design documents
|
||||
- **Markdown** - Technical documentation, ADRs
|
||||
- **SQL** - Database schema files
|
||||
- **YAML/JSON** - API specifications (OpenAPI), configurations
|
||||
- **Text** - Plain text documentation
|
||||
|
||||
### Knowledge Categories
|
||||
Documents are organized into categories for targeted delivery to specific agents:
|
||||
- `architecture` - System architecture and C4 model docs
|
||||
- `database` - Schema, ERD, and data model documentation
|
||||
- `api` - API specifications and endpoint docs
|
||||
- `deployment` - Infrastructure and DevOps documentation
|
||||
- `adr` - Architecture Decision Records
|
||||
- `workflow` - Business processes and workflows
|
||||
- `general` - Uncategorized general documentation
|
||||
|
||||
### Sync Knowledge Command
|
||||
```sh
|
||||
# Sync external knowledge sources (processes and caches local docs)
|
||||
deepwiki-rs sync-knowledge
|
||||
|
||||
# Force sync even if cache is fresh
|
||||
deepwiki-rs sync-knowledge --force
|
||||
```
|
||||
|
||||
### Configuration Example (litho.toml)
|
||||
```toml
|
||||
[knowledge.local_docs]
|
||||
enabled = true
|
||||
cache_dir = ".litho/cache/knowledge/local_docs"
|
||||
watch_for_changes = true
|
||||
|
||||
# Default chunking for large documents
|
||||
[knowledge.local_docs.default_chunking]
|
||||
enabled = true
|
||||
max_chunk_size = 8000
|
||||
chunk_overlap = 200
|
||||
strategy = "semantic" # Options: semantic, paragraph, fixed
|
||||
min_size_for_chunking = 10000
|
||||
|
||||
# Architecture documentation category
|
||||
[[knowledge.local_docs.categories]]
|
||||
name = "architecture"
|
||||
description = "System architecture documentation"
|
||||
paths = [
|
||||
"docs/architecture/**/*.md",
|
||||
"docs/design/**/*.pdf"
|
||||
]
|
||||
target_agents = [
|
||||
"SystemContextResearcher",
|
||||
"ArchitectureResearcher",
|
||||
"ArchitectureEditor"
|
||||
]
|
||||
|
||||
# Database documentation category
|
||||
[[knowledge.local_docs.categories]]
|
||||
name = "database"
|
||||
description = "Database schema documentation"
|
||||
paths = [
|
||||
"docs/database/**/*.md",
|
||||
"docs/schema/**/*.sql"
|
||||
]
|
||||
target_agents = [
|
||||
"ArchitectureResearcher",
|
||||
"DomainModulesDetector",
|
||||
"KeyModulesInsight"
|
||||
]
|
||||
```
|
||||
|
||||
## 🗄️ Database Documentation
|
||||
|
||||
Litho automatically analyzes SQL database projects (`.sqlproj`) and SQL files to generate comprehensive database documentation including:
|
||||
|
||||
- **Database Projects** - SQL Server project structure
|
||||
- **Tables** - Schema, columns, data types, constraints, primary keys
|
||||
- **Views** - View definitions and referenced tables
|
||||
- **Stored Procedures** - Parameters, operations, accessed tables
|
||||
- **Functions** - Scalar and table-valued functions
|
||||
- **Relationships** - Foreign keys and implicit references (with ERD diagrams)
|
||||
- **Data Flows** - ETL operations and data movement patterns
|
||||
|
||||
### Database Analysis Features
|
||||
```
|
||||
📊 Database code distribution: Projects(2) SQL Files(15) DAO(3)
|
||||
✅ Database overview analysis completed:
|
||||
- Database projects: 2 items
|
||||
- Tables: 12 items
|
||||
- Views: 5 items
|
||||
- Stored procedures: 8 items
|
||||
- Functions: 3 items
|
||||
- Table relationships: 6 items
|
||||
- Data flows: 4 items
|
||||
- Confidence: 8.5/10
|
||||
```
|
||||
|
||||
### Generated Database Documentation
|
||||
The database documentation is automatically included in the output as `6.Database-Overview.md` with:
|
||||
- Summary statistics table
|
||||
- Detailed table schemas with column definitions
|
||||
- Mermaid ER diagrams showing relationships
|
||||
- Stored procedure documentation
|
||||
- Data flow descriptions
|
||||
|
||||
## 📁 Output Structure
|
||||
Litho generates a well-organized documentation structure:
|
||||
|
||||
```
|
||||
project-docs/
|
||||
├── 1. Project Overview # Project overview, core functionality, technology stack
|
||||
├── 2. Architecture Overview # Overall architecture, core modules, module breakdown
|
||||
├── 3. Workflow Overview # Overall workflow, core processes
|
||||
├── 4. Deep Dive/ # Detailed technical topic implementation documentation
|
||||
│ ├── Topic1.md
|
||||
│ ├── Topic2.md
|
||||
├── 5. Boundary-Interfaces # API endpoints, external integrations
|
||||
├── 6. Database-Overview # Database schema, tables, relationships (SQL projects only)
|
||||
```
|
||||
|
||||
# 🤝 Contribute
|
||||
We welcome all forms of contributions! Report bugs or submit feature requests through [GitHub Issues](https://github.com/sopaco/deepwiki-rs/issues).
|
||||
|
||||
## Ways to Contribute
|
||||
- **Language Support**: Add support for additional programming languages
|
||||
- **Template Creation**: Design new documentation templates and styles
|
||||
- **Diagram Enhancements**: Improve Mermaid diagram generation algorithms
|
||||
- **Performance Optimization**: Enhance processing speed and memory usage
|
||||
- **Test Coverage**: Add comprehensive test cases for various code patterns
|
||||
- **Documentation**: Improve project documentation and usage guides
|
||||
- **Bug Fixes**: Help identify and fix issues in the codebase
|
||||
|
||||
## Development Contribution Process
|
||||
1. Fork this project
|
||||
2. Create a feature branch (`git checkout -b feature/amazing-feature`)
|
||||
3. Commit your changes (`git commit -m 'Add some amazing feature'`)
|
||||
4. Push to the branch (`git push origin feature/amazing-feature`)
|
||||
5. Create a Pull Request
|
||||
|
||||
# 🪪 License
|
||||
**MIT**. A copy of the license is provided in the [LICENSE](LICENSE) file.
|
||||
|
||||
# 👨 About Me
|
||||
> 🚀 Help me develop this software better by [sponsoring on GitHub](https://github.com/sponsors/sopaco)
|
||||
|
||||
An experienced internet veteran, having navigated through the waves of PC internet, mobile internet, and AI applications. Starting from an individual mobile application developer to a professional in the corporate world, I possess rich experience in product design and research and development. Currently, I am employed at [Kuaishou](https://en.wikipedia.org/wiki/Kuaishou), focusing on the R&D of universal front-end systems and AI exploration.
|
||||
|
||||
GitHub: [sopaco](https://github.com/sopaco)
|
||||
|
||||
|
||||
## FAQ
|
||||
|
||||
### What is Litho (deepwiki-rs)?
|
||||
|
||||
Litho is an AI-powered documentation generation engine built with Rust. It automatically analyzes your source code and generates comprehensive, professional architecture documentation in the C4 model format.
|
||||
|
||||
### What programming languages does Litho support?
|
||||
|
||||
Litho supports multiple programming languages including Rust, Python, Java, Go, C#, JavaScript, and more.
|
||||
|
||||
### What is C4 model?
|
||||
|
||||
C4 model is a software architecture documentation approach with four levels:
|
||||
- Context diagram (system context)
|
||||
- Container diagram (system containers)
|
||||
- Component diagram (container components)
|
||||
- Code diagram (component implementation)
|
||||
|
||||
### How do I install Litho?
|
||||
|
||||
```bash
|
||||
cargo install deepwiki-rs
|
||||
```
|
||||
|
||||
Or build from source:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/sopaco/deepwiki-rs
|
||||
cargo build --release
|
||||
```
|
||||
|
||||
### Can Litho integrate with CI/CD?
|
||||
|
||||
Yes, Litho can integrate with CI/CD pipelines to automatically generate documentation on every commit.
|
||||
|
||||
### Why use Litho instead of manual documentation?
|
||||
|
||||
- Automatically keeps documentation in sync with codebase
|
||||
- Saves hundreds of hours on manual maintenance
|
||||
- Professional C4 model structure
|
||||
- Consistent formatting and styling
|
||||
- Easy to navigate and understand
|
||||
|
||||
### Where can I get help?
|
||||
|
||||
- Documentation: https://github.com/sopaco/deepwiki-rs/tree/main/docs
|
||||
- GitHub Issues: https://github.com/sopaco/deepwiki-rs/issues
|
||||
File diff suppressed because it is too large
Load Diff
@@ -0,0 +1,47 @@
|
||||
---
|
||||
source_url: https://www.meti.go.jp/press/2026/06/20260630005/20260630005.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 8fe3759f4a3d7e578d6958d899028a4d6304269fdfdfd95082b36866c16bb50d
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521385175827877898'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T05:21:31.887000000Z
|
||||
message_excerpt: >-
|
||||
METI and NEDO physical AI multimodal foundation model program mentioned from Noetra context.
|
||||
---
|
||||
|
||||
2026年6月30日
|
||||
|
||||
同時発表:国立研究開発法人新エネルギー・産業技術総合開発機構
|
||||
|
||||
[ものづくり/情報/流通・サービス](https://www.meti.go.jp/press/category_03.html)
|
||||
|
||||
経済産業省は、フィジカルAIの実現に向けた政策を実施しています。その一環として、国立研究開発法人新エネルギー・産業技術総合開発機構(NEDO)と連携し、「AIロボット・フィジカルAIを見据えたマルチモーダル基盤モデル開発事業」を開始します。
|
||||
|
||||
## 1.内容
|
||||
|
||||
我が国の裾野の広い産業を生かした現場データを利活用し、フィジカルAIを実現することは我が国の勝ち筋の一つであり、そのためには、現場データを守りながら将来も安心して活用できる国産のマルチモーダル基盤モデル <sup>※</sup> が必要になると考えられます。また、AI利用の爆発的な拡大を踏まえると、エネルギーの自給率が低い我が国は、他国以上に AI 利用の省電力化が重要な課題となります。
|
||||
こうした状況に対処するため、経済産業省は、NEDOと共に関連政策を推進しているところ、この度、NEDOが実施した公募において、Noetra株式会社と国立研究開発法人産業総合技術研究所(産総研)が採択され、国産マルチモーダル基盤モデルの研究開発が始動することをお知らせします。
|
||||
本事業を通じて、Noetra株式会社は、日本のモデル開発・利活用事業者等のニーズを踏まえつつ、国際的に競争力のあるマルチモーダル基盤モデルを開発・提供するとともに、産総研は、国内外の研究機関等と連携して先進的な技術開発を実施し、将来を見据えた競争力ある基盤モデルの開発に貢献することを目指します。
|
||||
幅広い分野でのフィジカルAIのベースとなる国産のマルチモーダル基盤モデルを世界に先駆けて構築することで、世界で競争が激化するフィジカルAIについて、我が国の現場力とものづくり基盤という強みを生かして、労働力減少を乗り越える形で導入を加速し、国際競争力の獲得を目指していきます。
|
||||
|
||||
## 2.採択について
|
||||
|
||||
2026年3月24日から4月22日にかけて、NEDOにおいて以下の公募を実施し、採択結果を発表しました。以下のリンク先をご覧ください。
|
||||
|
||||
[AI ロボット・フィジカル AI を見据えたマルチモーダル基盤モデル開発事業](https://www.nedo.go.jp/koubo/CD3_100431.html)
|
||||
事業期間:2026年度~2030年度
|
||||
|
||||
※言語に留まらず、音声・画像・動画・センサーデータ等、多様なデータを扱うことが可能となるAIモデルのこと。
|
||||
|
||||
## 担当
|
||||
|
||||
商務情報政策局 情報産業課
|
||||
AI産業戦略室長 渡辺
|
||||
担当者:秋元、今村、宮川、依田
|
||||
電話:03-3501-1511(内線3981)
|
||||
メール:bzl-softsitu-jimu★meti.go.jp
|
||||
※[★]を[@]に置き換えてください。
|
||||
@@ -0,0 +1,88 @@
|
||||
---
|
||||
source_url: https://www.mhlw.go.jp/stf/shingi/0000516275_00006.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 79cb09951ee3df9f3a87c480a63b3ec4edd92382fd6819145b915a28e89e6455
|
||||
discovered_from:
|
||||
platform: 'discord'
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: 'tw'
|
||||
message_id: '1521370066216816690'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: '2026-06-30T04:21:29.475000000Z'
|
||||
message_excerpt: '医療情報システムの安全管理に関するガイドライン第7.0版が、医療DXと電子カルテ標準化に関わる実務リンクとして共有された。'
|
||||
score: 2
|
||||
---
|
||||
|
||||
1. [ホーム](https://www.mhlw.go.jp/index.html) \>
|
||||
2. [政策について](https://www.mhlw.go.jp/stf/seisakunitsuite/index.html) \>
|
||||
3. [審議会・研究会等](https://www.mhlw.go.jp/stf/shingi/indexshingi.html) \>
|
||||
4. [医政局が実施する検討会等](https://www.mhlw.go.jp/stf/shingi/indexshingiother_127238.html) \>
|
||||
5. [健康・医療・介護情報利活用検討会 医療等情報利活用ワーキンググループ](https://www.mhlw.go.jp/stf/shingi/other-isei_210261.html) \>
|
||||
6. 医療情報システムの安全管理に関するガイドライン 第7.0版(令和8年6月)
|
||||
|
||||
*医療情報システムの安全管理に関するガイドライン第7.0版*
|
||||
|
||||
「医療情報システムの安全管理に関するガイドライン」(以下「ガイドライン」という。)は令和8年6月に見直しを行いました。医療機関等におかれましては医療情報システムの取扱において、本ガイドラインを遵守いただくようお願い申し上げます。
|
||||
|
||||
## 医療情報システムの安全管理に関するガイドライン 第7.0版(令和8年6月)
|
||||
|
||||
### 概説編
|
||||
|
||||
[医療情報システムの安全管理に関するガイドライン 第7.0版(概説編)(令和8年6月)[1.2MB]](https://www.mhlw.go.jp/content/10808000/001716290.pdf)
|
||||
|
||||
### 経営管理編
|
||||
|
||||
[医療情報システムの安全管理に関するガイドライン 第7.0版(経営管理編)(令和8年6月)[1.8MB]](https://www.mhlw.go.jp/content/10808000/001716291.pdf)
|
||||
|
||||
### 企画管理編
|
||||
|
||||
[医療情報システムの安全管理に関するガイドライン 第7.0版(企画管理編)(令和8年5月)[2.1MB]](https://www.mhlw.go.jp/content/10808000/001716292.pdf)
|
||||
|
||||
### システム運用編
|
||||
|
||||
[医療情報システムの安全管理に関するガイドライン 第7.0版(システム運用編)(令和8年6月)[2.2MB]](https://www.mhlw.go.jp/content/10808000/001716295.pdf)
|
||||
|
||||
### 保守委託機関編
|
||||
|
||||
[医療情報システムの安全管理に関するガイドライン 第7.0版(保守委託機関編)[1.5MB]](https://www.mhlw.go.jp/content/10808000/001716297.pdf)
|
||||
|
||||
## Q&A
|
||||
|
||||
### ガイドラインのQ&A
|
||||
|
||||
医療情報の安全管理に関するガイドライン第7.0版に関するQ&A集は、現在改版中でございます。
|
||||
令和8年7月中に掲載する予定です。
|
||||
|
||||
## 医療機関・薬局におけるサイバーセキュリティ対策チェックリスト(令和8年6月)
|
||||
|
||||
医療機関等におけるサイバーセキュリティ対策については、ガイドラインを参照の上、適切な対応を行うこととしているところ、このうちまずは医療機関及び薬局が優先的に取り組むべき事項をチェックリストにまとめました。
|
||||
また医療機関及び薬局におけるチェックリストを用いた確認の実効性を高めるために、チェックリストマニュアルを作成しました。 医療機関、薬局及び医療情報システム・サービス事業者は、本マニュアルを参照しつつチェックリストを活用して、サイバーセキュリティ対策を行ってください。
|
||||
尚、令和7年年度版までは、「医療機関用」と「薬局用」にチェックリストのフォームが分かれていましたが、チェック項目は医療機関および薬局が同一であることから「医療機関・薬局におけるサイバーセキュリティ対策チェックリスト」として統合しております。マニュアルの名称についても「医療機関・薬局におけるサイバーセキュリティ対策チェックリストマニュアル」といたしました。
|
||||
|
||||
### 医療機関・薬局用チェックリスト
|
||||
|
||||
## サイバー攻撃を想定した事業継続計画(BCP)策定の確認表等
|
||||
|
||||
- サイバー攻撃を想定した事業継続計画(BCP)策定について医療機関等におけるサイバーセキュリティ対策チェックリストの中で求めております。このBCPを策定する上で記載すべき項目を確認表としてまとめました。また、それに付随して確認表の各項目に解説をつけた手引き、BCPのひな形も作成いたしましたので、各医療機関でサイバー攻撃を想定したBCPを策定する際に参考としてください。
|
||||
|
||||
### 医療機関用
|
||||
|
||||
### 薬局用
|
||||
|
||||
## 参考資料・関連リンク
|
||||
|
||||
### 教育支援ポータルサイト
|
||||
|
||||
医療機関・薬局向けの医療情報セキュリティ研修は令和8年度も実施予定です。
|
||||
令和8年7月中旬から参加登録可能です。
|
||||
|
||||
[](https://mist.mhlw.go.jp/)
|
||||
|
||||
|
||||
お問い合わせ先
|
||||
|
||||
医政局 医療情報担当参事官室
|
||||
|
||||
TEL:03-6812-7837[PDFファイルを見るためには、Adobe Readerというソフトが必要です。Adobe Readerは無料で配布されていますので、こちらからダウンロードしてください。](https://get.adobe.com/jp/reader/)
|
||||
|
||||
[](https://get.adobe.com/jp/reader/)
|
||||
@@ -0,0 +1,72 @@
|
||||
---
|
||||
source_url: "https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/"
|
||||
ingested: 2026-06-30
|
||||
sha256: df13cb0cdf759d1813679ce253ba9a5a115de9d55fb1ff4cc274c5b4fdca9eea
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521490855561793599"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T12:21:27.899000000Z"
|
||||
message_excerpt: "Microsoft LearnのエージェントアーキテクチャとSDLC統合設計 は、抽象論ではなくGitHubワークフローに落とす教材として具体度が高いです。"
|
||||
---
|
||||
|
||||

|
||||
|
||||
## エージェント アーキテクチャと SDLC 統合の設計
|
||||
|
||||
- モジュール
|
||||
- 9 ユニット
|
||||
|
||||
中級
|
||||
|
||||
DevOps エンジニア
|
||||
|
||||
管理者
|
||||
|
||||
開発者
|
||||
|
||||
ソリューション アーキテクト
|
||||
|
||||
GitHub
|
||||
|
||||
エージェント システムがGitHubワークフローを使用してソフトウェアを安全に構築する方法について説明します。
|
||||
|
||||
## 学習の目的
|
||||
|
||||
このモジュールを完了すると、次のことができるようになります。
|
||||
|
||||
- エージェントの責任を SDLC ステージにマップし、アーキテクチャの境界を定義する
|
||||
- 入力、出力、成功条件を使用して構造化されたエージェント タスクを定義する
|
||||
- 計画、推論、実行を分離して、検査可能で信頼性の高いワークフローを作成する
|
||||
- テンプレート、チェック、CODEOWNERS、ルール、環境を使用してプル要求ベースのガバナンスを実装する
|
||||
- 出力、コンテキスト、トリガー、およびジョブ間ハンドオフを使用して信頼性の高いワークフローを設計する
|
||||
- 可観測性、ツール ガバナンス、シークレット境界、フック、信頼性パターンを使用してエージェント システムを安全に運用する
|
||||
|
||||
## 前提条件
|
||||
|
||||
作業を開始する前に、次の作業を行う必要があります。
|
||||
|
||||
- GitHub アカウントとリポジトリ、ブランチ、プル要求に関する知識
|
||||
- GitHub Actions ワークフローと状態チェックに関する基本的な経験
|
||||
- ソフトウェア開発ライフサイクル (SDLC) の一般的な理解 (計画、実装、検証、展開)
|
||||
- 必要なレビュー、CODEOWNERS、ブランチ保護など、リポジトリ ガバナンスの概念の認識
|
||||
|
||||
一部の適用制御 (ルールセット/ブランチの保護や必要なチェックなど) では、リポジトリまたは組織の管理者のアクセス許可を構成する必要があります。
|
||||
|
||||
このモジュールでは、リポジトリ レベルのアーキテクチャ (プル要求、チェック、ルール) に重点を置いています。 実際には、エージェント システムには、ネットワーク アクセス制限などの環境レベルの制御も含まれます。 たとえば、クラウド エージェントGitHub Copilot構成可能なファイアウォールを使用して外部アクセスを制限します。 これらのコントロールは、実行時にエージェントがアクセスできる内容を定義します。一方、PR ベースのガバナンスでは、受け入れられる変更を定義します。
|
||||
|
||||
詳細については、「 Copilot cloud agent.
|
||||
|
||||
- [イントロダクション](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/1-introduction) min
|
||||
- [エージェントの責任を SDLC にマップする](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/2-agent-responsibilities) min
|
||||
- [入力、出力、成功条件を定義する](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/3-inputs-outputs-success-criteria) min
|
||||
- [計画、推論、実行を分離する](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/4-plan-reason-execution) min
|
||||
- [テンプレート、チェック、CODEOWNERS、ルール、環境ゲートを使用して PR ガバナンスを実装する例](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/5-pull-request-governance-controls) min
|
||||
- [信頼性の高いワークフローを構築する - 出力、コンテキスト、トリガー、およびジョブ間のハンドオフ](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/6-reliable-workflows) min
|
||||
- [エージェントの制御と運用 - 可観測性、ツール、MCP、シークレット、フック、信頼性](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/7-agent-operations-controls) min
|
||||
- [知識チェック](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/8-knowledge-check) min
|
||||
- [まとめ](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/9-summary) min
|
||||
|
||||
[開始](https://learn.microsoft.com/ja-jp/training/modules/design-agent-architecture-integration/#)
|
||||
@@ -0,0 +1,52 @@
|
||||
---
|
||||
source_url: "https://www.theregister.com/security/2026/06/29/nissan-says-oracle-peoplesoft-break-in-may-have-spilled-payroll-records-ssns/5263534"
|
||||
ingested: 2026-06-30
|
||||
sha256: f687fa6246dcead5f6259e452f8ee8d9b61e30e66b14de12a3d1b975f1d265e2
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521475788287774723"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T11:21:35.581000000Z"
|
||||
message_excerpt: "#tw digest flagged Nissan/Oracle PeopleSoft breach as an example of enterprise IT failure exposing payroll/bank data."
|
||||
score: 2
|
||||
---
|
||||
Carmaker points finger at an 'unknown' flaw as customer fallout continues
|
||||
|
||||
Nissan has joined the growing list of Oracle customers cleaning up after a cyberattack, warning employees that payroll records, bank details, Social Security numbers, and other personal data may have been stolen.
|
||||
|
||||
In a filing [submitted to the California Attorney General](https://oag.ca.gov/privacy/databreach/list) on Friday, Nissan Americas said Oracle had informed it of "a cyber event" involving the personnel records of "hundreds of companies." The automaker said it later learned Nissan had been "specifically targeted" in the attack.
|
||||
|
||||
A notification sent to current and former employees, seen by The Register, says the company believes attackers accessed a haul of sensitive info, including contact and banking information; Social Security, Social Insurance, or other national identification numbers; financial and tax records; and dependent and beneficiary details.
|
||||
|
||||
Current and former employees in the US, Canada, Mexico, and Brazil may have been affected, although Nissan said it is still working to determine exactly whose information was exposed.
|
||||
|
||||
Nissan said it kicked off its incident response plan after learning of the intrusion, brought in outside security specialists, and has been working with Oracle while keeping law enforcement informed. It plans to offer affected individuals credit or dark web monitoring where available.
|
||||
|
||||
The company has also put a few extra locks on the payroll office. Employees can now access pay slips or update direct deposit details only from a corporate network or through a secure VPN, while Nissan adds extra identity checks before processing payroll requests.
|
||||
|
||||
The accompanying employee FAQ pins the incident on "an unknown vulnerability in Oracle's PeopleSoft software" and says the campaign is affecting "hundreds of companies and institutions." The document offers no clue as to what the vulnerability is, whether Oracle has patched it, or whether the compromised PeopleSoft environment was hosted by Oracle or by Nissan itself.
|
||||
|
||||
The disclosure lands just weeks after [researchers linked the ShinyHunters extortion crew to a wave of attacks exploiting a PeopleSoft zero-day](https://www.theregister.com/cyber-crime/2026/06/11/shinyhunters-claims-oracle-peoplesoft-0-day-hit-100-orgs/5254443). More than 100 organizations and roughly 300 PeopleSoft instances were reportedly compromised before Oracle issued mitigation measures, with the gang claiming to have made off with HR, payroll, and other enterprise data.
|
||||
|
||||
## MORE CONTEXT
|
||||
|
||||
- [
|
||||
### Weak security means attackers could disable all of a city's public EV chargers
|
||||
](https://www.theregister.com/security/2026/04/24/attackers-could-disable-all-of-a-citys-public-ev-chargers/5222307)
|
||||
- [
|
||||
### US regulator tells GM to hit the brakes on customer tracking
|
||||
](https://www.theregister.com/security/2026/01/15/us-regulator-tells-gm-to-hit-the-brakes-on-customer-tracking/4130097)
|
||||
- [
|
||||
### 21K Nissan customers' data stolen in Red Hat raid
|
||||
](https://www.theregister.com/security/2025/12/23/21k-nissan-customers-data-stolen-in-red-hat-raid/1976802)
|
||||
- [
|
||||
### Porsche panic in Russia as pricey status symbols forget how to car
|
||||
](https://www.theregister.com/security/2025/12/09/porsche-panic-in-russia-as-cars-mysteriously-bricked/2097447)
|
||||
|
||||
Oracle has said little publicly about the reported attacks and didn't respond to The Register's questions, even as organizations have continued to disclose being caught in the fallout.
|
||||
|
||||
Nissan has not confirmed that the incidents are connected, though its California filing lists the breach period as May 27 through June 9, broadly aligning with the previously reported timeline.
|
||||
|
||||
The carmaker didn't respond to questions about how many current and former employees are affected, when Oracle first notified it of the breach, and whether the compromise was limited to Oracle-managed systems. ®
|
||||
File diff suppressed because one or more lines are too long
@@ -0,0 +1,421 @@
|
||||
---
|
||||
source_url: "https://developers.openai.com/codex/agent-approvals-security"
|
||||
ingested: 2026-06-30
|
||||
sha256: 78f89c1de793cdcc686b188fdaa5ab0ce1000f2f6b13ded16bd3cb96bb0aeb73
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521445609318649867"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T09:21:40.354000000Z"
|
||||
message_excerpt: "Codex permission profiles / config controls for file access and network destinations; relevant to local AI agent safe operation."
|
||||
score: 4
|
||||
---
|
||||
|
||||
Codex helps protect your code and data and reduces the risk of misuse.
|
||||
|
||||
This page covers how to operate Codex safely, including sandboxing, approvals, and network access. If you are looking for Codex Security, the product for scanning connected GitHub repositories, see [Codex Security](https://developers.openai.com/codex/security).
|
||||
|
||||
By default, the agent runs with network access turned off. Locally, Codex uses an OS-enforced sandbox that limits what it can touch (typically to the current workspace), plus an approval policy that controls when it must stop and ask you before acting.
|
||||
|
||||
For a high-level explanation of how sandboxing works across the Codex app, IDE extension, and CLI, see [sandboxing](https://developers.openai.com/codex/concepts/sandboxing). For a broader enterprise security overview, see the [Codex security white paper](https://trust.openai.com/?itemUid=382f924d-54f3-43a8-a9df-c39e6c959958&source=click).
|
||||
|
||||
## Sandbox and approvals
|
||||
|
||||
Codex security controls come from two layers that work together:
|
||||
|
||||
- **Sandbox mode**: What Codex can do technically (for example, where it can write and whether it can reach the network) when it executes model-generated commands.
|
||||
- **Approval policy**: When Codex must ask you before it executes an action (for example, leaving the sandbox, using the network, or running commands outside a trusted set).
|
||||
|
||||
Codex uses different sandbox modes depending on where you run it:
|
||||
|
||||
- **Codex cloud**: Runs in isolated OpenAI-managed containers, preventing access to your host system or unrelated data. Uses a two-phase runtime model: setup runs before the agent phase and can access the network to install specified dependencies, then the agent phase runs offline by default unless you enable internet access for that environment. Secrets configured for cloud environments are available only during setup and are removed before the agent phase starts.
|
||||
- **Codex CLI / IDE extension**: OS-level mechanisms enforce sandbox policies. Defaults include no network access and write permissions limited to the active workspace. You can configure the sandbox, approval policy, and network settings based on your risk tolerance.
|
||||
|
||||
In the `Auto` preset (for example, `--sandbox workspace-write --ask-for-approval on-request`), Codex can read files, make edits, and run commands in the working directory automatically.
|
||||
|
||||
Codex asks for approval to edit files outside the workspace or to run commands that require network access. If you want to chat or plan without making changes, switch to `read-only` mode with the `/permissions` command.
|
||||
|
||||
Codex can also elicit approval for app (connector) tool calls that advertise side effects, even when the action isn’t a shell command or file change. Destructive app/MCP tool calls always require approval when the tool advertises a destructive annotation, even if it also advertises other hints (for example, read-only hints).
|
||||
|
||||
## Network access Elevated Risk
|
||||
|
||||
For Codex cloud, see [agent internet access](https://developers.openai.com/codex/cloud/internet-access) to enable full internet access or a domain allow list.
|
||||
|
||||
For the Codex app, CLI, or IDE Extension, the default `workspace-write` sandbox mode keeps network access turned off unless you enable it in your configuration:
|
||||
|
||||
```toml
|
||||
[sandbox_workspace_write]
|
||||
network_access = true
|
||||
```
|
||||
|
||||
### Network isolation
|
||||
|
||||
Network access is controlled through destination rules that apply to scripts, programs, and subprocesses spawned by commands. When command network access is already enabled, turn on the `network_proxy` feature to constrain that traffic to the network policy you configure.
|
||||
|
||||
```toml
|
||||
[features.network_proxy]
|
||||
enabled = true
|
||||
domains = { "api.openai.com" = "allow", "example.com" = "deny" }
|
||||
```
|
||||
|
||||
For a one-off CLI session, use the boolean shorthand when you only need the toggle, and the table form when you also set policy options:
|
||||
|
||||
```bash
|
||||
codex \
|
||||
-c 'features.network_proxy=true' \
|
||||
-c 'sandbox_workspace_write.network_access=true'
|
||||
|
||||
codex \
|
||||
-c 'features.network_proxy.enabled=true' \
|
||||
-c 'features.network_proxy.domains={ "api.openai.com" = "allow", "example.com" = "deny" }' \
|
||||
-c 'sandbox_workspace_write.network_access=true'
|
||||
```
|
||||
|
||||
The feature changes how enabled network access is enforced; it does not grant network access by itself. Use `sandbox_workspace_write.network_access` with `workspace-write` config to decide whether commands have network access at all:
|
||||
|
||||
- Network off + `network_proxy` on: network stays off, and the feature does nothing.
|
||||
- Network on + `network_proxy` off: network stays on with unrestricted direct outbound access.
|
||||
- Network on + `network_proxy` on: network stays on, and outbound traffic is constrained by the configured network policy.
|
||||
|
||||
Admin-managed `experimental_network` requirements are separate from the user feature toggle. They can configure and start sandboxed networking without `features.network_proxy`, but they do not turn on network access when the active sandbox keeps it off. See [Managed configuration](https://developers.openai.com/codex/enterprise/managed-configuration#configure-network-access-requirements) for the administrator-side `requirements.toml` shape.
|
||||
|
||||
#### Network policy
|
||||
|
||||
Domain rules are allowlist-first:
|
||||
|
||||
- Exact hosts match only themselves.
|
||||
- `*.example.com` matches subdomains such as `api.example.com`, but not `example.com`.
|
||||
- `**.example.com` matches both the apex and subdomains.
|
||||
- A global `*` allow rule matches any public host that is not denied. Treat `*` as broad network access and prefer scoped rules when you can.
|
||||
- `deny` always wins over `allow`, and global `*` is only valid for allow rules.
|
||||
|
||||
#### Local and private destinations
|
||||
|
||||
By default, `allow_local_binding = false` blocks loopback, link-local, and private destinations:
|
||||
|
||||
- Specific exceptions: add an exact local IP literal or `localhost` allow rule when a command needs one local target.
|
||||
- Broader access: set `allow_local_binding = true` only when you intentionally want wider local/private reach.
|
||||
- Wildcards: wildcard rules do not count as explicit local exceptions.
|
||||
- Resolved addresses: hostnames that resolve to local/private IPs stay blocked even if they match the allowlist.
|
||||
|
||||
#### DNS rebinding protections
|
||||
|
||||
Before allowing a hostname, Codex performs a best-effort DNS and IP classification check:
|
||||
|
||||
- Lookups that fail or time out are blocked.
|
||||
- Hostnames that resolve to non-public addresses are blocked.
|
||||
- The check reduces DNS rebinding risk, but it does not eliminate it. Preventing rebinding completely would require pinning resolved IPs through the transport layer.
|
||||
|
||||
If hostile DNS is in scope, enforce egress controls at a lower layer too.
|
||||
|
||||
#### Dangerous settings
|
||||
|
||||
Two settings deliberately widen the trust boundary:
|
||||
|
||||
- `dangerously_allow_non_loopback_proxy = true` can expose proxy listeners beyond loopback.
|
||||
- `dangerously_allow_all_unix_sockets = true` bypasses the Unix socket allowlist.
|
||||
|
||||
Use them only in tightly controlled environments. When Unix socket proxying is enabled, listeners stay loopback-only even if non-loopback binding was requested, so sandboxed networking does not become a remote bridge into local daemons.
|
||||
|
||||
`network_proxy` is off by default. When you enable it:
|
||||
|
||||
| Setting | Default | Behavior |
|
||||
| --- | --- | --- |
|
||||
| `enabled` | `false` | Starts sandboxed networking only when command network access is already on. |
|
||||
| `domains` | unset | Uses allowlist behavior, so no external destinations are allowed until you add `allow` rules. Supports exact hosts, scoped wildcards, and global `*` allow rules; `deny` always wins. |
|
||||
| `unix_sockets` | unset | No Unix socket destinations are allowed until you add explicit `allow` rules. |
|
||||
| `allow_local_binding` | `false` | Blocks local and private-network destinations unless you add an exact local IP literal or `localhost` allow rule, or explicitly opt into broader local/private access. |
|
||||
| `enable_socks5` | `true` | Exposes SOCKS5 support when policy allows it. |
|
||||
| `enable_socks5_udp` | `true` | Allows UDP over SOCKS5 when SOCKS5 is available. |
|
||||
| `allow_upstream_proxy` | `true` | Lets sandboxed networking honor an upstream proxy from the environment. |
|
||||
| `dangerously_allow_non_loopback_proxy` | `false` | Keeps listener endpoints on loopback unless you deliberately expose them beyond localhost. |
|
||||
| `dangerously_allow_all_unix_sockets` | `false` | Keeps Unix socket access allowlist-based unless you deliberately bypass that protection. |
|
||||
|
||||
You can also control the [web search tool](https://platform.openai.com/docs/guides/tools-web-search) without granting full network access to spawned commands. Codex defaults to using a web search cache to access results. The cache is an OpenAI-maintained index of web results, so cached mode returns pre-indexed results instead of fetching live pages. This reduces exposure to prompt injection from arbitrary live content, but you should still treat web results as untrusted. If you are using `--yolo` or another [full access sandbox setting](https://developers.openai.com/codex/agent-approvals-security#common-sandbox-and-approval-combinations), web search defaults to live results. Use `--search` or set `web_search = "live"` to allow live browsing, or set it to `"disabled"` to turn the tool off:
|
||||
|
||||
```toml
|
||||
web_search = "cached" # default
|
||||
# web_search = "disabled"
|
||||
# web_search = "live" # same as --search
|
||||
```
|
||||
|
||||
Use caution when enabling network access or web search in Codex. Prompt injection can cause the agent to fetch and follow untrusted instructions.
|
||||
|
||||
- On launch, Codex detects whether the folder is version-controlled and recommends:
|
||||
- Version-controlled folders: `Auto` (workspace write + on-request approvals)
|
||||
- Non-version-controlled folders: `read-only`
|
||||
- Depending on your setup, Codex may also start in `read-only` until you explicitly trust the working directory (for example, via an onboarding prompt or `/permissions`).
|
||||
- The workspace includes the current directory and temporary directories like `/tmp`. Use the `/status` command to see which directories are in the workspace.
|
||||
- To accept the defaults, run `codex`.
|
||||
- You can set these explicitly:
|
||||
- `codex --sandbox workspace-write --ask-for-approval on-request`
|
||||
- `codex --sandbox read-only --ask-for-approval on-request`
|
||||
|
||||
### Protected paths in writable roots
|
||||
|
||||
In the default `workspace-write` sandbox policy, writable roots still include protected paths:
|
||||
|
||||
- `<writable_root>/.git` is protected as read-only whether it appears as a directory or file.
|
||||
- If `<writable_root>/.git` is a pointer file (`gitdir: ...`), the resolved Git directory path is also protected as read-only.
|
||||
- `<writable_root>/.agents` is protected as read-only when it exists as a directory.
|
||||
- `<writable_root>/.codex` is protected as read-only when it exists as a directory.
|
||||
- Protection is recursive, so everything under those paths is read-only.
|
||||
|
||||
### Run without approval prompts
|
||||
|
||||
You can disable approval prompts with `--ask-for-approval never` or `-a never` (shorthand).
|
||||
|
||||
This option works with all `--sandbox` modes, so you still control Codex’s level of autonomy. Codex makes a best effort within the constraints you set.
|
||||
|
||||
If you need Codex to read files, make edits, and run commands with network access without approval prompts, use `--sandbox danger-full-access` (or the `--dangerously-bypass-approvals-and-sandbox` flag). Use caution before doing so.
|
||||
|
||||
For a middle ground, `approval_policy = { granular = { ... } }` lets you keep specific approval prompt categories interactive while automatically rejecting others. The granular policy covers sandbox approvals, execpolicy-rule prompts, MCP prompts, `request_permissions` prompts, and skill-script approvals.
|
||||
|
||||
### Automatic approval reviews
|
||||
|
||||
By default, approval requests route to you:
|
||||
|
||||
```toml
|
||||
approvals_reviewer = "user"
|
||||
```
|
||||
|
||||
Automatic approval reviews apply when approvals are interactive, such as `approval_policy = "on-request"` or a granular approval policy. Set `approvals_reviewer = "auto_review"` to route eligible approval requests through a reviewer agent before Codex runs the request:
|
||||
|
||||
```toml
|
||||
approval_policy = "on-request"
|
||||
approvals_reviewer = "auto_review"
|
||||
```
|
||||
|
||||
For the full reviewer lifecycle, trigger conditions, configuration precedence, and failure behavior, see [Auto-review](https://developers.openai.com/codex/concepts/sandboxing/auto-review).
|
||||
|
||||
The reviewer evaluates only actions that already need approval, such as sandbox escalations, blocked network requests, `request_permissions` prompts, or side-effecting app and MCP tool calls. Actions that stay inside the sandbox continue without an extra review step.
|
||||
|
||||
The reviewer policy checks for data exfiltration, credential probing, persistent security weakening, and destructive actions. Low-risk and medium-risk actions can proceed when policy allows them. The policy denies critical-risk actions. High-risk actions require enough user authorization and no matching deny rule. Prompt-build, review-session, and parse failures fail closed. Timeouts are surfaced separately, but the action still does not run.
|
||||
|
||||
The [default reviewer policy](https://github.com/openai/codex/blob/main/codex-rs/core/src/guardian/policy.md) is in the open-source Codex repository. Enterprises can replace its tenant-specific section with `guardian_policy_config` in managed requirements. Local `[auto_review].policy` text is also supported, but managed requirements take precedence. For setup details, see [Managed configuration](https://developers.openai.com/codex/enterprise/managed-configuration#configure-automatic-review-policy).
|
||||
|
||||
In the Codex app, these reviews appear as automatic review items with a status such as Reviewing, Approved, Denied, Aborted, or Timed out. They can also include a risk level and user-authorization assessment for the reviewed request.
|
||||
|
||||
Automatic review uses extra model calls, so it can add to Codex usage. Admins can constrain it with `allowed_approvals_reviewers`.
|
||||
|
||||
### Common sandbox and approval combinations
|
||||
|
||||
| Intent | Flags / config | Effect |
|
||||
| --- | --- | --- |
|
||||
| Auto (preset) | *no flags needed* or `--sandbox workspace-write --ask-for-approval on-request` | Codex can read files, make edits, and run commands in the workspace. Codex requires approval to edit outside the workspace or to access network. |
|
||||
| Safe read-only browsing | `--sandbox read-only --ask-for-approval on-request` | Codex can read files and answer questions. Codex requires approval to make edits, run commands, or access network. |
|
||||
| Read-only non-interactive (CI) | `--sandbox read-only --ask-for-approval never` | Codex can only read files; never asks for approval. |
|
||||
| Automatically edit but ask for approval to run untrusted commands | `--sandbox workspace-write --ask-for-approval untrusted` | Codex can read and edit files but asks for approval before running untrusted commands. |
|
||||
| Auto-review mode | `--sandbox workspace-write --ask-for-approval on-request -c approvals_reviewer=auto_review` or `approvals_reviewer = "auto_review"` | Same sandbox boundary as standard on-request mode, but eligible approval requests are reviewed by Auto-review instead of surfacing to the user. |
|
||||
| Dangerous full access | `--dangerously-bypass-approvals-and-sandbox` (alias: `--yolo`) | [Elevated Risk](https://help.openai.com/articles/20001061) No sandbox; no approvals *(not recommended)* |
|
||||
|
||||
For non-interactive runs, use `codex exec --sandbox workspace-write`; Codex keeps older `codex exec --full-auto` invocations as a deprecated compatibility path and prints a warning.
|
||||
|
||||
With `--ask-for-approval untrusted`, Codex runs only known-safe read operations automatically. Commands that can mutate state or trigger external execution paths (for example, destructive Git operations or Git output/config-override flags) require approval.
|
||||
|
||||
#### Configuration in config.toml
|
||||
|
||||
For the broader configuration workflow, see [Config basics](https://developers.openai.com/codex/config-basic), [Advanced Config](https://developers.openai.com/codex/config-advanced#approval-policies-and-sandbox-modes), and the [Configuration Reference](https://developers.openai.com/codex/config-reference).
|
||||
|
||||
```toml
|
||||
# Always ask for approval mode
|
||||
approval_policy = "untrusted"
|
||||
sandbox_mode = "read-only"
|
||||
allow_login_shell = false # optional hardening: disallow login shells for shell-based tools
|
||||
|
||||
# Optional: Allow network in workspace-write mode
|
||||
[sandbox_workspace_write]
|
||||
network_access = true
|
||||
|
||||
# Optional: granular approval policy
|
||||
# approval_policy = { granular = {
|
||||
# sandbox_approval = true,
|
||||
# rules = true,
|
||||
# mcp_elicitations = true,
|
||||
# request_permissions = false,
|
||||
# skill_approval = false
|
||||
# } }
|
||||
```
|
||||
|
||||
You can also save presets as [profile files](https://developers.openai.com/codex/config-advanced#profiles), then select them with `codex --profile profile-name`:
|
||||
|
||||
```toml
|
||||
# ~/.codex/full_auto.config.toml
|
||||
approval_policy = "on-request"
|
||||
sandbox_mode = "workspace-write"
|
||||
```
|
||||
```toml
|
||||
# ~/.codex/readonly_quiet.config.toml
|
||||
approval_policy = "never"
|
||||
sandbox_mode = "read-only"
|
||||
```
|
||||
|
||||
### Test the sandbox locally
|
||||
|
||||
To see what happens when a command runs under the Codex sandbox, use these Codex CLI commands:
|
||||
|
||||
```bash
|
||||
# macOS
|
||||
codex sandbox macos [--permissions-profile <name>] [--log-denials] [COMMAND]...
|
||||
# Linux
|
||||
codex sandbox linux [--permissions-profile <name>] [COMMAND]...
|
||||
# Windows
|
||||
codex sandbox windows [--permissions-profile <name>] [COMMAND]...
|
||||
```
|
||||
|
||||
The `sandbox` command is also available as `codex debug`, and the platform helpers have aliases (for example `codex sandbox seatbelt` and `codex sandbox landlock`).
|
||||
|
||||
## OS-level sandbox
|
||||
|
||||
Codex enforces the sandbox differently depending on your OS:
|
||||
|
||||
- **macOS** uses Seatbelt policies and runs commands using `sandbox-exec` with a profile (`-p`) that corresponds to the `--sandbox` mode you selected. When restricted read access enables platform defaults, Codex appends a curated macOS platform policy (instead of broadly allowing `/System`) to preserve common tool compatibility.
|
||||
- **Linux** uses `bwrap` plus `seccomp` by default.
|
||||
- **Windows** uses the Linux sandbox implementation when running in [Windows Subsystem for Linux 2 (WSL2)](https://developers.openai.com/codex/windows#windows-subsystem-for-linux). WSL1 was supported through Codex `0.114`; starting in `0.115`, the Linux sandbox moved to `bwrap`, so WSL1 is no longer supported. When running natively on Windows, Codex uses a [Windows sandbox](https://developers.openai.com/codex/windows#windows-sandbox) implementation.
|
||||
|
||||
If you use the Codex IDE extension on Windows, it supports WSL2 directly. Set the following in your VS Code settings to keep the agent inside WSL2 whenever it’s available:
|
||||
|
||||
```json
|
||||
{
|
||||
"chatgpt.runCodexInWindowsSubsystemForLinux": true
|
||||
}
|
||||
```
|
||||
|
||||
This ensures the IDE extension inherits Linux sandbox semantics for commands, approvals, and filesystem access even when the host OS is Windows. Learn more in the [Windows setup guide](https://developers.openai.com/codex/windows).
|
||||
|
||||
When running natively on Windows, configure the native sandbox mode in `config.toml`:
|
||||
|
||||
```toml
|
||||
[windows]
|
||||
sandbox = "unelevated" # or "elevated"
|
||||
# sandbox_private_desktop = true # default; set false only for compatibility
|
||||
```
|
||||
|
||||
See the [Windows setup guide](https://developers.openai.com/codex/windows#windows-sandbox) for details.
|
||||
|
||||
When you run Linux in a containerized environment such as Docker, the sandbox may not work if the host or container configuration blocks the namespace, setuid `bwrap`, or `seccomp` operations that Codex needs.
|
||||
|
||||
In that case, configure your Docker container to provide the isolation you need, then run `codex` with `--sandbox danger-full-access` (or the `--dangerously-bypass-approvals-and-sandbox` flag) inside the container.
|
||||
|
||||
### Run Codex in Dev Containers
|
||||
|
||||
If your host cannot run the Linux sandbox directly, or if your organization already standardizes on containerized development, run Codex with Dev Containers and let Docker provide the outer isolation boundary. This works with Visual Studio Code Dev Containers and compatible tools.
|
||||
|
||||
Use the [Codex secure devcontainer example](https://github.com/openai/codex/tree/main/.devcontainer) as a reference implementation. The example installs Codex, common development tools, `bubblewrap`, and firewall-based outbound controls.
|
||||
|
||||
Devcontainers provide substantial protection, but they do not prevent every attack. If you run Codex with `--sandbox danger-full-access` or `--dangerously-bypass-approvals-and-sandbox` inside the container, a malicious project can exfiltrate anything available inside the devcontainer, including Codex credentials. Use this pattern only with trusted repositories, and monitor Codex activity as you would in any other elevated environment.
|
||||
|
||||
The reference implementation includes:
|
||||
|
||||
- an Ubuntu 24.04 base image with Codex and common development tools installed;
|
||||
- an allowlist-driven firewall profile for outbound access;
|
||||
- VS Code settings and extension recommendations for reopening the workspace in a container;
|
||||
- persistent mounts for command history and Codex configuration;
|
||||
- `bubblewrap`, so Codex can still use its Linux sandbox when the container grants the needed capabilities.
|
||||
|
||||
To try it:
|
||||
|
||||
1. Install Visual Studio Code and the [Dev Containers extension](https://marketplace.visualstudio.com/items?itemName=ms-vscode-remote.remote-containers).
|
||||
2. Copy the Codex example `.devcontainer` setup into your repository, or start from the Codex repository directly.
|
||||
3. In VS Code, run **Dev Containers: Open Folder in Container…** and select `.devcontainer/devcontainer.secure.json`.
|
||||
4. After the container starts, open a terminal and run `codex`.
|
||||
|
||||
You can also start the container from the CLI:
|
||||
|
||||
```bash
|
||||
devcontainer up --workspace-folder . --config .devcontainer/devcontainer.secure.json
|
||||
```
|
||||
|
||||
The example has three main pieces:
|
||||
|
||||
- `.devcontainer/devcontainer.secure.json` controls container settings, capabilities, mounts, environment variables, and VS Code extensions.
|
||||
- `.devcontainer/Dockerfile.secure` defines the Ubuntu-based image and installed tools.
|
||||
- `.devcontainer/init-firewall.sh` applies the outbound network policy.
|
||||
|
||||
The reference firewall is intentionally a starting point. If you depend on domain allowlisting for isolation, implement DNS rebinding and DNS refresh protections that fit your environment, such as TTL-aware refreshes or a DNS-aware firewall.
|
||||
|
||||
Inside the container, choose one of these modes:
|
||||
|
||||
- Keep Codex’s Linux sandbox enabled if the Dev Container profile grants the capabilities needed for `bwrap` to create the inner sandbox.
|
||||
- If the container is your intended security boundary, run Codex with `--sandbox danger-full-access` inside the container so Codex does not try to create a second sandbox layer.
|
||||
|
||||
## Version control
|
||||
|
||||
Codex works best with a version control workflow:
|
||||
|
||||
- Work on a feature branch and keep `git status` clean before delegating. This keeps Codex patches easier to isolate and revert.
|
||||
- Prefer patch-based workflows (for example, `git diff` / `git apply`) over editing tracked files directly. Commit frequently so you can roll back in small increments.
|
||||
- Treat Codex suggestions like any other PR: run targeted verification, review diffs, and document decisions in commit messages for auditing.
|
||||
|
||||
## Monitoring and telemetry
|
||||
|
||||
Codex supports opt-in monitoring via OpenTelemetry (OTel) to help teams audit usage, investigate issues, and meet compliance requirements without weakening local security defaults. Telemetry is off by default; enable it explicitly in your configuration.
|
||||
|
||||
### Overview
|
||||
|
||||
- Codex turns off OTel export by default to keep local runs self-contained.
|
||||
- When enabled, Codex emits structured log events covering conversations, API requests, SSE/WebSocket stream activity, user prompts (redacted by default), tool approval decisions, and tool results.
|
||||
- Codex tags exported events with `service.name` (originator), CLI version, and an environment label to separate dev/staging/prod traffic.
|
||||
|
||||
### Enable OTel (opt-in)
|
||||
|
||||
Add an `[otel]` block to your Codex configuration (typically `~/.codex/config.toml`), choosing an exporter and whether to log prompt text.
|
||||
|
||||
```toml
|
||||
[otel]
|
||||
environment = "staging" # dev | staging | prod
|
||||
exporter = "none" # none | otlp-http | otlp-grpc
|
||||
log_user_prompt = false # redact prompt text unless policy allows
|
||||
```
|
||||
- `exporter = "none"` leaves instrumentation active but doesn’t send data anywhere.
|
||||
- To send events to your own collector, pick one of:
|
||||
```toml
|
||||
[otel]
|
||||
exporter = { otlp-http = {
|
||||
endpoint = "https://otel.example.com/v1/logs",
|
||||
protocol = "binary",
|
||||
headers = { "x-otlp-api-key" = "${OTLP_TOKEN}" }
|
||||
}}
|
||||
```
|
||||
```toml
|
||||
[otel]
|
||||
exporter = { otlp-grpc = {
|
||||
endpoint = "https://otel.example.com:4317",
|
||||
headers = { "x-otlp-meta" = "abc123" }
|
||||
}}
|
||||
```
|
||||
|
||||
Codex batches events and flushes them on shutdown. Codex exports only telemetry produced by its OTel module.
|
||||
|
||||
### Event categories
|
||||
|
||||
Representative event types include:
|
||||
|
||||
- `codex.conversation_starts` (model, reasoning settings, sandbox/approval policy)
|
||||
- `codex.api_request` (attempt, status/success, duration, and error details)
|
||||
- `codex.sse_event` (stream event kind, success/failure, duration, plus token counts on `response.completed`)
|
||||
- `codex.websocket_request` and `codex.websocket_event` (request duration plus per-message kind/success/error)
|
||||
- `codex.user_prompt` (length; content redacted unless explicitly enabled)
|
||||
- `codex.tool_decision` (approved/denied, source: configuration vs. user)
|
||||
- `codex.tool_result` (duration, success, output snippet)
|
||||
|
||||
Associated OTel metrics (counter plus duration histogram pairs) include `codex.api_request`, `codex.sse_event`, `codex.websocket.request`, `codex.websocket.event`, and `codex.tool.call` (with corresponding `.duration_ms` instruments).
|
||||
|
||||
For the full event catalog and configuration reference, see the [Codex configuration documentation on GitHub](https://github.com/openai/codex/blob/main/docs/config.md#otel).
|
||||
|
||||
### Security and privacy guidance
|
||||
|
||||
- Keep `log_user_prompt = false` unless policy explicitly permits storing prompt contents. Prompts can include source code and sensitive data.
|
||||
- Route telemetry only to collectors you control; apply retention limits and access controls aligned with your compliance requirements.
|
||||
- Treat tool arguments and outputs as sensitive. Favor redaction at the collector or SIEM when possible.
|
||||
- Review local data retention settings (for example, `history.persistence` / `history.max_bytes`) if you don’t want Codex to save session transcripts under `CODEX_HOME`. See [Advanced Config](https://developers.openai.com/codex/config-advanced#history-persistence) and [Configuration Reference](https://developers.openai.com/codex/config-reference).
|
||||
- If you run the CLI with network access turned off, OTel export can’t reach your collector. To export, allow network access in `workspace-write` mode for the OTel endpoint, or export from Codex cloud with the collector domain on your approved list.
|
||||
- Review events periodically for approval/sandbox changes and unexpected tool executions.
|
||||
|
||||
OTel is optional and designed to complement, not replace, the sandbox and approval protections described above.
|
||||
|
||||
## Managed configuration
|
||||
|
||||
Enterprise admins can configure Codex security settings for their workspace in [Managed configuration](https://developers.openai.com/codex/enterprise/managed-configuration). See that page for setup and policy details.
|
||||
@@ -0,0 +1,37 @@
|
||||
---
|
||||
source_url: https://www.macrumors.com/2026/06/29/openclaw-ios-app/
|
||||
ingested: 2026-06-30
|
||||
sha256: c0644f83d634743605faa9e147783363054555697924cea33991052212625115
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521385175827877898'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T05:21:31.887000000Z
|
||||
message_excerpt: >-
|
||||
OpenClaw native iOS app signal for mobile agent operations and approvals.
|
||||
---
|
||||
|
||||
Popular open source AI agent OpenClaw is expanding to the iPhone and [iPad](https://www.macrumors.com/roundup/ipad/) with a new native iOS app. OpenClaw for iOS can be used alongside an existing gateway as a secure node for chat, voice approvals, sharing, and device-aware automation.
|
||||
|
||||
|
||||
The iOS app replaces iPhone and iPad workarounds that involved using Telegram or WhatsApp for on-the-go access.
|
||||
|
||||
OpenClaw is a self-hosted AI agent that runs on a Mac or PC. Users can connect an API key from Claude, OpenAI, Gemini, or other AI services, linking the model to content on the gateway machine. OpenClaw lets an AI model access messaging apps, files, web browsers, and more, so it can complete tasks.
|
||||
|
||||
To make use of the new iOS app, you'll need a gateway running on a local machine. The [App Store](https://www.macrumors.com/guide/app-store/) description says the iOS app can be used in multiple ways.
|
||||
|
||||
> - Pair with your private OpenClaw Gateway by QR code or setup code
|
||||
> - Chat with your assistant from iPhone
|
||||
> - Use realtime and background Talk mode
|
||||
> - Review Gateway action approvals from your iPhone
|
||||
> - Share text, links, and media directly from iOS into OpenClaw
|
||||
> - Enable device capabilities such as camera, screen, location, photos, contacts, calendar, and reminders when you choose
|
||||
> - Receive push wakes and node status updates for connected workflows
|
||||
|
||||
OpenClaw is a useful tool, but it has risks. It is susceptible to prompt injection and requires broad system permissions on gateway devices.
|
||||
|
||||
OpenClaw started out as Clawdbot, because the initial version created by Peter Steinberger used Claude. Anthropic complained about the name, prompting a rename.
|
||||
|
||||
The app can be downloaded from the App Store for free. \[[Direct Link](https://apps.apple.com/us/app/openclaw-ai-that-does-things/id6780396132)\]
|
||||
@@ -0,0 +1,44 @@
|
||||
---
|
||||
source_url: https://thehackernews.com/2026/06/oracle-e-business-suite-flaw-cve-2026.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 1d4888c2461d476a1aa0158902b19fcf8565e63f29f4dd977edffc3736868765
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521385175827877898'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T05:21:31.887000000Z
|
||||
message_excerpt: >-
|
||||
Oracle EBS active exploitation report from monitored Discord summary.
|
||||
---
|
||||
|
||||
[](https://blogger.googleusercontent.com/img/b/R29vZ2xl/AVvXsEhYwCBjb2uPzIs-8BNIxo90ae4xRgxzM1av-ijebBJ32Y2DEvRUvM-jMd6S535UdnbPKrLtFHxm0k9Lo7GJgVjCWCrH-0RNFZukDv7shdA02IkDs1Iqx8C-uH2hOCyfpJ01tmNVGhrvQ-6FGlmdjnCP0nXrq7zl5KVL3XZ84I9QTImD5DM8HYoJbA0A1P3w/s1700-e365/oracle.jpg)
|
||||
|
||||
A critical security flaw impacting Oracle E-Business Suite has come under active exploitation in the wild, according to Defused Cyber.
|
||||
|
||||
The vulnerability, tracked as **[CVE-2026-46817](https://nvd.nist.gov/vuln/detail/CVE-2026-46817)** (CVSS score: 9.8), refers to an improper privilege management and authentication flaw in Oracle Payments that could be abused to take over susceptible instances.
|
||||
|
||||
"Easily exploitable vulnerability allows unauthenticated attacker with network access via HTTP to compromise Oracle Payments," according to a description of the flaw in the NIST National Vulnerability Database (NVD). "Successful attacks of this vulnerability can result in the takeover of Oracle Payments."
|
||||
|
||||
The shortcoming impacts versions from 12.2.3 through 12.2.15. Patches for the flaw were [shipped](https://www.oracle.com/security-alerts/cspumay2026verbose.html) by Oracle as part of its Critical Security Patch Update last month.
|
||||
|
||||
[](https://thehackernews.uk/vpn-threat-report-m)
|
||||
|
||||
CVE-2026-46817 has since come under active exploitation, with Defused Cyber [noting](https://x.com/DefusedCyber/status/2071555353733394618) on Monday that "over the weekend, we observed an actor exploiting the vulnerability on our Oracle E-Business honeypots," adding "this vulnerability has no known previous exploitation and no public PoC \[proof-of-concept\] code exists."
|
||||
|
||||
That said, there are currently no details available on how the security flaw is being exploited, who is behind them, and if it's part of a broader opportunistic or targeted campaign aimed at unpatched systems.
|
||||
|
||||
Late last year, another critical flaw in the same product ([CVE-2025-61882](https://thehackernews.com/2025/10/oracle-ebs-under-fire-as-cl0p-exploits.html), CVSS score: 9.8) was weaponized by threat actors linked to the Cl0p ransomware operation, with early attacks launched as far back as August 2025.
|
||||
|
||||
Earlier this month, the company addressed a critical missing authentication zero-day vulnerability in PeopleSoft Suite ([CVE-2026-35273](https://thehackernews.com/2026/06/shinyhunters-exploits-oracle-peoplesoft.html), CVSS score: 9.8) that was actively exploited in ShinyHunters data theft and extortion attacks.
|
||||
|
||||
Automaker Nissan has since [acknowledged](https://oag.ca.gov/ecrime/databreach/reports/sb24-625558) that it was among those impacted, stating it was the victim of a break-in that involved the exploitation of the PeopleSoft flaw, potentially exposing payroll records, bank details, Social Security numbers, and other personal and financial data belong to its employees in the U.S., Canada, Mexico, and Brazil.
|
||||
|
||||
"What stood out was that CVE-2026-35273 isn't just another trivial, easy-to-exploit single-request vulnerability," Jake Knott, principal security researcher at watchTowr, said in a statement. "The attack chain is considerably more involved, combining multiple vulnerabilities to plant a malicious file that doesn’t execute immediately but waits until the server restarts."
|
||||
|
||||
"Where we would normally see simple bugs, this is a chain of multiple vulnerabilities, suggestive of a threat actor with genuine knowledge of and familiarity with the underlying codebase, and the ability to develop targeted capabilities against it."
|
||||
|
||||
Knott also pointed out that threat actors are exploiting vulnerabilities faster than ever before, urging organizations to assume compromise and activate incident response processes to determine whether access was obtained before patches were applied, what was accessed, and whether persistence was established.
|
||||
|
||||
SHARE **
|
||||
@@ -0,0 +1,72 @@
|
||||
---
|
||||
source_url: "https://www.preferred.jp/ja/news/pr20260622"
|
||||
ingested: 2026-06-30
|
||||
sha256: 5dcea81dc935e2f168c5a53b651e8e29988f9b68c25994556f62a07aacbb6a9a
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521445607905169540"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T09:21:40.017000000Z"
|
||||
message_excerpt: "PFN PLaMo 3.0 Prime primary release, kept as context for municipal/government AI evaluation discussion in the Discord digest."
|
||||
score: 2
|
||||
---
|
||||
|
||||
株式会社 Preferred Networks (本社:東京都千代田区、代表取締役社長:岡野原 大輔、以下 PFN )は、フルスクラッチで開発する国産生成 AI 基盤モデル PLaMo™ の最新フラッグシップモデル [PLaMo 3.0 Prime](https://plamo.preferredai.jp/) を本日正式に提供開始します。
|
||||
|
||||
PLaMo 3.0 Prime は、 2026 年 3 月に発表した PLaMo 3.0 Prime β (以下、β版)をもとに、モニター利用や社内評価を通じて得られた知見を反映し、企業利用における実用性を高めたモデルです。 API 経由またはオンプレミスでの利用が可能で、論理的思考を要する複雑なタスクに対応する Reasoning モデルに加え、応答速度の速い Non-reasoning モデルも提供することで、企業の様々な用途に応じて使い分けることができます。またコンテキスト長を 256k に拡張し、これまでにない長文の処理やエージェントでの利用が可能になりました。
|
||||
|
||||
|
||||
|
||||
### PLaMo 3.0 Primeの主な特長
|
||||
|
||||
- 推論力・精度の高い Reasoning モデルと、応答速度の速い Non-reasoning モデルを API またはオンプレミスで提供。企業の用途に応じて選択が可能
|
||||
- 独自開発のトークナイザによりトークン効率を高め、コストパフォーマンスが向上
|
||||
- 複雑な指示への対応、段階的推論、数理・アルゴリズム問題への対応力を強化
|
||||
- コーディング性能、ツール利用性能を高め、対応コンテキスト長を 64k から 256k に拡張することで、 AI エージェントとしての実務利用に対応
|
||||
- 独自データセットに加え、日本語の業務文書や対話、専門領域での利用を想定した学習・評価を行い、日本語での自然な文脈理解、論理展開、業務利用に必要な指示追従性能を向上
|
||||
- 危険な情報やセンシティブな情報に対する安全性が向上
|
||||
- 国立研究開発法人情報通信研究機構( NICT )との共同研究で得られた事前学習モデルをベースに開発した、国産生成 AI 基盤モデル PLaMo の最新フラッグシップモデル
|
||||
|
||||
Reasoning モデルは、複数の条件を整理しながら段階的に結論を導く能力に優れており、複雑な指示への対応、数理・アルゴリズム問題、専門性の高い質問応答、業務上の意思決定支援などに適しています。一方、 Non-reasoning モデルは、深い推論よりも応答速度が重視される用途に適しており、社内文書の要約、定型的な問い合わせ対応、情報抽出、分類、チャットボットなど、幅広い業務で効率的に活用できます。
|
||||
|
||||
|
||||
|
||||
PLaMo 3.0 Prime は高い日本語性能とコストパフォーマンスを両立
|
||||
|
||||
PFN が収集した複数の日本語ベンチマークの平均スコアとその評価にかかる推論・応答のコストで PLaMo 3.0 Prime と各モデルを比較 <sup>*1</sup> 。グラフの左上に行くほど、日本語力が高く、推論コストが低いことを示し、コストパフォーマンスに優れる。各点にはスコア / コスト / トークン数を記載しています。
|
||||
|
||||
|
||||
|
||||
指示した特定の出力形式に PLaMo がよく追従している例。 形式を守っているだけでなく、日本語による説明が簡潔でわかりやすい点も大きな特徴。
|
||||
|
||||
PLaMo 3.0 Prime は、β版で初めて導入された Reasoning 能力のさらなる強化に加え、日本語指示追従性の向上、外部ツールの呼び出し、複数ステップの処理、コード生成・修正、業務システムとの連携など、企業が生成 AI を実務に組み込む際に重要となる機能を強化しています。これにより、単発の質問応答にとどまらず、業務プロセスの一部を担う AI エージェントとしての応用が可能になります。
|
||||
|
||||
|
||||
|
||||
PLaMo 3.0 Prime は様々な日本語・英語のベンチマーク評価で性能が向上 \*2
|
||||
|
||||
PFN の社内評価では、 PLaMo 3.0 Prime は β 版および PLaMo 2.2 Prime と比較して、主要ベンチマークの大幅な性能向上が確認されています。また、 Qwen3.6-27B や gpt-oss-120b などの同性能帯のオープンモデルや、 GPT-5.4 mini 、 Claude Haiku 4.5 などの同価格帯のクローズドモデルとの比較においても、日本語での指示追従、コーディング、ツール利用などの領域で競争力のある結果を示しています。
|
||||
|
||||

|
||||
|
||||
PLaMo 3.0 Prime は HELM Safety の各カテゴリにおいて海外モデルと同等以上の安全性を確認 \*3
|
||||
|
||||
また、 NICT から提供を受けた安全性に関するデータを活用して PLaMo 3.0 Prime の安全性向上に取り組んだ結果、スタンフォード大学基盤モデル研究所が開発・運用する安全性評価ベンチマークスイート [HELM Safety](https://crfm.stanford.edu/helm/safety/latest/) において海外モデルと同程度以上の安全性能を達成しています。
|
||||
|
||||
**PLaMo 3.0 Prime** **および評価指標等の詳細はブログをご覧ください:**[https://tech.preferred.jp/ja/blog/plamo-3-0-prime-release/](https://tech.preferred.jp/ja/blog/plamo-3-0-prime-release/)
|
||||
|
||||
PFN は、今後も日本語性能に優れた国産生成 AI 基盤モデル PLaMo の開発と社会実装を進め、企業・自治体・研究機関における生成 AI 活用を支援するとともに、日本の産業競争力の強化に貢献していきます。
|
||||
|
||||
\*1 :日本語ベンチマークの詳細は [技術ブログ](https://tech.preferred.jp/ja/blog/plamo-3-0-prime-release/) を参照。評価コストは、実際にベンチマーク評価にかかった入力文および推論と応答のトークン数に、 PLaMo については PLaMo API の standard プランの料金、それ以外のモデルは [OpenRouter](https://openrouter.ai/) の平均価格をそれぞれ乗じて算出しています。
|
||||
|
||||
\*2 :その他のベンチマーク評価結果および測定条件は [技術ブログ](https://tech.preferred.jp/ja/blog/plamo-3-0-prime-release/) を参照。
|
||||
|
||||
\*3 : HELM Safety の測定条件は [技術ブログ](https://tech.preferred.jp/ja/blog/plamo-3-0-prime-release/) を参照。
|
||||
|
||||
**PLaMo** **について** [https://plamo.preferredai.jp/](https://plamo.preferredai.jp/)
|
||||
|
||||
PLaMo (プラモ)は、 PFN が主導して国内でフルスクラッチで開発する国産生成 AI 基盤モデルです。商用版のフラッグシップモデル PLaMo Prime 、自動車や製造設備などのエッジデバイス向けに軽量化された小規模言語モデル PLaMo Lite 、日本の金融知識を追加学習した金融特化型 PLaMo 、日本語の翻訳に特化した PLaMo 翻訳など、用途に合わせて提供しています。 PLaMo Prime はクラウド型 API 、 Amazon Bedrock Marketplace 、オンプレミス、 Snowflake で提供しています。国産 AI 構築プラットフォーム miibo 、法人向け生成 AI サービス Tachyon 生成 AI 、約 800 の自治体が導入する QommonsAI などのサービスに標準搭載されています。また、ガバメント AI としてデジタル庁が整備する生成 AI 利用環境「源内」で試用される国内大規模言語モデルの 1 つとして選定されています。
|
||||
|
||||
|
||||
@@ -0,0 +1,536 @@
|
||||
---
|
||||
source_url: "https://mariozechner.at/posts/2025-11-30-pi-coding-agent/"
|
||||
ingested: 2026-06-30
|
||||
sha256: dc49b7ab6ac876a3e98f4af032102c5606315c0c96d0e67d0a2caae092bd35e9
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1028287639918497822"
|
||||
channel_name: "chat"
|
||||
message_id: "1521463504773709945"
|
||||
author_id: "890908900520505354"
|
||||
posted_at: "2026-06-30T10:32:46.963000000Z"
|
||||
message_excerpt: "Direct #chat share of Mario Zechner’s pi coding-agent writeup."
|
||||
score: 4
|
||||
---
|
||||
2025-11-30
|
||||
|
||||
|
||||
|
||||
It's not much, but it's mine
|
||||
|
||||
## Table of contents
|
||||
|
||||
In the past three years, I've been using LLMs for assisted coding. If you read this, you probably went through the same evolution: from copying and pasting code into [ChatGPT](https://chatgpt.com/), to [Copilot](https://github.com/features/copilot) auto-completions (which never worked for me), to [Cursor](https://cursor.com/), and finally the new breed of coding agent harnesses like [Claude Code](https://claude.ai/code), [Codex](https://github.com/openai/codex), [Amp](https://ampcode.com/), [Droid](https://factory.ai/), and [opencode](https://opencode.ai/) that became our daily drivers in 2025.
|
||||
|
||||
I preferred Claude Code for most of my work. It was the first thing I tried back in April after using Cursor for a year and a half. Back then, it was much more basic. That fit my workflow perfectly, because I'm a simple boy who likes simple, predictable tools. Over the past few months, Claude Code has turned into a spaceship with 80% of functionality I have no use for. The [system prompt and tools also change](https://mariozechner.at/posts/2025-08-03-cchistory/) on every release, which breaks my workflows and changes model behavior. I hate that. Also, it flickers.
|
||||
|
||||
I've also built a bunch of agents over the years, of various complexity. For example, [Sitegeist](https://sitegeist.ai/), my little browser-use agent, is essentially a coding agent that lives inside the browser. In all that work, I learned that context engineering is paramount. Exactly controlling what goes into the model's context yields better outputs, especially when it's writing code. Existing harnesses make this extremely hard or impossible by injecting stuff behind your back that isn't even surfaced in the UI.
|
||||
|
||||
Speaking of surfacing things, I want to inspect every aspect of my interactions with the model. Basically no harness allows that. I also want a cleanly documented session format I can post-process automatically, and a simple way to build alternative UIs on top of the agent core. While some of this is possible with existing harnesses, the APIs smell like organic evolution. These solutions accumulated baggage along the way, which shows in the developer experience. I'm not blaming anyone for this. If tons of people use your shit and you need some sort of backwards compatibility, that's the price you pay.
|
||||
|
||||
I've also dabbled in self-hosting, both locally and on [DataCrunch](https://datacrunch.io/). While some harnesses like opencode support self-hosted models, it usually doesn't work well. Mostly because they rely on libraries like the [Vercel AI SDK](https://sdk.vercel.ai/), which doesn't play nice with self-hosted models for some reason, specifically when it comes to tool calling.
|
||||
|
||||
So what's an old guy yelling at Claudes going to do? He's going to write his own coding agent harness and give it a name that's entirely un-Google-able, so there will never be any users. Which means there will also never be any issues on the GitHub issue tracker. How hard can it be?
|
||||
|
||||
To make this work, I needed to build:
|
||||
|
||||
- **[pi-ai](https://github.com/badlogic/pi-mono/tree/main/packages/ai)**: A unified LLM API with multi-provider support (Anthropic, OpenAI, Google, xAI, Groq, Cerebras, OpenRouter, and any OpenAI-compatible endpoint), streaming, tool calling with TypeBox schemas, thinking/reasoning support, seamless cross-provider context handoffs, and token and cost tracking.
|
||||
- **[pi-agent-core](https://github.com/badlogic/pi-mono/tree/main/packages/agent)**: An agent loop that handles tool execution, validation, and event streaming.
|
||||
- **[pi-tui](https://github.com/badlogic/pi-mono/tree/main/packages/tui)**: A minimal terminal UI framework with differential rendering, synchronized output for (almost) flicker-free updates, and components like editors with autocomplete and markdown rendering.
|
||||
- **[pi-coding-agent](https://github.com/badlogic/pi-mono/tree/main/packages/coding-agent)**: The actual CLI that wires it all together with session management, custom tools, themes, and project context files.
|
||||
|
||||
My philosophy in all of this was: if I don't need it, it won't be built. And I don't need a lot of things.
|
||||
|
||||
## pi-ai and pi-agent-core
|
||||
|
||||
I'm not going to bore you with the API specifics of this package. You can read it all in the [README.md](https://github.com/badlogic/pi-mono/blob/main/packages/ai/README.md). Instead, I want to document the problems I ran into while creating a unified LLM API and how I resolved them. I'm not claiming my solutions are the best, but they've been working pretty well throughout various agentic and non-agentic LLM projects.
|
||||
|
||||
### There. Are. Four. Ligh... APIs
|
||||
|
||||
There's really only four APIs you need to speak to talk to pretty much any LLM provider: [OpenAI's Completions API](https://platform.openai.com/docs/api-reference/chat/create), their newer [Responses API](https://platform.openai.com/docs/api-reference/responses), [Anthropic's Messages API](https://docs.anthropic.com/en/api/messages), and [Google's Generative AI API](https://ai.google.dev/api).
|
||||
|
||||
They're all pretty similar in features, so building an abstraction on top of them isn't rocket science. There are, of course, provider-specific peculiarities you have to care for. That's especially true for the Completions API, which is spoken by pretty much all providers, but each of them has a different understanding of what this API should do. For example, while OpenAI doesn't support reasoning traces in their Completions API, other providers do in their version of the Completions API. This is also true for inference engines like [llama.cpp](https://github.com/ggml-org/llama.cpp), [Ollama](https://ollama.com/), [vLLM](https://github.com/vllm-project/vllm), and [LM Studio](https://lmstudio.ai/).
|
||||
|
||||
For example, in [openai-completions.ts](https://github.com/badlogic/pi-mono/blob/main/packages/ai/src/providers/openai-completions.ts):
|
||||
|
||||
- Cerebras, xAI, Mistral, and Chutes don't like the `store` field
|
||||
- Mistral and Chutes use `max_tokens` instead of `max_completion_tokens`
|
||||
- Cerebras, xAI, Mistral, and Chutes don't support the `developer` role for system prompts
|
||||
- Grok models don't like `reasoning_effort`
|
||||
- Different providers return reasoning content in different fields (`reasoning_content` vs `reasoning`)
|
||||
|
||||
To ensure all features actually work across the gazillion of providers, pi-ai has a pretty extensive test suite covering image inputs, reasoning traces, tool calling, and other features you'd expect from an LLM API. Tests run across all supported providers and popular models. While this is a good effort, it still won't guarantee that new models and providers will just work out of the box.
|
||||
|
||||
Another big difference is how providers report tokens and cache reads/writes. Anthropic has the sanest approach, but generally it's the Wild West. Some report token counts at the start of the SSE stream, others only at the end, making accurate cost tracking impossible if a request is aborted. To add insult to injury, you can't provide a unique ID to later correlate with their billing APIs and figure out which of your users consumed how many tokens. So pi-ai does token and cache tracking on a best-effort basis. Good enough for personal use, but not for accurate billing if you have end users consuming tokens through your service.
|
||||
|
||||
Special shout out to Google who to this date seem to not support tool call streaming which is extremely Google.
|
||||
|
||||
pi-ai also works in the browser, which is useful for building web-based interfaces. Some providers make this especially easy by supporting CORS, specifically Anthropic and xAI.
|
||||
|
||||
### Context handoff
|
||||
|
||||
Context handoff between providers was a feature pi-ai was designed for from the start. Since each provider has their own way of tracking tool calls and thinking traces, this can only be a best-effort thing. For example, if you switch from Anthropic to OpenAI mid-session, Anthropic thinking traces are converted to content blocks inside assistant messages, delimited by `<thinking></thinking>` tags. This may or may not be sensible, because the thinking traces returned by Anthropic and OpenAI don't actually represent what's happening behind the scenes.
|
||||
|
||||
These providers also insert signed blobs into the event stream that you have to replay on subsequent requests containing the same messages. This also applies when switching models within a provider. It makes for a cumbersome abstraction and transformation pipeline in the background.
|
||||
|
||||
I'm happy to report that cross-provider context handoff and context serialization/deserialization work pretty well in pi-ai:
|
||||
|
||||
```typescript
|
||||
import { getModel, complete, Context } from '@mariozechner/pi-ai';
|
||||
|
||||
// Start with Claude
|
||||
const claude = getModel('anthropic', 'claude-sonnet-4-5');
|
||||
const context: Context = {
|
||||
messages: []
|
||||
};
|
||||
|
||||
context.messages.push({ role: 'user', content: 'What is 25 * 18?' });
|
||||
const claudeResponse = await complete(claude, context, {
|
||||
thinkingEnabled: true
|
||||
});
|
||||
context.messages.push(claudeResponse);
|
||||
|
||||
// Switch to GPT - it will see Claude's thinking as <thinking> tagged text
|
||||
const gpt = getModel('openai', 'gpt-5.1-codex');
|
||||
context.messages.push({ role: 'user', content: 'Is that correct?' });
|
||||
const gptResponse = await complete(gpt, context);
|
||||
context.messages.push(gptResponse);
|
||||
|
||||
// Switch to Gemini
|
||||
const gemini = getModel('google', 'gemini-2.5-flash');
|
||||
context.messages.push({ role: 'user', content: 'What was the question?' });
|
||||
const geminiResponse = await complete(gemini, context);
|
||||
|
||||
// Serialize context to JSON (for storage, transfer, etc.)
|
||||
const serialized = JSON.stringify(context);
|
||||
|
||||
// Later: deserialize and continue with any model
|
||||
const restored: Context = JSON.parse(serialized);
|
||||
restored.messages.push({ role: 'user', content: 'Summarize our conversation' });
|
||||
const continuation = await complete(claude, restored);
|
||||
```
|
||||
|
||||
### We live in a multi-model world
|
||||
|
||||
Speaking of models, I wanted a typesafe way of specifying them in the `getModel` call. For that I needed a model registry that I could turn into TypeScript types. I'm parsing data from both [OpenRouter](https://openrouter.ai/) and [models.dev](https://models.dev/) (created by the opencode folks, thanks for that, it's super useful) into [models.generated.ts](https://github.com/badlogic/pi-mono/blob/main/packages/ai/src/models.generated.ts). This includes token costs and capabilities like image inputs and thinking support.
|
||||
|
||||
And if I ever need to add a model that's not in the registry, I wanted a type system that makes it easy to create new ones. This is especially useful when working with self-hosted models, new releases that aren't yet on models.dev or OpenRouter, or trying out one of the more obscure LLM providers:
|
||||
|
||||
```typescript
|
||||
import { Model, stream } from '@mariozechner/pi-ai';
|
||||
|
||||
const ollamaModel: Model<'openai-completions'> = {
|
||||
id: 'llama-3.1-8b',
|
||||
name: 'Llama 3.1 8B (Ollama)',
|
||||
api: 'openai-completions',
|
||||
provider: 'ollama',
|
||||
baseUrl: 'http://localhost:11434/v1',
|
||||
reasoning: false,
|
||||
input: ['text'],
|
||||
cost: { input: 0, output: 0, cacheRead: 0, cacheWrite: 0 },
|
||||
contextWindow: 128000,
|
||||
maxTokens: 32000
|
||||
};
|
||||
|
||||
const response = await stream(ollamaModel, context, {
|
||||
apiKey: 'dummy' // Ollama doesn't need a real key
|
||||
});
|
||||
```
|
||||
|
||||
Many unified LLM APIs completely ignore providing a way to abort requests. This is entirely unacceptable if you want to integrate your LLM into any kind of production system. Many unified LLM APIs also don't return partial results to you, which is kind of ridiculous. pi-ai was designed from the beginning to support aborts throughout the entire pipeline, including tool calls. Here's how it works:
|
||||
|
||||
```typescript
|
||||
import { getModel, stream } from '@mariozechner/pi-ai';
|
||||
|
||||
const model = getModel('openai', 'gpt-5.1-codex');
|
||||
const controller = new AbortController();
|
||||
|
||||
// Abort after 2 seconds
|
||||
setTimeout(() => controller.abort(), 2000);
|
||||
|
||||
const s = stream(model, {
|
||||
messages: [{ role: 'user', content: 'Write a long story' }]
|
||||
}, {
|
||||
signal: controller.signal
|
||||
});
|
||||
|
||||
for await (const event of s) {
|
||||
if (event.type === 'text_delta') {
|
||||
process.stdout.write(event.delta);
|
||||
} else if (event.type === 'error') {
|
||||
console.log(\`${event.reason === 'aborted' ? 'Aborted' : 'Error'}:\`, event.error.errorMessage);
|
||||
}
|
||||
}
|
||||
|
||||
// Get results (may be partial if aborted)
|
||||
const response = await s.result();
|
||||
if (response.stopReason === 'aborted') {
|
||||
console.log('Partial content:', response.content);
|
||||
}
|
||||
```
|
||||
|
||||
### Structured split tool results
|
||||
|
||||
Another abstraction I haven't seen in any unified LLM API is splitting tool results into a portion handed to the LLM and a portion for UI display. The LLM portion is generally just text or JSON, which doesn't necessarily contain all the information you'd want to show in a UI. It also sucks hard to parse textual tool outputs and restructure them for display in a UI. pi-ai's tool implementation allows returning both content blocks for the LLM and separate content blocks for UI rendering. Tools can also return attachments like images that get attached in the native format of the respective provider. Tool arguments are automatically validated using [TypeBox](https://github.com/sinclairzx81/typebox) schemas and [AJV](https://ajv.js.org/), with detailed error messages when validation fails:
|
||||
|
||||
```typescript
|
||||
import { Type, AgentTool } from '@mariozechner/pi-ai';
|
||||
|
||||
const weatherSchema = Type.Object({
|
||||
city: Type.String({ minLength: 1 }),
|
||||
});
|
||||
|
||||
const weatherTool: AgentTool<typeof weatherSchema, { temp: number }> = {
|
||||
name: 'get_weather',
|
||||
description: 'Get current weather for a city',
|
||||
parameters: weatherSchema,
|
||||
execute: async (toolCallId, args) => {
|
||||
const temp = Math.round(Math.random() * 30);
|
||||
return {
|
||||
// Text for the LLM
|
||||
output: \`Temperature in ${args.city}: ${temp}°C\`,
|
||||
// Structured data for the UI
|
||||
details: { temp }
|
||||
};
|
||||
}
|
||||
};
|
||||
|
||||
// Tools can also return images
|
||||
const chartTool: AgentTool = {
|
||||
name: 'generate_chart',
|
||||
description: 'Generate a chart from data',
|
||||
parameters: Type.Object({ data: Type.Array(Type.Number()) }),
|
||||
execute: async (toolCallId, args) => {
|
||||
const chartImage = await generateChartImage(args.data);
|
||||
return {
|
||||
content: [
|
||||
{ type: 'text', text: \`Generated chart with ${args.data.length} data points\` },
|
||||
{ type: 'image', data: chartImage.toString('base64'), mimeType: 'image/png' }
|
||||
]
|
||||
};
|
||||
}
|
||||
};
|
||||
```
|
||||
|
||||
What's still lacking is tool result streaming. Imagine a bash tool where you want to display ANSI sequences as they come in. That's currently not possible, but it's a simple fix that will eventually make it into the package.
|
||||
|
||||
Partial JSON parsing during tool call streaming is essential for good UX. As the LLM streams tool call arguments, pi-ai progressively parses them so you can show partial results in the UI before the call completes. For example, you can display a diff streaming in as the agent rewrites a file.
|
||||
|
||||
### Minimal agent scaffold
|
||||
|
||||
Finally, pi-ai provides an [agent loop](https://github.com/badlogic/pi-mono/blob/main/packages/ai/src/agent/agent-loop.ts) that handles the full orchestration: processing user messages, executing tool calls, feeding results back to the LLM, and repeating until the model produces a response without tool calls. The loop also supports message queuing via a callback: after each turn, it asks for queued messages and injects them before the next assistant response. The loop emits events for everything, making it easy to build reactive UIs.
|
||||
|
||||
The agent loop doesn't let you specify max steps or similar knobs you'd find in other unified LLM APIs. I never found a use case for that, so why add it? The loop just loops until the agent says it's done. On top of the loop, however, [pi-agent-core](https://github.com/badlogic/pi-mono/tree/main/packages/agent) provides an `Agent` class with actually useful stuff: state management, simplified event subscriptions, message queuing with two modes (one-at-a-time or all-at-once), attachment handling (images, documents), and a transport abstraction that lets you run the agent either directly or through a proxy.
|
||||
|
||||
Am I happy with pi-ai? For the most part, yes. Like any unifying API, it can never be perfect due to leaky abstractions. But it's been used in seven different production projects and has served me extremely well.
|
||||
|
||||
Why build this instead of using the Vercel AI SDK? [Armin's blog post](https://lucumr.pocoo.org/2025/11/21/agents-are-hard/) mirrors my experience. Building on top of the provider SDKs directly gives me full control and lets me design the APIs exactly as I want, with a much smaller surface area. Armin's blog gives you a more in-depth treatise on the reasons for building your own. Go read that.
|
||||
|
||||
## pi-tui
|
||||
|
||||
I grew up in the DOS era, so terminal user interfaces are what I grew up with. From the fancy setup programs for Doom to Borland products, TUIs were with me until the end of the 90s. And boy was I fucking happy when I eventually switched to a GUI operating system. While TUIs are mostly portable and easily streamable, they also suck at information density. Having said all that, I thought starting with a terminal user interface for pi makes the most sense. I could strap on a GUI later whenever I felt like I needed to.
|
||||
|
||||
So why build my own TUI framework? I've looked into the alternatives like [Ink](https://github.com/vadimdemedes/ink), [Blessed](https://github.com/chjj/blessed), [OpenTUI](https://github.com/sst/opentui), and so on. I'm sure they're all fine in their own way, but I definitely don't want to write my TUI like a React app. Blessed seems to be mostly unmaintained, and OpenTUI is explicitly not production ready. Also, writing my own TUI framework on top of Node.js seemed like a fun little challenge.
|
||||
|
||||
### Two kinds of TUIs
|
||||
|
||||
Writing a terminal user interface is not rocket science per se. You just have to pick your poison. There's basically two ways to do it. One is to take ownership of the terminal viewport (the portion of the terminal contents you can actually see) and treat it like a pixel buffer. Instead of pixels you have cells that contain characters with background color, foreground color, and styling like italic and bold. I call these full screen TUIs. Amp and opencode use this approach.
|
||||
|
||||
The drawback is that you lose the scrollback buffer, which means you have to implement custom search. You also lose scrolling, which means you have to simulate scrolling within the viewport yourself. While this is not hard to implement, it means you have to re-implement all the functionality your terminal emulator already provides. Mouse scrolling specifically always feels kind of off in such TUIs.
|
||||
|
||||
The second approach is to just write to the terminal like any CLI program, appending content to the scrollback buffer, only occasionally moving the "rendering cursor" back up a little within the visible viewport to redraw things like animated spinners or a text edit field. It's not exactly that simple, but you get the idea. This is what Claude Code, Codex, and Droid do.
|
||||
|
||||
Coding agents have this nice property that they're basically a chat interface. The user writes a prompt, followed by replies from the agent and tool calls and their results. Everything is nicely linear, which lends itself well to working with the "native" terminal emulator. You get to use all the built-in functionality like natural scrolling and search within the scrollback buffer. It also limits what your TUI can do to some degree, which I find charming because constraints make for minimal programs that just do what they're supposed to do without superfluous fluff. This is the direction I picked for pi-tui.
|
||||
|
||||
### Retained mode UI
|
||||
|
||||
If you've done any GUI programming, you've probably heard of retained mode vs immediate mode. In a retained mode UI, you build up a tree of components that persist across frames. Each component knows how to render itself and can cache its output if nothing changed. In an immediate mode UI, you redraw everything from scratch each frame (though in practice, immediate mode UIs also do caching, otherwise they'd fall apart).
|
||||
|
||||
pi-tui uses a simple retained mode approach. A `Component` is just an object with a `render(width)` method that returns an array of strings (lines that fit the viewport horizontally, with ANSI escape codes for colors and styling) and an optional `handleInput(data)` method for keyboard input. A `Container` holds a list of components arranged vertically and collects all their rendered lines. The `TUI` class is itself a container that orchestrates everything.
|
||||
|
||||
When the TUI needs to update the screen, it asks each component to render. Components can cache their output: an assistant message that's fully streamed doesn't need to re-parse markdown and re-render ANSI sequences every time. It just returns the cached lines. Containers collect lines from all children. The TUI gathers all these lines and compares them to the lines it previously rendered for the previous component tree. It keeps a backbuffer of sorts, remembering what was written to the scrollback buffer.
|
||||
|
||||
Then it only redraws what changed, using a method I call differential rendering. I'm very bad with names, and this likely has an official name.
|
||||
|
||||
### Differential rendering
|
||||
|
||||
Here's a simplified demo that illustrates what exactly gets redrawn.
|
||||
|
||||
The algorithm is simple:
|
||||
|
||||
1. **First render**: Just output all lines to the terminal
|
||||
2. **Width changed**: Clear screen completely and re-render everything (soft wrapping changes)
|
||||
3. **Normal update**: Find the first line that differs from what's on screen, move the cursor to that line, and re-render from there to the end
|
||||
|
||||
There's one catch: if the first changed line is above the visible viewport (the user scrolled up), we have to do a full clear and re-render. The terminal doesn't let you write to the scrollback buffer above the viewport.
|
||||
|
||||
To prevent flicker during updates, pi-tui wraps all rendering in synchronized output escape sequences (`CSI ?2026h` and `CSI ?2026l`). This tells the terminal to buffer all the output and display it atomically. Most modern terminals support this.
|
||||
|
||||
How well does it work and how much does it flicker? In any capable terminal like Ghostty or iTerm2, this works brilliantly and you never see any flicker. In less fortunate terminal implementations like VS Code's built-in terminal, you will get some flicker depending on the time of day, your display size, your window size, and so on. Given that I'm very accustomed to Claude Code, I haven't spent any more time optimizing this. I'm happy with the little flicker I get in VS Code. I wouldn't feel at home otherwise. And it still flickers less than Claude Code.
|
||||
|
||||
How wasteful is this approach? We store an entire scrollback buffer worth of previously rendered lines, and we re-render lines every time the TUI is asked to render itself. That's alleviated with the caching I described above, so the re-rendering isn't a big deal. We still have to compare a lot of lines with each other. Realistically, on computers younger than 25 years, this is not a big deal, both in terms of performance and memory use (a few hundred kilobytes for very large sessions). Thanks V8. What I get in return is a dead simple programming model that lets me iterate quickly.
|
||||
|
||||
## pi-coding-agent
|
||||
|
||||
I don't need to explain what features you should expect from a coding agent harness. pi comes with most creature comforts you're used to from other tools:
|
||||
|
||||
- Runs on Windows, Linux, and macOS (or anything with a Node.js runtime and a terminal)
|
||||
- Multi-provider support with mid-session model switching
|
||||
- Session management with continue, resume, and branching
|
||||
- Project context files (AGENTS.md) loaded hierarchically from global to project-specific
|
||||
- Slash commands for common operations
|
||||
- Custom slash commands as markdown templates with argument support
|
||||
- OAuth authentication for Claude Pro/Max subscriptions
|
||||
- Custom model and provider configuration via JSON
|
||||
- Customizable themes with live reload
|
||||
- Editor with fuzzy file search, path completion, drag & drop, and multi-line paste
|
||||
- Message queuing while the agent is working
|
||||
- Image support for vision-capable models
|
||||
- HTML export of sessions
|
||||
- Headless operation via JSON streaming and RPC mode
|
||||
- Full cost and token tracking
|
||||
|
||||
If you want the full rundown, read the [README](https://github.com/badlogic/pi-mono/blob/main/packages/coding-agent/README.md). What's more interesting is where pi deviates from other harnesses in philosophy and implementation.
|
||||
|
||||
### Minimal system prompt
|
||||
|
||||
Here's the system prompt:
|
||||
|
||||
```markdown
|
||||
You are an expert coding assistant. You help users with coding tasks by reading files, executing commands, editing code, and writing new files.
|
||||
|
||||
Available tools:
|
||||
- read: Read file contents
|
||||
- bash: Execute bash commands
|
||||
- edit: Make surgical edits to files
|
||||
- write: Create or overwrite files
|
||||
|
||||
Guidelines:
|
||||
- Use bash for file operations like ls, grep, find
|
||||
- Use read to examine files before editing
|
||||
- Use edit for precise changes (old text must match exactly)
|
||||
- Use write only for new files or complete rewrites
|
||||
- When summarizing your actions, output plain text directly - do NOT use cat or bash to display what you did
|
||||
- Be concise in your responses
|
||||
- Show file paths clearly when working with files
|
||||
|
||||
Documentation:
|
||||
- Your own documentation (including custom model setup and theme creation) is at: /path/to/README.md
|
||||
- Read it when users ask about features, configuration, or setup, and especially if the user asks you to add a custom model or provider, or create a custom theme.
|
||||
```
|
||||
|
||||
That's it. The only thing that gets injected at the bottom is your AGENTS.md file. Both the global one that applies to all your sessions and the project-specific one stored in your project directory. This is where you can customize pi to your liking. You can even replace the full system prompt if you want to. Compared to, for example, [Claude Code's system prompt](https://cchistory.mariozechner.at/), [Codex's system prompt](https://github.com/openai/codex/blob/main/codex-rs/core/prompt.md), or [opencode's model-specific prompts](https://github.com/sst/opencode/tree/dev/packages/opencode/src/session/prompt) (the Claude one is a [cut-down version](https://github.com/sst/opencode/blob/dev/packages/opencode/src/session/prompt/anthropic.txt) of the [original Claude Code prompt](https://github.com/sst/opencode/blob/dev/packages/opencode/src/session/prompt/anthropic-20250930.txt) they copied).
|
||||
|
||||
You might think this is crazy. In all likelihood, the models have some training on their native coding harness. So using the native system prompt or something close to it like opencode would be most ideal. But it turns out that all the frontier models have been RL-trained up the wazoo, so they inherently understand what a coding agent is. There does not appear to be a need for 10,000 tokens of system prompt, as we'll find out later in the benchmark section, and as I've anecdotally found out by exclusively using pi for the past few weeks. Amp, while copying some parts of the native system prompts, seems to also do just fine with their own prompt.
|
||||
|
||||
### Minimal toolset
|
||||
|
||||
Here are the tool definitions:
|
||||
|
||||
```
|
||||
read
|
||||
Read the contents of a file. Supports text files and images (jpg, png,
|
||||
gif, webp). Images are sent as attachments. For text files, defaults to
|
||||
first 2000 lines. Use offset/limit for large files.
|
||||
- path: Path to the file to read (relative or absolute)
|
||||
- offset: Line number to start reading from (1-indexed)
|
||||
- limit: Maximum number of lines to read
|
||||
|
||||
write
|
||||
Write content to a file. Creates the file if it doesn't exist, overwrites
|
||||
if it does. Automatically creates parent directories.
|
||||
- path: Path to the file to write (relative or absolute)
|
||||
- content: Content to write to the file
|
||||
|
||||
edit
|
||||
Edit a file by replacing exact text. The oldText must match exactly
|
||||
(including whitespace). Use this for precise, surgical edits.
|
||||
- path: Path to the file to edit (relative or absolute)
|
||||
- oldText: Exact text to find and replace (must match exactly)
|
||||
- newText: New text to replace the old text with
|
||||
|
||||
bash
|
||||
Execute a bash command in the current working directory. Returns stdout
|
||||
and stderr. Optionally provide a timeout in seconds.
|
||||
- command: Bash command to execute
|
||||
- timeout: Timeout in seconds (optional, no default timeout)
|
||||
```
|
||||
|
||||
There are additional read-only tools (grep, find, ls) if you want to restrict the agent from modifying files or running arbitrary commands. By default these are disabled, so the agent only gets the four tools above.
|
||||
|
||||
As it turns out, these four tools are all you need for an effective coding agent. Models know how to use bash and have been trained on the read, write, and edit tools with similar input schemas. Compare this to [Claude Code's tool definitions](https://cchistory.mariozechner.at/) or [opencode's tool definitions](https://github.com/sst/opencode/tree/dev/packages/opencode/src/tool) (which are clearly derived from Claude Code's, same structure, same examples, same git commit flow). Notably, [Codex's tool definitions](https://github.com/openai/codex/blob/main/codex-rs/core/src/tools/spec.rs) are similarly minimal to pi's.
|
||||
|
||||
pi's system prompt and tool definitions together come in below 1000 tokens.
|
||||
|
||||
### YOLO by default
|
||||
|
||||
pi runs in full YOLO mode and assumes you know what you're doing. It has unrestricted access to your filesystem and can execute any command without permission checks or safety rails. No permission prompts for file operations or commands. No [pre-checking of bash commands by Haiku](https://mariozechner.at/posts/2025-08-03-cchistory/#haiku-this-haiku-that) for malicious content. Full filesystem access. Can execute any command with your user privileges.
|
||||
|
||||
If you look at the security measures in other coding agents, they're mostly security theater. As soon as your agent can write code and run code, it's pretty much game over. The only way you could prevent exfiltration of data would be to cut off all network access for the execution environment the agent runs in, which makes the agent mostly useless. An alternative is allow-listing domains, but this can also be worked around through other means.
|
||||
|
||||
Simon Willison has [written extensively](https://simonwillison.net/2023/Apr/25/dual-llm-pattern/) about this problem. His "dual LLM" pattern attempts to address confused deputy attacks and data exfiltration, but even he admits "this solution is pretty bad" and introduces enormous implementation complexity. The core issue remains: if an LLM has access to tools that can read private data and make network requests, you're playing whack-a-mole with attack vectors.
|
||||
|
||||
Since we cannot solve this trifecta of capabilities (read data, execute code, network access), pi just gives in. Everybody is running in YOLO mode anyways to get any productive work done, so why not make it the default and only option?
|
||||
|
||||
By default, pi has no web search or fetch tool. However, it can use `curl` or read files from disk, both of which provide ample surface area for prompt injection attacks. Malicious content in files or command outputs can influence behavior. If you're uncomfortable with full access, run pi inside a container or use a different tool if you need (faux) guardrails.
|
||||
|
||||
### No built-in to-dos
|
||||
|
||||
pi does not and will not support built-in to-dos. In my experience, to-do lists generally confuse models more than they help. They add state that the model has to track and update, which introduces more opportunities for things to go wrong.
|
||||
|
||||
If you need task tracking, make it externally stateful by writing to a file:
|
||||
|
||||
```markdown
|
||||
# TODO.md
|
||||
|
||||
- [x] Implement user authentication
|
||||
- [x] Add database migrations
|
||||
- [ ] Write API documentation
|
||||
- [ ] Add rate limiting
|
||||
```
|
||||
|
||||
The agent can read and update this file as needed. Using checkboxes keeps track of what's done and what remains. Simple, visible, and under your control.
|
||||
|
||||
### No plan mode
|
||||
|
||||
pi does not and will not have a built-in plan mode. Telling the agent to think through a problem together with you, without modifying files or executing commands, is generally sufficient.
|
||||
|
||||
If you need persistent planning across sessions, write it to a file:
|
||||
|
||||
```markdown
|
||||
# PLAN.md
|
||||
|
||||
## Goal
|
||||
Refactor authentication system to support OAuth
|
||||
|
||||
## Approach
|
||||
1. Research OAuth 2.0 flows
|
||||
2. Design token storage schema
|
||||
3. Implement authorization server endpoints
|
||||
4. Update client-side login flow
|
||||
5. Add tests
|
||||
|
||||
## Current Step
|
||||
Working on step 3 - authorization endpoints
|
||||
```
|
||||
|
||||
The agent can read, update, and reference the plan as it works. Unlike ephemeral planning modes that only exist within a session, file-based plans can be shared across sessions, and can be versioned with your code.
|
||||
|
||||
Funnily enough, Claude Code now has a [Plan Mode](https://code.claude.com/docs/en/common-workflows#use-plan-mode-for-safe-code-analysis) that's essentially read-only analysis, and it will eventually write a markdown file to disk. And you can basically not use plan mode without approving a shit ton of command invocations, because without that, planning is basically impossible.
|
||||
|
||||
The difference with pi is that I have full observability of everything. I get to see which sources the agent actually looked at and which ones it totally missed. In Claude Code, the orchestrating Claude instance usually spawns a sub-agent and you have zero visibility into what that sub-agent does. I get to see the markdown file immediately. I can edit it collaboratively with the agent. In short, I need observability for planning and I don't get that with Claude Code's plan mode.
|
||||
|
||||
If you must restrict the agent during planning, you can specify which tools it has access to via the CLI:
|
||||
|
||||
```bash
|
||||
pi --tools read,grep,find,ls
|
||||
```
|
||||
|
||||
This gives you read-only mode for exploration and planning without the agent modifying anything or being able to run bash commands. You won't be happy with that though.
|
||||
|
||||
### No MCP support
|
||||
|
||||
pi does not and will not support MCP. I've [written about this extensively](https://mariozechner.at/posts/2025-11-02-what-if-you-dont-need-mcp/), but the TL;DR is: MCP servers are overkill for most use cases, and they come with significant context overhead.
|
||||
|
||||
Popular MCP servers like Playwright MCP (21 tools, 13.7k tokens) or Chrome DevTools MCP (26 tools, 18k tokens) dump their entire tool descriptions into your context on every session. That's 7-9% of your context window gone before you even start working. Many of these tools you'll never use in a given session.
|
||||
|
||||
The alternative is simple: build CLI tools with README files. The agent reads the README when it needs the tool, pays the token cost only when necessary (progressive disclosure), and can use bash to invoke the tool. This approach is composable (pipe outputs, chain commands), easy to extend (just add another script), and token-efficient.
|
||||
|
||||
Here's how I add web search to pi:
|
||||
|
||||
<video src="https://mariozechner.at/posts/2025-11-30-pi-coding-agent/media/websearch.mp4" controls=""></video>
|
||||
|
||||
I maintain a collection of these tools at [github.com/badlogic/agent-tools](https://github.com/badlogic/agent-tools). Each tool is a simple CLI with a README that the agent reads on demand.
|
||||
|
||||
If you absolutely must use MCP servers, look into [Peter Steinberger's](https://x.com/steipete) [mcporter](https://github.com/steipete/mcporter) tool that wraps MCP servers as CLI tools.
|
||||
|
||||
### No background bash
|
||||
|
||||
pi's bash tool runs commands synchronously. There's no built-in way to start a dev server, run tests in the background, or interact with a REPL while the command is still running.
|
||||
|
||||
This is intentional. Background process management adds complexity: you need process tracking, output buffering, cleanup on exit, and ways to send input to running processes. Claude Code handles some of this with their background bash feature, but it has poor observability (a common theme with Claude Code) and forces the agent to track running instances without providing a tool to query them. In earlier Claude Code versions, the agent forgot about all its background processes after context compaction and had no way to query them, so you had to manually kill them. This has since been fixed.
|
||||
|
||||
Use [tmux](https://github.com/tmux/tmux) instead. Here's pi debugging a crashing C program in LLDB:
|
||||
|
||||
<video src="https://mariozechner.at/posts/2025-11-30-pi-coding-agent/media/tmux.mp4" controls=""></video>
|
||||
|
||||
How's that for observability? The same approach works for long-running dev servers, watching log output, and similar use cases. And if you wanted to, you could hop into that LLDB session above via tmux and co-debug with the agent. Tmux also gives you a CLI argument to list all active sessions. How nice.
|
||||
|
||||
There's simply no need for background bash. Claude Code can use tmux too, you know. Bash is all you need.
|
||||
|
||||
### No sub-agents
|
||||
|
||||
pi does not have a dedicated sub-agent tool. When Claude Code needs to do something complex, it often spawns a sub-agent to handle part of the task. You have zero visibility into what that sub-agent does. It's a black box within a black box. Context transfer between agents is also poor. The orchestrating agent decides what initial context to pass to the sub-agent, and you generally have little control over that. If the sub-agent makes a mistake, debugging is painful because you can't see the full conversation.
|
||||
|
||||
If you need pi to spawn itself, just ask it to run itself via bash. You could even have it spawn itself inside a tmux session for full observability and the ability to interact with that sub-agent directly.
|
||||
|
||||
|
||||
|
||||
But more importantly: fix your workflow, at least the ones that are all about context gathering. People use sub-agents within a session thinking they're saving context space, which is true. But that's the wrong way to think about sub-agents. Using a sub-agent mid-session for context gathering is a sign you didn't plan ahead. If you need to gather context, do that first in its own session. Create an artifact that you can later use in a fresh session to give your agent all the context it needs without polluting its context window with tool outputs. That artifact can be useful for the next feature too, and you get full observability and steerability, which is important during context gathering.
|
||||
|
||||
Because despite popular belief, models are still poor at finding all the context needed for implementing a new feature or fixing a bug. I attribute this to models being trained to only read parts of files rather than full files, so they're hesitant to read everything. Which means they miss important context and can't see what they need to properly complete the task.
|
||||
|
||||
Just look at the [pi-mono issue tracker](https://github.com/badlogic/pi-mono/issues) and the pull requests. Many get closed or revised because the agents couldn't fully grasp what's needed. That's not the fault of the contributors, which I truly appreciate because even incomplete PRs help me move faster. It just means we trust our agents too much.
|
||||
|
||||
I'm not dismissing sub-agents entirely. There are valid use cases. My most common one is code review: I tell pi to spawn itself with a code review prompt (via a custom slash command) and it gets the outputs.
|
||||
|
||||
```markdown
|
||||
---
|
||||
description: Run a code review sub-agent
|
||||
---
|
||||
Spawn yourself as a sub-agent via bash to do a code review: $@
|
||||
|
||||
Use \`pi --print\` with appropriate arguments. If the user specifies a model,
|
||||
use \`--provider\` and \`--model\` accordingly.
|
||||
|
||||
Pass a prompt to the sub-agent asking it to review the code for:
|
||||
- Bugs and logic errors
|
||||
- Security issues
|
||||
- Error handling gaps
|
||||
|
||||
Do not read the code yourself. Let the sub-agent do that.
|
||||
|
||||
Report the sub-agent's findings.
|
||||
```
|
||||
|
||||
And here's how I use this to review a pull request on GitHub:
|
||||
|
||||
<video src="https://mariozechner.at/posts/2025-11-30-pi-coding-agent/media/subagent.mp4" controls=""></video>
|
||||
|
||||
With a simple prompt, I can select what specific thing I want to review and what model to use. I could even set thinking levels if I wanted to. I can also save out the full review session to a file and hop into that in another pi session if I wanted. Or I can say this is an ephemeral session and it shouldn't be saved to disk. All of that gets translated into a prompt that the main agent reads and based on which it executes itself again via bash. And while I don't get full observability into the inner workings of the sub-agent, I get full observability on its output. Something other harnesses don't really provide, which makes no sense to me.
|
||||
|
||||
Of course, this is a bit of a simulated use case. In reality, I would just spawn a new pi session and ask it to review the pull request, possibly pull it into a branch locally. After I see its initial review, I give my own review and then we work on it together until it's good. That's the workflow I use to not merge garbage code.
|
||||
|
||||
Spawning multiple sub-agents to implement various features in parallel is an anti-pattern in my book and doesn't work, unless you don't care if your codebase devolves into a pile of garbage.
|
||||
|
||||
## Benchmarks
|
||||
|
||||
I make a lot of grandiose claims, but do I have numerical proof that all the contrarian things I say above actually work? I have my lived experience, but that's hard to transport in a blog post and you'd just have to believe me. So I created a [Terminal-Bench 2.0](https://github.com/laude-institute/terminal-bench) test run for pi with Claude Opus 4.5 and let it compete against Codex, Cursor, Windsurf, and other coding harnesses with their respective native models. Obviously, we all know benchmarks aren't representative of real-world performance, but it's the best I can provide you as a sort of proof that not everything I say is complete bullshit.
|
||||
|
||||
I performed a complete run with five trials per task, which makes the results eligible for submission to the leaderboard. I also started a second run that only runs during CET because I found that error rates (and consequently benchmark results) get worse once PST goes online. Here are the results for the first run:
|
||||
|
||||
|
||||
|
||||
And here's pi's placement on the current leaderboard as of December 2nd, 2025:
|
||||
|
||||
|
||||
|
||||
And here's the [results.json](https://gist.github.com/badlogic/f45e8f6e481e5ab7d3a50659da84edaa) file I've submitted to the Terminal-Bench folks for inclusion in the leaderboard. The bench runner for pi can be found in [this repository](https://github.com/badlogic/pi-terminal-bench) if you want to reproduce the results. I suggest you use your Claude plan instead of pay-as-you-go.
|
||||
|
||||
Finally, here's a little glimpse into the CET-only run:
|
||||
|
||||
|
||||
|
||||
This is going to take another day or so to complete. I will update this blog post once that is done.
|
||||
|
||||
Also note the ranking of [Terminus 2](https://github.com/laude-institute/terminal-bench/tree/main/terminal_bench/agents/terminus_2) on the leaderboard. Terminus 2 is the Terminal-Bench team's own minimal agent that just gives the model a tmux session. The model sends commands as text to tmux and parses the terminal output itself. No fancy tools, no file operations, just raw terminal interaction. And it's holding its own against agents with far more sophisticated tooling and works with a diverse set of models. More evidence that a minimal approach can do just as well.
|
||||
|
||||
## In summary
|
||||
|
||||
Benchmark results are hilarious, but the real proof is in the pudding. And my pudding is my day-to-day work, where pi has been performing admirably. Twitter is full of context engineering posts and blogs, but I feel like none of the harnesses we currently have actually let you do context engineering. pi is my attempt to build myself a tool where I'm in control as much as possible.
|
||||
|
||||
I'm pretty happy with where pi is. There are a few more features I'd like to add, like [compaction](https://github.com/badlogic/pi-mono/issues/92) or [tool result streaming](https://github.com/badlogic/pi-mono/issues/44), but I don't think there's much more I'll personally need. Missing compaction hasn't been a problem for me personally. For some reason, I'm able to cram [hundreds of exchanges](https://mariozechner.at/posts/2025-11-30-pi-coding-agent/media/long-session.html) between me and the agent into a single session, which I couldn't do with Claude Code without compaction.
|
||||
|
||||
That said, I welcome contributions. But as with all my open source projects, I tend to be dictatorial. A lesson I've learned the hard way over the years with my bigger projects. If I close an issue or PR you've sent in, I hope there are no hard feelings. I will also do my best to give you reasons why. I just want to keep this focused and maintainable. If pi doesn't fit your needs, I implore you to fork it. I truly mean it. And if you create something that even better fits my needs, I'll happily join your efforts.
|
||||
|
||||
I think some of the learnings above transfer to other harnesses as well. Let me know how that goes for you.
|
||||
@@ -0,0 +1,119 @@
|
||||
---
|
||||
source_url: "https://prtimes.jp/main/html/rd/p/000001248.000031579.html"
|
||||
ingested: 2026-06-30
|
||||
sha256: 5931081fa2e0fb0b294a80851c6bbb3df7e43b302c5d1620997c8fa44ed5aaaf
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521460814140280933"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T10:22:05.466000000Z"
|
||||
message_excerpt: "ポプラ社と日本郵便が郵便局窓口で本を試行販売する話には、書店のない地域で本を買える場所を増やす実務的な期待が乗っていた."
|
||||
---
|
||||
|
||||
[
|
||||
|
||||
株式会社ポプラ社
|
||||
|
||||
](https://prtimes.jp/main/html/searchrlp/company_id/31579)
|
||||
|
||||
2026年6月30日 15時00分
|
||||
|
||||
株式会社ポプラ社(東京都品川区、代表取締役社長 加藤 裕樹/以下「ポプラ社」)と日本郵便株式会社(東京都千代田区、代表取締役社長 小池 信也/以下「日本郵便」)は、2026年7月22日(水)から、一部の郵便局窓口において児童書などを試行販売します。
|
||||
|
||||
|
||||
|
||||
## ■概要
|
||||
|
||||
ポプラ社と日本郵便は、より多くの子どもたちへ、新しい世界との出会いや感動を児童書の作品を通じて体験し、成長の糧にしてほしいと願っています。
|
||||
|
||||
しかし全国の書店数が減少し、書店が1軒もない「書店ゼロ地域」(注1)が存在するなど、書籍との接点が少なくなっている現状があります。こうした背景を踏まえて、児童書を中心に幅広いジャンルの書籍を出版しているポプラ社と、全国津々浦々に郵便局ネットワークを有する日本郵便が協力し、書店が減少している地域の郵便局窓口において書籍を試行販売します。
|
||||
|
||||
今回の試行販売の結果を踏まえ、他地域への拡大も検討いたします。
|
||||
|
||||
ポプラ社と日本郵便は、今後も、子どもたちの健やかな成長と地域の活性化に貢献してまいります。
|
||||
|
||||
## ■試行販売期間および試行販売を行う郵便局
|
||||
|
||||
**〇試行販売期間**
|
||||
|
||||
2026年7月22日(水)~2027年3月31日(水)
|
||||
|
||||
**〇試行販売を行う郵便局**
|
||||
|
||||

|
||||
|
||||
<table><colgroup><col> <col></colgroup><tbody><tr><td colspan="1" rowspan="1"><p>新地郵便局</p></td><td colspan="1" rowspan="1"><p>〒979-2799 福島県相馬郡新地町谷地小屋新地117-1</p><p><a href="https://map.japanpost.jp/p/search/dtl/300182065000/">https://map.japanpost.jp/p/search/dtl/300182065000/</a></p></td></tr><tr><td colspan="1" rowspan="1"><p>鹿島郵便局</p></td><td colspan="1" rowspan="1"><p>〒979-2399 福島県南相馬市鹿島区西町1-30</p><p><a href="https://map.japanpost.jp/p/search/dtl/300182063000/">https://map.japanpost.jp/p/search/dtl/300182063000/</a></p></td></tr><tr><td colspan="1" rowspan="1"><p>小高郵便局</p></td><td colspan="1" rowspan="1"><p>〒979-2199 福島県南相馬市小高区上町1-38</p><p><a href="https://map.japanpost.jp/p/search/dtl/300182027000/">https://map.japanpost.jp/p/search/dtl/300182027000/</a></p></td></tr><tr><td colspan="1" rowspan="1"><p>浪江郵便局</p></td><td colspan="1" rowspan="1"><p>〒979-1599 福島県双葉郡浪江町権現堂南深町41-1</p><p><a href="https://map.japanpost.jp/p/search/dtl/300182079000/">https://map.japanpost.jp/p/search/dtl/300182079000/</a></p></td></tr></tbody></table>
|
||||
|
||||
※ 窓口ロビーに専用什器(注2)を設置しますので、通常の書店同様、試し読みしていただけます。
|
||||
|
||||
※ 販売数に限りがあるため、売り切れとなる場合があります。あらかじめご了承ください
|
||||
|
||||
## ■株式会社ポプラ社について
|
||||
|
||||
1947年設立の児童図書を中心とした出版社。「かいけつゾロリ」シリーズ、「ズッコケ三人組」
|
||||
|
||||
シリーズ、「ねずみくんの絵本」シリーズ、「めがねうさぎ」シリーズなどベストセラー多数。
|
||||
|
||||
「ねずみくんの絵本」シリーズは2026年4月よりNHK Eテレでアニメ放送中。
|
||||
|
||||
URL: [https://www.poplar.co.jp/](https://www.poplar.co.jp/)
|
||||
|
||||
---
|
||||
|
||||
### (注1)全国の無書店市町村の状況(2026年3月末時点)
|
||||
|
||||
|
||||
|
||||
(出典:出版文化産業振興財団)
|
||||
|
||||
### 注2)什器の陳列イメージ
|
||||
|
||||
|
||||
|
||||
※陳列する書籍は実際のものとは異なる場合があります
|
||||
|
||||
**〈お客様のお問い合わせ先〉**
|
||||
|
||||
**日本郵便株式会社 お客様サービス相談センター**
|
||||
|
||||
0120-23-28-86(フリーダイヤル)
|
||||
|
||||
0570-046-666(有料/携帯電話からの場合はこちら)
|
||||
|
||||
※ガイダンスが流れますので、「*」のあとに「4」を選択
|
||||
|
||||
<受付時間 平日 9:00~19:00、土・日・休日 9:00~17:00>
|
||||
|
||||
**株式会社ポプラ社 社長室 広報担当**
|
||||
|
||||
03-5877-8165
|
||||
|
||||
このプレスリリースには、 メディア関係者向けの情報があります
|
||||
|
||||
[メディアユーザーログイン](https://prtimes.jp/main/action.php?run=html&page=medialogin&company_id=31579&release_id=1248&message=releasemediaonly&uri=) 既に登録済みの方はこちら
|
||||
|
||||
[メディアユーザー新規登録](https://prtimes.jp/main/registmedia/form) 無料
|
||||
|
||||
メディアユーザー登録を行うと、企業担当者の連絡先や、 イベント・記者会見の情報など様々な特記情報を閲覧できます。 ※内容はプレスリリースにより異なります。
|
||||
|
||||
すべての画像
|
||||
|
||||
---
|
||||
|
||||
種類
|
||||
|
||||
[その他](https://prtimes.jp/main/html/searchrlp/release_type_id/07/)
|
||||
|
||||
ビジネスカテゴリ
|
||||
|
||||
[雑誌・本・出版物](https://prtimes.jp/main/html/searchbiscate/busi_cate_id/007/lv2/19/)
|
||||
|
||||
キーワード
|
||||
|
||||
ダウンロード
|
||||
|
||||
[プレスリリース素材](https://prtimes.jp/im/action.php?run=html&page=releaseimage&company_id=31579&release_id=1248)
|
||||
|
||||
このプレスリリース内で使われている画像ファイルがダウンロードできます
|
||||
@@ -0,0 +1,80 @@
|
||||
---
|
||||
source_url: https://docs.redhat.com/ja/documentation/red_hat_enterprise_linux/9/html/configuring_and_managing_virtualization/sharing-files-between-the-host-and-its-virtual-machines-using-virtio-fs_sharing-files-between-the-host-and-its-virtual-machines
|
||||
ingested: 2026-06-29
|
||||
sha256: a73f36816cdc611785eb66c3f51d414d4ee7a015acb485f2e0e039e88bd58719
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: "tw"
|
||||
message_id: '1521164340986777651'
|
||||
author_id: '890908900520505354'
|
||||
posted_at: 2026-06-29T14:44:00.758000000Z
|
||||
message_excerpt: "https://docs.redhat.com/ja/documentation/red_hat_enterprise_linux/9/html/configuring_and_managing_virtualization/sharing-files-between-the-host-and-its-virtual-machines-using-virtio-fs_sharing-files-between-the-host-and-"
|
||||
---
|
||||
|
||||
## 20.2. virtiofs を使用してホストと仮想マシン間でファイルを共有する
|
||||
|
||||
---
|
||||
|
||||
virtiofs を使用すると、ホストと仮想マシン (VM) の間で、ローカルファイルシステムの構造と同じように機能するディレクトリーツリーとしてファイルを共有できます。
|
||||
|
||||
### 20.2.1. virtiofs を使用してホストと仮想マシン間でファイルを共有する
|
||||
|
||||
RHEL 9 をハイパーバイザーとして使用する場合は、 `virtiofs` 機能を使用して、ホストシステムとその仮想マシン間でファイルを効率的に共有できます。
|
||||
|
||||
**前提条件**
|
||||
|
||||
- 仮想化は、RHEL 9 ホストで [インストールされ、有効](https://docs.redhat.com/ja/documentation/red_hat_enterprise_linux/9/html/configuring_and_managing_virtualization/assembly_enabling-virtualization-in-rhel-9_configuring-and-managing-virtualization "第2章 仮想化の有効化") になります。
|
||||
- 仮想マシンと共有するディレクトリーがある。既存のディレクトリーを共有しない場合は、 *shared-files* などの新しいディレクトリーを作成します。
|
||||
```plaintext
|
||||
# mkdir /root/shared-files
|
||||
```
|
||||
- データを共有する仮想マシンは、ゲストオペレーティングシステムとして Linux ディストリビューションを使用します。
|
||||
|
||||
**手順**
|
||||
|
||||
1. 仮想マシンと共有するホストの各ディレクトリーを、仮想マシンの XML 設定の virtiofs ファイルシステムとして設定します。
|
||||
1. 目的の仮想マシンの XML 設定を開きます。
|
||||
```plaintext
|
||||
# virsh edit vm-name
|
||||
```
|
||||
2. 仮想マシンの XML 設定の `<devices>` に、以下のようなエントリーを追加します。
|
||||
```plaintext
|
||||
<filesystem type='mount' accessmode='passthrough'>
|
||||
<driver type='virtiofs'/>
|
||||
<binary path='/usr/libexec/virtiofsd' xattr='on'/>
|
||||
<source dir='/root/shared-files'/>
|
||||
<target dir='host-file-share'/>
|
||||
</filesystem>
|
||||
```
|
||||
この例では、ホストの `/root/shared-files` ディレクトリーを、仮想マシンの `host-file-share` として表示するように設定します。
|
||||
2. 仮想マシンの共有メモリーを設定します。そのためには、共有メモリーバッキングを XML 設定の `<domain>` セクションに追加します。
|
||||
```plaintext
|
||||
<domain>
|
||||
[...]
|
||||
<memoryBacking>
|
||||
<access mode='shared'/>
|
||||
</memoryBacking>
|
||||
[...]
|
||||
</domain>
|
||||
```
|
||||
3. 仮想マシンを起動します。
|
||||
```plaintext
|
||||
# virsh start vm-name
|
||||
```
|
||||
4. ゲストオペレーティングシステムにファイルシステムをマウントします。以下の例では、Linux ゲストオペレーティングシステムで事前に設定した `host-file-share` ディレクトリーをマウントします。
|
||||
```plaintext
|
||||
# mount -t virtiofs host-file-share /mnt
|
||||
```
|
||||
|
||||
**検証**
|
||||
|
||||
- 共有ディレクトリーが仮想マシンからアクセス可能になり、ディレクトリーに保存されているファイルを開けるようになりました。
|
||||
|
||||
**既知の問題と制限**
|
||||
|
||||
- `noatime` 、 `strictatime` など、アクセス時間に関連するファイルシステムのマウントオプションは virtiofs では機能しない可能性が高く、Red Hat はその使用を推奨しません。
|
||||
|
||||
**トラブルシューティング**
|
||||
|
||||
- `virtiofs` がユースケースに最適でない場合、またはシステムでサポートされていない場合は、代わりに [NFS](https://docs.redhat.com/ja/documentation/red_hat_enterprise_linux/9/html/configuring_and_managing_virtualization/sharing-files-between-the-host-and-its-virtual-machines_configuring-and-managing-virtualization#sharing-files-between-the-host-and-its-virtual-machines-using-NFS_sharing-files-between-the-host-and-its-virtual-machines "20.1. NFS を使用してホストとその仮想マシン間でファイルを共有する") を使用できます。
|
||||
@@ -0,0 +1,58 @@
|
||||
---
|
||||
source_url: https://nesbitt.io/2026/06/25/scrutineer.html
|
||||
ingested: 2026-06-30
|
||||
sha256: 0e151bd9bd5fbb57711bccabdad6bc58fa73614fb332d28143d16e1c9b9342e7
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: 1477793137064935675
|
||||
channel_name: tw
|
||||
message_id: 1521415419896922153
|
||||
author_id: 1477793167486226708
|
||||
posted_at: 2026-06-30T07:21:42.635000000Z
|
||||
message_excerpt: Scrutineer: AI-assisted OSS vulnerability scan, verification, patch and disclosure workflow designed not to flood maintainers.
|
||||
---
|
||||
|
||||
[Scrutineer](https://github.com/alpha-omega-security/scrutineer) scans open source repositories for security vulnerabilities and then handles everything that follows: verifying each one, working out who to contact, drafting a fix, and tracking it through to a published advisory. I’ve been building it for [Alpha-Omega](https://alpha-omega.dev/) for the past couple of months.
|
||||
|
||||
Large language models have made finding vulnerabilities in open source code much easier. Point one at a codebase and it turns up real bugs alongside invented ones, faster and cheaper than the fuzzers and scanners that came before, but the bottleneck hasn’t moved with it. Every finding still has to be read, confirmed, and fixed by a maintainer, whose time and attention is a finite resource the whole ecosystem depends on. Trying to secure everything by firing machine-generated reports at maintainers would [burn out](https://opensourcepledge.com/blog/burnout-in-open-source-a-structural-problem-we-can-fix-together/) the people the effort relies on.
|
||||
|
||||
When I [pointed a couple of AI scanners at curl](https://nesbitt.io/2026/05/12/not-a-security-issue.html) back in May, most of the output collapsed against the project’s own disclosure policy, and the findings worth having were buried in the rest. Scrutineer is built so the volume a model can generate never lands directly on a maintainer.
|
||||
|
||||
You add a repo by URL, it runs a pipeline of [skills](https://agentskills.io/) against the code, and presents the results in a web UI for triage. It’s already in the hands of ecosystem security engineers and several of the teams Alpha-Omega funds, and between us a fair number of vulnerabilities have been found, reported, fixed, and shipped in a release with its help.
|
||||
|
||||
### How a scan runs
|
||||
|
||||
Every scan is a skill on disk: a `SKILL.md` file, a JSON schema for its output, and any scripts it needs. When you add a repo the `triage` skill runs first and enqueues the rest of the pipeline in parallel. What comes back is a set of structured findings, each carrying a severity, a CWE, a location linked back to the source line, the affected versions, and a six-step trace of how it was reached.
|
||||
|
||||
Because skills are just files in a directory, changing what runs is editing markdown rather than recompiling a scanner. The default set lives in `skills/`, the `triage` skill’s `SKILL.md` lists what to trigger, and dropping a new directory in adds a scan type with no code changes.
|
||||
|
||||
### The skills
|
||||
|
||||
Each skill is a directory in the [skills folder](https://github.com/alpha-omega-security/scrutineer/tree/main/skills) on GitHub. `triage` runs first and gathers the context the audit feeds on, and a supporting cast of static-analysis, dedup, and export skills fills in around the edges. The ones that shape how the tool works:
|
||||
|
||||
- [`security-deep-dive`](https://github.com/alpha-omega-security/scrutineer/blob/main/skills/security-deep-dive/SKILL.md) is the model-backed audit that produces the findings, and by a wide margin the skill that matters most; everything else either feeds it context or acts on what it returns. It runs in two phases. The first builds an inventory of every sink in the codebase, each place that executes code, shells out, or touches a path that could be hostile, without judging any of them yet. The second works through that inventory one entry at a time, tracing each sink back to a trust boundary and deciding whether hostile input can reach it. The inventory is part of the report rather than scratch work, so two runs against the same commit land on the same list. It audits the project’s own code, not its dependencies’ known CVEs: a finding counts only if the vulnerable logic lives in the repo.
|
||||
- [`threat-model`](https://github.com/alpha-omega-security/scrutineer/blob/main/skills/threat-model/SKILL.md) derives the project’s security contract before any auditing happens: what it assumes about its callers, the properties it guarantees under those assumptions, what it leaves to the integrator, and which code is out of scope. Every claim is tagged `documented`, with a file and line or a closed issue behind it, or `inferred`, reasoned from the code and flagged for a human to confirm. It lifts whatever `SECURITY.md` already says about scope verbatim, so the model is a superset of the project’s own stated position rather than a competing one. The deep-dive loads this instead of re-deriving boundaries on every run, which keeps it on the parts of the code the project claims to defend.
|
||||
- [`maintainers`](https://github.com/alpha-omega-security/scrutineer/blob/main/skills/maintainers/SKILL.md) works out who to contact about a disclosure and sorts the people it finds into active leads, regular maintainers, one-off contributors, and bots. It pulls commit history, issue and PR activity, and registry ownership from ecosyste.ms, and reads `SECURITY.md` and `CODEOWNERS` for a named security contact, rather than mailing whoever appears first in the git log. The output names a disclosure channel to go with the people: private vulnerability reporting where the repo has it enabled, a published contact where there is one.
|
||||
- [`patch`](https://github.com/alpha-omega-security/scrutineer/blob/main/skills/patch/SKILL.md) proposes a fix for a confirmed finding as a unified diff against the scanned ref. It is held to a minimal change in place at the sink, matching the existing code style and reusing whatever sanitiser or validator the project already has, with a regression test when the suite makes one practical. If it cannot tell where the dangerous path diverges from legitimate use, it refuses rather than guess. A diff that parses, targets files that exist, and passes `git apply --check` is stored on the finding as its suggested fix and downloadable as a `.patch`; nothing is pushed, so the analyst reviews and opens the PR by hand.
|
||||
- [`breaking-change`](https://github.com/alpha-omega-security/scrutineer/blob/main/skills/breaking-change/SKILL.md) reads that proposed fix and works out whether shipping it would break the library’s top dependents. It classifies what the diff changes in the public API surface, a pure addition, a tightened input contract, a changed signature, or a same-shape change in behaviour, then checks the most-depended-on packages for whether they plausibly call the affected symbols. It is static analysis on the diff and the dependent metadata, never running anyone’s code, and it returns `unknown` rather than a confident wrong call when a package name is all it has to reason from. That verdict is often the difference between a fix that ships and one that sits.
|
||||
- [`release-watch`](https://github.com/alpha-omega-security/scrutineer/blob/main/skills/release-watch/SKILL.md) handles the part that is easy to lose track of once a patch lands. A finding reaches `fixed` when a commit merges upstream, but consumers cannot pin to a commit, they need a tagged release. So once a finding is fixed the skill polls the upstream’s releases, maps each tag back to its commit, and checks whether the fix is reachable from it. When a release carrying the fix appears it records the tag, URL, and timestamp on the finding; until then it reports the latest release and checks again on the next run.
|
||||
|
||||
There are more than thirty skills bundled by default, and the list keeps growing as we hit cases the existing ones don’t cover.
|
||||
|
||||
### The data underneath
|
||||
|
||||
A lot of what scrutineer has on a project before any code is read comes from [ecosyste.ms](https://ecosyste.ms/). The `metadata`, `packages`, `advisories`, and `dependents` skills all query its APIs: repo metadata, every published package and its download and dependent counts, known advisories already filed, and the projects downstream that a vulnerability would affect. The maintainer analysis leans on registry ownership data from the same place. The dependency side is read locally rather than fetched: the `dependencies` and `sbom` skills run [git-pkgs](https://github.com/git-pkgs/git-pkgs) over the checkout to index every manifest in the tree and emit a CycloneDX SBOM, so the dependency graph reflects what the repo declares. A finding then arrives with context attached, how widely the package is used and who depends on it, instead of a bare line number.
|
||||
|
||||
The instinct running through these skills is to rule a finding out rather than to collect it. The deep-dive keeps a sink only when it can trace hostile input to it. `breaking-change` and `patch` return `unknown` or refuse outright rather than commit to a wrong call, and `threat-model` writes down the project’s documented non-issues so they are never raised as bugs in the first place. Putting the burden of proof on the finding keeps most of the noise a model generates inside the tool rather than in someone’s inbox. And a project that documents in its `SECURITY.md` or threat model what it does not count as a vulnerability gives any scanner, not just this one, grounds to [drop those reports at source](https://nesbitt.io/2026/05/12/not-a-security-issue.html).
|
||||
|
||||
The reason scrutineer has a whole workflow rather than a report button is that a raw model finding is not something to send anyone. Every finding starts at **new** and moves through verification, triage, disclosure draft, and reporting, with a human gate at each step. High and critical findings auto-enqueue a cheap read-only classifier first that sorts them into true positive, false positive, already-fixed, or uncertain before any expensive work happens. A true positive on a serious finding then chains into an independent verification pass. Nothing reaches a maintainer until a person has looked at it, and when it does it arrives through GitHub’s private vulnerability reporting as a verified bug with a proposed patch attached, rather than another plausible-sounding maybe for them to disprove on a weekend.
|
||||
|
||||
### Findings in and out
|
||||
|
||||
Findings don’t have to originate in scrutineer to go through its workflow. POST another scanner’s output or a pentest report at it, SARIF, CSV, markdown, or a minimal JSON shape, and each one lands in the same triage and disclosure flow as a native finding, deduplicated by content fingerprint against what’s already there. An uploaded CycloneDX or SPDX SBOM resolves each component to a source repository and queues it for scanning. What leaves is in shapes a coordinator or a registry will take: a finding exports as an OSV record or a CSAF 2.0 advisory, and a disclosure bundle packs the OSV, the CSAF, the markdown report, and the patch into one tarball for when GitHub’s private reporting isn’t the route.
|
||||
|
||||
### Try it across your ecosystem
|
||||
|
||||
Scrutineer is MIT licensed and the code is on [GitHub](https://github.com/alpha-omega-security/scrutineer). It runs locally, scans run in an ephemeral Docker container by default with a read-only source mount and an egress allowlist, and you point it at Claude with either a Claude Code subscription token or an Anthropic API key.
|
||||
|
||||
What I’d most like now is for people to run it against repositories in ecosystems I’m not living in. The pipeline leans on ecosyste.ms and the major registries, so it already reaches across npm, PyPI, RubyGems, crates.io, Go, Packagist, Hex, and NuGet, but the skills were shaped by the projects we happened to scan first. If you work in an ecosystem with its own conventions and the default skills come up short, the fix is usually a new skill file, about as small a contribution as open source asks for, and the issue tracker is the place to tell me what broke.
|
||||
@@ -0,0 +1,56 @@
|
||||
---
|
||||
source_url: https://www.ses.com/network-and-technology/meo/meosphere
|
||||
ingested: 2026-06-30
|
||||
sha256: 14f909fa2035f79f05b135c52b02fa19a806818690a218c208b5d415110d1d05
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521340022077395035'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T02:22:06.394000000Z
|
||||
original_url: https://t.co/KKs7wr0Lpv
|
||||
original_context_url: https://x.com/mnishi41/status/2071776026427060618
|
||||
message_excerpt: MEOでのB2B衛星ネットワークの話
|
||||
---
|
||||
|
||||
|
||||
## meoSphere
|
||||
|
||||
meoSphere: SES’s Next-Generation Multi-Mission MEO Network
|
||||
|
||||
> meoSphere is being designed as a multi-mission network that adapts to customer needs, from real-time aircraft connectivity and dependable maritime communications, to high-resilience backhaul for remote enterprises, meoSphere will introduce new possibilities with custom hosted payloads, optical space-to-space data relay, space situational awareness, and multi-layered sovereign networking.
|
||||
>
|
||||
> **Carmel Ortiz** SVP of MEO Programs
|
||||
|
||||
Supports broadband connectivity on a standalone basis or as part of a multi-orbit managed solution.
|
||||
|
||||
Opens new markets through hosted payloads, optical free-space communications and sovereign networking capabilities.
|
||||
|
||||
Offers low latency and reliable, resilient, secure connectivity globally including on both poles.
|
||||
|
||||
5G-NTN based core system allows meoSphere connectivity to be added as a seamless extension of terrestrial networks and as part of a 5G-NTN mult-orbit solution.
|
||||
|
||||
Matched with a new portfolio of next generation electronically steerable antennas, meoSphere services are designed to support ultra-high bandwidth performance for target use cases.
|
||||
|
||||
Satellites communicate directly with one another to enable data to be relayed in space enhanced resiliency, reliability, and security for Sovereign Networking and other high availability, high security use cases.
|
||||
|
||||
Support for high-speed real-time or near real-time data relay between missions in space and ground stations for applications like Earth observation, Space Situational Awareness, space-based data centers, space stations and to complement Direct to Device LEO constellations.
|
||||
|
||||
Leveraging the larger spacecraft design of meoSphere satellites, mission-specific payloads can be hosted on one or more satellites for government and commercial customers.
|
||||
|
||||
Payloads to be hosted can include applications such as earth observation, space situational awareness, GPS alternative or augmentation and satellite UHF.
|
||||
|
||||
Future satellites will be able to process and store data in space.
|
||||
|
||||
Enables AI-driven analytics, faster insights, and reduced dependency on ground infrastructure.
|
||||
|
||||
Built in partnership with leading “new space” innovators with development of key elements managed by SES
|
||||
|
||||
Accelerates development and helps manage costs and delivery schedules while expanding SES’s technology and mission portfolio.
|
||||
|
||||
|
||||
|
||||
### Built for a New Era of Space Solutions
|
||||
|
||||
Together, these capabilities position meoSphere to deliver scalable, managed services for a wide variety of use cases both high-quality connectivity and beyond - delivering new opportunities for customers in the evolving social and geo-political environment on earth as well as a rapidly evolving space economy.
|
||||
@@ -0,0 +1,80 @@
|
||||
---
|
||||
source_url: "https://advisory.splunk.com/advisories/SVD-2026-0601"
|
||||
ingested: 2026-06-30
|
||||
sha256: fe3466546821450702237ad1014a0bb6bbba2647fcba18d6004aba84d0fc17aa
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521475788287774723"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T11:21:35.581000000Z"
|
||||
message_excerpt: "#tw digest mentioned Splunk Secure Gateway RCE as part of security-operations context."
|
||||
score: 2
|
||||
---
|
||||
**Advisory ID:** SVD-2026-0601
|
||||
|
||||
**CVE ID:** [CVE-2026-20251](https://www.cve.org/CVERecord?id=CVE-2026-20251)
|
||||
|
||||
**Published:** 2026-06-10
|
||||
|
||||
**Last Update:** 2026-06-10
|
||||
|
||||
**CVSSv3.1 Score:** 8.8, High
|
||||
|
||||
**CVSSv3.1 Vector:** [CVSS:3.1/AV:N/AC:L/PR:L/UI:N/S:U/C:H/I:H/A:H](https://www.first.org/cvss/calculator/3.1#CVSS:3.1/AV:N/AC:L/PR:L/UI:N/S:U/C:H/I:H/A:H)
|
||||
|
||||
**CWE:** [CWE-502](https://cwe.mitre.org/data/definitions/502.html)
|
||||
|
||||
**Bug ID:** VULN-69217
|
||||
|
||||
## Description
|
||||
|
||||
In Splunk Enterprise versions below 10.2.4, 10.0.7, 9.4.12, and 9.3.13, Splunk Cloud Platform versions below 10.3.2512.12, 10.2.2510.14, 10.1.2507.22, and 9.3.2411.132, and Splunk Secure Gateway versions below 3.10.6, 3.9.20, and 3.8.67, a low-privileged user that does not hold the ‘admin’ or ‘power’ Splunk roles could perform a Remote Code Execution (RCE) through the Splunk Secure Gateway app.
|
||||
|
||||
The Remote Code Execution is possible because of unsafe deserialization of App Key Value Store (KV Store) data through the ‘jsonpickle’ Python library, which reconstructs arbitrary Python objects from specially crafted JavaScript Object Notation (JSON) without adequate validation.
|
||||
|
||||
See [App Key Value Store](https://help.splunk.com/en/splunk-enterprise/administer/admin-manual/10.2/administer-the-app-key-value-store/about-the-app-key-value-store) and [About role-based user access](https://help.splunk.com/en/splunk-enterprise/administer/manage-users-and-security/10.2/manage-splunk-platform-users-and-roles/about-configuring-role-based-user-access) in the Splunk documentation for more information.
|
||||
|
||||
## Solution
|
||||
|
||||
Upgrade Splunk Enterprise to versions 10.4.0, 10.2.4, 10.0.7, 9.4.12, and 9.3.13, or higher.
|
||||
|
||||
Splunk is actively monitoring and patching Splunk Cloud Platform instances.
|
||||
|
||||
## Product Status
|
||||
|
||||
| Product | Base Version | Component | Affected Version | Fix Version |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| Splunk Enterprise | 10.4 | Splunk Secure Gateway | Not affected | N/A |
|
||||
| Splunk Enterprise | 10.2 | Splunk Secure Gateway | 10.2.0 to 10.2.3 | 10.2.4 |
|
||||
| Splunk Enterprise | 10.0 | Splunk Secure Gateway | 10.0.0 to 10.0.6 | 10.0.7 |
|
||||
| Splunk Enterprise | 9.4 | Splunk Secure Gateway | 9.4.0 to 9.4.11 | 9.4.12 |
|
||||
| Splunk Enterprise | 9.3 | Splunk Secure Gateway | 9.3.0 to 9.3.12 | 9.3.13 |
|
||||
| Splunk Cloud Platform | 10.3.2512 | Splunk Secure Gateway | Below 10.3.2512.12 | 10.3.2512.12 |
|
||||
| Splunk Cloud Platform | 10.2.2510 | Splunk Secure Gateway | Below 10.2.2510.14 | 10.2.2510.14 |
|
||||
| Splunk Cloud Platform | 10.1.2507 | Splunk Secure Gateway | Below 10.1.2507.22 | 10.1.2507.22 |
|
||||
| Splunk Cloud Platform | 9.3.2411 | Splunk Secure Gateway | Below 9.3.2411.132 | 9.3.2411.132 |
|
||||
| Splunk Secure Gateway | 3.10 | | Below 3.10.6 | 3.10.6 |
|
||||
| Splunk Secure Gateway | 3.9 | | Below 3.9.20 | 3.9.20 |
|
||||
| Splunk Secure Gateway | 3.8 | | Below 3.8.67 | 3.8.67 |
|
||||
|
||||
## Mitigations and Workarounds
|
||||
|
||||
Turn off or remove the Splunk Secure Gateway app. See [Manage app and add-on objects](https://help.splunk.com/en/splunk-enterprise/administer/admin-manual/10.2/meet-splunk-apps/manage-app-and-add-on-objects) in the Splunk documentation.
|
||||
|
||||
Note: Splunk Mobile, Spacebridge, and Mission Control rely on functionality in the Splunk Secure Gateway app. If you do not use any of these apps, features, or functionality, as a potential mitigation, you may turn off or remove the app.
|
||||
|
||||
## Detections
|
||||
|
||||
None
|
||||
|
||||
## Severity
|
||||
|
||||
Splunk rates this vulnerability an 8.8, High, with a CVSSv3.1 vector of CVSS:3.1/AV:N/AC:L/PR:L/UI:N/S:U/C:H/I:H/A:H.
|
||||
|
||||
If you remove or turn off the Splunk Secure Gateway app, there should be no impact and the severity would be Informational.
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
M Mahdan Argya Syarif (0xbeludan)
|
||||
@@ -0,0 +1,91 @@
|
||||
---
|
||||
source_url: "https://gigazine.net/news/20240630-state-of-terminal/"
|
||||
ingested: 2026-06-30
|
||||
sha256: 36c0408795b518ec031b94e1a4945422f7460ec8d439f35b1102b2a27fa1668c
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521460815574863942"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T10:22:05.808000000Z"
|
||||
message_excerpt: "ターミナルがなぜ黒背景に白字になったかという記事は、いまの開発環境の見慣れたUIがどこから来たのかを辿る軽めの技術文化史です."
|
||||
---
|
||||
|
||||
2024年06月30日 13時00分 [ソフトウェア](https://gigazine.net/news/C4/)
|
||||
|
||||
[](https://i.gzn.jp/img/2024/06/30/state-of-terminal/00.jpg)
|
||||
|
||||
|
||||
PCを用いたアプリケーション開発やファイルの操作などを行う際、ユーザーがテキストベースでコマンドを入力して、コンピューターのシステムやアプリケーションを制御するためのホストアプリケーション「 **[ターミナル](https://learn.microsoft.com/ja-jp/windows/terminal/)** 」が用いられることがあります。このターミナルについて、ソフトウェアエンジニアの **[グレゴリー・アンダース](https://gpanders.com/)** 氏がその歴史などについて解説しています。
|
||||
|
||||
**State of the Terminal | g.p. anders**
|
||||
**[https://gpanders.com/blog/state-of-the-terminal/](https://gpanders.com/blog/state-of-the-terminal/)**
|
||||
|
||||
[](https://gpanders.com/blog/state-of-the-terminal/)
|
||||
|
||||
|
||||
現代まで続くターミナルは、 **[Digital Equipment Corporation](https://ja.wikipedia.org/wiki/%E3%83%87%E3%82%A3%E3%82%B8%E3%82%BF%E3%83%AB%E3%83%BB%E3%82%A4%E3%82%AF%E3%82%A4%E3%83%83%E3%83%97%E3%83%A1%E3%83%B3%E3%83%88%E3%83%BB%E3%82%B3%E3%83%BC%E3%83%9D%E3%83%AC%E3%83%BC%E3%82%B7%E3%83%A7%E3%83%B3)** が1978年に発売したビデオ表示端末の **[VT100](https://ja.wikipedia.org/wiki/VT100)** にそのルーツをたどることができます。
|
||||
|
||||
[](https://www.flickr.com/photos/stiefkind/30280228885/)
|
||||
|
||||
by [Wolfgang Stief](https://www.flickr.com/photos/stiefkind/)
|
||||
|
||||
ビデオ表示端末とは、それ以前の **[テレタイプ端末](https://ja.wikipedia.org/wiki/%E3%83%86%E3%83%AC%E3%82%BF%E3%82%A4%E3%83%97%E7%AB%AF%E6%9C%AB)** を改良したものです。テレタイプ端末はキーボードで入力した内容や受信したメッセージを紙に出力するものでしたが、ビデオ表示端末は紙を使うことなく、インタラクティブなインターフェイスを備え、ディスプレイ上に情報を表示することができました。
|
||||
|
||||
VT100の登場まで、ビデオ表示端末は各デバイスごとに独自の **[エスケープシーケンス](https://ja.wikipedia.org/wiki/%E3%82%A8%E3%82%B9%E3%82%B1%E3%83%BC%E3%83%97%E3%82%B7%E3%83%BC%E3%82%B1%E3%83%B3%E3%82%B9)** を使用していました。そのため、当時のアプリケーションにはどのシーケンスを使うべきかを考えるプロセスが必要となり、さらなる発展の妨げとなっていました。
|
||||
|
||||
そこで、このような問題を解決するために、 **[Termcap](https://ja.wikipedia.org/wiki/Termcap)** などの **[ヘルパープログラム](https://atmarkit.itmedia.co.jp/icd/root/97/5798697.html)** などが開発されました。現代でも、Termcapの改良版である **[ライブラリ](https://ja.wikipedia.org/wiki/%E3%83%A9%E3%82%A4%E3%83%96%E3%83%A9%E3%83%AA)** である **[Terminfo](https://ja.wikipedia.org/wiki/Terminfo)** が使用されています。
|
||||
|
||||
その後、ECMA-48やANSI X3.64のようなエスケープシーケンスの規格が整備され、VT100はこれらのエスケープシーケンス規格をサポートした最初のビデオ表示端末となりました。VT100は標準エスケープシーケンス規格をサポートすることで、確実なプログラムの起動が可能になりました。その結果VT100は高い人気を集め、多くのクローンが生み出されたそうです。
|
||||
|
||||
[](https://www.flickr.com/photos/stiefkind/15272092560/)
|
||||
|
||||
by [Wolfgang Stief](https://www.flickr.com/photos/stiefkind/)
|
||||
|
||||
VT100のターミナルをベースとして、1984年にはマサチューセッツ工科大学でX Window Systemの標準的なターミナルソフトである **[xterm](https://ja.wikipedia.org/wiki/Xterm)** が開発されました。xtermは従来のビデオ表示端末にはなかったマウストラッキングや設定可能なカラーパレットなどの機能を備えており、複数のクローンがこれらの機能をコピーすることになりました。こうしてxtermはターミナルソフトにおける新しいデファクトスタンダードに成長したとのこと。
|
||||
|
||||
現代のターミナルベースのアプリケーションでは、ユーザーは自身が確認できるテキストと、ターミナルの状態を変更する制御コードという2種類のデータをターミナルに書き込むことになります。制御コードには、カーソルを現在の行の先頭に移動する「/r」や、カーソルを次の行に移動する「/n」などの **[C0制御コード](https://en.wikipedia.org/wiki/C0_and_C1_control_codes)** などが用いられます。
|
||||
|
||||
これらのターミナルは、シェルから直接コードを実行することができるなど、基本的には非常に使いやすく設計されています。しかし、現代のターミナルエミュレーターのシステムを支えるのは、xtermのような古いテクノロジーであるため、「CtrlやAltなどの修飾キーの扱い方」などの問題が生じてきました。
|
||||
|
||||
[](https://i.gzn.jp/img/2024/06/30/state-of-terminal/04.jpg)
|
||||
|
||||
|
||||
それでも、度重なるアップデートや開発によってこれらの問題は解決に向かいつつあります。アンダース氏は「ターミナルの基盤となるテクノロジーは、現代のテクノロジーの基準からすると非常に古いものとなっています。しかし、これは欠点ではなく強みです。ターミナルソフトは登場したり消えたりしていきますが、ターミナルの基盤となるプラットフォームが消えることはありません」と述べています。
|
||||
|
||||
**・関連記事**
|
||||
**[ターミナルの文字列出力にかっこいいエフェクトを追加できるライブラリ「TerminalTextEffects」 - GIGAZINE](https://gigazine.net/news/20240529-terminal-text-effects)**
|
||||
|
||||
**[1930年製のタイプライターをLinuxのターミナル画面にしてアスキーアートまで打ち込ませてしまうムービー - GIGAZINE](https://gigazine.net/news/20200418-typewriter-1930-linux-terminal)**
|
||||
|
||||
**[ターミナル上でサクッと遊べるテキストベースのシューティングゲーム「Terminal Phase」 - GIGAZINE](https://gigazine.net/news/20200125-terminal-phase)**
|
||||
|
||||
**[無料でターミナルからグラフィカルにウェブサイトを表示できるテキストベースブラウザ「Browsh」 - GIGAZINE](https://gigazine.net/news/20201119-browsh)**
|
||||
|
||||
**[1992年のハッカー映画「スニーカーズ」の有名なデータ復号エフェクトを再現するコマンドラインツール「No More Secrets」 - GIGAZINE](https://gigazine.net/news/20230730-no-more-secrets)**
|
||||
|
||||
**[ターミナルでYouTubeを見たりDOOMを動かしたりできるChromiumベースのブラウザ「Carbonyl」 - GIGAZINE](https://gigazine.net/news/20230130-carbonyl-chromium-running-inside-terminal)**
|
||||
|
||||
**・関連コンテンツ**
|
||||
|
||||
- [](https://gigazine.net/news/20250903-return-enter-key/)
|
||||
[ReturnキーやEnterキーの誕生経緯](https://gigazine.net/news/20250903-return-enter-key/)
|
||||
- [](https://gigazine.net/news/20201227-emoji-utf-8/)
|
||||
[絵文字の偉大な功績の1つは「文字コードを統一したこと」](https://gigazine.net/news/20201227-emoji-utf-8/)
|
||||
- [](https://gigazine.net/news/20200704-how-vim-become-popular/)
|
||||
[全能テキストエディタ「Vim」の歴史と開発者に広く普及した理由](https://gigazine.net/news/20200704-how-vim-become-popular/)
|
||||
- [](https://gigazine.net/news/20221108-fortran-programming-code/)
|
||||
[世界初の高水準言語「Fortran」が考案から約70年経ってもいまだに使用されている理由とは?](https://gigazine.net/news/20221108-fortran-programming-code/)
|
||||
- [](https://gigazine.net/news/20231224-ancient-computer-all-caps/)
|
||||
[古いコンピュータやOSで小文字ではなく大文字が使用されていた理由とは?](https://gigazine.net/news/20231224-ancient-computer-all-caps/)
|
||||
- [](https://gigazine.net/news/20200418-typewriter-1930-linux-terminal/)
|
||||
[1930年製のタイプライターをLinuxのターミナル画面にしてアスキーアートまで打ち込ませてしまうムービー](https://gigazine.net/news/20200418-typewriter-1930-linux-terminal/)
|
||||
- [](https://gigazine.net/news/20211113-amiga-at-nasa/)
|
||||
[NASAのスペースシャトル打ち上げを制御していたのは「Amiga」だった](https://gigazine.net/news/20211113-amiga-at-nasa/)
|
||||
- [](https://gigazine.net/news/20070606_windows_mobile_6_japanese/)
|
||||
[本日より提供開始された「Windows Mobile 6日本語版」の機能は?](https://gigazine.net/news/20070606_windows_mobile_6_japanese/)
|
||||
|
||||
2024年06月30日 13時00分00秒 in [ソフトウェア](https://gigazine.net/news/C4/), Posted by darkhorse\_log
|
||||
|
||||
You can read the machine translated English article **[What is the background behind the white …](https://gigazine.net/gsc_news/en/20240630-state-of-terminal)**.
|
||||
@@ -0,0 +1,74 @@
|
||||
---
|
||||
source_url: https://www.city.wakayama.wakayama.jp/_res/projects/default_project/_page_/001/066/652/1221-2.pdf
|
||||
ingested: 2026-06-30
|
||||
sha256: 79213511b7fbdd4507734b6aa3fb3fcac16e632eb18bccd7e8ca6407e49e5dd2
|
||||
discovered_from:
|
||||
platform: 'discord'
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: 'tw'
|
||||
message_id: '1521370066216816690'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: '2026-06-30T04:21:29.475000000Z'
|
||||
message_excerpt: '和歌山市の人工衛星+AI漏水調査。全管路約2,300kmを見ながら現地調査を約25%まで絞れた行政実装例として共有された。'
|
||||
score: 2
|
||||
---
|
||||
|
||||
# 衛星画像を活用した水道管の漏水調査について
|
||||
|
||||
記 者 発 表
|
||||
|
||||
令和 7 年 12 月 22 日
|
||||
|
||||
担 当 課
|
||||
|
||||
維持管理課
|
||||
|
||||
担 当 者
|
||||
|
||||
木下、川上
|
||||
|
||||
電
|
||||
|
||||
話
|
||||
|
||||
435-1131
|
||||
|
||||
内
|
||||
|
||||
線
|
||||
|
||||
3219
|
||||
3235
|
||||
|
||||
衛星画像を活用した水道管の漏水調査について
|
||||
本市では、漏水調査の効率化と漏水箇所の早期発見を図るため、令和 7 年 5 月 30 日
|
||||
から衛星画像を活用した漏水調査を実施しています。
|
||||
1
|
||||
|
||||
調査概要
|
||||
人工衛星から地表へマイクロ波を照射し、水道水特有の反射波をAI(人工知能)で
|
||||
解析することで、地中約 3 メートルまでの漏水の疑いのある箇所(POI)を半径 100m
|
||||
の範囲で抽出が可能となり、漏水調査の効率化が図れます。従来の漏水調査は、調査
|
||||
員が歩いて平成元年以前に敷設された管路(1,229km)を対象として調査を実施して
|
||||
きましたが、衛星画像を活用することで、市内全域の水道管(2,325km)を対象とし
|
||||
た調査を行っています。
|
||||
|
||||
2
|
||||
|
||||
進捗状況について
|
||||
令和 7 年 8 月に衛星画像解析を完了し、漏水の疑いのある箇所(POI)の特定を終え、
|
||||
10 月から現地調査を実施しています。11 月 30 日時点で 31 件の漏水を発見しており、
|
||||
早期の修繕につなげています。
|
||||
|
||||
漏水の疑いのある箇所(POI) 半径 100m
|
||||
POI 調査完了箇所
|
||||
漏水発見数
|
||||
|
||||
613 箇所
|
||||
134 箇所
|
||||
31 件
|
||||
|
||||
市内全域調査延長の約 25%
|
||||
調査済みの発見数約 23%
|
||||
|
||||
出典:東亜グラウト工業株式会社公式 HP
|
||||
@@ -0,0 +1,103 @@
|
||||
---
|
||||
source_url: https://www.waseda.jp/inst/research/news/84905
|
||||
ingested: 2026-06-30
|
||||
sha256: bebff3219d6847b2eade4dae965eff3d197994d617dfcbb62eb39f9bb67c873c
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521355036448391169'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T03:21:46.099000000Z
|
||||
message_excerpt: 'Cyborg insect oxygen diving suit for disaster and infrastructure inspection.'
|
||||
score: 2
|
||||
---
|
||||
|
||||
### 酸素供給スーツで3時間潜水するサイボーグ昆虫を実現
|
||||
|
||||
## 世界初、陸上昆虫で水中探査が可能に
|
||||
|
||||
## 酸素供給スーツで3時間潜水するサイボーグ昆虫を実現
|
||||
|
||||
### ~浸水した災害現場やインフラ内部での活用に期待~
|
||||
|
||||
#### 【ポイント】
|
||||
|
||||
- 早稲田大学と南洋理工大学シンガポールの研究グループは、サイボーグ昆虫が水中や低酸素環境で活動するための柔軟な「潜水スーツ」を開発しました。
|
||||
- このスーツは、酸素発生タンク、柔軟な防水シェル、酸素供給チューブから構成され、昆虫の呼吸口に酸素を直接届けます。
|
||||
- スーツを装着しない場合は水中で約2分後に活動を停止しましたが、装着時には最大3時間、水中で活動を続けられました。
|
||||
- 将来的には、浸水したがれき、排水管、トンネルなど、従来のロボットが入りにくい災害・インフラ点検現場での活用が期待されます。
|
||||
|
||||
南洋理工大学シンガポールの佐藤裕崇(さとう ひろたか)教授らの研究グループは、 [早稲田大学理工学術院](https://www.waseda.jp/fsci/) 創造理工学部の [梅津 信二郎](https://w-rdb.waseda.jp/html/100000725_ja.html) (うめず しんじろう)教授らと共同で、サイボーグ昆虫が水中や低酸素環境で活動するための柔軟な「潜水スーツ」を開発しました。
|
||||
大雨や洪水の後の災害現場では、がれきの隙間や排水路、半分水没した空間など、人や従来のロボットが入りにくい場所が多数生じます。研究グループは、サイボーグ昆虫が水中や低酸素環境でも活動できる柔軟な「潜水スーツ」を開発しました。このスーツは、酸素を発生させる小型タンク、昆虫の体を覆う柔らかい防水シェル、呼吸口へ酸素を届けるシリコーンチューブから構成されます。実験では、スーツを装着しない昆虫は水中で約2分後に活動を停止しましたが、装着時には最大3時間、水中で移動を続けることができました。本成果は、災害救助や浸水したインフラ点検に向けた、陸上・水中の両方で活動できるサイボーグ昆虫※1の実現につながるものです。
|
||||
本研究成果は、2026年6月29日に国際学術誌「Nature Communications」に掲載されました。
|
||||
|
||||
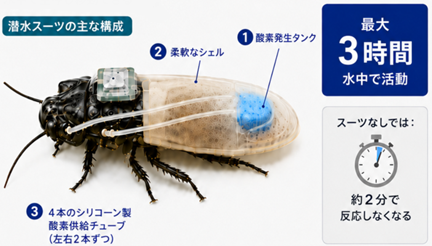
|
||||
|
||||
クレジット:シンガポール南洋理工大学(NTU Singapore)および早稲田大学。 図は Nature Communications に掲載された研究資料に基づき作成。
|
||||
|
||||
#### (1)これまでの研究で分かっていたこと
|
||||
|
||||
サイボーグ昆虫は、生きた昆虫に小型の電子制御装置を取り付け、昆虫自身の筋肉を利用して移動する小型のソフトロボット※2です。人工の小型ロボットでは、モーターなどの駆動装置に多くの電力が必要となるため、動作時間が限られます。一方、サイボーグ昆虫は昆虫本来の優れた運動能力を活用するため、少ない電力で長時間活動でき、狭く複雑な空間にも進入できます。
|
||||
そのため、災害現場での探索や、配管・トンネルなど人が入りにくい場所の点検への応用が期待され、同研究グループのサイボーグ昆虫は、2025年に発生したミャンマー大地震において、シンガポールのレスキュー隊による現地での捜索活動に活用されました。しかし、サイボーグ昆虫は基本的に陸上での活動を前提としていました。昆虫は体の側面にある気門※3から空気を取り込み、体内の気管を通じてガス交換を行います。そのため、水中に沈むと水から酸素を取り込むことができず、活動を継続することが困難でした。
|
||||
|
||||
#### (2) 今回の研究で明らかになったこと
|
||||
|
||||
本研究では、サイボーグ昆虫が水中や低酸素環境でも活動できるようにするため、昆虫が装着できる小型で柔軟な潜水スーツを開発しました。
|
||||
この潜水スーツは、主に3つの部品から構成されます。第1に、酸素を発生させる酸素発生タンクです。第2に、昆虫の体の一部を覆い、水の侵入を防ぐ柔軟なシェルです。第3に、発生した酸素を昆虫の呼吸口へ届ける4本のシリコーン製酸素供給チューブです。これらを組み合わせることで、水を遮断しながら、昆虫の呼吸に必要な酸素を直接供給する仕組みを実現しました。
|
||||
酸素発生タンクは、透明な樹脂材料を用いて3Dプリントで作製しました。タンク内部には、二酸化マンガン※4を分散させた多孔材を配置しています。ここに濃度調整した過酸化水素水※5を加えると、二酸化マンガンが触媒として働き、過酸化水素が分解されて酸素が発生します。発生した酸素は、柔軟なシェルとシリコーンチューブを通って、昆虫の胸部にある気門へ送られます。
|
||||
実験には、体が大きく、丈夫で、羽を持たないことからサイボーグ昆虫研究でよく用いられるマダガスカルオオゴキブリを使用しました。スーツを装着しない場合、ゴキブリは水中で約2分後に活動停止しました。一方、潜水スーツを装着した場合には、最大3時間、水中で活動を続けることができました。これにより、従来は陸上での移動が中心だったサイボーグ昆虫を、陸上と水中の両方で活動できる「水陸両用サイボーグ昆虫」へ展開しました。
|
||||
|
||||
|
||||
|
||||
クレジット:シンガポール南洋理工大学(NTU Singapore)および早稲田大学。 図は Nature Communications に掲載された研究資料に基づき作成。
|
||||
|
||||
#### (3)研究の波及効果や社会的影響
|
||||
|
||||
本成果は、災害救助やインフラ点検におけるサイボーグ昆虫の活動範囲を広げるものです。実際の災害現場では、大雨や洪水によって、がれきの中の通路、排水溝、地下空間、トンネルなどが浸水することがあります。このような場所では、人の立ち入りが危険であり、従来のロボットもサイズ、電力、防水性の制約から十分に移動できない場合があります。
|
||||
本研究で開発した潜水スーツにより、サイボーグ昆虫は陸上だけでなく、水たまりや浸水空間、低酸素や有毒ガスを含む環境でも活動できるようになりました。被災地での人命探索、浸水した配管・排水路・トンネルの点検、狭い空間の環境調査などへの応用が期待されます。
|
||||
また、本研究の考え方は、ゴキブリ以外の陸生昆虫にも応用できる可能性があります。多くの昆虫は、体表の気門から酸素を取り込み、体内の気管を通じて酸素を運ぶ共通した呼吸の仕組みを持っています。そのため、将来的には、他の種類のゴキブリ、バッタ、甲虫などへの展開も考えられます。
|
||||
|
||||
#### (4)課題、今後の展望
|
||||
|
||||
今後は、実際の災害現場に近い環境での検証が必要です。たとえば、がれき、泥、水流、狭い隙間、障害物がある環境で、サイボーグ昆虫が安定して移動できるかを確認する必要があります。また、長時間の使用に向けて、潜水スーツの耐久性、防水性、酸素供給の安定性をさらに高めることも重要です。
|
||||
さらに、実用化に向けては、センサーや無線通信、位置推定、ナビゲーション技術との統合が必要になります。将来的には、災害現場やインフラ点検現場で、サイボーグ昆虫が取得した情報を外部に送信し、人が入れない場所の状況把握に役立てることを目指します。
|
||||
|
||||
#### (5)研究者のコメント
|
||||
|
||||
本研究では、昆虫が本来持つ優れた移動能力を活かしながら、その活動領域を水中や低酸素環境へと拡張しました。小さく、軽く、柔らかい装着型システムによって、昆虫の自然な動きを妨げることなく酸素を供給できた点が重要です。サイボーグ昆虫はすでに災害現場での捜索活動に活用されていますが、本技術により、水没した空間や酸欠環境など、これまで到達が難しかった場所での活動も可能になると期待しています。将来的には、災害救助に加え、下水道や配管などのインフラ点検への応用も進めていきます。
|
||||
|
||||
#### (6)用語解説
|
||||
|
||||
※1 サイボーグ昆虫
|
||||
生きた昆虫に小型の電子装置やセンサーなどを取り付け、昆虫自身の筋肉を利用して移動させる技術です。小型ロボットに比べて少ない電力で移動できる利点があります。
|
||||
|
||||
※2 ソフトロボット
|
||||
柔らかい材料や構造を用いて、環境や生物の体に適応しやすいロボットや装置を作る研究分野です。
|
||||
|
||||
※3 気門昆虫の体表にある小さな呼吸口です。空気は気門から体内に入り、気管と呼ばれる管を通じて全身に送られます。
|
||||
|
||||
※4 二酸化マンガン
|
||||
過酸化水素の分解を促進する触媒として使われる物質です。本研究では、酸素発生タンク内で酸素を発生させるために用いられました。
|
||||
|
||||
※5 過酸化水素
|
||||
分解されると水と酸素を生じる化学物質です。本研究では、希釈した過酸化水素を用いて酸素を発生させました。
|
||||
|
||||
#### (7)論文情報
|
||||
|
||||
雑誌名:Nature Communications
|
||||
論文名:Underwater Suit-Wearing Cyborg Insect Capable of Hours-Long Diving and Terra-Aqua Travel
|
||||
執筆者名(所属機関名): Zifu FAN <sup>*1</sup>, Kazuki KAI <sup>*1</sup>, Kewei SONG <sup>*1</sup>, Duc Long LE <sup>*1</sup>, Thu Ha TRAN <sup>*1</sup>, Mingyu HAO <sup>*2</sup>, Wei Yang WAN <sup>*1</sup>, Shinjiro UMEZU <sup>*3</sup>, Hirotaka SATO <sup>*1<br></sup>\*1: School of Mechanical and Aerospace Engineering, Nanyang Technological University; Singapore 637460, Singapore.
|
||||
\*2: School of Electrical and Electronic Engineering, Nanyang Technological University; Singapore 639798, Singapore.
|
||||
\*3: School of Creative Science and Engineering, Waseda University; Tokyo 169-8555, Japan.
|
||||
掲載⽇時(⽇本時間): 2026年6月29日18時(日本時間)(online first)
|
||||
掲載URL: [https://doi.org/10.1038/s41467-026-74235-1](https://doi.org/10.1038/s41467-026-74235-1)
|
||||
DOI: 10.1038/s41467-026-74235-1
|
||||
|
||||
#### (8)キーワード
|
||||
|
||||
サイボーグ昆虫、潜水スーツ、水中移動、災害救助、探索ロボット、酸素供給、ソフトロボット
|
||||
|
||||
#### (9)研究助成(外部資金による助成を受けた研究実施の場合)
|
||||
|
||||
本研究および本論文の出版に関し、早稲田大学のスーパー・グローバル・ユニバーシティ事業およびシンガポール教育省(RG82/24)より支援を受けた。
|
||||
@@ -0,0 +1,98 @@
|
||||
---
|
||||
source_url: "https://gigazine.net/news/20220630-fake-russian-history-chinese-wikipedia/"
|
||||
ingested: 2026-06-30
|
||||
sha256: 9ec1a2677c22672074860782f2ad777cc045945c0eeb803427390357a0e07c04
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: "1477793137064935675"
|
||||
channel_name: "tw"
|
||||
message_id: "1521460815574863942"
|
||||
author_id: "1477793167486226708"
|
||||
posted_at: "2026-06-30T10:22:05.808000000Z"
|
||||
message_excerpt: "Wikipediaに「架空のロシアの歴史」が10年書き込まれていたという話は、情報の信頼性と創作衝動が奇妙に混ざるネット史ネタとして強いです."
|
||||
---
|
||||
|
||||
2022年06月30日 19時00分 [メモ](https://gigazine.net/news/C7/)
|
||||
|
||||
[](https://i.gzn.jp/img/2022/06/30/fake-russian-history-chinese-wikipedia/00.jpg)
|
||||
|
||||
|
||||
「調べ物をする際にはインターネット百科事典のWikipediaを見る」という人も多いはずですが、Wikipediaの記事作成・編集はボランティアによって支えられているため、時には誤解やデマが混入することがあります。2022年6月には、中国語版Wikipediaに数百万語に及ぶ「架空のロシアの歴史」が含まれており、これらの記事がたった1人の女性によって記されていたことが判明しました。
|
||||
|
||||
**She Spent a Decade Writing Fake Russian History. Wikipedia Just Noticed.**
|
||||
**[https://www.sixthtone.com/news/1010653/she-spent-a-decade-writing-fake-russian-history.-wikipedia-just-noticed.-](https://www.sixthtone.com/news/1010653/she-spent-a-decade-writing-fake-russian-history.-wikipedia-just-noticed.-)**
|
||||
|
||||
[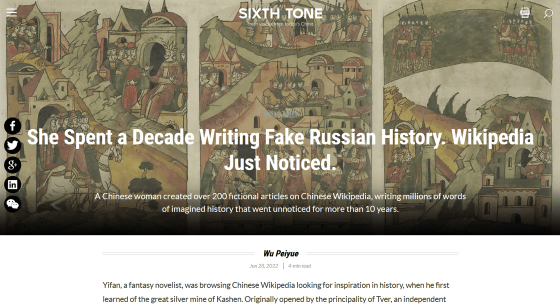](https://www.sixthtone.com/news/1010653/she-spent-a-decade-writing-fake-russian-history.-wikipedia-just-noticed.-)
|
||||
|
||||
|
||||
**A woman wrote fake Russian history on Chinese Wikipedia for 10 years**
|
||||
**[https://happymag.tv/wiki-fake-russian-history/](https://happymag.tv/wiki-fake-russian-history/)**
|
||||
|
||||
ある日、中国のファンタジー作家であるYifan氏は歴史的事実から執筆のインスピレーションを得るため、中国語版Wikipediaでさまざまな記事を閲覧しました。そんな中、Yifan氏は中世のロシアに存在した「Kashen銀鉱山」という大規模な銀鉱山についての興味深い記述に出くわしました。
|
||||
|
||||
|
||||
当該記事によれば、Kashen銀鉱山は13世紀~15世紀に存在した **[トヴェリ大公国](https://ja.wikipedia.org/wiki/%E3%83%88%E3%83%B4%E3%82%A7%E3%83%AA%E5%A4%A7%E5%85%AC%E5%9B%BD)** が開いた銀鉱山であり、約3万人の奴隷と約1万人の解放奴隷が働く当時としては世界最大規模の産業の1つだったとのこと。銀鉱山はトヴェリ大公国にとって重要な財源でしたが、近接する **[モスクワ大公国](https://ja.wikipedia.org/wiki/%E3%83%A2%E3%82%B9%E3%82%AF%E3%83%AF%E5%A4%A7%E5%85%AC%E5%9B%BD)** が銀鉱山を奪おうとしてトヴェリ大公国に戦争を仕掛けるなど、歴史的な争いの火種にもなったとWikipediaには記されていました。なお、トヴェリ大公国は1485年に **[モスクワ大公国に組み込まれて消滅](https://ja.wikipedia.org/wiki/%E3%83%88%E3%83%B4%E3%82%A7%E3%83%AA%E5%A4%A7%E5%85%AC%E5%9B%BD#%E3%83%A2%E3%82%B9%E3%82%AF%E3%83%AF%E5%A4%A7%E5%85%AC%E5%9B%BD%E3%81%B8%E3%81%AE%E5%BE%93%E5%B1%9E)** しましたが、Kashen銀鉱山はその後も採掘が続けられ、18世紀半ばに銀の枯渇で閉山されたとのこと。
|
||||
|
||||
Kashen銀鉱山を巡る中国語版Wikipediaの記述は非常に豊富であり、トヴェリ大公国とモスクワ大公国との争い、関連する貴族や技術者、鉱山を取り巻く歴史などの関連記事は数百件に上りました。Yifan氏はこれらの記事を読みあさって多くを学びましたが、もっと深くKashen銀鉱山について知りたいと思い、関連するロシア語版Wikipediaの記事や脚注にも目を向けました。
|
||||
|
||||
すると、なぜかロシア語版の記事の方が中国語版より短かったり、そもそもロシア語版の記事が存在しなかったりすることが判明。また、中世の採掘方法についての脚注に21世紀の自動採掘技術を説明した論文が参照されているなど、いくつかの矛盾があることが明らかになりました。さらに調査を重ねた結果、Yifan氏は「そもそも『Kashen銀鉱山』など存在しなかった」という結論に至ったそうです。
|
||||
|
||||
|
||||
|
||||
|
||||
Kashen銀鉱山に関する一連の記述は実在する歴史上の事柄や人物と混ざり合っており、戦争や経済など多岐にわたる記述も非常に詳細でした。さらに、百科事典にそのまま収録できるような硬い文体だったため、真実と虚偽を見分けることは非常に困難だったとYifan氏は述べています。たとえば、実際にトヴェリ大公国とモスクワ大公国は14世紀~15世紀にかけて **[争いを繰り広げていました](https://ja.wikipedia.org/wiki/%E3%83%88%E3%83%B4%E3%82%A7%E3%83%AA%E5%A4%A7%E5%85%AC%E5%9B%BD#%E3%83%A2%E3%82%B9%E3%82%AF%E3%83%AF%E5%85%AC%E5%9B%BD%E3%81%A8%E3%81%AE%E9%97%98%E4%BA%89)** が、架空の歴史を書いた人物はこの歴史的事実を取り入れつつ、戦争の主要な動機としてKashen銀鉱山を位置づけていたとのこと。
|
||||
|
||||
Kashen銀鉱山にまつわる記事を作成・編集した人物は4つのアカウントを使い回しており、中国のインターネットユーザーからはそのうちの1つである「折毛(Zhemao)」という名前で呼ばれています。Wikipediaの調査によると、Zhemaoは2010年ごろ、実在する **[清](https://ja.wikipedia.org/wiki/%E6%B8%85)** の政治家・ **[ヘシェン](https://ja.wikipedia.org/wiki/%E3%83%98%E3%82%B7%E3%82%A7%E3%83%B3)** に関する「偽のエピソード」を執筆。やがてロシアの歴史に目を向け始め、2012年にロシア皇帝 **[アレクサンドル1世](https://ja.wikipedia.org/wiki/%E3%82%A2%E3%83%AC%E3%82%AF%E3%82%B5%E3%83%B3%E3%83%89%E3%83%AB1%E4%B8%96_\(%E3%83%AD%E3%82%B7%E3%82%A2%E7%9A%87%E5%B8%9D\))** の記事を編集して以降、徐々に想像で作り上げた「架空のロシアの歴史」を中国語版Wikipediaに広げ始めました。
|
||||
|
||||
最終的に、Zhemaoが作成した中国語版Wikipediaの記事は206件に上り、数百もの関連記事を編集したとのことで、架空のロシアの歴史についての総文字数は数百万語に及ぶとされています。実在した国家間の争いを基に研究や空想を織り込んで壮大な偽史を作り上げたZhemaoに対し、一部のネットユーザーは「中国の **[ホルヘ・ルイス・ボルヘス](https://ja.wikipedia.org/wiki/%E3%83%9B%E3%83%AB%E3%83%98%E3%83%BB%E3%83%AB%E3%82%A4%E3%82%B9%E3%83%BB%E3%83%9C%E3%83%AB%E3%83%98%E3%82%B9)** 」というニックネームを付けたとのこと。
|
||||
|
||||
[](https://i.gzn.jp/img/2022/06/30/fake-russian-history-chinese-wikipedia/02.jpg)
|
||||
|
||||
|
||||
Zhemaoは自身のプロフィールに「ロシア駐在の外交官の娘で、ロシア史の学位を持ち、ロシア人と結婚してロシア国籍を取得した」と記していましたが、発表した謝罪文で実際には高校を出ただけの専業主婦だと明かしています。
|
||||
|
||||
謝罪文によると、Zhemaoは最初に編集した2つの記述の矛盾を埋めるために偽の記述を作りだし、やがて壮大な架空のロシアの歴史を書くようになったと説明しています。「ことわざにもあるように、うそを隠すためにもっとうそをつくことになりました。何十万文字も書いた記述を削除するのをためらった結果、何百万文字もの記述を削除することとなり、アカデミックの連帯も崩れてしまいました。迷惑をかけたことの取り返しはつかず、処分は永久追放しかないのかもしれません」とZhemaoは述べ、今後は手に職をつけて真面目に仕事をし、Wikipediaの編集から手を引くとしています。
|
||||
|
||||
6月17日の時点で、Zhemaoによって作られた中国語版Wikipediaの項目はほとんどが削除されるか、正しいものに修正されているとのこと。しかし、一部の記述は英語やアラビア語、ロシア語、ルーマニア語のWikipediaにも翻訳されているとのことで、そのうちの一部は依然として残っているそうです。
|
||||
|
||||
なお、Wikipedia編集者はこの事件について「中国語版Wikipedia全体の信頼性を揺るがした」と非難していますが、多くのインターネットユーザーは数百万語もの架空の歴史を書き上げたZhemaoの才能と粘り強さを称賛し、「いつか小説を出版するべき」との声も上がっています。
|
||||
|
||||
**・関連記事**
|
||||
**[ロシアいわく「Wikipediaが虚偽の情報を掲載している」として500万円超の罰金を科すと警告 - GIGAZINE](https://gigazine.net/news/20220406-russia-threatens-wikipedia)**
|
||||
|
||||
**[日本語版Wikipediaの情報は少数のユーザーによってゆがめられているという指摘 - GIGAZINE](https://gigazine.net/news/20210323-japanese-wikipedia-misinformation)**
|
||||
|
||||
**[歴史上のさまざまなデマを集めた「デマ博物館」が公開中、中世から21世紀までのあらゆるデマを一気に読むことが可能 - GIGAZINE](https://gigazine.net/news/20200114-hoaxes-museum-history)**
|
||||
|
||||
**[「幻の世界」や「ユートピア」など太古に思い描かれた架空の世界のイラストを集めた本「The Book of Legendary Lands」 - GIGAZINE](https://gigazine.net/news/20150403-legendary-lands)**
|
||||
|
||||
**[古代や中世の「服」は自動車並みの価格で取引されていた - GIGAZINE](https://gigazine.net/news/20220213-ancient-clothe-cost)**
|
||||
|
||||
**[フランス料理が今の形になるまでの変遷とは? - GIGAZINE](https://gigazine.net/news/20190721-french-cuisine-history)**
|
||||
|
||||
**[チョコレートとキリスト教にまつわる知られざる歴史とは? - GIGAZINE](https://gigazine.net/news/20220402-chocolate-history-theology)**
|
||||
|
||||
**[世界中で食べられる「パン」の歴史とは? - GIGAZINE](https://gigazine.net/news/20180515-who-invented-bread)**
|
||||
|
||||
**・関連コンテンツ**
|
||||
|
||||
- [](https://gigazine.net/news/20220801-wikipedia-judicial-behavior/)
|
||||
[Wikipediaの記事が司法判断に影響を与えていることが判明、Wikipedia内の語句がまるごと含まれる例も](https://gigazine.net/news/20220801-wikipedia-judicial-behavior/)
|
||||
- [](https://gigazine.net/news/20220303-russian-invasion-ukraine-playing-out-wikipedia/)
|
||||
[ロシアのWikipedia編集者はウクライナへの軍事侵攻にどう反応しているのか?](https://gigazine.net/news/20220303-russian-invasion-ukraine-playing-out-wikipedia/)
|
||||
- [](https://gigazine.net/news/20170502-china-great-wall-of-culture/)
|
||||
[中国が2万人のスタッフを雇って「中国版Wikipedia」を作成へ](https://gigazine.net/news/20170502-china-great-wall-of-culture/)
|
||||
- [](https://gigazine.net/news/20231001-china-qing-dynasty-collapse/)
|
||||
[中国最後の王朝である清王朝はなぜ急激に崩壊を迎えたのか?](https://gigazine.net/news/20231001-china-qing-dynasty-collapse/)
|
||||
- [](https://gigazine.net/news/20210323-japanese-wikipedia-misinformation/)
|
||||
[日本語版Wikipediaの情報は少数のユーザーによってゆがめられているという指摘](https://gigazine.net/news/20210323-japanese-wikipedia-misinformation/)
|
||||
- [](https://gigazine.net/news/20200827-scotland-wikipedia-writer/)
|
||||
[Wikipediaがたった1人の管理者にめちゃくちゃな言語で編集されてしまう](https://gigazine.net/news/20200827-scotland-wikipedia-writer/)
|
||||
- [](https://gigazine.net/news/20160108-russia-mordor/)
|
||||
[Google翻訳が「ロシア」を指輪物語の敵国「モルドール」と翻訳してしまう事態が発生](https://gigazine.net/news/20160108-russia-mordor/)
|
||||
- [](https://gigazine.net/news/20140715-2-7-million-wikipedia-articles/)
|
||||
[Wikipediaにひとりで270万もの記事を投稿した男の正体とは?](https://gigazine.net/news/20140715-2-7-million-wikipedia-articles/)
|
||||
|
||||
2022年06月30日 19時00分00秒 in [メモ](https://gigazine.net/news/C7/), Posted by log1h\_ik
|
||||
|
||||
You can read the machine translated English article **[It turns out that one woman has been wri…](https://gigazine.net/gsc_news/en/20220630-fake-russian-history-chinese-wikipedia)**.
|
||||
@@ -0,0 +1,46 @@
|
||||
---
|
||||
source_url: https://www.404media.co/wikipedia-cofounder-larry-sanger-banned-from-site-for-canvassaing/
|
||||
ingested: 2026-06-29
|
||||
sha256: d26a83b5590ce5d618f3625b8a26045ffa7e10e8068d81f2c75a8fa76448061a
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1028287639918497822'
|
||||
channel_name: chat
|
||||
message_id: '1521292658935332884'
|
||||
author_id: '890908900520505354'
|
||||
posted_at: 2026-06-29T23:13:54.141000000Z
|
||||
message_excerpt: https://www.404media.co/wikipedia-cofounder-larry-sanger-banned-from-site-for-canvassaing/
|
||||
---
|
||||
Larry Sanger, one of Wikipedia’s cofounders, was banned from editing the site indefinitely after other editors determined he was canvassing, or in other words, calling on his followers off platform in order to influence Wikipedia’s content.
|
||||
|
||||
Sanger has spent more than a decade criticizing Wikipedia for what he claims is an ideological, left-wing bias on a variety of topics, and on X has framed this recent ban as further proof of everything that’s wrong with Wikipedia. The [*New York Post*](https://nypost.com/2026/06/22/tech/left-leaning-wikipedia-blocked-founder-from-editing-site-after-he-campaigned-to-make-it-more-balanced/?ref=404media.co) took that bait and last night published an article with the headline “Left-leaning Wikipedia blocked founder from editing site—after he campaigned to make it more balanced.”
|
||||
|
||||
Wikipedia editors obviously reject that framing and say that Sanger was banned for wielding his followers to sway discussion and decision making on Wikipedia. The discussion that led to the decision to ban Sanger concluded with what an editor called a “clear consensus” to ban Sanger.
|
||||
|
||||
“There is general agreement among participants that he has engaged in off-wiki [canvassing](https://en.wikipedia.org/wiki/Wikipedia:CANVASSING?ref=404media.co) and is [not here](https://en.wikipedia.org/wiki/Wikipedia:NOTHERE?ref=404media.co) to constructively build the encyclopedia,” the editor said in a note closing the discussion. “There is also a significant concern shared by many editors that his actions constitute calls for [outing](https://en.wikipedia.org/wiki/Wikipedia:OUTING?ref=404media.co).”
|
||||
|
||||
While Sanger has been railing about bias on Wikipedia for years, the specific issue here is around his WikiProject Intellectual Diversity. WikiProjects are group efforts among Wikipedia volunteers to deal with certain issues on the site. For example, in 2024 I wrote about [WikiProject AI Cleanup](https://www.404media.co/the-editors-protecting-wikipedia-from-ai-hoaxes/), a group of volunteers who focus on removing AI-generated content from the online encyclopedia. Sanger’s WikiProject Intellectual Diversity, as its name implies, aims to bring more intellectual diversity to the site, mostly meaning more right-leaning perspectives.
|
||||
|
||||
Sanger’s WikiProject Intellectual Diversity and its goals alone do not merit a ban according to Wikipedia’s policies. The problem, according to Wikipedia editors, is that during the discussion about whether to allow WikiProject Intellectual Diversity to become an official WikiProject, Sanger invited his 91,000 followers on X to influence that discussion.
|
||||
|
||||
“Wikipedians are now debating whether my proposed WikiProject Intellectual Diversity should be permitted to become an official WikiProject (club/group of editors),” Sanger [said on X](https://x.com/lsanger/status/2068009265218953588?ref=404media.co) on Friday and linked to the Wikipedia talk page about the issue. “Lots opposed. Also lots in favor.”
|
||||
|
||||
“Can I still join the movement?” one [person replied to Sanger on X](https://x.com/NewsNFTU/status/2068019628886942058?ref=404media.co).
|
||||
|
||||
“Let's just say that if I answer that question one way or another, the playground moms who rule Wikipedia might block me,” Sanger responded.
|
||||
|
||||
As one volunteer wrote in the discussion page about whether to ban Sanger:
|
||||
|
||||
“Since the return from his self-imposed exile pretty much all he has done is try to start a right-wing/conservative pressure group within Wikipedia not to improve articles on topics that may be under-represented or highlight high-quality sources that could be utilised more, but to instead attempt to rewrite policies and guidelines to his political bent while throwing baseless aspersions about the conduct of many users (mostly those in privileged positions such as admins) and alleging they're being funded by shadow money. Frankly if this was anyone else claiming all this with the way he is, we'd have shown them the door long ago.”
|
||||
|
||||
Ilyas Lebleu, another Wikipedia volunteer and admin, told me that they had warned Sanger about similar behavior two months ago, but that Sanger ignored them.
|
||||
|
||||
“Larry tried to frame the community discussion as a pseudo-legalistic process, bringing a list of ‘charges’ and ‘counts’ from ‘prosecutors,’ instead of an open community discussion,” Lebleu said.
|
||||
|
||||
Discussions about potential bans are supposed to remain open for at least 72 hours. While consensus that Sanger had violated Wikipedia policies was clear, Sanger was banned at some point before that deadline. He was then briefly unbanned, and then again indefinitely banned once 72 hours had elapsed and the discussion about the ban closed.
|
||||
|
||||
“Wikipedia has become more of a mob-rule anarchy than ever,” Sanger said in a statement sent to me by a spokesperson. “In the kangaroo court in which a mob ousted me, Wikipedia’s administrators showed that they don’t appear to value details like formal charges, a designated prosecutor, basic decorum, distinction between prosecution and judge, dispassionate adjudication, and so forth. They have no proper system other than triggering a mob to selectively enforce their hodgepodge of vague rules.”
|
||||
|
||||
“Now that same mob has blocked me for trying to bring an intellectually diverse group of thinkers and editors to the site,” Sanger continued. “Subscribing to their groupthink is now an official requirement of being a member in good standing. Something must change, and now. I only wonder if the system as it currently stands can even allow the discourse necessary to fix the system.”
|
||||
|
||||
Sanger’s claim that Wikipedia has a left-leaning bias isn’t unique or new. Elon Musk has railed against the site for years as well, an effort that culminated with the launch of his [highly flawed](https://www.404media.co/grokipedia-is-the-antithesis-of-everything-that-makes-wikipedia-good-useful-and-human/), AI-generated Grokipedia. But the stakes for Wikipedia as a reliable source of information are higher than ever as every corner of the internet is struggling to deal with a flood of AI-generated, error-filled slop.
|
||||
@@ -0,0 +1,49 @@
|
||||
---
|
||||
source_url: https://www.wolfssl.com/wolftpm-add-tpm-2-0-v1-85-pqc-post-quantum-support/
|
||||
ingested: 2026-06-30
|
||||
sha256: 56903e3f29834c03321ac031bd296fdb4dfa61736eff7ff3bd33944effcf2595
|
||||
discovered_from:
|
||||
platform: discord
|
||||
channel_id: '1477793137064935675'
|
||||
channel_name: tw
|
||||
message_id: '1521324831096705217'
|
||||
author_id: '1477793167486226708'
|
||||
posted_at: 2026-06-30T01:21:44.582000000Z
|
||||
context_url: https://x.com/yousukezan/status/2071752910283915461
|
||||
message_excerpt: >-
|
||||
TPM 2.0 v1.85 PQC support pointer; practical post-quantum hardware-backed security.
|
||||
---
|
||||
|
||||
As the cybersecurity landscape prepares for the advent of quantum computing, the Trusted Platform Module (TPM) ecosystem is evolving to meet these new challenges. wolfSSL is proud to announce that **wolfTPM** now includes initial support for the **TPM 2.0 Library Specification v1.85**, bringing Post-Quantum Cryptography (PQC) capabilities to your hardware-backed security workflows.
|
||||
|
||||
This update introduces support for the National Institute of Standards and Technology (NIST) standardized algorithms: **ML-DSA (Dilithium)** and **ML-KEM (Kyber)**.
|
||||
|
||||
**ML-DSA: Quantum-Resistant Digital Signatures**
|
||||
The transition to PQC requires more than just new algorithms; it requires new ways of interacting with TPM hardware. wolfTPM now supports the sequence-based signing and verification commands required by ML-DSA, including:
|
||||
|
||||
- TPM2\_SignSequenceStart / TPM2\_VerifySequenceStart
|
||||
- TPM2\_SignSequenceComplete / TPM2\_VerifySequenceComplete
|
||||
- TPM2\_SignDigest / TPM2\_VerifyDigestSignature
|
||||
|
||||
These commands allow for context-based signing, ensuring that large messages can be processed securely through the TPM’s post-quantum engines.
|
||||
|
||||
**ML-KEM: Enhanced Key Encapsulation**
|
||||
For secure key exchange, wolfTPM now implements the ML-KEM (formerly Kyber) commands:
|
||||
|
||||
- **TPM2\_Encapsulate**: A public-key operation to generate a shared secret and a ciphertext.
|
||||
- **TPM2\_Decapsulate**: A private-key operation used to recover the shared secret from the ciphertext.
|
||||
|
||||
**New PQC Types and Structures**
|
||||
To support these advanced algorithms, we have integrated several new types and structure tags into our library, such as TPM2B\_KEM\_CIPHERTEXT, TPM2B\_SHARED\_SECRET, and TPM\_ST\_MESSAGE\_VERIFIED. These additions ensure that your application can seamlessly handle the larger key sizes and unique data structures associated with post-quantum algorithms.
|
||||
|
||||
**Getting Started**
|
||||
To explore these new features, ensure you are using a TPM that supports the v1.85 specification. You can find new unit tests in the wolfTPM source code to help guide your implementation:
|
||||
|
||||
- test\_wolfTPM2\_MLDSA\_\*
|
||||
- test\_wolfTPM2\_MLKEM\_\*
|
||||
|
||||
For more details, view the full [Pull Request #445](https://github.com/wolfSSL/wolfTPM/pull/445) on GitHub.
|
||||
|
||||
Interested in a commercial license or post-quantum consulting? Contact us at [[email protected]](mailto:[email protected]) or call [+1 425 245 8247](tel:14252458247).
|
||||
|
||||
**[Download](https://www.wolfssl.com/download/) wolfSSL Now**
|
||||
Reference in New Issue
Block a user